
Avoiding the AI Trap: Keeping Your Brain Sharp in the Age of Generative AI
Updated: Oct 8

UIC University 365 Institute of Communication
Series AI Learning Series | Level Basic (Free)
Duration 25 minutes | Access Free
Digital Communication, Marketing, Branding, Content Strategy, Media Studies

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture

The Hook: The Most Convenient Thing You Have Ever Done
Something happened to your reading in the last two years, and you may not have noticed it. Not the amount. The mode. You can now find out what almost any document says without deciding whether it is worth reading. You can get a position on a question without forming one. You can produce a plausible paragraph without knowing what you think.
Each of those is a genuine convenience, and each one removes a rep. This is the structure of the trap: the tool that removes the work removes the exercise at the same time, and the exercise was the thing that maintained the capacity. You do not lose the ability first and then stop. You stop, and the ability goes.
There is now hard evidence about what this looks like over four months. A study from MIT's Media Lab released as a preprint in June 2025 put 54 participants through essay writing across three conditions: with a large language model, with a search engine, or with no tools at all. The group using the model showed the weakest and most localised brain connectivity of the three, reported the lowest sense of ownership of their own writing, and 83 percent could not quote from an essay they had written minutes earlier. In a fourth session, with the tool removed, they showed lower engagement than participants who had never used it. The paper had not completed peer review when released and the sample was modest, so the sizes are provisional. The direction is not really in question, and it matches decades of work on automation and skill decay.
The counter-argument is equally real, and this lecture gives it its due. Used properly, the same tools produce documented learning gains, better recall, and more sophisticated reasoning. In that same study, the group that had written without tools and was then given access showed higher memory and broader brain activation than the group that had started with the model. The tool is not the variable. The order is. Which is the argument for a set of deliberate practices rather than for either enthusiasm or abstinence.
This lecture covers what cognitive offloading is and what the research actually shows, the confidence effect that makes the trap invisible from inside, where it shows up in a normal working week, how the automation literature is useful and where the analogy breaks, seven countermeasures that hold up, how to design guardrails for your own work, and how to measure whether your capability is holding or quietly leaving.
Step 1: What Cognitive Offloading Is, and What the Evidence Shows
The definition. Cognitive offloading is using an external system to reduce the mental effort a task requires. It is not new and it is not inherently bad. Writing is offloading memory onto paper. A calendar is offloading scheduling. A calculator is offloading arithmetic. Every one of those made people capable of things they could not do before, and the trade-offs were understood and accepted.
The question is not whether offloading is good or bad. It is which specific capacities you are willing to let go of, and whether you have decided that deliberately.
The mechanism that makes it stick. A cognitive process gets stronger with use and weaker without it. That principle is not controversial. What is easy to miss is that the exercise is often invisible: when you delegate a task, you do not feel a muscle go unused. You feel relief.
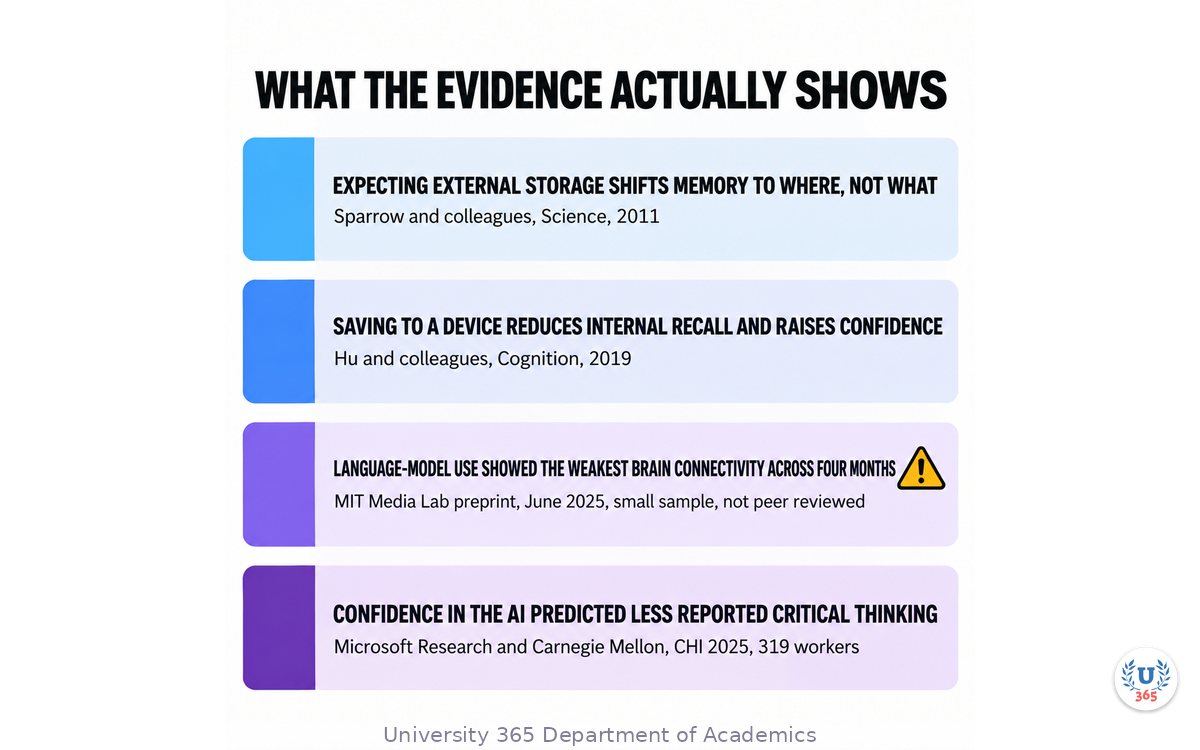
What the research shows, source by source. Four findings, each with its scope stated honestly.
External storage shifts what you remember toward where to find it. Classic work by Sparrow and colleagues published in Science in 2011 found that when people expect information to be stored externally, their memory shifts toward the location rather than the content. The effect is well established and the practical reading is specific: knowing where something is is not the same as knowing it, and if your whole reading system stores rather than retains, you will reliably know where things are and reliably not have them.
Saving to a device can reduce internal recall while increasing confidence. A 2019 study by Hu, Luo and colleagues in Cognition found that participants who saved word pairs to a computer recalled less internally but felt more confident about their recall. The confidence finding is the important half, and it reappears throughout this lecture.
The language-model effect on neural engagement is measurable. The MIT study described in the hook is the sharpest recent measurement. Its own stated limitations matter: an essay-writing task in an educational setting, one model family, a small sample, and a preprint. Its own authors caution against generalising across tasks. The consistent pattern across the four sessions is what carries weight, not any single percentage.
Confidence in the tool predicts less critical thinking at work. A survey by researchers at Microsoft Research and Carnegie Mellon, presented at CHI in 2025, collected 319 knowledge workers and 936 real examples of AI use at work. Higher confidence in the AI's ability on a task was associated with less reported critical thinking. Higher confidence in the respondent's own ability was associated with more. The study is self-reported, which limits what it can establish about actual performance, and it aligns with the other three findings.
What the four together support, and what they do not. They support a specific claim: routine offloading reduces the exercised capacity while increasing your confidence that it is intact. That combination is what makes the trap structural rather than a matter of willpower. They do not support the claim that using AI makes you less intelligent in general. No study establishes that, the effect sizes found are task-specific, and the same tools show learning gains when the order of use is right.
Step 2: The Confidence Effect That Makes the Trap Hard to See
Of everything in the evidence base, the confidence effect deserves its own section, because it is what stops you noticing.
The finding, restated. In both the Cognition study and the workplace survey, the people using the external aid felt more confident, not less. In the workplace survey, the direction ran both ways and is worth separating: confidence in the AI predicted less critical thinking, confidence in yourself predicted more.
Why confidence is the diagnostic that fails. Fluency is not comprehension. Text you have just read feels familiar, and familiarity is easily mistaken for knowledge, which is the reason rereading is such an ineffective study method and such a popular one. When the fluency comes from generated text rather than from your own reading, the same illusion arrives faster and with less basis. You are confident about material you have not processed because it arrived in clear, well-formed prose.
The competence trap inside it. The workplace finding points to a self-reinforcing loop. The more you believe the tool handles a task, the less you check. The less you check, the less you develop the domain knowledge that would let you check. The less domain knowledge you have, the more plausible the tool's output looks. Nothing in the loop feels like degradation, and the loop is invisible from inside it.
Two experiments you can run on yourself this week. Both take minutes.
The first is a quoting test. Take something you produced with assistance last week and try to state its central argument, from memory, in two sentences, without opening the document. The MIT group's version of this test found 83 percent unable to quote their own essays. Yours will be more forgiving and it will still be informative.
The second is a prediction test. Before you ask for an output, write down what you expect it to say. Then compare. If your prediction is consistently accurate, you understand the domain and the tool is accelerating you. If it is consistently vague or wrong, the tool is supplying judgement you do not have, which means you cannot evaluate the result.
What to do with the answer. Neither test tells you to stop using the tools. They tell you where you need a deliberate practice to keep the capacity. A person who can predict the output and then checks it is using an amplifier. A person who cannot predict it and does not check it is using a substitute and cannot tell the difference.
The confidence rule to adopt. Confidence is a signal to check more, not less. When an output feels obviously correct, that is the moment to name one claim in it and verify it. The cost is thirty seconds. The alternative is a system that is only ever tested by its own assurances.
Step 3: Where It Shows Up in Your Working Week
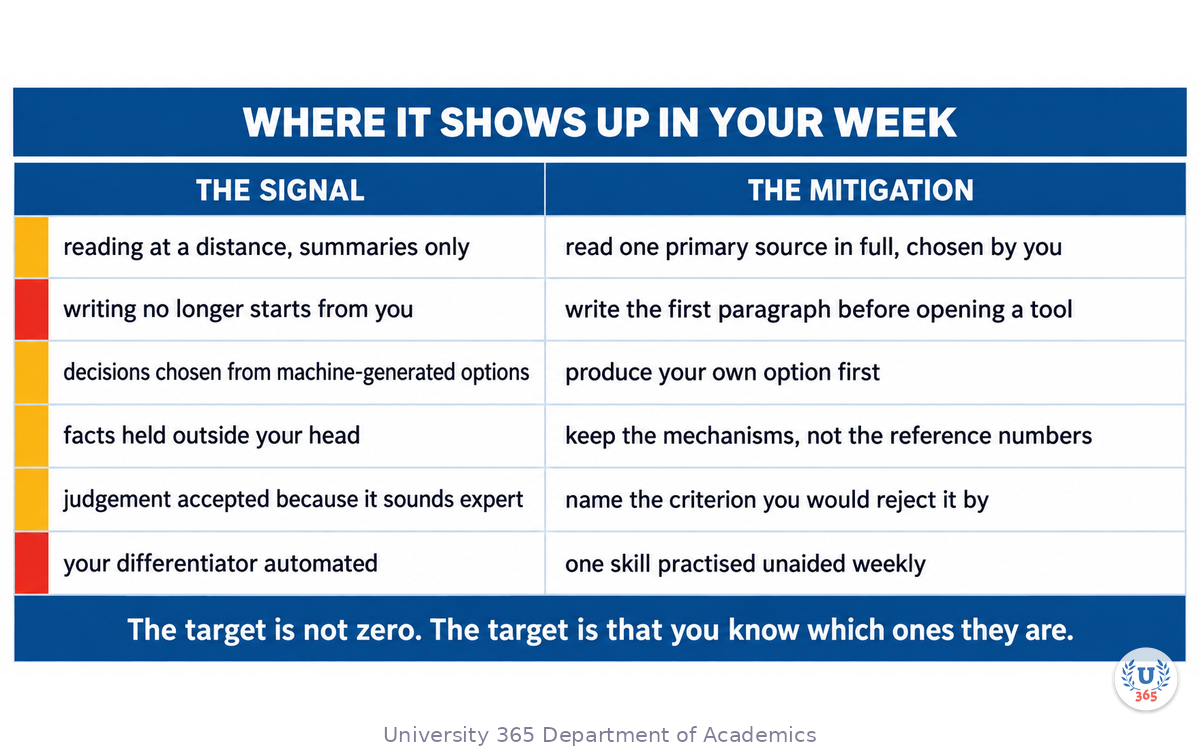
The abstract case becomes actionable when you locate it in your own hours. Six places where the pattern appears for knowledge and communication work, in roughly the order they cost you most.
1. Reading at a distance. You summarise rather than read. The immediate gain is large: an hour of reading compressed to three minutes. The cost is that your map of a field thins without any signal, because you still know the names and the conclusions. Mitigation: always read one primary source in full after any summarised set, chosen by you rather than by the summary.
2. Writing that has stopped starting from you. You open the assistant before you open the document. The first sentence is not yours, the structure is not yours, and your job becomes editing. Editing is a real skill and it is not the same skill as forming an argument. Mitigation: write the first paragraph and the outline before opening any tool, every time, even badly.
3. Decision-making by draft. You produce three options with a tool and pick one, without having generated an option yourself. The options are all drawn from the same distribution, which is why they feel similar, and the choice among them is a choice among variations of one idea. Mitigation: produce your own option first, then ask for the ones you are missing.
4. Memory delegated to search. You no longer hold facts you use weekly, because you can retrieve them. Defensible for reference material, costly for the concepts your judgement is built from. Mitigation: distinguish retrieval from understanding. Reference numbers can live outside your head. The mechanisms and their trade-offs cannot.
5. Judgement delegated to confidence. You accept a recommendation because it sounds expert. This is the confidence effect doing its work at the point of decision. Mitigation: for any recommendation you accept, name the criterion you would use to reject it. If you cannot name one, you have not made a decision.
6. Skill delegated in the area you are paid for. This is the expensive one. You automate the part of your work that was your differentiator and it works well for a year, and then the market shifts and you cannot produce the thing unaided. Mitigation: one skill deliberately unassisted, practised on a schedule, chosen because it is central to what you are valued for.
How to audit your week in fifteen minutes. Look at last week's calendar and list every AI-assisted task. For each, mark whether you could have produced the core of it unaided. Count the ones you could not. That count is a rough measure of how much of your week is substitution rather than amplification, and the target is not zero. The target is that you know which ones they are.
The one that is genuinely fine. Administrative work: formatting, transcribing, converting, templating, reformatting across formats. Offloading those costs you nothing worth keeping. The trap is not in them. It is in the tasks that sit next to the ones you care about, where the convenience is the same and the exercise that disappears was the point.
Step 4: The Automation Parallels, and Their Limits
Aviation is the most useful comparison available, because it is the field that has been automating expert judgement longest and measuring what happened.
What the record shows. Aviation safety literature has documented for years that heavy reliance on automation degrades manual flying skills and, more consequentially, the ability to take over when automation hands back control unexpectedly. Training regimes responded with mandatory manual flying: hours flown by hand, on a schedule, regardless of whether automated systems would do it better. The practice is not nostalgia. It exists because the skill that is exercised only when the automation fails is the skill that will have failed too.
Why the parallel holds. Three structural similarities. The automation is reliable enough that the skill is rarely needed, so the decay is invisible until the moment it matters. The performance metrics improve while the underlying capability drops, because the task gets done either way. And the person in the loop keeps feeling competent, because they are still supervising successfully.
Where the parallel breaks, and this matters. A pilot's failure is immediate, physical and attributable. A knowledge worker's is slow and diffused across years, which means it produces no feedback that would prompt a correction. And the handover is different in kind: an aircraft hands back control suddenly and completely, while an assistant degrades your capability gradually across many small delegations. The absence of a dramatic handover is why the aviation training practice is not obviously transferable. You have to schedule your manual flying without any incident to prompt it.
Navigation is the second useful analogue, and it is better measured. Research published in Nature Communications in 2017 by Peer and colleagues found reduced hippocampal activity and weaker spatial-memory performance among participants who followed turn-by-turn directions compared with those who navigated themselves. The effect is well established and small in daily consequence, and the generalisable point is the one that matters: the mental process that constructs a route is the process that maintains the spatial map, and following instructions removes it.
What the literature does not support. It does not support claims that automation makes people less capable in general, and any argument that leans on a single dramatic number should be treated with suspicion. The pattern is narrower than the fear and more consistent than the reassurance: the specific process that is offloaded is the specific process that declines.
The practical translation. Pick the process you would most regret losing, name it, and schedule the manual version. That is the whole of the analogy applied. The aviation answer was not to fly less. It was to fly by hand on a schedule.
Step 5: Seven Countermeasures That Hold
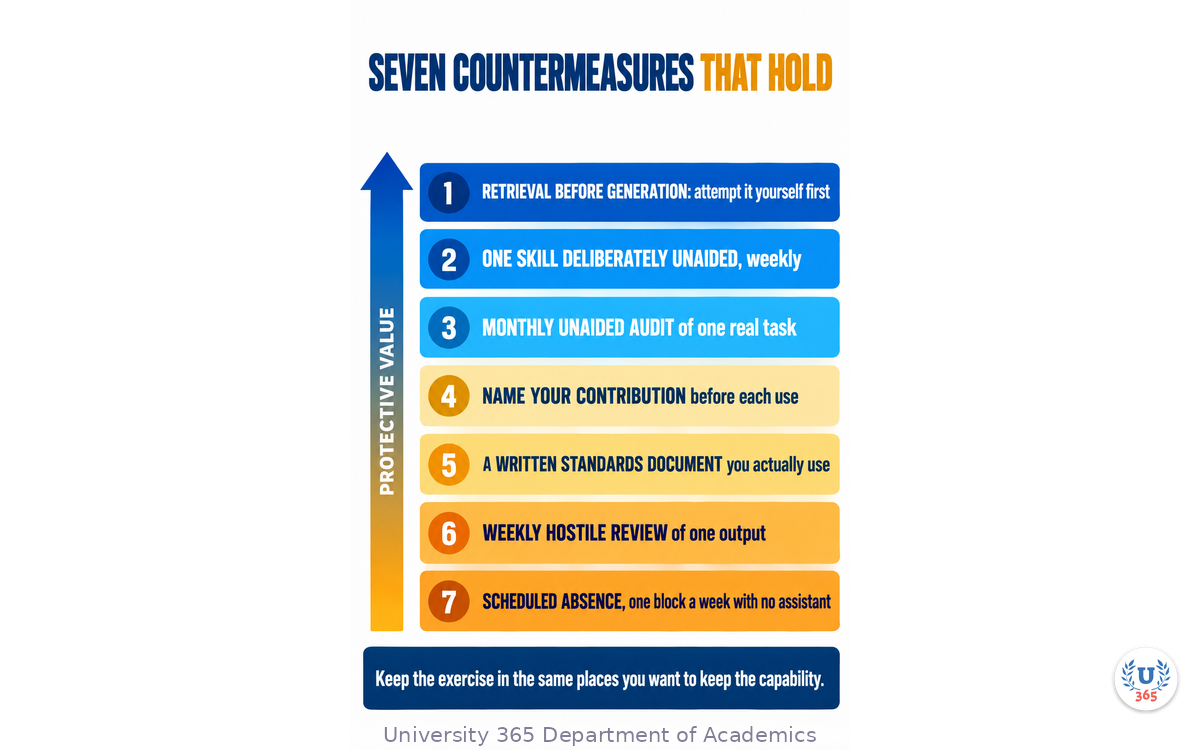
These are ordered by protective value, and the first three do most of the work.
1. Retrieval before generation. Attempt the task yourself before opening any assistant. Even five minutes of your own attempt changes the interaction fundamentally: you now have something to react to, a position to defend, and a way to notice when the tool's answer does not fit what you already understood. This is the single most protective habit available, it costs nothing, and it applies to every task in Step 3.
2. One skill deliberately unassisted. Choose the capability most central to your professional value and practise it without tools on a fixed schedule. Weekly is enough for most skills, monthly is too little. Keep it visible: put it in the calendar as an appointment rather than an intention.
3. A monthly unaided audit. Once a month, do one significant recurring task the old way, start to finish, and compare it with your assisted baseline. Two purposes: it tells you whether your capability is holding, and it tells you whether the assistant is still adding anything. Both answers change as the tools improve and as you change.
4. Name your contribution before each use. Before a task of consequence, state what you are bringing and which capability the tool is supposed to amplify. If you cannot state your contribution, the task is a substitution and it is worth knowing that before you do it rather than after.
5. A written standards document that you use. Your definition of a good output for each recurring task, applied on every run. This is protective for a non-obvious reason: it moves judgement from the model back to you, because the model is now applying your criteria rather than supplying its own defaults.
6. A weekly hostile review of one output. Take one assisted output and check it as if a rival had submitted it. What is unverified, what is generic, what would you challenge. Twenty minutes a week. This keeps your critical faculty load-bearing rather than ceremonial, and the workplace survey finding makes the point precisely: your own confidence is what drives checking, and confidence in the tool is what suppresses it.
7. Scheduled absence. One block a week with no assistant available for the work you care about. Not a digital detox in the wellness sense, and not an evening off screens. A working block, on real work, without the tools. The aviation answer in its plainest form.
What none of these do. They do not reduce your output, and none of them asks you to use the tools less. They redistribute which parts of the task you keep. Read together, the seven say one thing: keep the exercise in the same places you want to keep the capability.
What to drop if you only keep one. The monthly unaided audit. It detects the problem, and everything else in the list is easier to sustain once you know whether you have a problem.
Step 6: Designing Your Own Guardrails
Countermeasures are individual habits. Guardrails are structural: they hold when you are busy, tired, or under deadline, which is exactly when habits fail. Four to build, in the order they pay back.
Guardrail 1: The task classification. Write your recurring tasks into two lists. List A is work where the output is what matters and you would not miss the process: formatting, transcription, conversion, first-pass extraction, templating. List B is work where the process is what builds your capability: argument formation, analysis, design decisions, client reasoning, anything you are valued for. Automate List A fully and without guilt. Apply the retrieval rule to List B without exception. The value of the classification is that it removes the decision from the moment when you are least able to make it well.
Guardrail 2: The order rule, enforced by tooling where possible. Put your own attempt before the tool, structurally rather than by intention. Open the document before the chat window. Keep your notes file open and the assistant closed when you start. If your team uses a shared process, make the rule explicit: a first draft from the author, then tool support. Making it procedural rather than personal is what makes it survive a busy week.
Guardrail 3: The artefact requirement, in any team you run. Require reasoning rather than output. If you manage people, ask for the decision and the criterion, the analysis and the assumption, the design and the rejected alternative. Not as a policing measure against AI use, which is unenforceable and mostly pointless, but because a team that only ever produces finished output has no shared judgment to build on.
Guardrail 4: The capability register. Once a quarter, list the capabilities your team or your role depends on and mark each as exercised, partially exercised, or delegated. The register is short, a dozen lines. Its function is that delegated capabilities become visible while they are still recoverable, rather than at the point where someone notices a gap.
How to know a guardrail is actually holding. A habit is a guardrail if it survived a bad week. Test yours: did the rule hold last time you were behind, or did it quietly not apply. The one that breaks under load is not a guardrail yet, and the fix is to make it smaller or to move it into a process rather than a preference.
The organisational version, briefly. At team level the same four apply with one addition: make the unaided practice legitimate. In most organisations, doing a task the slower way when a tool is available looks inefficient and is quietly discouraged. A team that expects its people to keep hard skills has to say so out loud, because the incentive otherwise points entirely the other way.
Step 7: Measuring Whether Your Brain Is Still Sharp
You cannot manage what you do not measure, and the measures here have to be honest ones rather than satisfaction surveys.
Measure 1: The unaided comparison. Once a month, one significant task done start to finish without assistance. Compare it against the same task assisted, against your own written criteria rather than against a feeling. What you are looking for is not whether the assisted version is better, which it usually is, but whether the gap has widened over six months. A widening gap means the capability is being transferred rather than amplified.
Measure 2: The recall test. Pick three things you learned in the last quarter that matter to your work. From memory, in writing, explain each in two sentences with its main trade-off. Then check. The gap between what you wrote and what is true is your retention, and it is a more honest measure than any sense of having kept up.
Measure 3: The prediction test. Before requesting a consequential output, write down what you expect it to say. Score your prediction. A high and stable score means you hold the domain knowledge that makes the tool usable, which is the condition the workplace survey identified for more critical engagement.
Measure 4: The substitution count. From the weekly audit in Step 3, the number of AI-assisted tasks you could not have produced unaided. Track it monthly. It does not have to be zero, and it should not be climbing indefinitely without you having decided that each one is acceptable.
Measure 5: The exercise ledger. One line a week: which capability did you deliberately exercise without assistance, and for how long. The ledger is the only measure that tracks the input rather than the output, and the input is what determines next year's output.
Reading the five together. No single measure is decisive, and the combination is reasonably robust. Measure 1 catches capability loss. Measure 2 catches retention loss. Measure 3 catches the loss of the domain knowledge that makes the tool safe to use. Measure 4 catches the structural drift. Measure 5 tells you whether you are doing anything about it.
What to do with a bad reading. Do not respond by cutting tool use. The research on both sides says the gains from proper use are real. Respond by reallocating: move hours from assisted work to one unassisted capability, restore the retrieval step, and re-measure in a month. The measures are a steering wheel, not a verdict.
The honest limit of self-measurement. You are the least reliable judge of your own decline, which is the entire point of Step 2. Where it matters, get an outside reading: a colleague who reviews your work, a mentor who knew your earlier standard, a test you did not design. Nothing here replaces that, and the measures above are the best available when you cannot get it.
Step 8: The Team Dimension: Offloading Across a Group
Everything so far has been about one person. Teams are different in one specific way that changes the failure mode: capability can concentrate rather than spread, and the group can lose a skill without any individual noticing.
The concentration problem. In a team of eight where one person is genuinely strong at the hard part, the natural workflow routes all of that work to them. The remaining seven progressively stop exercising it, and the team's capability in that area ends up in one head. This was already true before AI, and AI accelerates it in two ways: it makes the strong person faster, which increases the case for routing everything to them, and it lets a weaker person produce output that looks like the strong person's, which hides the gap.
The visible symptom, and the invisible one. The visible symptom is a bottleneck: everything hard waits for one person. The invisible symptom is that the team's shared judgement has narrowed while its output volume has risen, and the second does not show up in any usual metric.
Four practices for the team version.
Rotate the hard work deliberately. Whoever owns a hard task teaches it to one other person rather than doing it. The teaching is the transfer, and it costs the strong person an hour per quarter rather than a week.
Require reasoning artefacts from everyone, including the strongest. A team where the strongest member delivers conclusions without reasoning teaches nobody and cannot be checked. This is the same artefact requirement from the guardrails section, applied upward.
Keep one capability deliberately unautomatable. A skill the team maintains by hand, on a schedule, chosen because the team would be badly exposed without it. The aviation practice again, at group level.
Run the capability register as a standing item. Twice a year, list the capabilities the team depends on and mark each as spread across several people, held by one person, or delegated to tools. The third category is the one that grows silently.
The failure that is specific to teams. Individual substitution is visible to the individual. Team substitution is not, because the work still gets done and the person who would have noticed has also stopped. The countermeasure is structural rather than motivational: an artefact requirement, a rotation, and a register. None of them depends on anyone noticing.
The manager's question to ask twice a year. Which capability would hurt most if it sat in one head at the same time as a tool outage, and who is the second person. If there is no second person, that is the next quarter's development work, and it is worth more than any tooling decision.
Feynman Summary: Explain It Like You Are 12
If you always let someone else carry your school bag, your arms do not get stronger. You do not notice anything at first. You just stop carrying it.
Using AI for everything is like that, but for your thinking. It feels great. You get things done faster. But the part of you that works things out stops getting practice, and you do not feel it happening.
Scientists tested this. People who wrote essays with AI remembered almost nothing about their own essays, even a few minutes later. And they felt sure they had done well. That feeling is the sneaky part.
The fix is not to stop using AI. It is to do some of the work yourself first, every time. Write your own first sentence. Try the problem before you ask. Pick one skill and keep practising it without help, like a pilot who still practises flying by hand.
Then check, once a month, whether you can still do the important things alone. If you can, keep going. If you cannot, do more of it yourself. That is all.
Mindmap: The Complete Picture
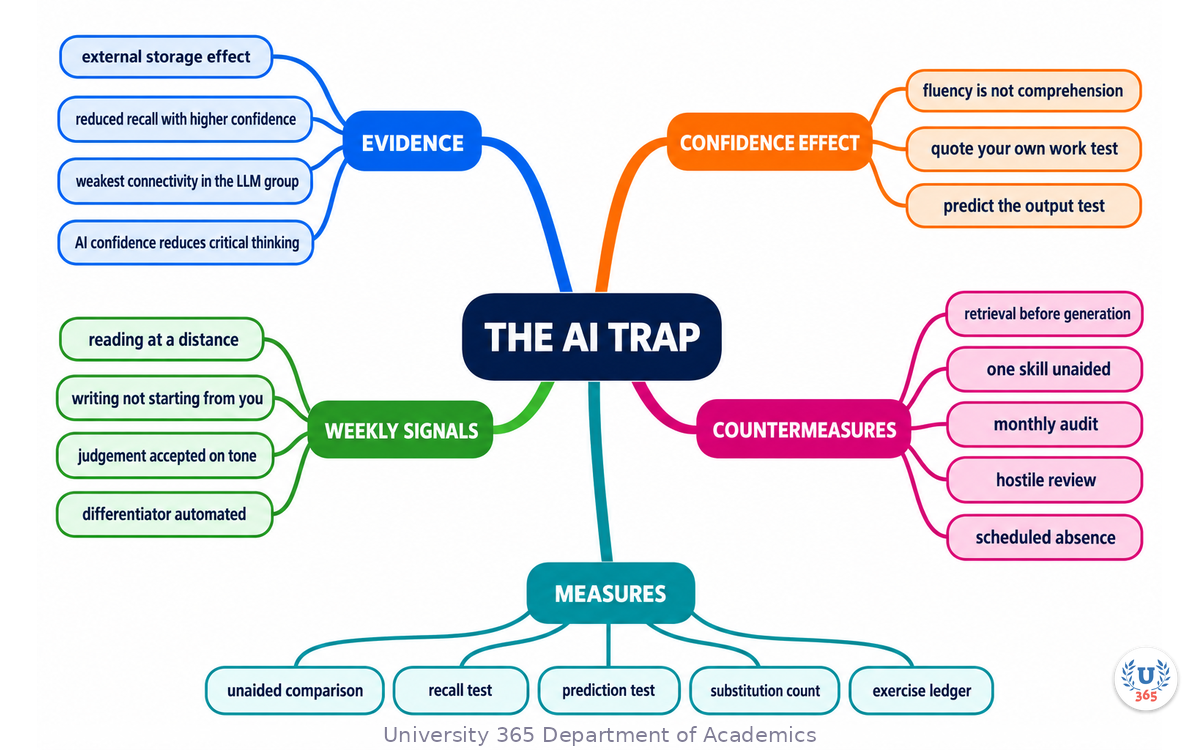
The mindmap shows the four evidence findings with their scope, the confidence effect and the two self-experiments, the six weekly places the pattern appears, the automation parallels with where they break, the seven countermeasures in priority order, the four structural guardrails, and the five measures with how to read them together.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: A Thirty-Day Cognitive Fitness Plan
Exercise: Measure, Reallocate, Re-Measure
This exercise gives you a baseline reading on five measures, then changes one thing, then re-measures. Budget fifty minutes to set up, then about twenty minutes a week for four weeks.
Part 1: The baseline (30 minutes).
Run the weekly audit from Step 3 on last week's calendar. List every AI-assisted task and mark whether you could have produced the core of it unaided. Count the ones you could not. That is measure 4.
Choose one significant recurring task. Do it once, start to finish, unaided. Keep the output and score it against your own criteria. That is measure 1.
Choose three things you learned in the last quarter. From memory, write two sentences on each with its main trade-off. Then check against the source. That is measure 2.
Before your next consequential request to an assistant, write down what you expect it to say. Compare when it answers. That is measure 3.
Part 2: Change one thing (10 minutes).
From Step 5, choose the single countermeasure that addresses the weakest of your four readings. Choose one, not four.
If your weakest reading was retention, choose retrieval before generation. If it was capability, choose one skill unassisted. If it was prediction accuracy, choose a month of reading the primary sources.
Write the specific rule, with a trigger and a frequency. "Before any document revision, I write the opening paragraph myself, every time." Not "I will try to write more myself."
Part 3: Run it for four weeks (20 minutes a week).
Keep the exercise ledger: one line a week naming the capability you exercised unaided and for how long.
Each week, do one hostile review of an assisted output. Write what you would challenge.
At the end of week four, re-run the reading you chose to improve. Compare it against the baseline.
Part 4: Decide (10 minutes).
If the reading improved, keep the rule and add the next countermeasure.
If it did not improve, the rule was too large. Halve it and run another four weeks. A rule that survives is worth more than a rule that is ambitious.
Write down the one capability you are not willing to lose, and put the practice in your calendar as a recurring appointment.
What to Observe
On the unaided attempt, where exactly did you reach for the tool, and what was happening in your thinking at that moment?
Did your prediction of the assistant's output match? Where it did not, was the difference in the facts or in the judgement?
How many of the substitution tasks from the baseline did you decide to keep delegating? Were those decisions deliberate or simply uncontested?
Did the rule you chose survive all four weeks, including the busy ones?
Applied AI Connection
You ran the measurement, chose the intervention, and decided what to keep delegating. An assistant can generate comparison material, check your recall against a source, and help you design the experiment. It cannot supply the unaided attempt, and the unaided attempt is the measurement. That division is CI = HI + (AI x HI): the human sets the standard and does the exercise, and the machine amplifies what the human brought rather than standing in for it.
Glossary
Term | Definition |
Cognitive offloading | Using an external system to reduce the mental effort a task requires, such as writing a note or delegating a summary. Neutral in itself; the cost depends on whether the process was the learning. |
Cognitive debt | The accumulation of long-term learning costs from repeated short-term offloading, a term coined in the MIT Media Lab essay-writing study. |
Automation complacency | Reduced attention and readiness in a person supervising a reliable automated system, documented extensively in aviation safety. |
Deskilling | The loss of a practised capability after it is delegated, so that the person can no longer perform the task unaided. |
Fluency illusion | Mistaking the ease of reading well-formed text for actual comprehension of it, the reason rereading feels effective and is not. |
Google effect | The shift of memory toward where information can be found rather than its content, when external storage is expected. Described in Sparrow and colleagues, Science, 2011. |
Retrieval practice | Actively recalling material from memory rather than rereading it, the mechanism that produces durable learning. |
Unaided audit | Doing one significant recurring task without AI assistance, on a schedule, to check whether your own capability is holding. |
Hostile review | Checking one assisted output as if a rival had submitted it, looking for what is unverified or generic. |
Capability register | A short quarterly list of the capabilities a role or team depends on, each marked as exercised, partially exercised, or delegated. |
Hippocampal spatial map | The brain's internal representation of an environment, built while navigating and reduced when directions are followed instead. |
CI-First | Co-Intelligence First: the U365 principle that the human is the orchestrator and the AI is the amplifier. CI = HI + (AI x HI). |
UNOP | University 365 Neuroscience-Oriented Pedagogy, the institutional learning method that sets the 25-minute focus block and the isochrone protocol. |
UP-Context-Engineering Method | University 365 Prompting-Context Method: reusable context, role, user persona and audience persona blocks applied to a class of tasks. |
5M2S | University 365's microlearning formula, 5 Minutes to Success, describing a unit designed to be read in about five minutes and to end in a decision. |
Quiz: TEST YOUR UNDERSTANDING
1. What does the research on cognitive offloading actually support?
A) Using AI makes people less intelligent in general
B) Offloading a specific process reduces the exercised capacity for that process while increasing confidence that it is intact
C) Offloading has no measurable effect on capability
D) Offloading always improves both output and capability
2. Why is the confidence effect the thing that makes the trap hard to see?
A) It makes the tools slower
B) It reduces the number of available models
C) Heightened confidence suppresses the checking that would reveal the gap
D) It only affects beginners
3. In the MIT Media Lab study, what happened to the group that wrote without tools first and was then given AI assistance?
A) They showed lower memory and weaker activation than the AI-first group
B) They showed higher memory recall and broader brain activation than the AI-first group
C) They refused to use the tool
D) Their results were identical to the AI-first group
4. What is the aviation analogy's practical translation?
A) Use automation less overall
B) Keep a deliberate, scheduled practice of the manual version of the skill
C) Abandon automation entirely for critical tasks
D) Trust the automation more, since it is reliable
5. Which single countermeasure is described as the one to keep if you keep only one?
A) Retrieval before generation
B) A weekly hostile review
C) The monthly unaided audit, because it detects whether you have a problem
D) Scheduled absence from the tools
Answers: 1-B, 2-C, 3-B, 4-B, 5-C
Related Resources
U365 INSIDE Publications
Lecture: Microlearning for an AI-Driven World: The learning programme that keeps the exercise in place
Lecture: Generative AI for a Superhuman You: The amplification model and where amplification becomes substitution
Lecture: Is ChatGPT Study Mode the Future of Learning? A Faculty Review: What AI tutoring does when tested honestly
External Resources
Your Brain on ChatGPT (MIT Media Lab preprint, June 2025): The four-month essay-writing study and its stated limitations
The Impact of Generative AI on Critical Thinking (CHI 2025, Microsoft Research and Carnegie Mellon): The 319-participant workplace survey on confidence and critical thinking
Google Effects on Memory (Sparrow, Liu and Wegner, Science, 2011): The original external-storage finding
A Role for Metamemory in Cognitive Offloading (Hu and colleagues, Cognition, 2019): Reduced internal recall with increased confidence after saving to a device
Hippocampal Activity During GPS Navigation (Peer and colleagues, Nature Communications, 2017): Reduced hippocampal activity when following directions
The science of effective learning with spacing and retrieval practice (Nature Reviews Psychology, 2022): The evidence base for retrieval as the protective practice
Related U365 Lectures (Coming Soon)
Lecture 5: Building a Personal Retrieval Schedule (UIC, AI Learning Series)
Lecture 6: Working With Agents Without Losing Your Judgement (UIC, AI Learning Series)
U.Copilot for This Lecture
Discuss this lecture with U.Copilot, your AI chat companion trained on this content.
Copy and paste the following prompt into the U.Copilot chat on university-365.com:
You are U.Copilot for Lectures, an AI chat companion specially trained on University 365 lecture content. You are helping a Fellow who just completed the lecture "Avoiding the AI Trap: Keeping Your Brain Sharp in the Age of Generative AI" from the AI Learning Series at the U365 Institute of Communication (UIC). Your role is to help the Fellow keep their capability while using AI well. You can: - Run the weekly audit with them and classify their tasks into those where the output matters and those where the process does - Check their from-memory explanations against the source and show them the gap, without filling it in for them - Score their predictions of what an output would say, and explain what a low score means - Help them design one countermeasure with a trigger and a frequency, small enough to survive a busy week - Draft the capability register for their role or their team - Review an output they produced with assistance, as a hostile reviewer, after they have written their own assessment Three rules you must keep. Never answer before the Fellow has attempted, because the retrieval is the learning. Never fill a gap in their knowledge with confident prose; name what is missing instead. And when they ask you to do a task unaided as part of an audit, do not do it for them, because the audit measures them, not you. Use the UP-Context-Engineering Method: provide context-rich, role-aware responses that account for the Fellow's role, the capabilities that matter most in it, and the skills they cannot afford to lose.
Next Steps
Here is what to do next, in order:
Run the weekly audit on last week and count the tasks you could not have produced unaided
Run the two self-experiments from Step 2 today: the quoting test and the prediction test
Choose one countermeasure, write it as a rule with a trigger and a frequency, and make it small enough to survive a bad week
Put the monthly unaided audit in your calendar as a recurring appointment, because no incident will prompt it
Write the capability register for your role, or for your team if you manage one, and mark each capability honestly
Answer the manager's question from Step 8: which capability would hurt most if it sat in one head during a tool outage, and who is the second person
Continue with Lecture 5 in this series, Building a Personal Retrieval Schedule, which turns the retention measure into a weekly practice
The tools are not the problem and abstinence is not the answer. Using them to remove the reps, without ever deciding to, is. Decide deliberately, measure honestly, and keep the exercise where you want the capability.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. Research findings cited here include a preprint that had not completed peer review at the time of publication, with a modest sample and a single task type, and its magnitudes should be treated as provisional. It is not medical or psychological advice. AI capability and tool behaviour change quickly; verify current technical details against primary sources before professional use.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Communication (UIC).
Lea Loringam, Dean of Communication, UIC
Signed for the academic year 2026.




Comments