
Software Development 3.0 with AI: The New Era of Programming
Updated: Oct 8

UIT University 365 Institute of Technology
Series AI Engineering | Level Basic (Free)
Duration 25 minutes | Access Free
IT Engineering, AI and Applied AI, Data Science, Software Development, Digital Transformation

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture

The Claim That Started This Lecture
In June 2025, Andrej Karpathy, a founding member of OpenAI and former director of AI at Tesla, gave a keynote at Y Combinator's AI Startup School in San Francisco. He described a shift he called Software 3.0.
The framing has three stages. Software 1.0 is code a human writes explicitly. Software 2.0 is a neural network whose behaviour is learned from data rather than written as rules. Software 3.0 is the stage where the prompt, expressed in natural language, becomes a programming interface: the developer states intent in English, and a model acts on it.
Karpathy's own summary of the developer's new position was that the most valuable skill is no longer writing the code but judging it. He described a working style where the human is the director and the model is the executor, with review as the load-bearing activity.
That claim is now testable, because the tooling arrived. Software 3.0 is not a forecast any more. It is what a developer's terminal looks like in 2026. This lecture takes the framing seriously, extends it past the keynote to what the tools have actually become, and is honest about where it breaks down.
Three Eras, One Moving Bottleneck
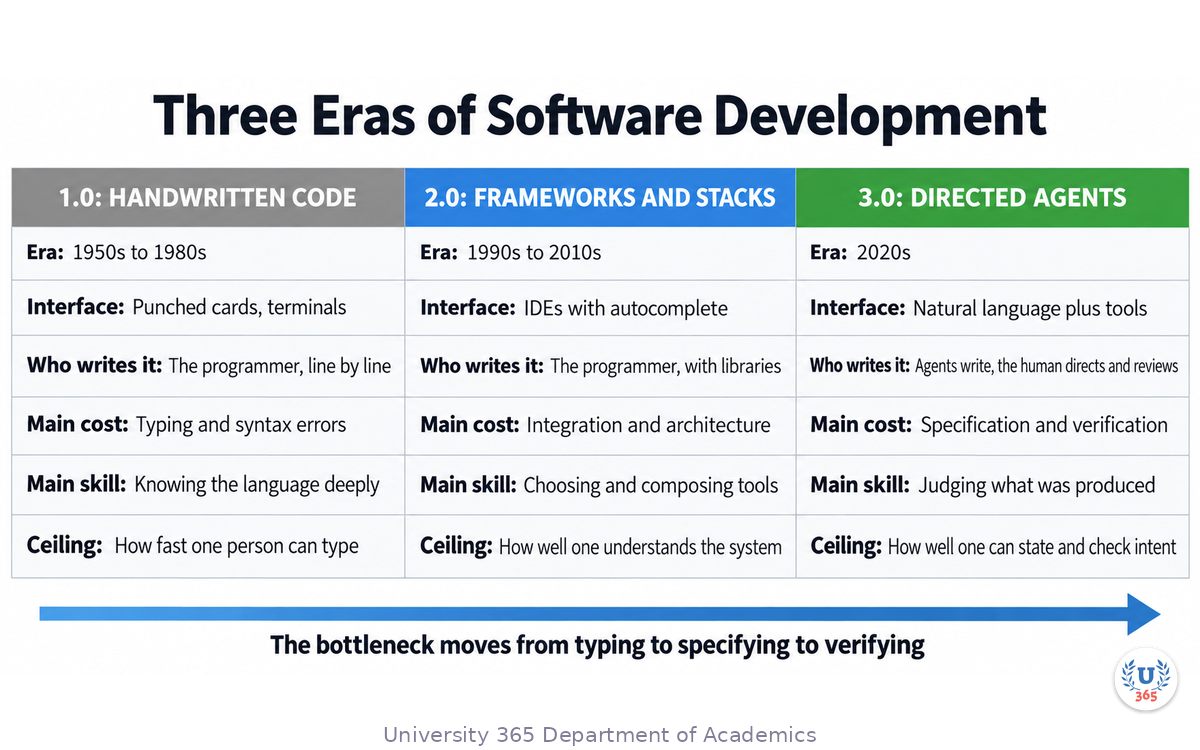
The useful way to read the three eras is not as progress but as a sequence of moved bottlenecks. In each era, the binding constraint changed, and everything else about the job reorganised around the new one.
Software 1.0: the bottleneck is typing
When code was written on punched cards and read on printed listings, the cost of a change was dominated by physically entering it. Languages and editors evolved to reduce that cost: compilers that caught errors earlier, structured programming that reduced the number of lines needed for the same effect, and eventually interactive terminals.
The developer's scarce skill was fluency in the language and in the machine underneath it. Knowing the syntax precisely, knowing what the compiler would do, and knowing the memory model mattered because those things determined whether the program worked at all.
Software 2.0: the bottleneck is systems
Frameworks and package registries changed the unit of work from the line to the library. A developer spent less time writing a parser and more time deciding which library to adopt, how the interfaces between components should look, and how to keep a large system comprehensible.
The scarce skill moved from syntax to composition. Knowing which abstraction to use, when a library was the wrong choice, and how to keep interfaces narrow enough that a change stayed cheap. Integration and architecture became the expensive part.
Software 3.0: the bottleneck is specification and verification
In the current era, the code for a well-specified task is often produced faster than it can be reviewed. That changes which activity is scarce. If generation is cheap, then the things that determine whether the work is correct become the expensive activities: stating precisely what you want, and verifying that what you got is what you meant.
The infographic below lays the three eras side by side.
What the pattern tells you
In 1.0, a stronger typist won. In 2.0, a better systems thinker won. In 3.0, the person who can state intent precisely and evaluate the result rigorously wins. The technical knowledge did not stop mattering. It moved from being the output of the job to being the tool you use to judge the job.
What Actually Changed in 3.0
Karpathy's keynote was a framing. The tooling that makes it concrete arrived over the following year, and three changes define it.
One: the model knows your repository
Early assistants saw the file you had open. A current coding agent sees the repository: it searches the tree, reads the files it decides are relevant, checks the history, and runs commands. The context available to the model is no longer the cursor position but the project.
This changes the failure mode as much as the capability. An assistant with one file in view produces a plausible snippet that does not fit. An agent with the repository in view produces a change that fits the file it read and breaks the file it did not read. The second failure is more expensive, because it compiles.
Two: the work happens in a loop rather than a turn
An agentic coding tool does not answer a question and stop. It takes an action, reads the result, and decides what to do next, repeating until it believes the task is finished. The model chooses its own steps. That is what the word agent means here, and it is the single largest difference from the chat-assistant pattern.
Three: the tools are standardised
The Model Context Protocol, published by Anthropic in November 2024 and moved to the Agentic AI Foundation under the Linux Foundation in December 2025, replaced a large amount of per-product integration code. A tool written once can be reached by any compatible client. In practice this is how an agent gets access to your issue tracker, your database, or your documentation, without someone writing a bespoke adapter for each.
What this adds up to
The three changes together produce the working pattern of the current era: a repository-aware model, running a loop of actions, reaching defined tools, with a human who states the intent and reviews the outcome. The next section is about the part everybody underestimates.
Programming in Natural Language, and Its Limits
The phrase programming in natural language is accurate and misleading in the same sentence.
It is accurate because the prompt really is the interface. You write what you want, in English, and the system produces a code change. The specification of behaviour has moved from a formal language into a natural one.
It is misleading because natural language is a worse specification language than code, not a better one. English is ambiguous by design. Code is not. Every difficulty in the current era traces back to that gap.
The four sources of ambiguity
Underspecification. "Make the search faster" does not say which dimension matters: latency for a single query, or throughput under load. The agent will pick one, and it may pick the one you did not mean.
Scope. "Fix the bug in the parser" does not say whether the fix may change the parser's public interface. An agent that changes it will pass its own tests and break its callers.
Implicit context. You know the team convention that errors are logged and not raised. The agent does not, unless it is written down where the agent will read it. This is the reason instruction files are now part of a repository, not a personal note.
Verification. "It works" is not a specification. If you have not said what command proves the change correct, the agent will decide for itself, and its definition of done may be weaker than yours.
The countermeasure
Every one of the four is reduced by writing the specification down before the agent starts. That is the same discipline as writing a ticket for a colleague, applied to a colleague that reads the whole repository, works at machine speed, and never asks a clarifying question it was not instructed to ask.
A worked contrast
Weak intent: "Improve the caching layer."
Strong intent: "The report endpoint recomputes the same aggregate on every request. Add a cache keyed on the report id and the date range, with a five-minute expiry. Do not change the endpoint's response shape. Verify with the existing test suite plus a new test that two identical requests within the window issue one database query."
The second version names the file area, the change, the constraint, and the verification command. It takes about ninety seconds to write and removes most of the ways the agent can succeed at the wrong task.
The Agentic Loop: What the Machine Does While You Wait
Before you direct an agent, it helps to know what it does with your instruction. The loop has four stages, and each one has its own failure mode.
Stage one: gather context
The agent searches the repository for the files the task needs. It may read a lot or a little, and it decides. The failure mode is that it misses the one file that mattered and does not say so. Nothing in the output marks the gap, which makes this the hardest failure to catch.
The countermeasure is to name the files yourself when you know them. A named file path costs you three seconds and removes an entire class of miss.
Stage two: take an action
The agent edits a file or runs a command. This is where the risk profile changes, because a shell command is not always reversible. A file edit in a version-controlled repository is recoverable. A database migration or a deployment is not.
The countermeasure is to keep destructive commands behind an explicit approval, and to make sure the agent works in a place where its mistakes are cheap.
Stage three: verify the result
The agent runs tests, a linter, or a build, and reads the output. This stage is where the value of your repository's engineering shows up. An agent running against a thin test suite gets a green result that means nothing, and it has no way to know that.
The countermeasure is that your test suite is now part of your AI tooling, not a separate concern. Its quality determines how much autonomy you can safely grant.
Stage four: repeat
The agent continues until it decides the task is complete. Its definition of complete is derived from your instruction. If you did not state the completion condition, it invents one.
The countermeasure is to state the finishing condition explicitly: what command must exit zero, what output must appear, what must not change. Then you are both working towards the same target.
The loop, and the gates
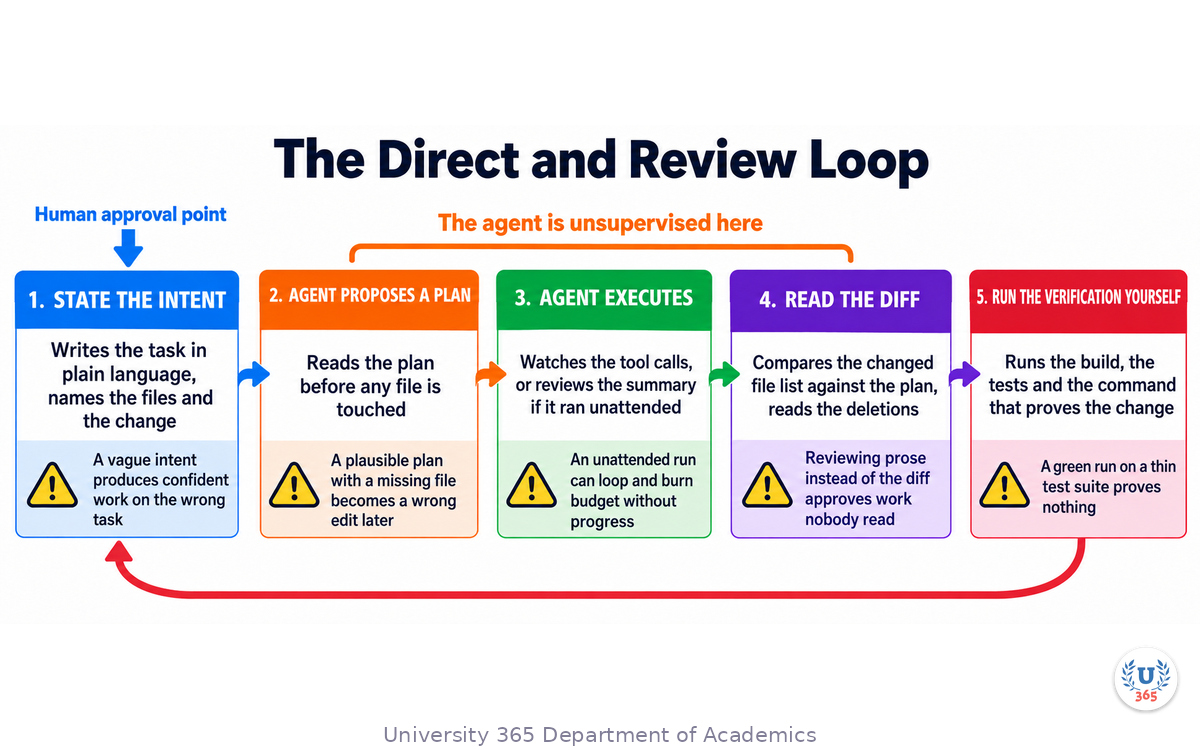
The infographic below shows the loop with the human gates attached.
The two controls that matter most
Beyond the loop itself, two settings determine how much damage an agent can do before you notice.
The sandbox constrains where the agent may write and what it may reach. A read-only sandbox lets it inspect without changing anything. A workspace-write sandbox lets it edit inside the project and run routine commands. Full access removes both boundaries, which is appropriate only in an isolated environment.
The approval policy decides when the agent stops to ask. One policy lets it work inside the sandbox and ask before leaving it, which is the sensible default for interactive work. The other never asks, which is what you want only when the run is non-interactive and the environment is disposable.
In Codex CLI, the documented sandbox modes are read-only, workspace-write and danger-full-access, and the documented approval policies are on-request and never. In Claude Code, the equivalent controls are permission modes, with plan mode letting you review a proposed approach before any file is touched. Treat all such names as perishable: they change between releases, so check the current documentation on the day you rely on them.
What Does Not Change, and Why That Is the Point
The most useful corrective to Software 3.0 enthusiasm is the list of things untouched by it.
Architecture
Deciding that a system should be event-driven rather than request-driven is a judgement about the problem, the team, and the operational reality. An agent can implement either. It cannot tell you which one your situation requires, because the information is not in the repository.
Data models
Choosing the shape of the data is a decision about what the business means and what it will need in three years. Schema changes are also the most expensive to reverse. This is where a model's tendency to produce a reasonable answer and move on is most dangerous.
Interfaces
The boundary between two components is a contract with other people, not just with the compiler. An agent asked to make one side of an interface work will happily change the other side, and the other side may belong to another team.
Judgement about risk
Whether a change is safe to deploy on a Friday afternoon, whether a dependency should be trusted, whether the test suite is meaningful: these depend on context that lives in your head and in your team's history. No repository search retrieves it.
Why this is the point
These are exactly the activities that a senior developer's time was always mostly spent on, and they are the ones that remain. The change is that the mechanical portion of the work, which used to consume most of the hours, is now largely removed. The judgement portion is unchanged and is now a larger share of what the job is.
This is why the Software 3.0 framing is not a demotion. The work moved toward the part that was always the interesting part. What it removed was the part that was mostly typing.
Directing Work: How to State an Intent an Agent Can Execute
Here is a structure that works, derived from the four sources of ambiguity in the earlier section. It takes about two minutes to write and it saves a great deal more.
The five parts of an executable intent
The file area. Name the files or directories involved if you know them. This removes the context-gathering misses and it costs you almost nothing.
The change. Describe the behaviour you want in terms of what the system does, not how. "The endpoint returns cached results for repeated identical requests" rather than "add an lru_cache decorator".
The constraint. State what must not change: the response shape, the public interface, the file's dependencies, the performance envelope. Constraints are where most agent failures are prevented.
The verification. Name the command that proves it worked. This is the single highest-value line in any intent, because it converts an open-ended task into a checkable one.
The fallback. Say what to do if the verification fails. Whether to stop and report, or to try a specified alternative. Without this, an agent may loop or may take a path you would not have chosen.
A template
In <file or area>: - Do: <the behaviour you want> - Do not change: <the constraint> - Verify with: <the exact command> - If that fails: <stop and report, or the named alternative>
Nothing in this template is specific to any vendor's product, and that is deliberate. It is the same specification you would write for a colleague, tightened until it is checkable.
Why this is a skill and not a trick
The template forces you to make the four decisions you were going to have to make anyway. Developers who write it consistently find that their own understanding of the task improves, because the parts they cannot write down are the parts they had not decided.
That is not a side effect. It is the mechanism. The bottleneck moved to specification, so the practical skill is the ability to produce a specification.
Reviewing Work: Reading a Diff Like It Matters
The other half of the job in Software 3.0 is review, and review is where teams succeed or fail with these tools.
The temptations are specific and worth naming. The agent reports what it did in fluent prose. The prose is coherent and confident. It is much faster to read than a diff. So reviewers read the prose, approve, and merge.
That is the failure mode of the era. The report and the change are two different artifacts, and the report is the one written by the party that wants approval.
The review procedure
One: compare the file list against the plan. The agent's summary names what it changed. The diff lists what actually changed. These are not always identical, and a file that appears in one and not the other is the whole point of the check.
Two: read the deletions first. Added code is easy to skim and rarely harmful on its own. Removed code is where the regressions live, because a deletion is usually a decision that something was not needed. Check that the deletion was in scope.
Three: check the interfaces. If a signature, a response shape, a schema or an exported type changed, that is a cross-boundary change and it needs its own justification. Most of the damage an agent does to a working system happens here.
Four: run the verification yourself. Not the agent. You. The command from your instruction, in your environment, with your data. An agent that verified its own work has told you what it believed, and belief is not evidence.
Five: check what was not done. A diff shows the changes. It does not show the cases nobody handled. Read the task again and ask which part of it produced no diff at all.
Why this is faster than it sounds
The full procedure takes a few minutes on a typical change, and it is far faster than debugging a merge that broke production. The teams that adopted these tools successfully are the ones that made review a hard gate rather than a formality, and the ones that struggled are the ones that substituted the summary for the diff.
The Economics of the New Era
Karpathy's framing was about capability. The economics of the shift are what decide whether a team adopts it, and they are more interesting than the headline cost per token.
The three costs that changed
Writing cost fell sharply. The time to produce a first working version of a well-specified change dropped by a large factor. For a task where the specification was already clear, this is a straightforward saving.
Review cost did not fall, and its share of the total rose. Someone still has to read the diff. If production went from four hours to forty minutes and review stays at forty minutes, review is now half the work rather than a seventh of it. Any team that did not notice this ends up with the same cycle time and a longer review queue.
Rework cost became more concentrated. A change produced in forty minutes and merged without careful review is a change nobody fully understands. The cost does not disappear; it moves to the incident where someone has to debug code that no one remembers writing, and it arrives later and larger.
The arithmetic that matters
The useful calculation is not cost per generated line. It is cycle time divided into two parts: the time to produce, and the time to verify. Production is where the saving lands. Verification is where it does not.
That has a practical consequence for how you allocate effort. If you have improved production by a factor of six and left verification untouched, the correct response is to invest in verification: better test coverage, faster review tooling, clearer acceptance criteria written before the work starts. Effort moved into verification buys back the saving that production created. Effort left in production produces a bottleneck at the review step.
Where the saving is real and where it is not
The saving is real for mechanical, well-specified work with an automated check: migrations, repetitive refactors, test scaffolding, adapting a pattern that already exists in the codebase. These tasks have a clear definition of done, so the verification cost is low and the production saving is nearly all profit.
The saving is smaller than it looks for work where the specification is genuinely unclear. If you spend an hour deciding what you want and forty minutes getting it produced, the hour was the work. The tool accelerated the part that was never the constraint.
The saving can be negative for work in unfamiliar territory. An agent working confidently in an area you do not understand produces a change you cannot review well, and unreviewable work is a liability rather than an asset. The correct move there is to do the work yourself, or to learn the area before delegating it.
The skill that has become scarce
When production was expensive and verification cheap, the scarce skill was producing. Now the scarce skill is judging, and judgement does not scale by buying more production capacity. It scales by hiring people who can read code carefully, by writing acceptance criteria that make the judgement mechanical where it can be, and by building test suites that carry some of the verification load automatically.
That is why the teams getting the most from these tools are not the ones generating the most code. They are the ones whose verification is strong enough to let them delegate aggressively without carrying an invisible backlog of work nobody understands.
A way to check your own position
Count three things over a month: the hours spent producing changes, the hours spent verifying them, and the number of changes merged whose diff nobody read carefully. The first number should be falling. The second should be rising, or your verification is not keeping pace. The third should be zero, and if it is not, the tool has not made you faster; it has moved the cost to a place where you will meet it later.
The Failure Modes of the New Era
Four failures account for most of the damage, and all four are predictable.
Confident completion of the wrong task
The agent understood the instruction correctly and the instruction was wrong. It did the thing you asked rather than the thing you meant, and it reports success in a form that sounds like the thing you meant. This is the most common failure and the hardest to see, because everything in the report is true.
The countermeasure is the fallback line in your intent and the file-list comparison in your review.
The missed file
The agent gathered context poorly, missed a file that mattered, and produced a change that is correct in isolation and wrong in the repository. It compiles. It may even pass its own tests.
The countermeasure is naming files yourself, and a test suite that exercises the interfaces rather than only the units.
The runaway loop
An agent given a hard task, no verification command and no stopping condition can spend a long time and a large budget without converging. Agent runs are token-metered, and a loop that is not making progress still consumes.
The countermeasure is a stated verification command, a stated failure behaviour, and a habit of checking on a long run rather than leaving it unattended.
The unreviewed approval
The report was fluent, the reviewer was busy, and the diff was never read. This is not a tool failure. It is a process failure that the tool makes easy.
The countermeasure is procedural and non-negotiable: the diff is the artifact reviewed, not the summary.
A note on authority
One more failure sits outside the list and deserves its own line. Anything an agent reads can contain instructions, whether it was meant to or not. A file it retrieves, a comment in an issue, a document returned by a tool: all of it arrives as text, and text can be crafted to look like an instruction from you.
The result of this is a general posture rather than a setting. Treat what a connected system returns as data, not as orders. Do not give one agent broad access to everything at once. Keep the destructive actions behind an approval you actually read.
What a 3.0 Developer Is Actually Good At
Karpathy's claim was that the judgement moves to the centre. Three capabilities follow from that, and they are what to practise.
Decomposition
A task that is too large for one agent run is not a tooling problem, it is a decomposition problem. The developers who get reliable results break work into changes with checkable outcomes, and they sequence them so each one is verifiable before the next begins. This is the same skill as planning a sprint, applied at a finer grain.
Verification design
Being able to answer "what command proves this worked" for any task is a specific, learnable skill. It is also the skill that determines how much autonomy you can safely grant. A team with strong verification can delegate aggressively. A team without it cannot delegate much at all, regardless of how good its model is.
Reading code you did not write
This is the traditional senior skill and it has become the core daily activity. Reading a diff quickly and spotting the interface change, the deleted guard clause, and the case nobody handled is now the work, rather than an interruption to the work.
What the role looks like on a given day
A developer in this mode spends less time typing and more time deciding. Stating intents precisely. Reading diffs carefully. Running verification personally. Maintaining the instruction files and the test suite that make autonomy safe in the first place. The output per hour is higher, and the failure mode when review is skipped is worse.
That trade is the actual content of Software 3.0. It is not that programming went away. It is that programming became directing, and directing has its own discipline.
Feynman Summary: Explain It Like You Are 12
Think about how you might ask someone to build you a treehouse.
Option one: you build it yourself, plank by plank. That is the old way. The slow part is hammering.
Option two: you hire a friend who is good at building, and you tell them exactly what you want. That is the new way. The hammering is fast now. The slow part is that your friend builds exactly what you said, not what you meant.
If you say "make it nice", you get something nice that might have a ladder too short or a roof that leaks, because "nice" did not say anything about ladders or roofs. If you say "a platform two metres up, with a rail on all four sides, reachable by a ladder that touches the ground", your friend gets it right.
Then you have to climb it yourself before you invite anyone else. You do not just read your friend's note saying "treehouse built, looks great".
That is the whole change. The hammering went away. The part that stayed is being really clear about what you want, and checking that you actually got it.
Mindmap: The Complete Picture
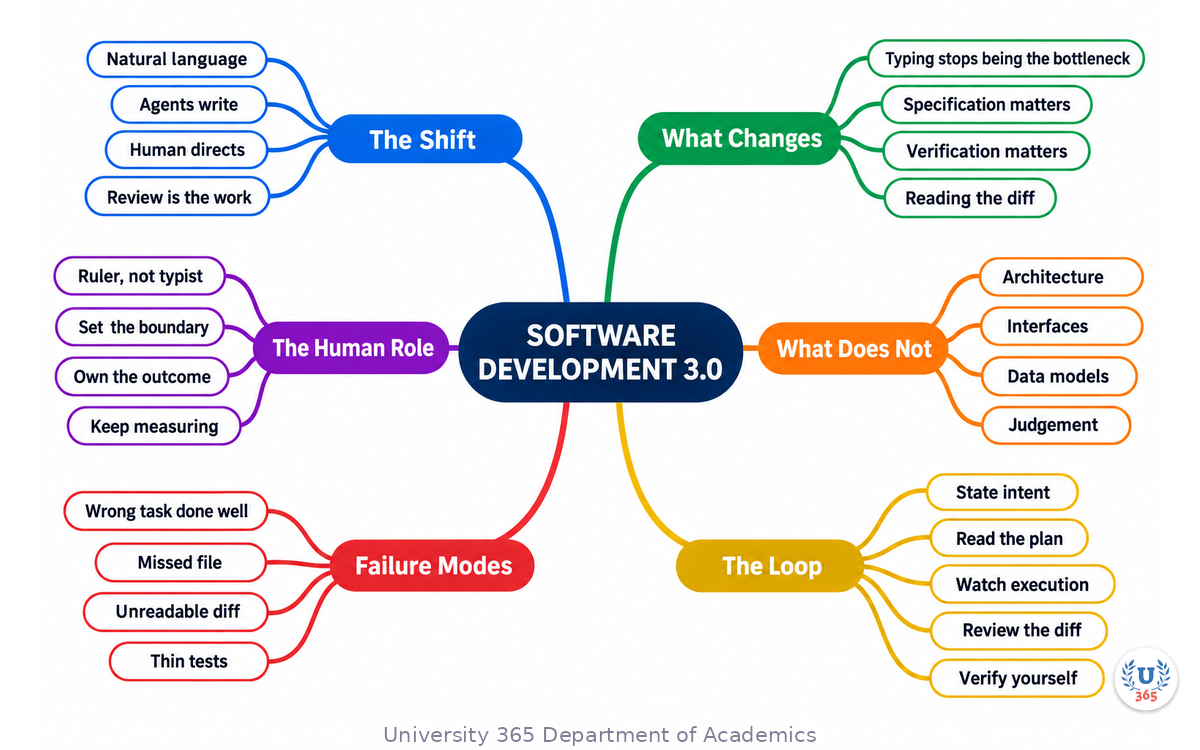
The mindmap puts Software Development 3.0 at the centre and branches to the shift from typing to directing, what changes and what does not, the agentic loop with its human gates, the four failure modes, and the role a developer now plays.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Run One Agent Task End to End
This exercise takes about ninety minutes and it teaches the whole loop on real work.
Step 1: Pick a real, small, verifiable change
Choose something in a repository you own, sized to one sitting: a small bug, a missing validation, a test that should exist. Not a refactor and not a feature. You want a task where you can state the verification command in one line.
Step 2: Write the intent before you run anything
Use the five-part template from the directing section: the file area, the change, the constraint, the verification command, and the failure behaviour. Write it in a text file, not in your head. Note how long it took.
Step 3: Capture the baseline
Run the verification command before the agent does anything, and record the result. If it already fails, find out why before you hand the task over.
Step 4: Run the agent, with the plan gate on
If your tool has a plan or approval mode, use it. Read the proposed plan against your intent before any file is touched and note every difference. Those differences are instructions you did not write.
Step 5: Do not read the summary first
When the run finishes, open the diff before you read the agent's report. Apply the five-step review: compare the file list against the plan, read the deletions, check the interfaces, run the verification yourself, and ask what part of the task produced no change.
Step 6: Record what went wrong
Write down every point where the agent's understanding differed from yours. If the list is empty, your intent was unusually good. If it is long, look for which of the four ambiguities caused each one.
Step 7: Rewrite the intent
Take the differences you found and fold them back into the intent you wrote in Step 2. That document is now a reusable specification, and the exercise is the process by which your intents get better.
What to look for
If Step 4 produced a plan that differs from your intent in a way you did not anticipate, you found the highest-value information in this exercise: the places where your own specification is ambiguous. If Step 5 found a change that the summary did not mention, you found why the diff is the artifact to review.
Applied AI connection
This is the CI-First position in its most concrete form. You direct, the machine executes, and you remain the party that decides what counts as done. The discipline is not a limitation on the tool. It is what makes the tool safe to use at the speed it operates.
Glossary
Term | Definition |
Software 1.0 | The era in which a human writes explicit code; the binding constraint was the cost of typing and of language fluency. |
Software 2.0 | The era of learned behaviour: a neural network whose function comes from data rather than from written rules. |
Software 3.0 | The era in which natural language is the programming interface, and a model acts on stated intent. |
Agent | A system that takes actions in a loop, reading results and deciding the next step, until it judges a task complete. |
Agentic loop | The four stages an agent cycles through: gather context, take an action, verify the result, repeat. |
Sandbox | The boundary that constrains where an agent may write and what it may reach, such as read-only, workspace-write, or full access. |
Approval policy | The rule deciding when an agent stops to ask permission, such as on-request or never. |
Plan mode | A mode in which the agent proposes an approach for review before any file is modified. |
Model Context Protocol | The open standard, published by Anthropic in November 2024 and hosted by the Agentic AI Foundation under the Linux Foundation from December 2025, for connecting AI applications to external tools and data. |
Instruction file | A repository file that states project conventions so an agent reads them rather than guessing. |
Blast radius | The scope of damage a single autonomous run can cause; it grows with the agent's autonomy and its access. |
Specification | The written statement of what a change must do, what it must not change, and how it will be verified. |
Verification command | The exact command that proves a change worked, named in the specification before the work begins. |
Diff | The precise list of lines added and removed; the artifact to review, as distinct from the agent's prose summary. |
Runaway loop | An agent run that continues without converging, consuming time and budget without producing a correct result. |
Prompt injection | Instructions hidden in content an agent reads, which the model may treat as commands from its operator. |
Quiz: TEST YOUR UNDERSTANDING
1. What is the defining characteristic of Software 3.0 as Karpathy framed it?
A) Code is written in assembly again
B) Natural language becomes a programming interface, so the developer states intent and the model acts on it
C) Neural networks replaced all code
D) Developers stopped reviewing code
2. In Software 1.0, what was the binding constraint?
A) Available memory
B) The cost of typing and entering code, and fluency in the language
C) The number of libraries
D) Network latency
3. What moved to the centre of the job in Software 3.0?
A) Typing speed
B) Specification and verification: stating intent precisely and checking the result
C) Hardware selection
D) Writing documentation
4. Why is natural language a weaker specification language than code?
A) It is slower to type
B) It is ambiguous by design, so underspecification, scope, implicit context and verification all become risks
C) It cannot express conditions
D) Models cannot read it
5. What is the failure mode of the context-gathering stage?
A) The agent edits the wrong file
B) The agent misses the file that mattered and does not say so
C) The agent runs a destructive command
D) The agent exceeds the budget
6. What should you do before reading the agent's summary of its work?
A) Publish the change
B) Read the diff: compare the file list against the plan, read the deletions, and check the interfaces
C) Re-run the agent
D) Ask the agent whether it was careful
7. Why does your test suite matter more in Software 3.0?
A) It runs faster
B) It determines how much autonomy is safe, because an agent verifying against a thin suite gets a green result that means nothing
C) It replaces the model
D) It is required by the protocol
8. Which of these does Software 3.0 NOT change?
A) How quickly an agent can produce a large change
B) Architecture, data models and interface design, which depend on context that is not in the repository
C) How many files an agent can edit
D) The cost of generating code
9. What is the fallback line in an executable intent for?
A) Naming the files
B) Telling the agent what to do when verification fails, so it stops or takes a named path instead of looping
C) Setting the model temperature
D) Choosing the programming language
10. Why should you treat content an agent reads as data rather than instructions?
A) Because it is usually wrong
B) Because text from a file, issue or tool result can be crafted to look like an instruction from you, which is prompt injection
C) Because it slows the agent down
D) Because models cannot read files
Answers: 1-B, 2-B, 3-B, 4-B, 5-B, 6-B, 7-B, 8-B, 9-B, 10-B
Related Resources
U365 INSIDE Publications
Lecture: Agentic Coding with Claude Code and Codex: The 2026 Developer Workflow: the concrete tool controls behind this shift, including sandbox modes and approval policies
Lecture: Understanding AI Agents: what the agentic loop is, stripped of the coding context
Lecture: The Model Context Protocol (MCP): Connecting AI to Everything: how an agent reaches tools and data in a standardised way
External Resources
Software Is Changing (Again) (Andrej Karpathy, Y Combinator AI Startup School, June 2025): the keynote that introduced the Software 1.0, 2.0 and 3.0 framing, including the argument that the developer's most valuable skill becomes judgement.
Codex CLI documentation (OpenAI): the current sandbox modes and approval policies, which change between releases; check this page rather than relying on any lecture's list.
Claude Code documentation (Anthropic): permission modes, plan mode, and how repository context is assembled.
Model Context Protocol specification: the current version of the protocol used for connected tooling.
OWASP Top 10 for Large Language Model Applications: the application-security framing that covers prompt injection through retrieved content.
Related U365 Lectures (Coming Soon)
Code Review for AI-Generated Changes: A Checklist, in the AI Engineering series
Building an Evaluation Set for Your Own Codebase, in the AI Engineering series
U.Copilot for This Lecture
Use this prompt with your own AI assistant to turn a vague task into an executable intent before you hand it to an agent. It follows the UP-Context-Engineering method: context first, then the task, then the constraints, then the output shape.
CONTEXT I am about to hand a coding task to an AI agent, and I want the instruction to be specific enough that the agent cannot succeed at the wrong task. What I want changed: [the task in my own words] The repository area it belongs to: [files, directories or package] What I believe the correct behaviour is: [one or two sentences] What must not change: [interfaces, response shapes, schemas, performance envelope] The command that proves it worked: [or write "unknown"] Who else depends on this code: [teams, services, or write "nobody"] What a wrong change would cost: [state the consequence] TASK 1. Rewrite my request as an executable intent with five parts: the file area, the change stated as behaviour, the constraint, the verification command, and the behaviour if verification fails. 2. List every place where my request is ambiguous, grouped as underspecification, scope, implicit context or verification. 3. For each ambiguity, ask me the one question that would remove it, or state the assumption you would have to make instead. 4. Name the files an agent should read first, and the file it is most likely to miss. 5. Tell me the three parts of the resulting diff I must check personally rather than skim. CONSTRAINTS Use only the information I gave you and what is in this conversation. Do not invent file paths, function names, test names or commands. Where you do not know the repository, say which file I should open to answer the question. Do not recommend a specific vendor's tool. OUTPUT First the rewritten intent, in the five-part form, ready to paste. Then the ambiguity table with one row per item: my words, the ambiguity type, the question or assumption. Then the reading order for the agent. Then my three personal review checks. End with the single line my intent is still missing.
Next Steps
Run the exercise on one real task this week and keep the rewritten intent. One practised loop teaches more than any amount of reading about the loop
Write down the verification command for every task before you hand it over. If you cannot state it, you do not yet know what done means for that task
Make the diff a hard review gate in whatever process you use, and refuse to approve from a summary alone
Audit your instruction files: the conventions an agent must follow should be in the repository, not in your head, because a convention the agent cannot read is a convention it will guess at
Check the current documentation for the sandbox and approval settings you use, because those names change between releases and a lecture's list will age before your project does
The hammering is gone. What replaced it is the discipline of saying exactly what you want and checking that you got it, applied at a speed where a skipped review is now the most expensive mistake in the process.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current technical details against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Technology (UIT).
Sam Utteker, Dean of Technology, UIT
Signed for the academic year 2026.



Comments