
The Complete History of AI: From Turing to Today
Updated: Oct 8

UIT University 365 Institute of Technology
Series AI Foundations | Level Basic (Free)
Duration 25 minutes | Access Free
IT Engineering, AI and Applied AI, Data Science, Software Development, Digital Transformation

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture

Why the History Matters to You
Every tool you use this week is the survivor of a selection process that lasted seventy years, and most of it failed. The field has been pronounced finished, abandoned, revived, and pronounced finished again. Knowing which ideas survived, and why, tells you which of today's claims to trust.
There is a practical reason to read this. The vocabulary in current AI reporting borrows from every era at once. A product page may describe a transformer model running an agentic loop over a retrieval index. Each of those words came from a different decade and answered a different failure. If you do not know what each layer was invented to fix, you cannot tell which parts of a system are load-bearing.
This lecture walks the whole line: the question Turing posed, the first program that made people believe machine intelligence was a decade away, the two collapses that followed, the statistical turn that quietly replaced rule-writing, the deep learning decade, and the general-model era you are living in now. It ends with the pattern the field repeats, and what that pattern says about the model you are about to build on.
The shape of the line
One habit helps before you start. Read the history as a sequence of bottlenecks, not as a sequence of heroes. Each era had a method that looked sufficient and a constraint nobody had solved yet. Compute, data, algorithms, and evaluation took turns as the thing that stopped progress. When you know which constraint is binding, a great deal of the loudest news becomes predictable.
The Foundations: Computation and the Question of Machine Thinking
The history starts with a formal question, not a machine. In 1936 Alan Turing described a theoretical device that could compute anything computable, by reading symbols off a tape, changing them according to a table of rules, and moving along the tape. The device was never built as described. Its purpose was to prove a limit: some problems cannot be solved by any mechanical procedure at all.
That result matters twice. It gave computer science its definition of computation, and it set the boundary of what a machine can be asked to decide. Everything afterwards is engineering inside that boundary.
The imitation game
In 1950 Turing published a different paper, asking whether machines can think. He replaced the unanswerable question with a testable one. Put a person at a terminal, let them exchange text with either a human or a machine, and see whether the person can tell. This is the imitation game, known now as the Turing test.
The move was methodological. Instead of arguing about the nature of thought, he defined an observable behaviour and let the argument follow the evidence. That habit recurs across the whole history, and it is the reason evaluation benchmarks exist today.
In 1943, in between those two papers, Warren McCulloch and Walter Pitts published a mathematical model of a neuron as a threshold unit: it sums weighted inputs and fires if the sum crosses a level. This is the ancestor of every neural network in use now, and it appeared before there was a computer to run it on.
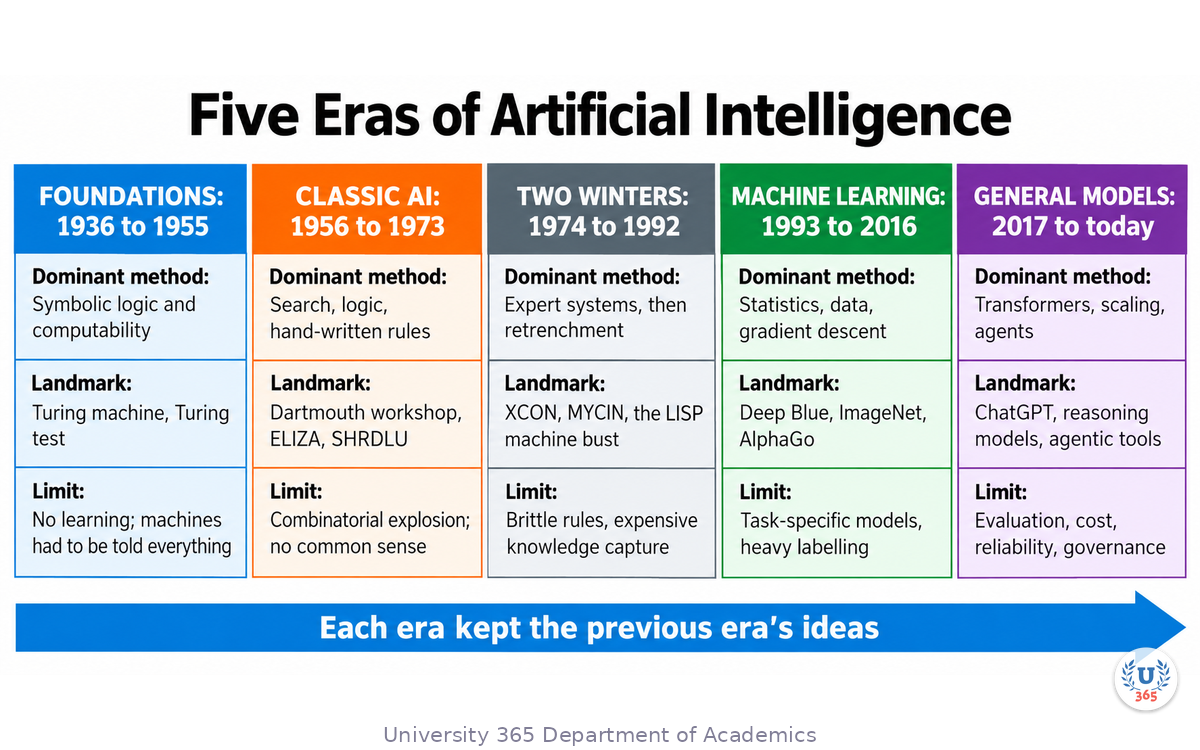
The infographic below lays the five eras side by side, with the method, the landmark system and the characteristic limit of each.
The 1956 workshop
In the summer of 1956, a group met at Dartmouth College for a two-month workshop. The proposal that funded it used the phrase artificial intelligence and claimed that a careful group could make significant progress on the problem of making machines use language and form abstractions. The participants included John McCarthy, Marvin Minsky, Claude Shannon, and Herbert Simon. Their expectation was that a generation of work would settle the question.
Dartmouth is conventionally called the founding event. What it founded was a research programme with a specific bet: that reasoning could be captured as symbol manipulation, and that if the symbols were right, thinking would follow.
The early systems and their limits
Two programs from this era are still worth knowing.
The Logic Theorist, written by Allen Newell and Herbert Simon in 1956, proved theorems from the Principia Mathematica. The General Problem Solver, from 1957, attempted to separate the strategy of problem solving from the domain it was applied to. Both were demonstrations that a machine could manipulate abstractions.
The limit showed up quickly. Herbert Gelernter's Geometry Theorem Prover from 1959 managed its search space by tracking what it had already tried. Programs that searched without that discipline met the combinatorial explosion: each extra step multiplied the number of states to examine. A method that worked on a toy problem collapsed at realistic size.
This is the first appearance of a pattern that repeats: the method was correct, the constraint was something else.
Classic AI: The First Promise
If the 1950s produced the founding bet, the 1960s produced the optimism.
In 1965, Hubert Dreyfus published a critique arguing that the symbolic approach rested on assumptions about human reasoning that would not hold. The funding agencies had other information: demonstrations kept arriving, and research groups kept promising that natural language translation, general problem solving, and machine vision were within reach.
In 1966 the ALPAC report, commissioned by US funding agencies, reviewed machine translation and found that the results did not justify continued investment at the level planned. Funding was reduced sharply. This is the first recorded instance of a gap between a demonstration and a working product closing a research programme.
ELIZA and the illusion problem
In 1966 Joseph Weizenbaum wrote ELIZA, a program that mimicked a psychotherapist by reflecting a user's own statements back as questions. It had no model of the conversation and no understanding of the words. Several users, including Weizenbaum's own secretary, asked him to leave the room so they could talk to it in private.
Weizenbaum spent much of his later career arguing against the interpretation people took from his own program. The lesson he drew is worth keeping in view now: people read comprehension into a system that reflects their own language back at them. That reading is a property of the reader, not of the program, and it has recurred with every generation of conversational system since.
SHRDLU and the blocks world
In the late 1960s Terry Winograd built SHRDLU, a program that understood instructions about a small world of coloured blocks, could answer questions about it, and could explain why it could not perform an impossible action. In its own world it was a genuine success.
Its limitation was exactly that phrase. The rules were written for one world by hand, and outside it the program knew nothing. Scaling it meant writing more rules, and the effort per new domain did not fall.
By 1969 Minsky and Papert's work on perceptrons had also made the point that a simple single-layer network could not represent certain functions, including some elementary logical relations. That result was read much more broadly than it was stated, and it contributed to the shift of money and attention away from connectionism for nearly two decades.
What the era got right
The 1960s produced symbolic reasoning, the first knowledge representation schemes, and the first serious work on search and planning. Every later hybrid system that combines a language model with a planner and a symbolic checker is reusing those ideas under new names. The era failed on the scaling question, not on the concepts.
The First Winter: When the Money Stopped
The 1969 Mansfield Amendment in the United States restricted defence funding to research with a direct military mission. In 1973 the Lighthill report in the United Kingdom concluded that AI research had failed to deliver on any of its earlier promises and recommended that funding be limited to two universities. British AI research was cut back severely, and the effect reached the United States through the funding agencies.
Between roughly 1974 and 1980, the field contracted. Grant programmes were closed, groups were dissolved, and the term itself became difficult to put in a proposal.
Why it happened
The mechanism was not a single bad result. Three expectations had been set publicly and none was met on time.
The first was machine translation. The second was a general-purpose reasoning system that would work outside a hand-built world. The third was machine vision, which had been treated as a summer project problem and turned out to be a decade-long research programme.
The critical detail is that progress did continue during the winter. Work on representation, on logic programming, and on early connectionism kept going at lower volume. The collapse was in funding and in public credibility, not in the ideas.
The habit to take from it
A field that announces its timeline publicly creates a schedule it will be judged against. When the schedule slips, the reaction is not proportional to the slip. This is worth remembering when reading any capability forecast today. The forecast is not usually wrong about direction. It is usually wrong about the interval between a demonstration and a deployment.
Expert Systems and the Second Collapse
The recovery came from a narrower ambition: stop trying to build a general reasoner, and encode the knowledge of a specialist instead.
An expert system holds a knowledge base of rules supplied by human specialists and an inference engine that applies them to a case. The method worked well enough to sell.
MYCIN, developed at Stanford in the 1970s, recommended antibiotic treatment for blood infections. In evaluations it performed at the level of human specialists on the cases it covered. It was never deployed for routine care, partly because the surrounding questions of liability and clinical workflow were unsolved.
XCON, developed at Carnegie Mellon for Digital Equipment Corporation, configured orders for VAX computer systems. By the mid-1980s it was reported to save the company a substantial sum annually and became the demonstration that the technology had commercial value. The expert-systems industry grew through the decade.
The knowledge acquisition bottleneck
Then the cost per rule became the problem. Each rule had to be extracted from an expert, written down, tested, and maintained when the underlying product or procedure changed. XCON grew to several thousand rules, and updating it became an engineering project in its own right.
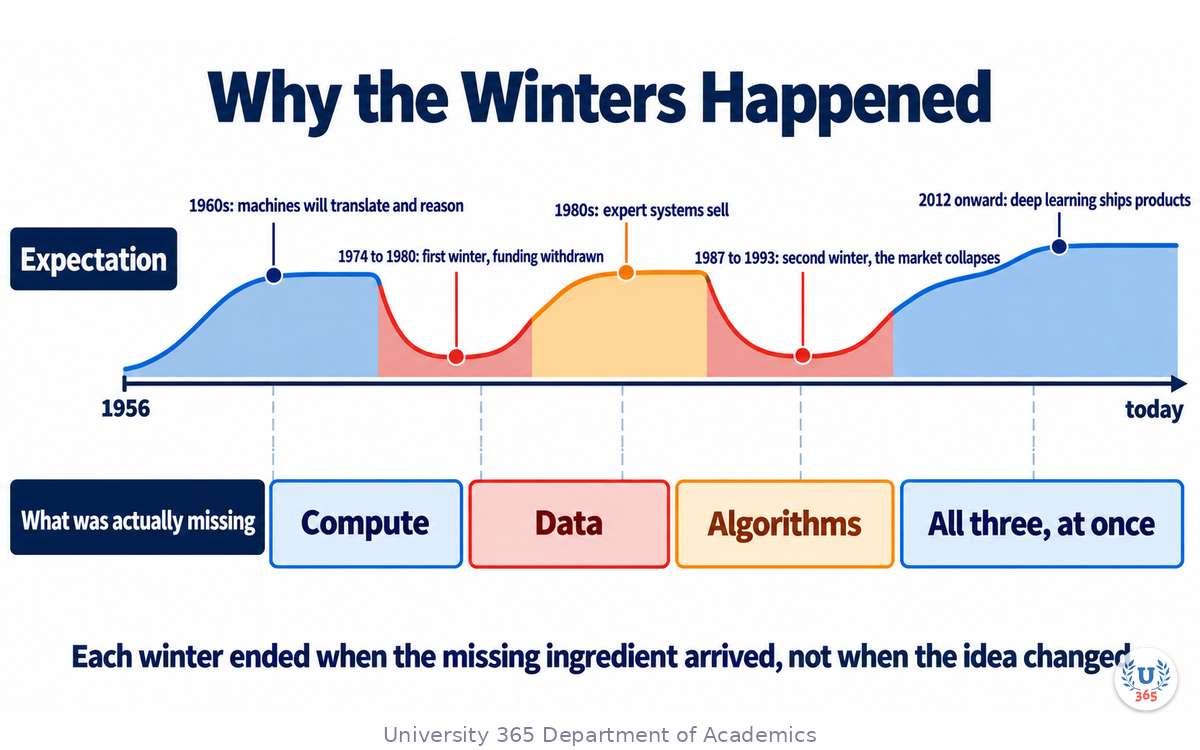
The infographic below compares the expectation against what was actually missing across the same timeline, which is the mechanism behind both winters.
In 1984, John Hopfield published work showing that a class of recurrent networks had stable dynamical states, which revived interest in neural computation. Work on backpropagation, popularised around 1986, showed how to train a multi-layer network with gradient descent. The learning route had become viable, and the rule-writing route was visibly expensive.
The 1987 collapse
The expert-systems market was built on specialised hardware, the LISP machine, sold at a large premium. When general-purpose workstations became fast enough to run the same software, that premium disappeared. In 1987 the market for LISP machines collapsed, and with it much of the specialised AI industry.
Estimates at the time put the loss of the specialised AI hardware market in the hundreds of millions of dollars within roughly a year. The second winter followed the same shape as the first: real capability, a scaling cost nobody had priced, and a funding reaction larger than the technical setback.
The Statistical Turn: Learning from Data
The recovery this time did not come from a grand claim. It came from the decision to stop writing rules and start estimating them from examples.
The shift is best understood through a change in the question. The symbolic era asked how to represent knowledge. The statistical era asked how to minimise error on data the system had not seen during training. That is a narrower and more measurable objective, and measurability turned out to matter as much as the mathematics.
Four systems that mark the turn
In 1997, IBM's Deep Blue defeated the reigning world chess champion Garry Kasparov. The machine combined substantial parallel search with hand-tuned evaluation. It demonstrated that a carefully engineered system could beat the best human in a bounded domain, and it did so mainly by searching, not by learning.
In 2011, IBM's Watson won the television quiz show Jeopardy against its strongest human champions. Watson combined natural language processing, information retrieval over a large corpus, and a confidence-scoring stage that decided when to answer. Its design was explicitly hybrid, and the confidence calibration was as important as the question answering.
In 2011, Apple shipped Siri, which put speech recognition and a narrow task assistant in front of a mass audience. Its accuracy depended on statistical speech models trained on large amounts of audio, not on grammatical rules.
In 2012, a neural network called AlexNet won the ImageNet image classification competition with a large margin over the runners-up. It was a deep convolutional network trained on graphics processors. Error rates that had fallen slowly for years dropped sharply in one entry.
The three ingredients
AlexNet did not invent the convolutional network. The architecture had been described decades earlier. What changed was that three ingredients arrived together.
Compute came from graphics processors designed for video games, used as general matrix hardware. Data came from the internet: ImageNet alone provided over a million labelled images. Algorithms had improved through decades of quiet work on activation functions, regularisation, and training procedures.
Every large jump in this history has the same anatomy. A long-standing idea meets the missing ingredient, and a decade of slow measurement looks like an overnight change.
Deep Learning Arrives: 2012 to 2017
After 2012 the sequence of results accelerated.
In 2014, generative adversarial networks showed that two networks competing against each other could produce realistic images, and the technique spread across media generation. In the same period, sequence-to-sequence models with attention made machine translation quality jump, and speech recognition on consumer devices became good enough to be used in public.
In 2016, DeepMind's AlphaGo defeated Lee Sedol at Go, four games to one. Go had been treated as the hardest classical board game for machine play because the branching factor is far too large for exhaustive search and because position evaluation is difficult to express as a rule set. AlphaGo combined a learned policy network, a learned value network, and Monte Carlo tree search, and trained further by playing itself.
In 2017, AlphaGo Zero removed the human game records from the training entirely and learned from self-play alone, which established that the learning procedure, not the human data, was doing the work.
What made the period work
Each of these systems had a measurable objective, a large dataset, and enough compute to run many experiments. The cycle from idea to measurement to revision was short, which is what distinguishes a working research programme from a promising one.
The limits were also visible. Every model was trained for one task. A translation model could not describe a photograph. A game model could not do anything else. The result was a portfolio of narrow systems, each expensive, each requiring its own labelled data.
That portfolio is exactly the constraint that the next architecture removed.
The Transformer and the General Model Era
In 2017 a group at Google published a paper titled Attention Is All You Need, describing an architecture built entirely on attention rather than on recurrence or convolution. The transformer processes a sequence as a set of positions that attend to each other, which allows training to be parallelised across very long inputs.
That last property is the reason for everything that followed. Recurrent networks had to process a sequence step by step, which limited how much hardware could be applied at once. The transformer removed that limit, so the natural response was to train it on far more data with far more compute.
The scaling sequence
The results arrived in steps. BERT showed that pretraining on unlabelled text and then fine-tuning produced strong results across many language tasks. The GPT line showed that scaling the same architecture and training it to predict the next token kept improving quality, and that at sufficient scale a single model could perform tasks it had not been specifically trained for.
The public inflection was the release of ChatGPT in late 2022. Within two months it had reached an estimated hundred million users, a pace that made it the fastest consumer application adoption recorded up to that point. The technical step was real, and so was the change in who could use it: the interface, not the model, is what moved it from a research result to a household tool.
Agents, tools, and connected context
Between 2023 and 2026 the attention moved from what a model can say to what it can do. Three developments define the current period.
Reasoning models spend additional computation at answer time, generating intermediate steps before committing to an output. On hard mathematics, science, and coding evaluations this changes the achievable score substantially, and it also changes the cost profile, because thinking consumes tokens.
Tool use became a standard capability. A model can call a function, read a file, run a query, or drive a browser, and the results return into its context. This is what turns a language model into an agent: a system that takes actions in a loop until a task is finished.
Standardised connection arrived with the Model Context Protocol, published by Anthropic in November 2024 and moved to the Agentic AI Foundation under the Linux Foundation in December 2025. It gives every compatible client one way to reach a tool or data source, which replaced a large amount of custom integration work.
What changed in the models themselves
The model line has moved quickly. OpenAI's GPT family moved from GPT-4 through the GPT-5 series to the GPT-5.6 generation, whose Sol, Terra and Luna tiers cover the capability and price range. Anthropic's Claude line moved from Claude 3 through Claude 4 to the Claude 5 generation, with Opus 5 as the current flagship, Sonnet 5 as the workhorse, and Fable 5 as the generally available Mythos-class model. Google's Gemini line moved to the Gemini 3 generation, with Gemini 3.1 Pro reported at 77.1 percent on the ARC-AGI-2 reasoning benchmark.
Open-weight families closed much of the gap. Meta's Llama line, DeepSeek's V3 and V4 systems, Alibaba's Qwen line, and Moonshot's Kimi models are now routinely in the same conversations as the closed frontier.
The honest summary is that the top of the field has moved from a single dominant system to a group of systems whose published scores sit within each other's margins of error. Which one you should use depends on the task, the price, the context length, and the deployment rules that apply to you, not on a headline ranking.
What the 2026 Landscape Actually Looks Like
A current snapshot, with the caveat that this section dates fastest of anything in this lecture.
Three structural facts are stable enough to plan around.
First, capability is tiered rather than singular. Each major vendor now ships a top model, a mid-price workhorse and a cheap fast tier, and the price difference between tiers is larger than the capability difference for most work. Choosing per task is now a normal engineering activity.
Second, the frontier benchmarks have started to saturate. MMLU, the long-standing general knowledge benchmark, is above ninety percent for frontier systems. SWE-bench Verified, the coding benchmark built from real GitHub issues, sits at the top of its range: Claude Opus 5 was measured at 97.0 percent by the independent evaluator vals.ai, with GPT-5.6 Sol at 96.2 percent and Claude Fable 5 at 95.0 percent, differences inside the combined margins of error. OpenAI published an audit in 2026 finding that a large share of the audited failing tasks in that benchmark had flawed tests, and a July 2026 audit estimated that roughly thirty percent of the tasks in SWE-bench Pro's public split were broken. When a benchmark has no headroom left, a score difference stops being a capability difference.
Third, the benchmarks that still discriminate are the reasoning ones. GPQA-Diamond tests graduate-level science questions that resist web lookup, with a human expert baseline near sixty-five percent. ARC-AGI-2 tests abstract pattern reasoning and still shows a large gap to human performance. Humanity's Last Exam is a set of expert-written questions across more than a hundred subjects, and independent measurement puts the best systems far below the expert baseline.
The governance layer
The current period also has something the earlier eras did not: binding rules. The European Union's AI Act entered into force in August 2024, with its prohibitions applying from February 2025 and its general-purpose model obligations phasing in from August 2025. If you build on a model in Europe, the compliance question is part of the architecture, not an afterthought.
The cost and reliability question
Every era has had a bottleneck, and the current one is not raw capability. It is the combination of cost, reliability and evaluation. Agents that loop consume tokens in ways that are hard to predict, a model can complete the wrong task confidently, and the benchmarks that would catch a regression are the ones that have saturated.
If you want to know where the field is fragile right now, that is the answer: not in what models can produce, but in whether a given system can be trusted to produce it on the hundredth run, at a price you agreed to in advance.
The Pattern You Should Take From All of It
Seven decades compress into one repeating shape.
An idea appears that is genuinely correct. Early demonstrations look like the general case when they are the special case. A public timeline is set. The bottleneck turns out to be compute, data, or evaluation rather than the idea. The reaction arrives, funding contracts, and the ideas survive at lower volume. Then the missing ingredient shows up, and the field advances faster than anyone expected.
The winters were not periods when the ideas were wrong. They were periods when the cost of the next step had been misjudged, and the mistake was in the estimate, not in the science.
How to use the pattern
Three practical habits follow from it.
Judge a claim by the constraint it depends on, and ask whether that constraint has actually moved. A capability claim that rests on more compute is a claim about capital. A claim that rests on more data is a claim about labelling and rights. A claim that rests on evaluation is a claim about measurement, and that is the one most often skipped.
Expect the interval, not the direction, to be wrong. Almost every forecast in this history named the right capability and the wrong date.
Keep your own measurements. The field's benchmarks saturate and vendors change how they run their evaluations, as the 2026 SWE-bench controversy showed. A small evaluation set built from your own tasks will tell you more about whether a new model helps you than any leaderboard, and it will keep working when the leaderboard does not.
Feynman Summary: Explain It Like You Are 12
Imagine you want to build a machine that can answer any question. For seventy years people have tried, and the story keeps repeating in the same way.
First someone has a clever idea, and it works on a small puzzle. Then everyone gets excited and says the whole thing will be solved in a few years. Then the clever idea meets a real problem, and it turns out the idea was fine but the machine was too slow, or there was not enough information, or nobody could tell whether the answers were getting better. The money stops, and people say the whole idea was silly.
But the clever idea is still sitting there. A few years later the missing piece shows up, and suddenly the same clever idea works, and everyone acts as if it came out of nowhere.
That has happened three times now. The ideas never died. What ran out was patience, and what ran out first was the thing the idea needed to actually run.
So when you hear that a computer will be able to do something amazing in two years, ask what it needs to make that true, and then check whether that thing exists yet. If it does not, the prediction is probably right about what will happen and wrong about when.
Mindmap: The Complete Picture
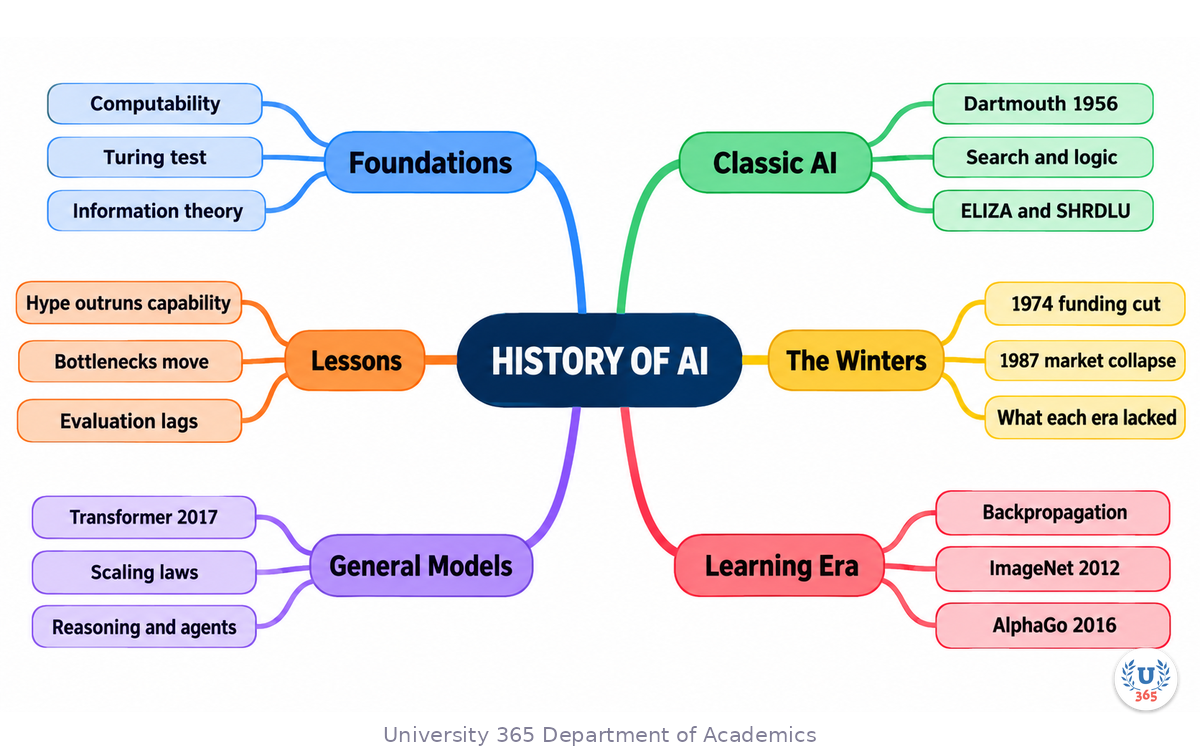
The mindmap puts the history at the centre and branches to the six parts of the story: the foundations in computability and the Turing test, classic AI and its scaling wall, the two winters and what caused each, the learning era from backpropagation to AlphaGo, the general model era from the transformer to agents and connected tools, and the lessons that carry forward.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Chart Your Own Tool's Lineage
This exercise takes about forty minutes, and it produces a one-page document you should keep next to your architecture notes.
Step 1: List what you actually use
Write down every AI system in your current workflow: the assistant in your editor, the chat product you open, the coding agent in your terminal, any model you call through an API. One line each. Do not include tools you have read about but do not run.
Step 2: Trace each one back
For each entry, write down what you know about its lineage. Which model family does it use, and which era does that family descend from? A tool built on a transformer with tool use descends from 2017 and from the agent work after 2023. A classifier you trained on your own data descends from the statistical turn.
Step 3: Name the bottleneck for each
For each tool, write which of the four constraints is currently binding: compute, data, algorithm, or evaluation. If you cannot tell, that is a finding. Write "unknown" and move on.
Step 4: Identify what has no evaluation
Mark every tool in your list that has no test set of your own behind it. These are the entries where you cannot tell whether a model upgrade helped or hurt, and they are the ones to fix first.
Step 5: Write the forecast you would have made
For each tool, write one sentence describing what a 1970s observer would have predicted, and one sentence on what actually happened. The gap between those two sentences is the lesson of this lecture, applied to your own stack.
What to look for
If Step 3 produced "unknown" for most of your tools, you are running a stack you cannot reason about. If Step 4 marked most of your tools, you are exposed to a model change you will not detect until a user reports it.
Applied AI connection
This is the same discipline as the CI-First position: you remain the orchestrator, and your systems are things you understand and measure rather than things you inherited. The history is not background reading. It is the map of which parts of your stack are load-bearing and which are fashion.
Glossary
Term | Definition |
Turing machine | A formal model of computation in which a device reads and writes symbols on a tape according to a table of rules; used to define what is computable. |
Turing test | A test in which a person exchanges text with a human or a machine and tries to tell which is which. |
Symbolic AI | The approach that represents knowledge as explicit symbols and rules, and reasons by manipulating them. |
Combinatorial explosion | The rapid growth in the number of states a search must examine as each step is added, which makes naive search unusable at realistic size. |
AI winter | A period of sharply reduced funding and public credibility for AI research, following unmet expectations; the two main ones began around 1974 and 1987. |
ALPAC report | The 1966 review that found machine translation results did not justify continued funding at the planned level, and reduced it. |
Lighthill report | The 1973 United Kingdom review that concluded AI had not delivered on its promises and recommended limiting funding; it contributed to the first winter. |
ELIZA | A 1966 program that reflected a user's statements back as questions, and which many users read as understanding. |
SHRDLU | A late-1960s program that understood and discussed a small hand-built world of blocks, and could not operate outside it. |
Expert system | A program holding a knowledge base of rules supplied by specialists plus an inference engine that applies them to a case. |
Knowledge acquisition bottleneck | The cost of extracting, writing, testing and maintaining rules from human experts, which limits how far an expert system can scale. |
LISP machine | Hardware designed to run the Lisp language efficiently, sold at a premium and central to the 1980s expert-systems market. |
Backpropagation | The training method that computes how much each weight in a network contributed to the error, and adjusts it; popularised around 1986. |
Convolutional network | A network that applies learned filters across an input, exploiting local structure; the architecture behind the 2012 ImageNet jump. |
ImageNet | A labelled image dataset published in 2009 with over a million images, used as the benchmark whose 2012 result started the deep learning era. |
Generative adversarial network | Two networks trained against each other, one generating data and one judging it, used to produce realistic media. |
Transformer | The 2017 architecture built entirely on attention, which processes a sequence as mutually attending positions and can be trained in parallel over long inputs. |
Scaling laws | The empirical finding that model quality improves predictably as parameters, data and compute are increased together. |
Reasoning model | A model that spends additional computation at answer time generating intermediate steps before committing to an output. |
Agent | A system that takes actions in a loop, calling tools and reading results, until a task is finished. |
Model Context Protocol | The open standard published by Anthropic in November 2024, now hosted by the Agentic AI Foundation under the Linux Foundation, for connecting AI applications to tools and data. |
Benchmark saturation | The state in which a benchmark's scores cluster near the top, so a difference between two models stops indicating a capability difference. |
GPQA-Diamond | A set of 198 graduate-level science questions written to resist web lookup, with a human expert baseline near sixty-five percent. |
ARC-AGI-2 | A benchmark of abstract visual pattern puzzles that still shows a large gap between model and human performance. |
Humanity's Last Exam | A benchmark of expert-written questions across more than a hundred subjects, designed to resist retrieval and remain hard for frontier systems. |
EU AI Act | The European Union regulation on artificial intelligence, in force since August 2024, with obligations phased in from February and August 2025. |
Quiz: TEST YOUR UNDERSTANDING
1. What did Turing's 1936 paper establish?
A) That a machine could pass as human in conversation
B) A formal model of computation, and the existence of problems no mechanical procedure can solve
C) That neural networks could learn any function
D) That machine translation was achievable within a decade
2. Why did the Dartmouth workshop matter?
A) It produced the first working expert system
B) It named the field and funded a research programme built on the bet that reasoning is symbol manipulation
C) It demonstrated machine translation
D) It proved the perceptron could not learn logic
3. Which constraint ended the first AI winter?
A) A shortage of training data
B) Funding withdrawal after promised capabilities did not arrive, following the ALPAC and Lighthill reports
C) A failed benchmark
D) The invention of the transformer
4. What was the knowledge acquisition bottleneck?
A) The speed of inference on specialised hardware
B) The cost of extracting, writing and maintaining rules from human experts
C) The size of the ImageNet dataset
D) The number of attention heads a model could support
5. Why is the 1987 collapse associated with LISP machines?
A) LISP machines were too slow to run expert systems
B) The expert-systems market depended on premium specialised hardware, and general workstations removed that premium
C) LISP was banned in the United States
D) LISP machines could not connect to the internet
6. What three ingredients arrived together in 2012?
A) Transformers, attention and scaling laws
B) Graphics-processor compute, large labelled datasets, and improved training algorithms
C) Expert systems, LISP machines and inference engines
D) Reinforcement learning, self-play and Monte Carlo tree search
7. What property of the transformer made the later scaling possible?
A) It used fewer parameters than earlier architectures
B) It removed the step-by-step processing of recurrent networks, so training could be parallelised over long inputs
C) It eliminated the need for training data
D) It required no attention mechanism
8. Why does benchmark saturation matter to a practitioner?
A) It means models have stopped improving
B) It means a score difference between two models no longer indicates a capability difference, so the benchmark stops helping you choose
C) It means the benchmark is too easy to run
D) It means the models are cheaper to host
9. Which two events of the current period changed how models are used, rather than how well they score?
A) MMLU and ImageNet
B) Tool use and the Model Context Protocol, which turned a language model into a system that can act on external data
C) The ALPAC report and the Lighthill report
D) Backpropagation and the LISP machine
10. What does the pattern across all three eras suggest you should expect from capability forecasts?
A) That they are usually wrong about direction
B) That they are usually right about the capability and wrong about the interval between demonstration and deployment
C) That they are reliable to within a year
D) That they are irrelevant to engineering decisions
Answers: 1-B, 2-B, 3-B, 4-B, 5-B, 6-B, 7-B, 8-B, 9-B, 10-B
Related Resources
U365 INSIDE Publications
Lecture: Understanding AI Benchmarks: how the field measures what these systems can do, and where the measurements stop working
Lecture: Understanding AI Agents: what changed when models started taking actions rather than producing text
Lecture: The AI Stack 2026: What Every Developer Needs: where each of these ideas sits in a system you actually run
External Resources
Computing Machinery and Intelligence (Turing, 1950): the paper that replaced the question of machine thought with a testable one.
A Proposal for the Dartmouth Summer Research Project on Artificial Intelligence (1955): the document that named the field and set its first programme.
A Logical Calculus of the Ideas Immanent in Nervous Activity (McCulloch and Pitts, 1943): the threshold-unit model of a neuron.
Attention Is All You Need (Vaswani et al., 2017): the transformer architecture that the current period rests on.
ImageNet Classification with Deep Convolutional Neural Networks (Krizhevsky, Sutskever and Hinton, 2012): the result that opened the deep learning decade.
Humanity's Last Exam (Center for AI Safety and Scale AI): the expert-written benchmark described in the current-landscape section, at lastexam.ai.
EU Artificial Intelligence Act: the official regulation text and its application timeline, published by the European Union.
vals.ai SWE-bench Verified leaderboard: the independent evaluation behind the coding figures quoted in this lecture, including how each entry was evaluated.
Related U365 Lectures (Coming Soon)
Foundations of Machine Learning: What a Model Actually Learns, in the AI Foundations series
The Transformer Explained: Attention in Plain Language, in the AI Engineering series
U.Copilot for This Lecture
Use this prompt with your own AI assistant to apply the history to a decision you are facing. It follows the UP-Context-Engineering method: context first, then the task, then the constraints, then the output shape.
CONTEXT I am deciding whether to build on an AI capability, and I want to separate a real shift from a forecast that is right about direction and wrong about timing. The capability I am considering: [one sentence] The tool or model it depends on: [name, vendor and version] What I would replace or stop doing if it works: [state the current process] What it depends on to work: [compute, data, algorithm, or evaluation -- pick the one you think is binding, or write "unknown"] What a wrong decision would cost me: [state the consequence and the timeline] The date I need it to work by: [date] TASK 1. Identify which bottleneck this capability depends on, and state what evidence would show that the bottleneck has actually moved rather than been announced as moving. 2. Name the closest historical parallel in the seventy-year record, and say what happened to the timeline in that case. 3. List the published benchmark or evaluation that would demonstrate this capability, and say whether that benchmark has headroom left or has saturated. 4. Tell me what the smallest test on my own data would look like: how many examples, what counts as a pass, and how long it would take. 5. Give me the three conditions under which I should abandon the plan. CONSTRAINTS Use only the information I gave you plus what is in this conversation. Do not invent benchmark figures, model version numbers, prices or dates. Where a claim depends on a current model landscape, say which source should be checked and how recently. Separate what is measured from what is forecast. OUTPUT First a one-line verdict: proceed, proceed with a pilot, or wait. Then a table with one row per dependency: dependency, is it actually in place, evidence, evidence date. Then the historical parallel in two sentences. Then the smallest test design as a numbered list. Then the three abandon conditions. End with the single question I should ask the vendor before committing.
Next Steps
Complete Step 4 of the exercise this week: mark every AI tool you run which has no test set of your own behind it. You cannot detect a regression you have no measurement for
Pick one capability claim you are currently acting on and write down which constraint it depends on: compute, data, algorithm, or evaluation. Then find the evidence that the constraint moved
Read the current version of the benchmarks named in this lecture before you quote any figure from it, because the coding and reasoning leaderboards change monthly, and how a score was produced matters as much as the number
Build a fifty-example evaluation set from your own work and run it against the model you use now. That baseline is what makes every future model decision measurable
Apply the interval rule to the next forecast you read: accept the direction, and ask separately what has to be true for the date to hold
The ideas in this field have proved durable. What has repeatedly run out is the margin between what a method needs and what the world can supply, and that margin is what you should be measuring before you commit your own work to it.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current technical details against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Technology (UIT).
Sam Utteker, Dean of Technology, UIT
Signed for the academic year 2026.




Comments