
Understanding AI Benchmarks
Updated: Oct 8

UIT University 365 Institute of Technology
Series AI Foundations | Level Basic (Free)
Duration 25 minutes | Access Free
IT Engineering, AI and Applied AI, Data Science, Software Development, Digital Transformation

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture

The Number That Fooled You
In February 2026, OpenAI published a note explaining why it had stopped reporting a widely quoted coding benchmark. The reason was not that its models scored badly. The reason was that the benchmark had stopped measuring the thing it claimed to measure: an audit found that a large share of the problems a model failed had flawed test cases, so a "failure" was often the grader's fault, not the model's.
In July 2026 the same pattern repeated on the newer version. An OpenAI audit of the public split of the harder benchmark estimated that roughly thirty percent of its tasks were broken, and the company retracted its earlier recommendation to adopt it.
Both events matter to you for one reason. If a frontier lab with dedicated evaluation teams can quote a number that later turns out to measure something else, then any figure you read on a leaderboard deserves a second question before it enters a decision.
This lecture teaches you the second question. It covers what benchmarks actually are, the five families in use, why the head-line benchmarks have started to break, the six ways a score misleads you, and how to build the one measurement that will never mislead you: a small test set of your own work.
What a Benchmark Actually Is
A benchmark is a fixed set of tasks, a scoring rule, and a published result. All three parts can be wrong, and the third one is where the trouble usually starts.
The four components
The task set is a collection of problems with known correct answers. MMLU is roughly fourteen thousand multiple-choice questions across fifty-seven academic subjects. GPQA-Diamond is 198 questions in biology, chemistry and physics, written by PhD-level experts and designed so that a search engine cannot answer them. SWE-bench Verified is 500 Python issues drawn from real open-source repositories, each paired with the pull request that fixed it.
The scoring rule decides what counts as correct. Multiple-choice grading is exact match. Coding benchmarks usually require the repository's own tests to pass after the model's patch is applied. Agent benchmarks often compare the final state of a database or a file tree against an annotated goal state, which means the grader is checking an outcome rather than a string.
The setup is the surrounding machinery: the prompt template, how many attempts are allowed, whether the model may use tools, and how much reasoning effort it spends. This is the component most readers never see, and it is the one that makes two published numbers incomparable.
The human baseline is the reference point for the task. On GPQA-Diamond, domain PhDs score near sixty-five percent and skilled non-experts with web access score around thirty-four percent. Without that reference a score of seventy percent has no meaning.
Why the setup matters more than the score
Consider two published figures for the same capability. One lab runs a model with a minimal agent scaffold that edits files directly with shell commands. Another runs the same model inside a purpose-built coding setup with retrieval, planning and retry logic. The second number can be twenty points higher without the model changing at all.
This is not dishonesty. It is the difference between measuring a model and measuring a product. Both are worth knowing, and neither is comparable to the other. A table that places them in adjacent cells implies a comparison that was never performed.
The rule that follows is simple: a benchmark score is a statement about a model inside a setup, on a task set, at a date. Drop any one of those four and the number stops meaning anything.
The Five Families: Knowledge and Reasoning
The first family asks whether a model knows things and can reason about them.
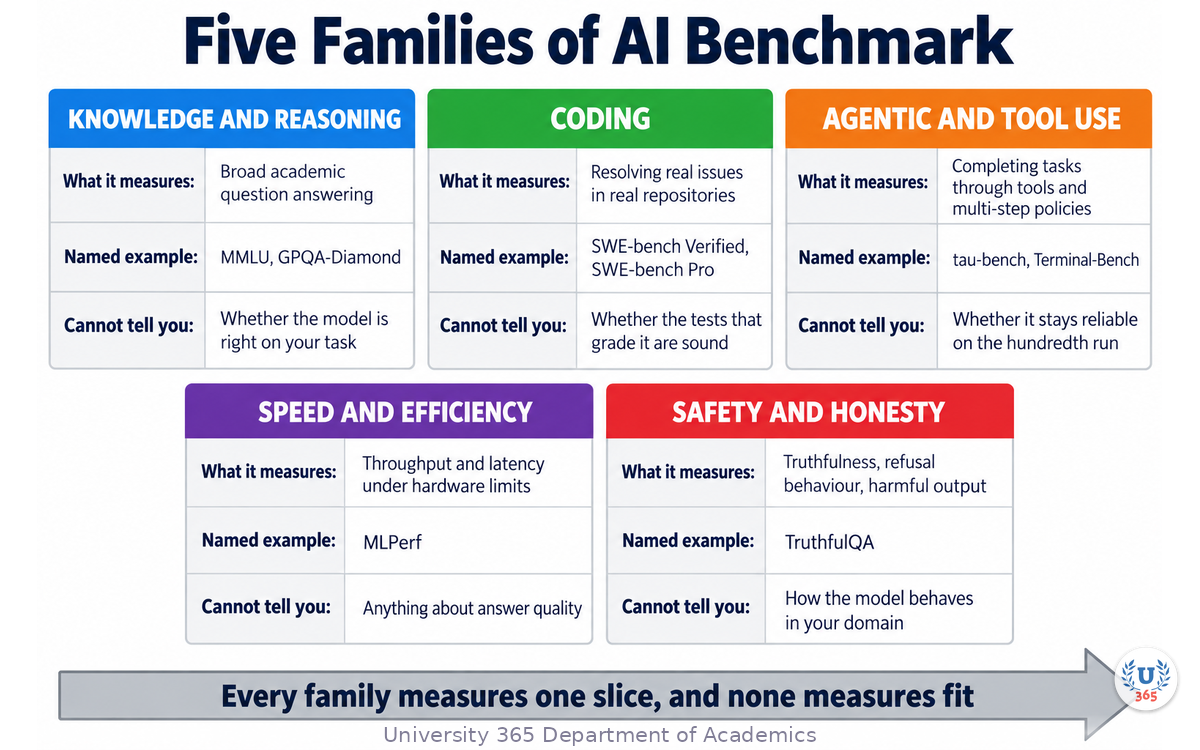
MMLU (Massive Multitask Language Understanding) covers fifty-seven subjects from elementary mathematics to law. For years it was the standard general-knowledge score. It is now effectively saturated: frontier systems clear ninety percent, and the remaining spread carries little information. When a vendor leads with an MMLU number, ask why they did not include one of the benchmarks with headroom left.
GPQA-Diamond is the harder successor in the same spirit. The questions are written to be answerable by experts and unfindable by search, and the diamond subset keeps only the questions where both human annotators answered correctly. With an expert baseline near sixty-five percent, a score above that level means something real.
ARC-AGI-2 tests abstract visual pattern reasoning. It presents a small number of coloured grids and asks the model to infer the transformation rule and apply it to a new grid. Human performance is far above frontier models on this set, which makes it the clearest available measure of generalisation, and also the one with the most headroom.
Humanity's Last Exam, built by the Center for AI Safety and Scale AI, is a set of around two thousand five hundred expert-written questions across more than a hundred subjects, deliberately resistant to retrieval. Independent measurement puts the best systems well below the expert baseline on it.
TruthfulQA measures something different: whether a model produces accurate answers on questions where humans commonly hold misconceptions. It belongs in this family because it tests honesty rather than knowledge, and the two can diverge sharply.
What this family cannot tell you
Whether the model is right on your task. A system can score at expert level on graduate physics and produce a confidently wrong answer about your company's data model, because your data model never appeared in its training set and was never in a benchmark. Knowledge benchmarks measure breadth on public material.
How a Benchmark Is Built: The Design Decisions
Before a benchmark can produce a number, someone has to make five decisions, and each one shapes what the number can mean.
What counts as a task. A task can be a question with one right answer, a repository issue with a reference patch, a goal state in a simulated system, or an open-ended output graded against criteria. The choice determines whether the benchmark can be graded automatically. Automatic grading is what makes a benchmark cheap to run at scale, and it is also what limits the kind of capability it can measure. Anything requiring taste, judgement or a long-horizon outcome is expensive to grade, which is why the oldest benchmarks measure the answerable kind of task.
How difficulty is controlled. The designers filter. GPQA kept only the questions where both expert annotators answered correctly and where skilled non-experts with web access still failed. Humanity's Last Exam tested candidate questions against frontier models and dropped the ones the models could already answer. This filtering is what makes a benchmark hard, and it is also why the first scores are near zero. A benchmark built this way has deliberately removed everything the current generation can do.
How the human baseline is measured. A benchmark needs a reference point, and getting one is harder than it sounds. The GPQA paper reports roughly sixty-five percent for domain PhDs and around thirty-four percent for skilled non-experts with web access. Those figures come from a specific study with a specific sample, and they carry the same uncertainty as any other measurement. A benchmark whose human baseline is asserted rather than measured cannot tell you whether a model has passed it.
How the test set is held back. Publication is what makes a benchmark useful and what eventually destroys it, because published questions end up in training data. The defences are partial: keep a private split, rotate the questions, or write new ones after each model's training cut-off. MathArena takes the third route deliberately, testing models only on competitions held after their release, so the material cannot have been memorised.
How the evaluation setup is standardised. If every lab runs the benchmark its own way, the leaderboard is a comparison of scaffolds. A standardised setup runs every model through identical machinery, which isolates the model from the engineering around it. The trade is real: a standardised setup measures a capability that no product actually ships, because products do have retrieval, planning and retries.
What this means when you read a table
Every one of these decisions is a place where two published numbers can diverge without either being wrong. The practical consequence is that a table is only comparable down its own column, and often only within a single evaluator's runs. When you see a benchmark table that mixes sources, the correct reading is that the rows are separate experiments arranged to look like a ranking.
The design decision you should make yourself
The most useful version of this exercise is to make the five decisions for your own workload. What counts as a task in your setting? How will you hold examples back so your own system does not overfit to them? What is your reference point, whether a human doing the work or a previous version of your process? What is the standardised setup you will always run? Answering those five questions is the whole of building a benchmark, and it takes an afternoon rather than a research programme.
Sector Benchmarks and What a Regulator Will Ask
The general benchmarks tell you how a model performs on public academic material. They tell you nothing about a regulated domain, and in a regulated domain the question is not which model scores highest but which evidence a reviewer will accept.
Why sector benchmarks exist
A general benchmark asks whether a model can reason across academic subjects. A sector benchmark asks whether it can perform the specific reasoning a professional field requires, using the vocabulary and the failure modes of that field. The distinction matters because domain performance does not follow from general performance. A model can score at expert level on graduate physics and still mishandle a clinical dosing question, because the clinical reasoning involves constraints the physics questions never exercised.
The established examples are worth knowing by name, because they are the ones that appear in procurement and compliance discussions. MedQA draws on the United States Medical Licensing Examination and measures clinical knowledge and reasoning. PubMedQA and BioASQ cover biomedical literature comprehension and semantic indexing. LegalBench and CaseHOLD cover statutory interpretation, case comparison, contract analysis and the prediction of court decisions. FiQA covers financial sentiment, opinion extraction and question answering. MathVista and CharXiv measure mathematical and chart reasoning in visual contexts, which is where document-heavy professional work actually lives.
What these benchmarks can and cannot establish
They can establish that a model performs at a measured level on a standardised sample of professional tasks. That is a genuine and useful claim, and it is the claim a reviewer will understand.
They cannot establish that the model is safe for your process. Three gaps are structural. First, a benchmark sample cannot cover the long tail of your operations, and it is the long tail where incidents happen. Second, a score is an average across a task set, and your process may live entirely in one category where performance is worse. Third, a benchmark measures a model in isolation, while your deployment includes retrieval, guardrails and a human reviewer, all of which can change the outcome in either direction.
The evidence a reviewer will actually want
In a regulated setting, a benchmark score is the beginning of a file rather than the end of one. What tends to satisfy a reviewer is narrower and more concrete: a documented scope statement of what the system is allowed to do, a test set drawn from your own cases with the acceptance criteria written down, a record of the pass rate across repeated runs, a description of the human review step and who performs it, and a log of the model version in use and the date it changed. None of that is provided by a leaderboard, and all of it is producible by a small team in a few weeks.
The practical rule for a regulated deployment
Start from the obligation, not from the benchmark. Write down what the governing rule requires you to be able to demonstrate, then design the measurement that demonstrates it. A sector benchmark can support that measurement as context. It cannot stand in for it, because a reviewer's question is about your system, and no public benchmark has ever been run on your system.
The Five Families: Coding
The second family asks whether a model can change a real codebase.
SWE-bench Verified gives the model a GitHub issue and the repository, and requires a patch that makes the project's own tests pass. It is the closest public proxy for whether a model can fix a real bug in a real repository without help. The 2026 figures put Claude Opus 5 at 97.0 percent as measured by the independent evaluator vals.ai, with GPT-5.6 Sol at 96.2 percent and Claude Fable 5 at 95.0 percent. Those intervals overlap, so the ranking between the top entries is a statistical tie.
SWE-bench Pro raises the difficulty with 1,865 tasks across 41 professional repositories, split into public, commercial and held-out sets. Two score families exist and are not comparable: vendor-run numbers using each lab's own scaffold, which run fifteen to thirty points higher, and the standardized Scale SEAL leaderboard where every model is run through the same setup.
Aider Polyglot tests 225 difficult exercises across C++, Go, Java, JavaScript, Python and Rust, and scores accuracy, adherence to the required edit format, and how much of the task the model completes without human help.
Terminal-Bench measures whether a model can operate a live terminal: managing an environment, debugging, and completing multi-step system operations. The 2026 standings put GPT-5.6 Sol at 89.5 percent and Claude Opus 5 at 89.1 percent on version 2.1 at high effort.
The trap in this family
The benchmark's tests are code written by humans, and code written by humans has bugs. OpenAI's February and July 2026 audits found a substantial share of tasks where a model's failure was caused by a defective test rather than a defective solution. When you read a coding score, you are reading two things at once: how good the model is, and how good the grader is.
The Five Families: Agentic and Tool Use
The third family, and the one that grew fastest, asks whether a system can complete a task rather than answer a question.
An agentic benchmark has to supply a world. It gives the model a set of tools, a policy document, and a goal, and it checks the state of the world afterwards.
tau-bench places an agent in a simulated customer service setting, such as retail or airline booking, with domain-specific APIs and a policy it must follow. Success is measured by comparing the final database state against an annotated goal. It also introduces the pass^k metric, which measures whether the agent succeeds consistently across repeated attempts rather than once. That metric matters more than the headline rate: an agent that succeeds sixty percent of the time and succeeds five times in a row fifteen percent of the time cannot carry a business process.
Terminal-Bench and its successor versions test long-horizon terminal work.
BrowseComp, released by OpenAI in 2026, tests whether an agent can find hard-to-locate information across multiple web sources. The published spread is instructive: a base model without browsing scored under one percent, with basic browsing under two percent, a reasoning model around ten percent, and a purpose-built research agent above fifty percent. The capability lived in the scaffold as much as in the model.
Why this family is the most useful and the least comparable
Agentic scores are the closest thing to the work you actually want done, and they are also the most sensitive to the setup, because the scaffold, the tool set and the retry policy are all part of the measurement. Two agents scoring sixty percent and eighty percent may differ in their engineering rather than their model.
The useful question is not which agent scores highest. It is what the agent's pass rate is on your task, at your cost, on the hundredth run.
The Five Families: Speed, Efficiency and Safety
The last two families are small and often skipped, and both can decide a deployment.
MLPerf, run by MLCommons, measures throughput and latency for training and inference under defined hardware conditions. It tells you what a system costs to serve and whether it meets a latency budget. It says nothing about answer quality, and a fast wrong answer is not progress.
Sector benchmarks apply the same discipline inside one domain. MedQA draws on the United States Medical Licensing Examination. BioASQ and PubMedQA cover biomedical literature. LegalBench and CaseHOLD cover statutory interpretation and court decisions. FiQA covers financial sentiment and question answering. These are the benchmarks to consult when your deployment is in a regulated field, because they are the ones a reviewer will ask about.
Safety and honesty benchmarks include TruthfulQA, adversarial robustness suites, and refusal-behaviour evaluations. Their scores are the hardest to interpret, because a refusal rate can be too low or too high, and the correct value depends on your application rather than on the benchmark.
The structural point of this lecture is in the infographic below. Every family measures one slice, and none of them measures fit.
Why the Frontier Benchmarks Started to Break
Three mechanisms broke the head-line benchmarks, and all three are predictable.
Contamination. Benchmarks are published, and models are trained on the internet. When test questions end up in training data, the score measures recall rather than reasoning. Detection is difficult, and the counter-measures are partial: held-out private splits, rotating question sets, and questions written after a model's training cut-off. MathArena uses this last approach deliberately, testing models only on competitions that took place after their release.
Saturation. When every frontier model scores above ninety percent, the remaining gap sits inside the noise. MMLU reached this state. SWE-bench Verified is close: seven models on the independent setup clear ninety-five percent, and the top three are inside each other's margins of error. A saturated benchmark cannot help you choose.
Broken grading. This is the newest and the most damaging. OpenAI's audits in 2026 found large shares of tasks whose tests were defective. The consequence is that a low score may be measuring the benchmark, not the model, and a high score may be measuring how many broken tasks happened to pass.
The HLE scoring dispute
A fourth issue is worth knowing about because it illustrates how far apart measurements can get. Humanity's Last Exam was designed to resist saturation, and for a period one vendor reported a score in the middle sixties for a model while independent evaluators, testing what they understood to be the same model on the same benchmark, reported a figure under twenty percent. The gap was around forty-eight percentage points.
Explanations offered for the divergence include different scoring setupes, different subsets, different model snapshots, and grading by a model rather than by exact match. Whatever the cause, the episode establishes the practical rule: when two numbers for the same capability disagree by tens of points, at least one of them is measuring something you were not told about.
What replaced them
The field has not converged on a successor. What has happened instead is a shift toward measuring tasks rather than answers: agents completing workflows, cost per completed task, and reliability across repeated runs. Those are harder to publish as a single number, which is precisely why they are harder to game.
The Six Ways a Score Misleads You
Read the infographic before the list; it is the summary of this section.
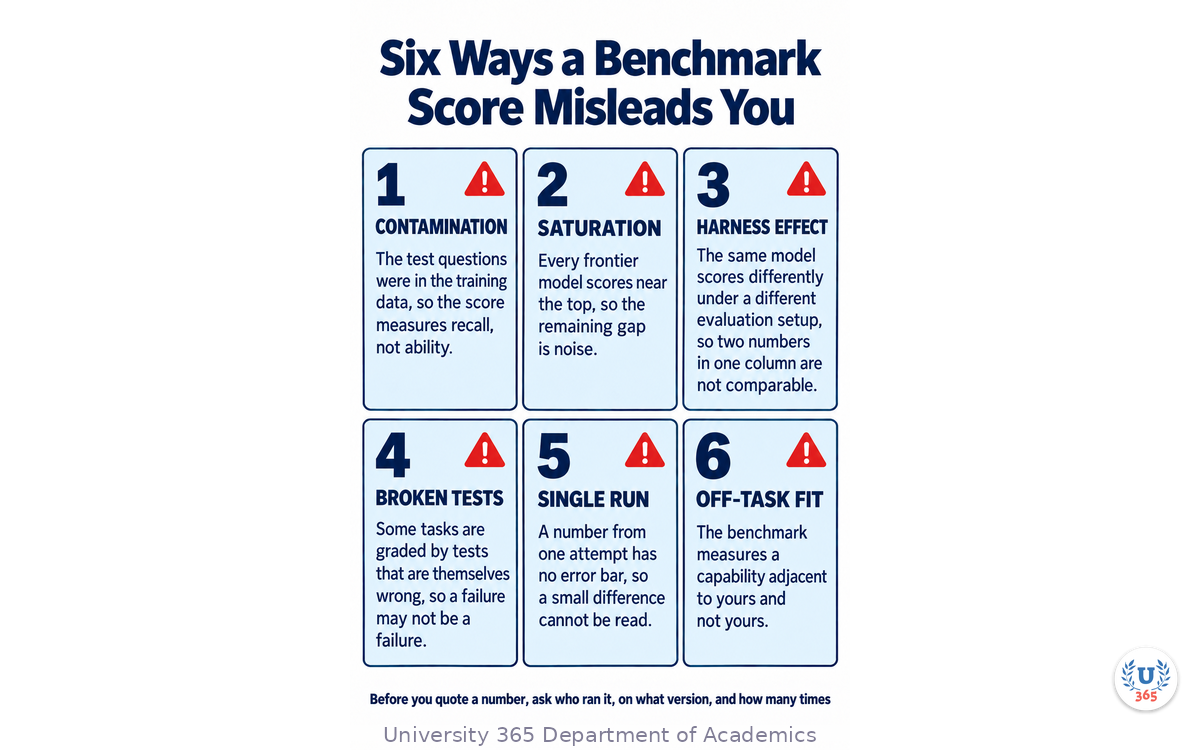
1. Contamination. The test questions were in the training data. The score measures recall. The defence is a benchmark whose questions were written after the model's cut-off, or a private held-out split.
2. Saturation. Every model scores near the ceiling, so a difference is noise. The defence is to check whether the benchmark has headroom against its human baseline before you quote any gap from it.
3. The setup effect. The same model scores differently under a different scaffold. The defence is to record who ran the evaluation and on what setup, and never to compare a vendor-run number with a standardized one.
4. Broken tests. Some tasks are graded by defective tests. The defence is to look for a published audit, and to treat a benchmark with no audit history more cautiously than one with a documented one.
5. The single-run number. A result from one attempt has no error bar. The defence is to require a trial count and an interval. Values within one interval are not a ranking.
6. Off-task fit. The benchmark measures a capability adjacent to yours. The defence is the only one that fully works: measure the thing you actually do.
The rule behind all six
Every one of these failures is a version of the same mistake: treating a measurement as a property. A benchmark score is an event that happened in a specific configuration on a specific day. It is evidence, and evidence has to be examined.
How to Read a Leaderboard in Four Minutes
A practical procedure, in order.
One: find the setup. If two numbers in the same column came from different scaffolds, the column is fiction assembled out of true parts. Look for a note on whether the evaluation was vendor-run or third-party.
Two: find the trial count. A mean over five attempts is a different kind of object from a single run. If there is no interval, treat any difference below a few points as unmeasured.
Three: read the footnotes before the table. That is where the effort settings, the fallbacks, the subsets and the memorisation warnings live. A model that falls back to a smaller sibling on refusals has an effective score that is a blend.
Four: check the date. Capability numbers from six months ago describe a different generation. The 2026 model landscape moved through several full generations in a year.
Five: check whether the benchmark still has headroom. If the top scores are clustered at the ceiling, it has stopped discriminating, regardless of what the table implies.
Six: find the one number that matters for you. Almost always, that is the cost per completed task on your workload. Almost never is it on the leaderboard.
Build the Only Benchmark That Matters to You
Everything above points at one conclusion: you need your own evaluation set, and it is not difficult to build.
The reasons are structural rather than aesthetic. Public benchmarks saturate. Vendors change setupes. Your task is not on any of them. A small test set drawn from your own work sidesteps all three problems at once, and it keeps working when the public numbers stop meaning anything.
What a working test set looks like
Fifty examples is enough to detect a change that matters and small enough to build in an afternoon. Each example needs four parts: a realistic input, the correct output, the specific property that makes the output acceptable, and the way you would check that property.
The third part is where most attempts fail. "Summarise this document" is not a checkable property. "Names every party and states the effective date, using only the document's own wording" is.
How to use it
Run the set before you adopt a model and after every model or prompt change. The absolute score matters less than the direction of change. A drop of two examples out of fifty after a model upgrade is a real signal, and it is one no leaderboard would have given you.
Record the model, the date, the prompt version and the score each time. In six months you will have something no vendor can sell you: an evaluation history of your own system.
Feynman Summary: Explain It Like You Are 12
Imagine you want to know which of five chefs is best. You could give them all the same recipe and see who follows it well. That is a benchmark.
The problem is that everyone has started using the same recipe, so all five chefs have memorised it. Now they all cook it well, and you still do not know who is best. That is saturation.
Worse, someone found the recipe online before the test and practised on it. That is contamination. And some of the recipe cards have typos in them, so a chef who does it right gets marked wrong. That is broken grading.
Also, one chef was allowed to use a kitchen with better equipment. That is the setup, and it means you were never really comparing the chefs.
So the only test that really works is: give each chef the meal you actually want to eat, and taste it yourself. It does not matter what the cooking contest said. You have your answer, and you can run the same test again next month.
Mindmap: The Complete Picture
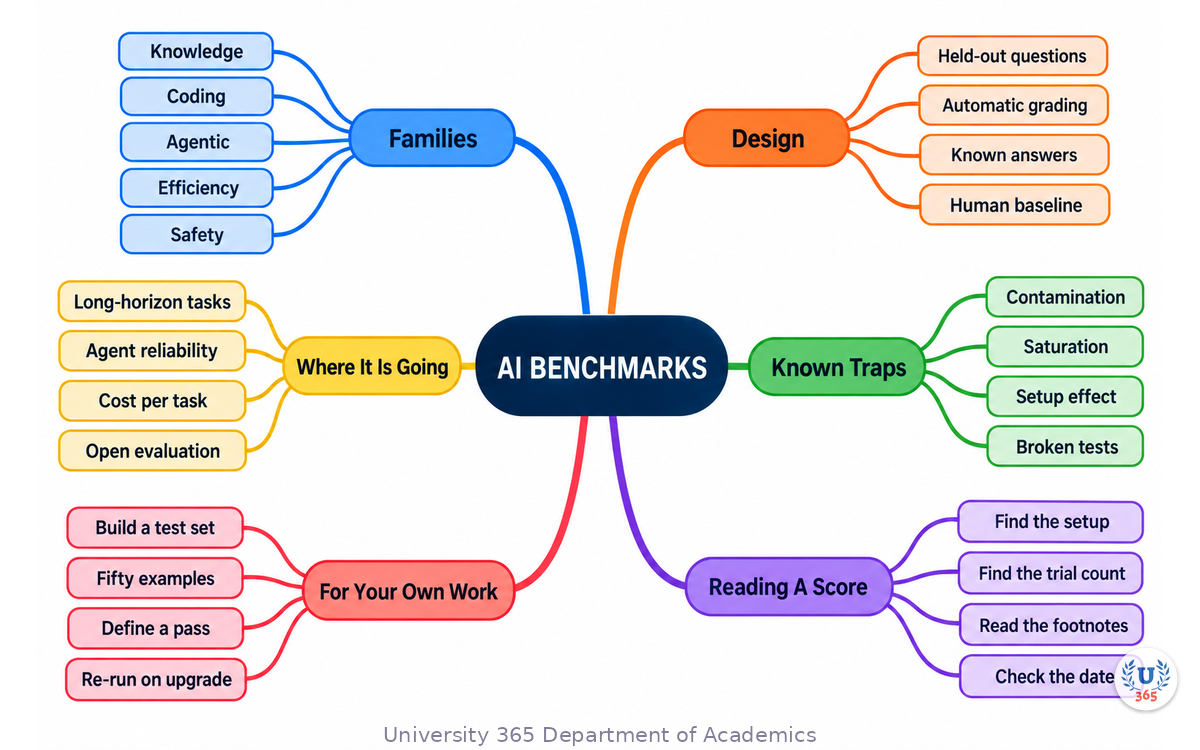
The mindmap puts benchmarks at the centre and branches to the five families, the design choices behind a fair task set, the six known traps, the procedure for reading a published score, the test set you should build, and the direction the field is moving.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Build a Fifty-Example Test Set
This exercise takes about two hours, and it produces an asset that will outlive every leaderboard in this lecture.
Step 1: Choose one workflow
Pick a single task your team or you repeat: classifying support messages, drafting replies to a standard request, extracting fields from documents, writing a specific kind of test, or summarising a fixed document type. One workflow, not five.
Step 2: Gather fifty real examples
Pull fifty real inputs from your own history. Real inputs, not invented ones. If you cannot find fifty, that is useful information about how well you understand your own process.
Step 3: Write the correct output for each
For open-ended tasks, write the *acceptance property* rather than a single expected answer. For example: "the reply states the refund window and does not promise a date that the policy does not guarantee."
Step 4: Define the check
One line per example describing how a person would verify it. If the check requires judgement, say who judges and what they are told to look for.
Step 5: Write a scoring script
Something that runs your workflow over the fifty inputs, records the outputs, and prints a score. It does not need to judge quality automatically. It needs to produce a file a human can review in twenty minutes.
Step 6: Establish the baseline
Run it against the model you use today, and record the score with the date and the prompt version. This is the number every future decision gets compared against.
What to look for
If Step 3 was difficult, you learned that you do not have a written specification for your own process, which is a finding worth acting on independently of any model question. If Step 5 produced outputs you cannot score in twenty minutes, the acceptance properties in Step 3 are too vague.
Applied AI connection
This is the CI-First position applied to evaluation. You are the orchestrator; the measurement of your system is yours to own. A team that can run fifty examples against a new model in an afternoon will adopt the right improvements and reject the wrong ones, and will not be moved by a leaderboard entry either way.
Glossary
Term | Definition |
Benchmark | A fixed set of tasks, a scoring rule, and a published result, used to compare systems. |
Task set | The collection of problems with known correct answers that a benchmark scores against. |
Evaluation setup | The surrounding machinery of an evaluation: prompt template, attempt count, tool access and reasoning effort. Two numbers from different setupes are not comparable. |
Human baseline | The reference score achieved by human experts on a benchmark, without which a model's score has no scale. |
MMLU | Massive Multitask Language Understanding: roughly fourteen thousand multiple-choice questions across fifty-seven academic subjects; now saturated. |
GPQA-Diamond | A 198-question graduate-level science benchmark written to resist web lookup, with an expert baseline near sixty-five percent. |
ARC-AGI-2 | A benchmark of abstract visual pattern puzzles that still shows a large gap between human and model performance. |
Humanity's Last Exam (HLE) | Around two thousand five hundred expert-written questions across more than a hundred subjects, built to resist retrieval. |
TruthfulQA | A benchmark measuring whether a model answers accurately on questions where humans commonly hold misconceptions. |
SWE-bench Verified | 500 human-validated Python issues from real repositories, scored on whether the project's tests pass after the model's patch. |
SWE-bench Pro | A harder coding benchmark of 1,865 tasks across 41 professional repositories, with vendor-run and standardized score families that are not comparable. |
Terminal-Bench | A benchmark measuring whether a model can operate a live terminal through multi-step system tasks. |
tau-bench | An agentic benchmark placing an agent in a simulated service setting with tools and a policy, scored against an annotated goal state. |
pass^k | A consistency metric for agents: the probability of succeeding on k independent attempts in a row. |
BrowseComp | A benchmark testing whether an agent can locate hard-to-find information across multiple web sources. |
MLPerf | An MLCommons benchmark measuring training and inference throughput and latency under defined hardware conditions. |
MedQA, BioASQ, LegalBench, FiQA | Sector benchmarks covering clinical knowledge, biomedical literature, legal reasoning, and financial question answering respectively. |
Contamination | The condition in which benchmark questions appeared in a model's training data, so the score measures recall rather than ability. |
Saturation | The state in which all frontier models score near a benchmark's ceiling, so remaining differences are noise. |
Held-out split | A portion of a benchmark kept private so it cannot enter training data. |
Error bar | The uncertainty interval around a score, without which a small difference between two results cannot be read. |
Cost per completed task | The total spend divided by the number of successfully finished tasks; usually the number that decides a deployment. |
Quiz: TEST YOUR UNDERSTANDING
1. What does a benchmark score actually describe?
A) The model's intelligence in general
B) A model, inside a setup, on a task set, at a date
C) The cost of running the model
D) The vendor's engineering quality
2. Why did OpenAI stop reporting SWE-bench Verified?
A) Its models scored too low
B) An audit found a large share of audited failed problems had flawed tests, so the benchmark stopped measuring frontier coding capability
C) The benchmark was deleted
D) It was replaced by MMLU
3. What is the setup effect?
A) The speed at which a model responds
B) The same model scoring differently under a different evaluation setup, which makes two published numbers incomparable
C) A hardware requirement
D) The process of cleaning test data
4. Why does a human baseline matter?
A) It sets the price of the model
B) Without a reference point, a raw score has no scale or meaning
C) It determines the setup
D) It prevents contamination
5. What is pass^k and why does it matter?
A) The number of tasks in a benchmark
B) The probability an agent succeeds on k independent attempts in a row, which measures consistency rather than a single success
C) The cost per task
D) The number of models compared
6. Which family of benchmark tells you nothing about answer quality?
A) Knowledge and reasoning
B) Coding
C) Speed and efficiency
D) Safety and honesty
7. What is contamination?
A) Mixing two benchmarks together
B) Benchmark questions appearing in training data, so the score measures recall rather than ability
C) A scoring bug
D) Using the wrong setup
8. Why is a saturated benchmark useless for choosing a model?
A) It is too expensive to run
B) All frontier scores cluster at the ceiling, so the remaining gap is inside the noise
C) It has too few questions
D) It measures only coding
9. What is the most reliable defence against every trap described in this lecture?
A) Only reading vendor-reported numbers
B) Building a small evaluation set from your own work and re-running it on every change
C) Waiting six months after a model is released
D) Using the largest benchmark available
10. What should you check before comparing two numbers on one leaderboard?
A) Whether the models have the same number of parameters
B) Whether the same setup, trial count and version were used, and what the footnotes say
C) Whether the models share a vendor
D) Whether the benchmark is more than a year old
Answers: 1-B, 2-B, 3-B, 4-B, 5-B, 6-C, 7-B, 8-B, 9-B, 10-B
Related Resources
U365 INSIDE Publications
Lecture: The Complete History of AI: From Turing to Today: where benchmarks came from, and why each era needed a new one
Lecture: Understanding AI Agents: the systems the agentic benchmarks try to measure
Lecture: The AI Stack 2026: What Every Developer Needs: where observability and evaluation sit in a production system
External Resources
Why SWE-bench Verified no longer measures frontier coding capabilities (OpenAI, February 2026): the audit and the retraction of a benchmark recommendation.
SWE-bench Pro audit note (OpenAI, July 2026): the estimate that roughly thirty percent of the public split's tasks are broken.
GPQA: A Graduate-Level Google-Proof Q&A Benchmark (Rein et al., 2023): the task design, the expert baseline and the diamond subset.
Humanity's Last Exam (Center for AI Safety and Scale AI): the benchmark materials and the published results, at lastexam.ai.
ARC Prize leaderboard: the live standings and the human baselines for ARC-AGI-2.
vals.ai SWE-bench Verified leaderboard: the independent evaluation behind the coding figures quoted here, with the setup recorded per entry.
tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains: the task design and the pass^k metric.
MLPerf (MLCommons): the training and inference benchmark rules and results.
Artificial Analysis: an independent evaluator publishing capability, price and speed together, which is often more useful than a single capability table.
Related U365 Lectures (Coming Soon)
Evaluating Tool-Using Agents: Test Sets That Catch Regressions, in the AI Engineering series
Reliability Engineering for AI Systems: Pass Rates, Retries and Cost, in the AI Engineering series
U.Copilot for This Lecture
Use this prompt with your own AI assistant to interrogate a benchmark claim before you act on it. It follows the UP-Context-Engineering method: context first, then the task, then the constraints, then the output shape.
CONTEXT I am about to make a decision based on a published AI benchmark score, and I want to know how much weight the number can carry. The score I saw: [the number, the model and the version] Where I saw it: [vendor page, leaderboard, article, or review] What it was measuring: [the benchmark name] The decision it would inform: [what I would choose or buy differently] What else I know about my task: [one sentence on what I actually need the system to do] TASK 1. Break the number into its four components: task set, scoring rule, setup and human baseline. Say which of the four I have not been told. 2. Tell me who ran the evaluation and whether it is comparable to numbers from other sources. 3. Say whether this benchmark has headroom left against its human baseline, or has saturated. 4. List the checks I should run before quoting the number, including version, trial count and any published audit of the benchmark's tasks. 5. Design the smallest test on my own data that would settle the decision, including how many examples I need and what counts as a pass. CONSTRAINTS Use only the information I gave you and what is in this conversation. Do not invent scores, version numbers, dates or benchmark names. Where a claim depends on a current leaderboard, name the source that should be checked and how recently. Separate what is measured from what is inferred. OUTPUT First a one-line verdict on how much weight the score can carry: high, medium or low. Then a table with one row per component: component, what I know, what is missing. Then the checks as a numbered list. Then the smallest test design. End with the single question I should ask the vendor before treating the number as evidence.
Next Steps
Build the fifty-example test set this week using the exercise above. It is the only measurement in this lecture that will still be useful in a year
Run it against the model you use now and record the score with the date, the model version and the prompt version
Apply the four-minute procedure the next time you see a leaderboard, before you form an opinion: setup, trial count, footnotes, date
Check whether the benchmark you rely on has headroom against its human baseline. If the top scores cluster at the ceiling, look for a successor
Keep a written record of model changes in your own systems, with the test set result beside each one, so a regression is detectable rather than discovered by a user
Benchmarks remain useful. What they are not is a substitute for knowing what your own system does, and the difference between those two positions is now large enough to decide which teams adopt improvements correctly and which ones chase numbers.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current technical details against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Technology (UIT).
Sam Utteker, Dean of Technology, UIT
Signed for the academic year 2026.




Comments