
Chain of Thought Prompting: The Key to Advanced AI Reasoning
Updated: 11 hours ago

UIT University 365 Institute of Technology
Series AI Skills Series
Duration 25 minutes
IT Engineering, AI and Applied AI, Data Science, Software Development, Digital Transformation

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture

The Two Things You Are Being Told
You have read that asking a model to think step by step makes it substantially more accurate on hard problems. You have also read that the reasoning a model shows you is not the reasoning it actually used, so you should not trust it. Both statements are in circulation, both come from real research, and they are not in conflict.
The confusion comes from asking one technique to do two different jobs. Chain of thought is a technique for improving accuracy, and it works. A reasoning trace is also read by people as an explanation of the answer, and that reading is unreliable. The same generated text serves both purposes, which is exactly why the distinction is easy to lose.
Chain of thought prompting entered the literature in 2022 with the paper "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models" by Jason Wei and co-authors at Google. The finding was direct: show a model a few worked examples that include intermediate reasoning steps rather than only input-output pairs, and its accuracy on arithmetic, commonsense and symbolic reasoning jumps sharply. By 2026 the technique has been absorbed into the models themselves: the current generation of reasoning models generates an internal chain of thought before answering, whether or not you ask.
This lecture separates the two questions. It covers what chain of thought does mechanically, how to write it, what the reasoning-model generation changed, how to test whether a trace is load-bearing for the answer, and the four production failure modes that catch teams who treat a plausible-looking trace as evidence.
What Chain of Thought Actually Does
Start with the mechanism, because the mechanism explains every later caveat.
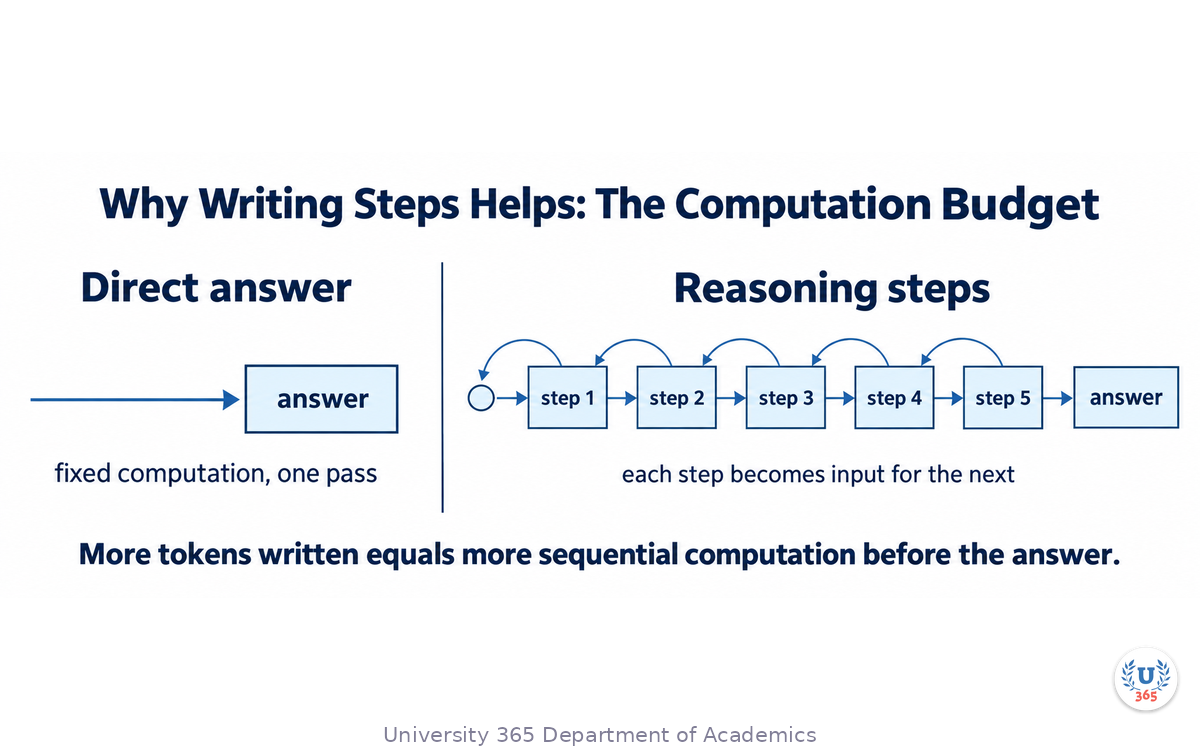
A language model generates one token at a time, and each token is computed with a fixed amount of computation. That is the constraint: the arithmetic performed between the input and the output does not grow with the difficulty of the problem. A hard question and an easy one receive the same depth of processing per token.
Chain of thought changes one thing about that budget. Every token the model writes becomes part of the input for the next token. Writing a reasoning step therefore buys additional computation: the intermediate values are computed, stored as text, and made available for the next step. Ten reasoning steps give the model ten times the sequential computation it would have used to answer directly.
That is the whole mechanism, and it has three consequences worth stating plainly.
It helps most on problems with intermediate state. Multi-step arithmetic, logic with several constraints, planning, and anything where a partial result has to be held while the rest is computed. It helps least on tasks that are a single lookup or a single classification, where the answer is one step from the input.
It helps models above a size threshold. The original paper reports the effect emerging at scale: chain of thought produced large gains on models in the tens of billions of parameters while producing flat or negative results on smaller ones. The reason is that the model has to be capable of producing a valid intermediate step at all. Instructing a small model to reason step by step can produce confident steps that are wrong, which is worse than a direct wrong answer, because the wrongness looks deliberate.
It changes the output, so it changes your latency, your token bill and your failure surface. A reasoning answer is longer than a direct answer. That cost is real, and the section on cost returns to it.
The named variants
Four variants appear often enough to deserve names, and choosing among them is most of the practical work.
Zero-shot chain of thought. You append "Let's think step by step" or an equivalent instruction and the model produces its own reasoning without examples. It was reported in 2022 as a single instruction that improved accuracy across a range of benchmarks, and it remains the cheapest intervention available.
Few-shot chain of thought. You provide two to five worked examples that include the intermediate reasoning. This is what the original paper describes, and it gives you more control because the examples set the shape of the reasoning you want. It costs context window on every call.
Structured reasoning. Instead of free prose, you require a specific format: a numbered list of steps, a JSON object with a steps array and a final_answer field, or a filled-in template. Structured reasoning is what makes a trace machine-checkable, and it is what you should use in any system where a downstream component consumes the reasoning.
Program-aided reasoning. The model writes code instead of prose, and the code is executed. Arithmetic moves out of the model and into an interpreter, which removes an entire class of errors. This variant trades model accuracy for infrastructure: you now have to run untrusted code, which is a security decision, not a prompting one.
What chain of thought is not
It is not a debugger. A trace shows you text the model produced, not the computation that produced the answer. The next section explains the difference and why it matters.
It is not a substitute for a tool. If the task is arithmetic or data retrieval, a calculator or a query gives you a correct result. Reasoning improves the model's chances of getting arithmetic right; a tool removes the question.
It is not free. Every reasoning token costs money, adds latency and consumes context you may need for retrieved documents.
The Technique Grew Up: Reasoning Models
If you learned chain of thought as a prompt you write, the biggest change since is that a class of models now does it internally. Reasoning models allocate a variable amount of computation before producing their answer, and that computation is generated as a chain of thought.
What this changes for you:
You often no longer need to ask. A reasoning model will produce an internal chain regardless of your instruction. Adding "think step by step" to a reasoning model can be redundant, and on some models it degrades the output by interfering with the format the model was trained to use.
You now control the amount, not the presence. Most reasoning models expose an effort or thinking-budget setting: a low setting for a simple task, a high setting for a hard one. This is the correct control surface, and it maps directly onto your cost decision. A classification task does not need a high reasoning setting, and paying for one is a straightforward waste.
The trace is often summarized, and sometimes withheld. Providers differ on what they return. Some expose the full reasoning text, some expose a summary, and some return only the answer with the reasoning bill attached. Any verification design you build must be built against what your provider actually returns, and that is a fact to check rather than assume.
The prompt-engineering surface moved. With a reasoning model, the control you have sits in the task definition, the output contract, the examples and the tools you grant, not in telling the model to reason. "Be thorough" is now a budget instruction rather than a technique.
The practical rule for 2026. Ask which class of model you are calling before you write the prompt. On a standard model, chain of thought is a technique you apply. On a reasoning model, it is a resource you budget. Applying the wrong one produces a prompt that is either redundant or actively harmful.
Writing a Chain of Thought That Works
The technique is simple and the writing is not, because a chain of thought is a specification for how to reason, and most prompts leave that unspecified.
Rule 1: State the output contract, separately from the reasoning. The model must know what the final answer looks like, and it must know that the reasoning is not the final answer. A prompt that asks for reasoning and an answer in one blob produces output you cannot parse. State it explicitly: "reason in at most six numbered steps, then output the answer as a single line beginning with ANSWER: ".
Rule 2: Name the steps you want, when you know them. For a reconciliation task, the steps are known: find the two figures, compute the difference, identify which is larger, state which side is short. Writing those four steps into the prompt is worth more than any generic instruction to reason carefully, because it removes the model's freedom to choose a method you did not want.
Rule 3: Constrain the length of the reasoning. An unbounded trace drifts. "At most six steps" keeps the output parseable and keeps the cost predictable. When the model needs more steps, you will see it fail in an obvious way rather than in a diffuse one.
Rule 4: Give the model somewhere to put its uncertainty. A step that says "unknown, needs a lookup" is more useful than a confident invented value. Ask for it: "if a required value is not present in the input, write MISSING for that step and continue". This turns a silent hallucination into a visible branch.
Rule 5: Separate the reasoning from the verdict when a decision follows. If a downstream system acts on the answer, the answer should be a machine-readable field, not a sentence inside a paragraph. "Reason, then output a JSON object with decision, confidence and reasoning_steps" is a contract you can validate.
A chain-of-thought skeleton
This is the shape that works for most analytical tasks. Adapt the step names:
You are analysing a vendor invoice against a purchase order. Reason in at most five numbered steps: 1. List the line items on the invoice with their amounts. 2. List the line items on the purchase order with their amounts. 3. For each item present in both, state the difference. 4. List items present in only one of the two documents. 5. State whether the invoice total is above, equal to, or below the order total. If a value required for a step is absent from the documents, write MISSING for that step. After the steps, output exactly one JSON object on its own line: {"total_delta": <number>, "verdict": "over" | "equal" | "under", "items_only_on_invoice": [...], "items_only_on_order": [...]} Do not add commentary after the JSON.
Three properties of that prompt are deliberate. The steps are concrete and countable. The missing-value rule gives the model a legal way to admit ignorance. And the output is a strict contract, so a validation failure is detectable rather than invisible.
Match the reasoning style, not just the answer format. If your examples reason in five terse steps, the model will reason in five terse steps. If they reason in prose paragraphs, expect prose. Your examples set the shape as much as the content.
Include one case where the correct outcome is "cannot determine". This is the single highest-value example you can add. It gives the model a demonstration that the honest answer is sometimes a refusal, which measurably reduces invented values.
Do not use examples from your evaluation set. The example set is training data for the prompt, and scoring the prompt on its own examples measures memorization.
A Worked Example, Prompt by Prompt
The technique is easier to believe when you see the same task attempted three ways. This example uses a scheduling constraint problem, which is a good test because the reasoning is genuinely sequential: a partial result constrains the next step.
The task. Four meetings must be placed in three rooms across two days. Certain pairs cannot overlap. Determine whether a valid arrangement exists and produce one.
Attempt 1, direct answer. "Place meetings A, B, C and D in rooms 1 to 3 across Monday and Tuesday, respecting the following conflicts. Return an arrangement." This is the baseline. The model answers in one pass, and when the constraints interact it will frequently produce an arrangement that violates one of them, without flagging the violation.
Attempt 2, zero-shot chain of thought. The same prompt with one line added: "Work through the constraints one at a time before you answer." Accuracy improves, and the output becomes inconsistent in shape: sometimes a list, sometimes a paragraph, sometimes an arrangement with no explanation.
Attempt 3, structured chain of thought. The prompt now states the contract and the steps:
Reason in at most six numbered steps: 1. List every conflict pair. 2. For each conflict pair, state the two meetings that cannot share a time slot. 3. Choose an order for the meetings from most constrained to least. 4. Place the most constrained meeting first and record the slot. 5. Place each remaining meeting in a slot that respects every conflict so far. If no slot works, write IMPOSSIBLE for the meeting and continue. 6. State whether an arrangement was produced. Then output one JSON object: {"arrangement": [{"meeting": "A", "day": "Mon", "room": 1}, ...], "verdict": "placed" | "impossible"} If step 5 records IMPOSSIBLE for any meeting, the verdict is "impossible" and the arrangement contains only the meetings that were placed.
The third version is longer than the other two and it produces a parseable result, a visible failure when the constraints are unsatisfiable, and a fixed shape that a validator can check. That is the point of the whole technique: you are not asking the model to be smarter, you are giving it a procedure and a place to put each intermediate result.
Faithfulness: Why You Cannot Read the Answer Off the Trace
Here is the finding that produces most of the confusion around this technique. The reasoning text a model produces is not a guaranteed record of the computation that produced its answer.
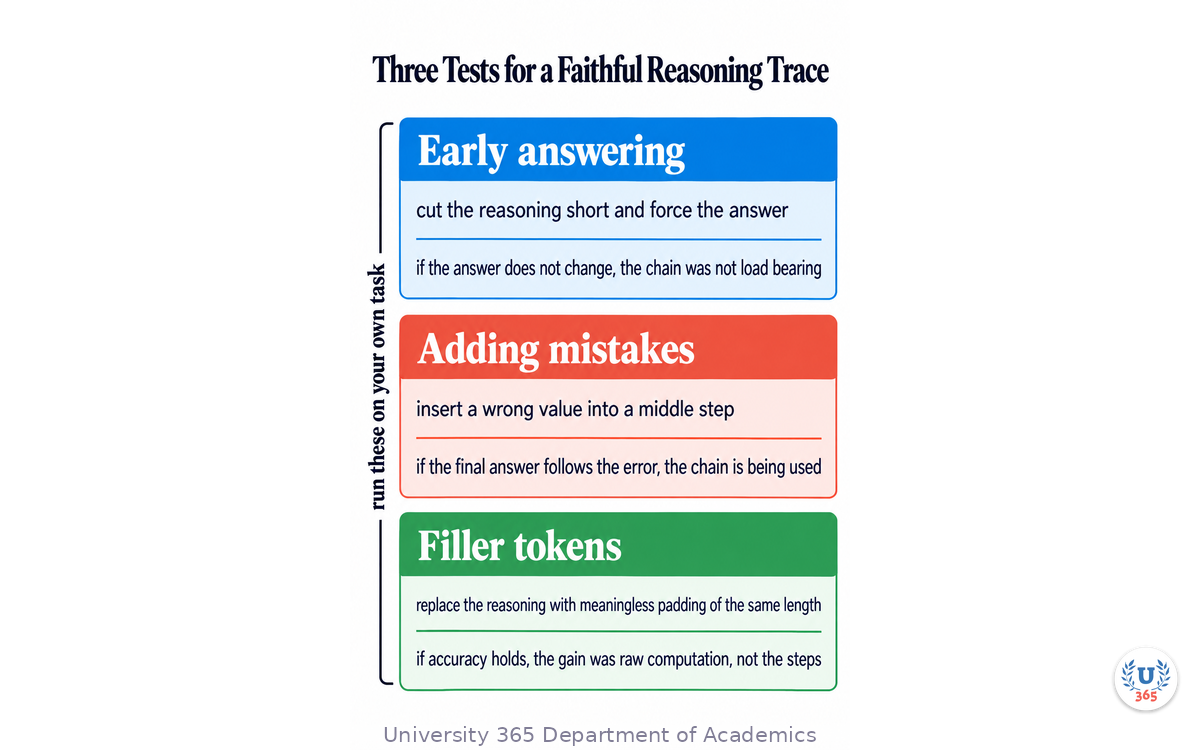
The measurement work is explicit. In "Measuring Faithfulness in Chain-of-Thought Reasoning", published in 2023 by Tamera Lanham and co-authors at Anthropic, the authors test three hypotheses about why chain of thought helps, and they find that the stated reasoning is frequently not what caused the answer. Their tests are worth knowing because you can run similar ones:
Early answering. Truncate the reasoning chain and see whether the model still reaches the same answer. If it does, the reasoning was not load-bearing for that answer.
Adding mistakes. Insert an error into the chain of thought and see whether the model follows it. If the final answer does not change, the model was not reading its own reasoning.
Filler tokens. Replace the reasoning with meaningless padding of the same length. If accuracy does not drop, the gain came from extra computation rather than from the specific steps.
Their headline conclusion is uncomfortable and useful: models show large variation across tasks in how strongly they rely on their own chain, and as models become larger and more capable they produce less faithful reasoning on many of the tasks studied. A companion result from the same period, "Language Models Don't Always Say What They Think" by Miles Turpin and co-authors, demonstrated the practical shape of the problem: adding a biasing feature to the input changed the model's answer, while the model's stated reasoning never mentioned the bias.
By 2026 this has become an active research area rather than a settled one. Work published through 2026 on reasoning-model monitorability reports that current reasoning models struggle to control what they reveal in their chains of thought, which cuts both ways: you cannot reliably force a model to hide its reasoning, and you cannot assume that what you see is complete.
What this means for how you use the trace
Use the trace to improve accuracy, not to justify a decision. The trace is a performance artifact. The score is the evidence.
Verify the answer, not the story. If the answer is checkable, check it. Run the arithmetic, validate the JSON, query the database. A trace is not a substitute for a check, and a fluent trace makes an unchecked answer feel checked.
Treat a trace as an input to review, not as a replacement for it. A human reading a trace can spot an obviously wrong step, which is genuine value. That is a different claim from "the trace explains why the model answered as it did", which the research does not support.
Measuring Whether the Reasoning Is Load-Bearing
The faithfulness result does not mean the technique is unreliable. It means the technique's value has to be measured rather than assumed, and the measurement is available to you.
Test 1: does the reasoning improve the score at all? Run the same evaluation set twice: once with the plain prompt, once with the chain-of-thought prompt, both on the same frozen model. Report both numbers. If the difference is inside the noise of your set, you have measured nothing, and the honest conclusion is that the technique did not help on this task.
Test 2: does a truncated chain change the answer? For a sample of your cases, cut the reasoning off after the first step and force the model to answer. Count how often the answer changes. A high rate means the later steps were carrying the answer; a low rate means the model had the answer early and the rest is decoration.
Test 3: does an injected error propagate? Insert a wrong intermediate value into the trace and let the model continue. If the final answer follows the injected error, the chain is being used. If the answer ignores it, the chain is not driving the result.
Test 4: is the error caught by your own validation? Take the cases where the reasoning arrived at a wrong final answer. How many of them would your output validation have flagged? This number tells you whether your guard is doing the work your trust in the trace is being asked to do.
Test 5: does the reasoning cost more than it earns? Compute cost and latency per request with and without reasoning, and compare to the accuracy difference. On a task where reasoning buys one point of accuracy for three times the latency, the honest answer may be that a direct prompt with a stricter output contract is the better system.
A measurement design for one afternoon
Take 60 real cases, split them 40 for development and 20 held out. Run four configurations on all 60: direct answer, zero-shot chain of thought, structured chain of thought, and structured reasoning with one "cannot determine" example added. Freeze the model. Score all four with the same metric. Then run tests 2 and 3 on the best configuration alone. You will finish with four numbers, a truncation-change rate, an error-propagation rate, and a defensible statement about whether the technique earned its cost on your task. That is the whole evidence base you need, and it takes less time than arguing about it.
Where Chain of Thought Fails in Production
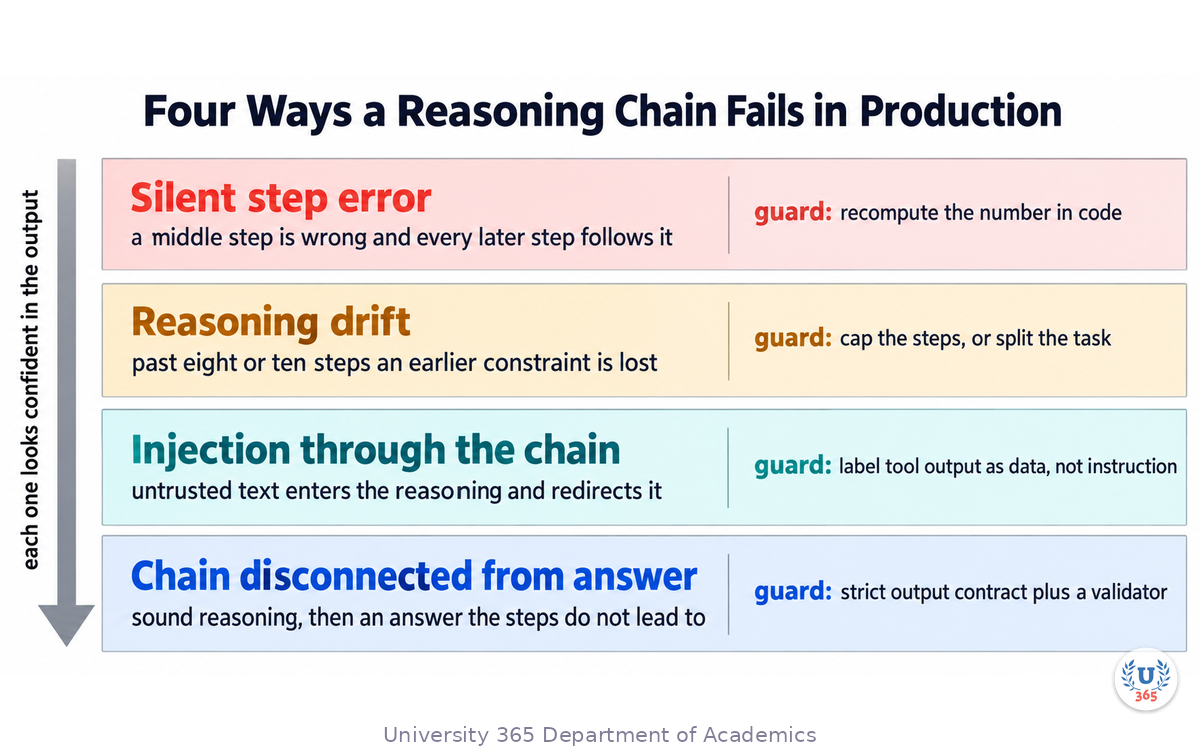
Four failure patterns account for most of the damage, and each has a specific guard.
Silent step errors. A middle step is wrong, the later steps follow it, and the final answer is confidently wrong. This is the most common failure and it is invisible in the output. Guard: make each step checkable where possible, and validate the final output against an independent source. When a step computes a number, recompute it in code rather than trusting it.
Reasoning drift over a long chain. Past eight or ten steps, the model loses track of an earlier constraint and produces an answer that contradicts a step it wrote itself. Longer chains are not automatically better. Guard: cap the step count and, for genuinely hard problems, split the task into two calls with the first call's output as the second call's input.
Prompt injection through the reasoning. If the input contains text from an untrusted source, that text can enter the reasoning and redirect it. A document that contains a sentence looking like an instruction is the classic case. Guard: label untrusted content as data, constrain the model to extract from it rather than to follow it, and never let a document's content change the output contract. This risk is identical for reasoning traces and for tool results, and it is covered in more depth in our lecture on the Model Context Protocol.
Reasoning that is not connected to the answer. The model produces a sound chain and then answers something else, because the contract between the two was never stated. Guard: a strict output contract with the answer in a machine-readable field, plus a validator that rejects a response whose answer is absent.
Chain of Thought in an Agent
An agent adds one element to everything above: the reasoning connects to actions. That changes what a trace is for.
Reasoning before a tool call is a plan, and it should be checkable. When an agent reasons its way to calling a tool with specific arguments, that reasoning is the plan. Validate the plan's output, the tool arguments, against a schema before the call runs. This is where an agent's reasoning failure turns into a real-world effect, so it is where the validation belongs.
Reasoning after a tool call is a summary, and it should not be trusted. A tool result returning an error, and the model reasoning that the call succeeded anyway, is a common and dangerous pattern. Guard: the check is the tool's own read-back, never the model's account of it. If the write was supposed to change a record, read the record.
Interleaved reasoning is where reasoning models earn their keep. An agent that alternates reasoning and tool calls can adapt a plan to a result: query, see an unexpected schema, reason again, adjust the query. This is a real capability gain over a single reasoning pass, and it is also where cost grows fastest, because every step may trigger a new reasoning phase.
Keep the trace out of the context you cannot afford. In a long agent run, accumulated reasoning consumes context that retrieved documents need. Summarize completed phases and drop the raw traces of steps that are already validated.
The verification rule for agents. The model's reasoning is a plan; the tool's read-back is the evidence. Keep the two separate in your code and in your review process, because the failure mode where they merge is the one that ships silently.
Cost, Latency and the Decision to Reason
Reasoning is a resource. Treat the decision to spend it the same way you treat any other per-request cost.
Write the budget per request class. A classification call, an extraction call and a hard analysis call have different values. Set a reasoning effort level, or a step cap, per class, and record the choice next to the prompt. A team that reasons at maximum on every call is paying for a capability it is not measuring.
Measure latency as a user-facing number. Reasoning adds time before the first useful output. If the interface waits for the whole response, the user waits longer. If the interface can stream the reasoning, the user sees progress, and whether that is appropriate depends on the audience. Decide deliberately rather than discovering it in production.
Account for reasoning tokens in your retrieval budget. A high reasoning setting can consume context that documents need, which reduces retrieved evidence and can lower accuracy while raising cost. The two budgets are connected, and tuning one without watching the other produces confusing results.
Re-decide at every model version change. A new model version may reason by default, may ignore your instruction, or may expose a different effort scale. Re-run the comparison from the measurement section on each upgrade. A reasoning configuration is a configuration, not a constant.
Feynman Summary: Explain It Like You Are 12
Imagine you have to solve a hard puzzle in your head, and you are only allowed one thought before you answer. You can do that for easy puzzles. For a hard one, one thought is not enough, so you guess.
Now imagine you are allowed to write down your working. You write the first number, then the second, then the difference. Each line you write stays in front of you, so the next line can use it. Nothing about your brain got better. You just gave yourself room to work.
That is what asking an AI to think step by step does. Writing each step gives it more room, because every word it writes becomes something it can read back.
The trap is what people do with the written working. It looks like a tidy explanation of the answer, so it is tempting to read it as the reason. It is often not. The AI can write a tidy-looking set of steps and then answer something the steps do not lead to, or it can decide the answer early and write steps that merely fit. Tests have shown this repeatedly.
So use the written working to get better answers, and check the answers with something else. If a step does a sum, add it up yourself. If the answer is supposed to be in a certain format, check the format. The working is a tool for thinking, not a receipt for the result.
Mindmap: The Complete Picture
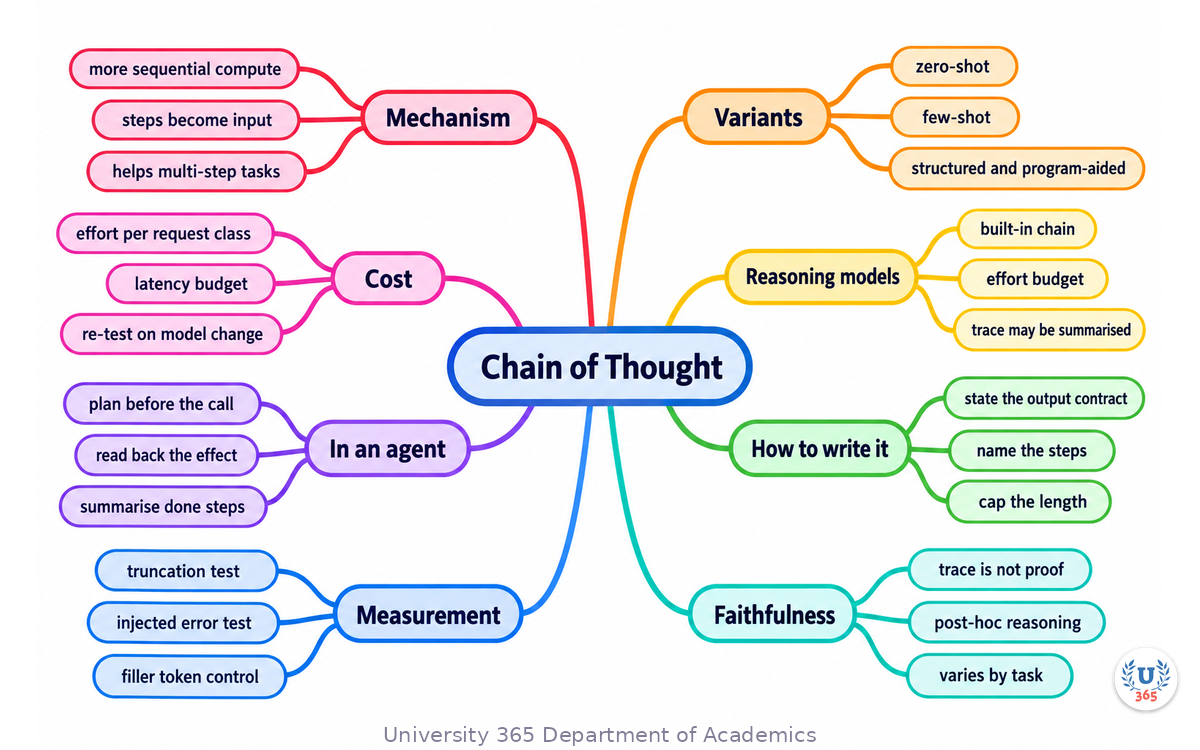
The mindmap puts the mechanism at the centre and branches to the variants, the reasoning-model generation, the writing rules, the faithfulness result, the measurement tests, the failure modes, the agent case and the cost trade-off.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Test Whether Your Reasoning Helps
This exercise takes about two hours and produces a measured answer to a question most teams answer by belief: does asking for reasoning improve your task, and is the reasoning doing the work?
Step 1: Choose one task and freeze everything
Pick a task you already run in production. Write the output contract. Freeze the model and its version, and record both. Do not change the model or the prompt style during the exercise.
Step 2: Build 60 cases and split them
Forty for development, twenty held out. Take them from real traffic. Include at least four cases where the correct answer is "cannot determine", because those cases decide whether the reasoning is honest.
Step 3: Write four configurations
A direct answer. B zero-shot chain of thought. C structured chain of thought with a step cap and a machine-readable answer. D configuration C plus one worked example whose correct outcome is "cannot determine".
Step 4: Score all four on all 60 cases
Use one deterministic metric where you can. Report the four scores on the development split and on the held-out split separately. An improvement that appears only on the development split is not a result.
Step 5: Run the truncation test on the winner
Take twenty cases, cut the reasoning after the first step, force the answer, and count how often the answer changes. Write the number down.
Step 6: Run the injected-error test on the winner
Take twenty cases, insert a wrong intermediate value, and count how often the final answer follows the error. Write that number down too.
Step 7: Run the cost comparison
Measure tokens and wall-clock for configuration A and configuration C on the same twenty cases. Compute the cost per request for each.
Step 8: Write the one-page finding
Four scores, two test rates, two costs, and one sentence stating which configuration you will run in production and why. Include the case where you are least confident.
What to look for
If configuration C beats A on the held-out set and the truncation test shows the answer changes when the chain is cut, the reasoning is doing real work. If C beats A and the truncation test shows the answer rarely changes, you have a computation gain without a reasoning gain, which is still useful and is a different claim. If D beats C, your task has an honesty problem, and adding the "cannot determine" example is the fix.
Applied AI connection
This is CI-First applied to a technique that is easy to adopt on faith. You define the metric, you freeze the model, you measure the technique instead of assuming it, and you keep the decision about what to trust. The machine produces the reasoning; the human decides what that reasoning is evidence for, and the answer is usually "a better answer", not "an explanation".
Glossary
Term | Definition |
Chain of thought (CoT) | Prompting a model to produce intermediate reasoning steps before its final answer, which increases the computation available for the answer. |
Zero-shot CoT | Eliciting reasoning with an instruction alone, without worked examples, such as "think step by step". |
Few-shot CoT | Providing worked examples that include the intermediate reasoning, which sets the shape of the reasoning the model produces. |
Structured reasoning | Requiring the reasoning in a fixed format, such as numbered steps or a JSON object with a steps array, so it can be parsed and validated. |
Program-aided reasoning | Having the model write code that is then executed, moving arithmetic out of the model and into an interpreter. |
Test-time compute | Computation performed during generation rather than during training; writing reasoning tokens is one way to spend it. |
Faithfulness | The degree to which a model's stated reasoning reflects the computation that produced its answer. Frequently low. |
Early answering | A faithfulness test that truncates the reasoning to see whether the answer still appears, which reveals whether the chain was load-bearing. |
Adding mistakes | A faithfulness test that corrupts a reasoning step to see whether the final answer follows the corruption. |
Filler tokens | A control test that replaces reasoning with meaningless padding of the same length, isolating the effect of extra computation from the content of the steps. |
Reasoning model | A model that generates an internal chain of thought before answering and typically exposes an effort or thinking-budget setting. |
Reasoning effort | The provider control that sets how much internal computation a reasoning model spends on a request. |
Output contract | The explicit specification of the final answer's shape, kept separate from the reasoning so the answer can be validated. |
Step cap | A limit on the length of the reasoning, which keeps the output parseable and the cost predictable. |
Silent step error | A wrong intermediate step that later steps follow, producing a confidently wrong answer with no visible signal. |
Reasoning drift | Loss of an earlier constraint over a long chain, producing an answer that contradicts a step the model itself wrote. |
Injected error | A deliberate wrong value inserted into a reasoning chain during testing, used to measure whether the chain drives the answer. |
Monitorability | The property of a reasoning model that determines how reliably its chain of thought can be observed; an active research area in 2026. |
Quiz: TEST YOUR UNDERSTANDING
1. What does chain of thought change about a model's computation?
A) It increases the model's parameter count
B) It gives the model more sequential computation, because each reasoning token becomes available as input for the next
C) It retrieves relevant documents from a database
D) It fine-tunes the model on your examples
2. Which task benefits LEAST from chain of thought?
A) Multi-step arithmetic with intermediate values
B) A single-label classification where the answer is one step from the input
C) Constraint satisfaction with several interacting rules
D) Planning a sequence of dependent actions
3. What does the faithfulness research show about a reasoning trace?
A) The trace always reflects the computation that produced the answer
B) The trace frequently does not reflect that computation, and larger, more capable models can be less faithful on some tasks
C) Traces are only unfaithful when the model is small
D) Faithfulness cannot be tested
4. What does the truncation test measure?
A) How long the reasoning takes to generate
B) Whether the answer changes when the reasoning is cut short, which shows whether the chain was load-bearing
C) Whether the model can be made to hide its reasoning
D) The token cost of the reasoning
5. You add "find the best alternative" to a prompt that also asks the model to report impossibility. What happens?
A) The model reports impossibility more reliably
B) The model loses its legal way to report impossibility and will always produce an arrangement
C) The output becomes shorter
D) The reasoning becomes faithful
6. On a reasoning model, what is the correct control surface?
A) A "think step by step" instruction, always
B) The reasoning-effort or thinking-budget setting, chosen per request class
C) Lowering the temperature
D) Increasing the number of examples
7. What is the correct verification rule for an agent that reasons before a tool call?
A) Trust the reasoning if it reads coherently
B) Validate the tool arguments against a schema and confirm the effect by reading the record back
C) Ask the model to confirm it worked
D) Disable reasoning for tool calls
8. Why does an "over-reasoning" failure matter on a simple classification task?
A) Because it raises the token bill only
B) Because the chain gives the model room to justify a wrong label, which makes the error harder for a reviewer to spot
C) Because the model refuses to answer
D) Because the output contract is broken
9. Which test isolates the value of extended computation from the content of the reasoning?
A) The filler-tokens control
B) The injected-error test
C) The held-out set
D) The step cap
10. What is the main production risk of a long reasoning chain that exceeds about eight to ten steps?
A) The model refuses to continue
B) Reasoning drift, where an earlier constraint is lost and the answer contradicts the model's own step
C) The output contract becomes invalid by definition
D) The cost falls
Answers: 1-B, 2-B, 3-B, 4-B, 5-B, 6-B, 7-B, 8-B, 9-A, 10-B
Related Resources
U365 INSIDE Publications
Lecture: Prompt Engineering: Craft the Best Prompts with the OPRO Method: the search-based counterpart to this lecture, where the instruction itself is optimized against a score
Lecture: Prompt Engineering at Production Scale: the system-level view of prompts, evaluation and versioning
Lecture: The Model Context Protocol (MCP): Connecting AI to Everything: the injection risk that reaches a reasoning chain through tool results
External Resources
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models (Wei et al., 2022, arXiv 2201.11903): the paper that introduced few-shot chain of thought and reported the scale dependence: arxiv.org/abs/2201.11903
Large Language Models are Zero-Shot Reasoners (Kojima et al., 2022, arXiv 2205.11916): the origin of the "think step by step" instruction as a standalone technique: arxiv.org/abs/2205.11916
Measuring Faithfulness in Chain-of-Thought Reasoning (Lanham et al., 2023, arXiv 2307.13702): the early-answering, adding-mistakes and filler-token tests, and the finding that stated reasoning is frequently not the computation behind the answer: arxiv.org/abs/2307.13702
Language Models Don't Always Say What They Think (Turpin et al., NeurIPS 2023, arXiv 2305.04388): the demonstration that a biasing feature can change the answer without appearing in the stated reasoning: arxiv.org/abs/2305.04388
Program of Thought Prompting (Chen et al., 2022, arXiv 2211.12588): the program-aided variant, where the model writes executable code instead of prose reasoning: arxiv.org/abs/2211.12588
OWASP Top 10 for Large Language Model Applications: the application-security framing for prompt injection, which reaches reasoning chains through untrusted input: owasp.org/www-project-top-10-for-large-language-model-applications
Related U365 Lectures (Coming Soon)
Measuring Reasoning Quality: Test Sets for Chain-of-Thought Prompts, in the AI Skills Series
Monitorability and Oversight of Reasoning Models, in the AI Skills Series
U.Copilot for This Lecture
Use this prompt with your own AI assistant to design a chain-of-thought test for a task you own. It follows the UP-Context-Engineering method: context first, then the task, then the constraints, then the output shape.
CONTEXT I want to know whether asking for reasoning actually improves one of my tasks, and whether the reasoning is doing the work. The task: [one sentence] The exact output I need: [name the output contract] The model and version I run it on: [name it, and say whether it is a reasoning model] How much reasoning it does today: [none, a think-step-by-step instruction, or an effort setting] How many real examples I have, and the split I can hold out: [numbers] Whether the answer is checkable by code: [yes, how, or no] My current latency limit per request: [milliseconds or seconds] TASK 1. Tell me whether this task is a candidate for chain of thought, and say why in terms of intermediate state. 2. Write four configurations for me: direct answer, zero-shot CoT, structured CoT with a step cap and a machine-readable answer, and structured CoT plus one worked example whose correct outcome is "cannot determine". 3. Write the structured prompt for me, with an explicit output contract and a rule for missing values. 4. Design the truncation test for my task: how to cut the chain, what to hold constant, and what rate would tell me the chain is load-bearing. 5. Design the injected-error test for my task, including where in the chain to insert the error. 6. Tell me what my output validation should check, given that I should not trust the trace as evidence. 7. Name the two failure modes from this lecture most likely to hit my task, and the guard for each. CONSTRAINTS Use only what I gave you plus this conversation. Do not invent benchmark numbers, prices or model version names. Where a number depends on my example set, say so instead of estimating. Do not instruct me to trust the reasoning trace as proof of the answer. Do not use em dashes. OUTPUT First a verdict on whether to test chain of thought on this task, with the reason. Then the four configurations as labelled headings. Then the structured prompt as a code block. Then the two test designs. Then the validation checklist. Then the failure-mode table.
Next Steps
Decide which model class you are calling before you write the prompt. On a standard model, chain of thought is a technique. On a reasoning model, it is a budget you set per request class.
Write the output contract separately from the reasoning this week. A contract in a machine-readable field is what turns a plausible trace into a validated answer.
Run the four-configuration comparison on 60 real cases and report the held-out numbers. Belief about this technique is easier to hold than a measured result, and the measurement takes an afternoon.
Run the truncation and injected-error tests on your winner. Those two rates are the difference between claiming the reasoning works and showing that it does.
Add one "cannot determine" example to any prompt where inventing a value is costly. It is the highest-value single example you can add, and it changes the model's willingness to admit a gap.
Chain of thought is the most widely adopted reasoning technique in production and the most widely misread. Keep the two claims apart: it reliably improves the answer on the right task, and it does not reliably explain the answer. Measure the first, and never let the second stand in for a check.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current technical details against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Technology (UIT).
Sam Utteker, Dean of Technology, UIT
Signed for the academic year 2026.



Comments