
Claude Fable 5: Anthropic's Next-Generation Intelligence for Long-Running Agents

Updated: 6 days ago
Status: Active | Last tested: 2026-08-24 (claude-fable-5) | Re-check: trigger-based (max 6 months)

Tool Snapshot
Tagline: Next-generation intelligence for long-running agents
Category: Large Language Model
Provider: Anthropic
Version tested: claude-fable-5
Context window: 1,000,000 tokens (1M)
License: Proprietary (API-only)
Platforms: Claude API, Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry
Primary use cases:
Long-horizon agentic workflows (multi-step research, coding, analysis)
Complex creative writing (novels, screenplays, long-form articles)
Enterprise knowledge work requiring sustained context across documents
Extended coding sessions with autonomous debugging and refactoring
Research synthesis across large document sets
Pricing summary: API: $10 per million input tokens, $50 per million output tokens. Prompt caching: $12.50/MTok (5m writes), $20/MTok (1h writes), $1/MTok cache hits. Consumer plans available on claude.com.
Official links:
Official page: https://docs.anthropic.com/en/docs/about-claude/models
API documentation: https://platform.claude.com/docs
Pricing: https://claude.com/pricing
Artificial Analysis: https://artificialanalysis.ai/models/claude-fable-5
LLM specifications:
Context Window: 1,000,000 tokens (1M)
Max Output: 128,000 tokens (128K)
Thinking: Adaptive (always on)
Default Effort: high
Api Id: claude-fable-5
Knowledge Cutoff: January 2026
Input Modalities: Text and image
Output Modalities: Text
Architecture: Transformer-based, proprietary (Anthropic)
Parameters: Not disclosed (proprietary)
Variants: Claude Fable 5 (primary), Claude Mythos 5 (limited availability, same pricing)
Local Availability: Not available on Ollama (proprietary, API-only)
Platforms: Claude API, Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry
Released: June 2026
CI-First Benefit Score | 5.2/10 - CI-First Positive |
Time / Quantity / Quality / Skill | 5 / 7 / 6 / 3 |
CI-First Profile | Co-Creator and Thought Partner (1), Coach and Tutor (3) |
Humics Protection | Humics-Neutral (-1) |
AI Imposture Risk | Medium |
User Sentiment | Positive but cost-conscious (Reddit, Artificial Analysis) |
Pricing | API: $10/$50 per MTok (highest in Claude lineup) |
Platforms | Claude API, Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry |
For detailed explanations of the CI-First evaluation terms used in this review, including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
The Problem
Complex knowledge work requires models that can sustain coherent reasoning across long sessions. Most LLMs lose context, repeat themselves, or produce inconsistent outputs when working through multi-step problems that span thousands of tokens and many tool calls. Long-running agents need a model that maintains quality across extended trajectories without degradation.
Creative professionals and knowledge workers also face a related problem: the best models for quick tasks are often too shallow for sustained creative or analytical work. You need a model that can hold an entire novel outline, a complex research dossier, or a large codebase in its working memory and produce coherent, contextually aware output at every step.
The Outcome
You get a model with a 1M-token context window and 128K max output that maintains reasoning quality across long sessions. Claude Fable 5 handles extended agentic workflows where other models degrade. On the Artificial Analysis Intelligence Index, it scores 62 (ranked 3 of 187 models), placing it well above the median of 35.
For writers and researchers, the 1M context window means you can load entire documents, reference materials, and prior work into a single conversation. The adaptive thinking mode (always on, default effort high) means the model reasons through complex problems rather than pattern-matching to surface answers.
The cost is significant: $10 per million input tokens and $50 per million output tokens, making it the most expensive model in the Claude lineup. This pricing positions it for high-value tasks where quality and context length matter more than cost efficiency.
Who Should Use Claude Fable 5
Claude Fable 5 targets users who need the highest available model capability for sustained, complex work.
Students (advanced and graduate level): Researchers working on long-form theses, literature reviews, or multi-document synthesis. The 1M context window lets you load entire reference sets. Best for those who already understand their field and need a reasoning partner, not a tutor.
Professionals: Software engineers running long coding sessions, analysts working across large document sets, and creative writers developing extended narratives. The model supports tool use and multi-step agent workflows.
Everyone: This is not a general-purpose chatbot. The high cost per token makes it impractical for casual use. Choose Claude Sonnet 5 or Haiku 4.5 for everyday tasks.
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Advanced coding and AI coursework benefit from the 1M context window and sustained reasoning. |
UIB (Business Management, Entrepreneurship) | Moderate | Long-form business analysis and strategic document synthesis. |
UIC (Digital Communication, Marketing) | Low | Not a primary tool for communication coursework, though long-form content drafting is possible. |
UID (Digital Design, UX/UI) | Low | Not directly applicable to design coursework, though design documentation can benefit from long context. |
Skill level: advanced. Prerequisites: familiarity with prompt engineering and context management. Time to first result: 15 minutes. Time to competence: several sessions of guided use.
How Claude Fable 5 Works
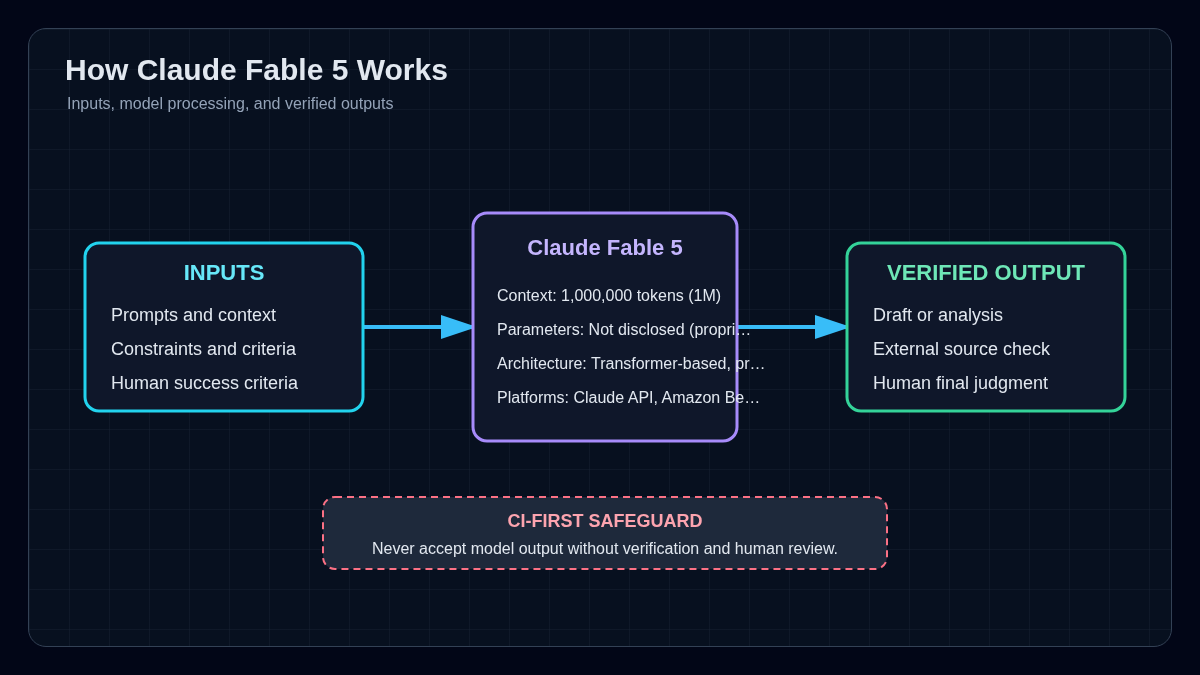
Claude Fable 5 is a proprietary transformer-based model from Anthropic, released June 2026. Anthropic has not disclosed the parameter count or architecture details.
Inputs
Text and image. You send messages via the Claude API, Amazon Bedrock, or Google Cloud Vertex AI. The model processes up to 1 million input tokens in a single request.
Outputs
Text only, up to 128,000 tokens per response. The adaptive thinking mode is always on with a default effort level of high, meaning the model reasons through problems before producing output.
Underlying Technology
Underlying technology: Transformer-based architecture with adaptive reasoning. The model uses a newer tokenizer (introduced with Claude 4.7 and later) that produces approximately 30 percent more tokens for the same text compared to earlier models. This contributes to improved performance but affects cost calculations.
Key Capabilities
Key capabilities: Tool use, vision (image input), multilingual support, and prompt caching. Prompt caching reduces costs significantly: cache hits cost $1 per million tokens (a 90 percent discount on the $10 base input price).
Integrations
Integrations: Claude API (first-party), Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry. Available through the Claude consumer app on claude.com.
Benchmark Position
Benchmark position: On the Artificial Analysis Intelligence Index v4.1.1 (which includes GDPval-AA v2, Terminal-Bench v2.1, Humanity's Last Exam, GPQA Diamond, and other evaluations), Claude Fable 5 ranks 3 of 187 models with a score of 62. It is among the leading models in intelligence but is expensive and slower than average (71 tokens per second vs. median 75).
Getting Started with Claude Fable 5
Installation
1. Choose your access method. For API access, sign up at platform.claude.com. For cloud deployment, use Amazon Bedrock or Google Cloud Vertex AI. For consumer use, visit claude.com.
2. Get your API key. After creating an Anthropic Console account, generate an API key from the dashboard. Store it securely.
3. Make your first API call. Use the model ID claude-fable-5 in your request. The endpoint accepts standard message format with text and image inputs.
4. Enable prompt caching for cost savings. Add cache_control to your system prompt or large context blocks. Cache hits reduce input costs from $10 to $1 per million tokens.
5. Set the max_tokens parameter. Fable 5 supports up to 128,000 output tokens. Adjust based on your task.
6. Configure tool use if needed. The model supports function calling for agentic workflows.
First 15 Minutes Checklist
15-minute checklist: (a) Create an Anthropic Console account. (b) Generate an API key. (c) Send a test message to claude-fable-5. (d) Verify the response. (e) Enable prompt caching on a second call. (f) Compare costs between cached and uncached requests.
Real Workflows
Workflow 1: Long-Form Research Synthesis
Learner type: Graduate researcher or professional analyst
CI-First benefit tags: Quantity (7), Quality (6)
Connects to: URC research methodology, U365 LIPS Digital Second Brain
Time estimate: 45-90 minutes per session
Step 1 (You): Gather 5-10 research papers or reports. Prepare a research question and sub-questions.
Step 2 (Model): Load all documents into the context window (up to 1M tokens). Ask the model to synthesize key findings across documents, identify contradictions, and note gaps.
Step 3 (You): Review the synthesis. Mark claims that need verification. Identify which sections are model-generated vs. source-quoted.
Step 4 (Model): Ask the model to expand specific sections with citations from the loaded documents. Request a structured summary with thematic groupings.
Step 5 (You): Cross-check 3-5 key claims against the original documents. Rewrite sections where the model's synthesis diverges from source intent.
Sample prompt:
I have loaded 8 research papers on transformer architecture improvements. Please synthesize: (1) the three most significant advances identified across these papers, (2) areas where the papers disagree, (3) methodological gaps that future research should address. For each claim, cite the specific paper and page. Do not speculate beyond what the documents state.
Verification checklist:
Multi-Model Check: Run the same synthesis through Claude Sonnet 5 and compare outputs.
External Source: Verify 3 key claims against the original documents.
Human Review: A subject-matter expert reviews the synthesis for accuracy and completeness.
CI-First Test: Could you have produced this synthesis without the model in the same time? If yes, the model added speed but not capability.
Workflow 2: Extended Coding Session with Autonomous Debugging
Learner type: Software engineer or UIT student
CI-First benefit tags: Time (5), Quantity (7)
Connects to: UIT Technology curriculum, SL-OS project documentation
Time estimate: 2-4 hours per session
Step 1 (You): Define the coding task. Load relevant codebase files and documentation into the context.
Step 2 (Model): Ask the model to implement a feature or fix a bug. The adaptive thinking mode reasons through the problem before writing code.
Step 3 (You): Review the generated code. Check for edge cases, security issues, and alignment with your codebase conventions.
Step 4 (Model): Ask the model to debug issues you identified. Provide error messages and context.
Step 5 (You): Run the code in your environment. Verify tests pass. Commit only after manual review.
Sample prompt:
I have loaded my Flask application code (15 files). Please implement a rate-limiting middleware that: (1) limits requests per IP to 100 per minute, (2) returns a 429 status with a Retry-After header, (3) uses Redis for distributed counting, (4) includes unit tests. Follow the existing code style in the loaded files.
Verification checklist:
Multi-Model Check: Ask Claude Sonnet 5 to review the same code for issues.
External Source: Run the code in a staging environment and verify behavior.
Human Review: A senior engineer reviews the code for security, performance, and maintainability.
CI-First Test: Did the model's output teach you something about the codebase or approach that you did not know before? If not, it was a typing shortcut, not a learning moment.
Strengths, Limits, and AI Imposture Risk
Strengths
Strengths:
Time (5/10): Significant time savings for long-horizon tasks. The 1M context window eliminates the need to chunk and re-summarize. However, verification of large outputs takes time.
Quantity (7/10): Genuine volume increase. 128K max output and sustained quality across long sessions produce real usable content, not surface volume.
Quality (6/10): Verified quality improvements on complex tasks. Intelligence Index score of 62 (rank 3 of 187) confirms strong reasoning. Quality degrades less than competitors on extended sessions.
Skill (3/10): Limited skill building. The model does the thinking for you. Prolonged use risks atrophying independent reasoning. Best used as a thought partner, not a replacement for your own analysis.
Limits
Limits:
Cost: At $10/$50 per million tokens, it is the most expensive Claude model. A single long-horizon agent session can cost $50-200 in API fees. Not suitable for high-volume or cost-sensitive applications.
Speed: 71 tokens per second is slower than average (median 75). For real-time applications, Claude Sonnet 5 or Haiku 4.5 are better choices.
No local deployment: The model is proprietary and API-only. Not available on Ollama or any local inference platform. Data privacy requires trust in Anthropic's infrastructure.
Verbose: The model generated 83M tokens during Intelligence Index evaluation (median 72M). This verbosity increases cost.
AI Imposture Risk
AI Imposture Risk:
Time Illusion: Medium. Fast generation masks slow verification. Reviewing 128K tokens of output takes real time.
Quantity Illusion: Low. Output volume is genuine and usable.
Skill Illusion: Medium. Extended reliance may weaken independent analytical skills. Users may mistake model reasoning for their own understanding.
U365 Co-Intelligence Rating
CI-First Profile
CI-First Profile: Primary: Co-Creator and Thought Partner (1). Secondary: Coach and Tutor (3). The model excels as a reasoning partner for complex tasks but is too expensive and verbose for routine tutoring.
Collaboration Mode
Collaboration Mode: Centaur. Clear division of labor: the model generates and reasons, you direct and verify. The model does not replace your judgment; it amplifies your capacity for sustained work.
CI-First Benefit Score
CI-First Benefit Score:
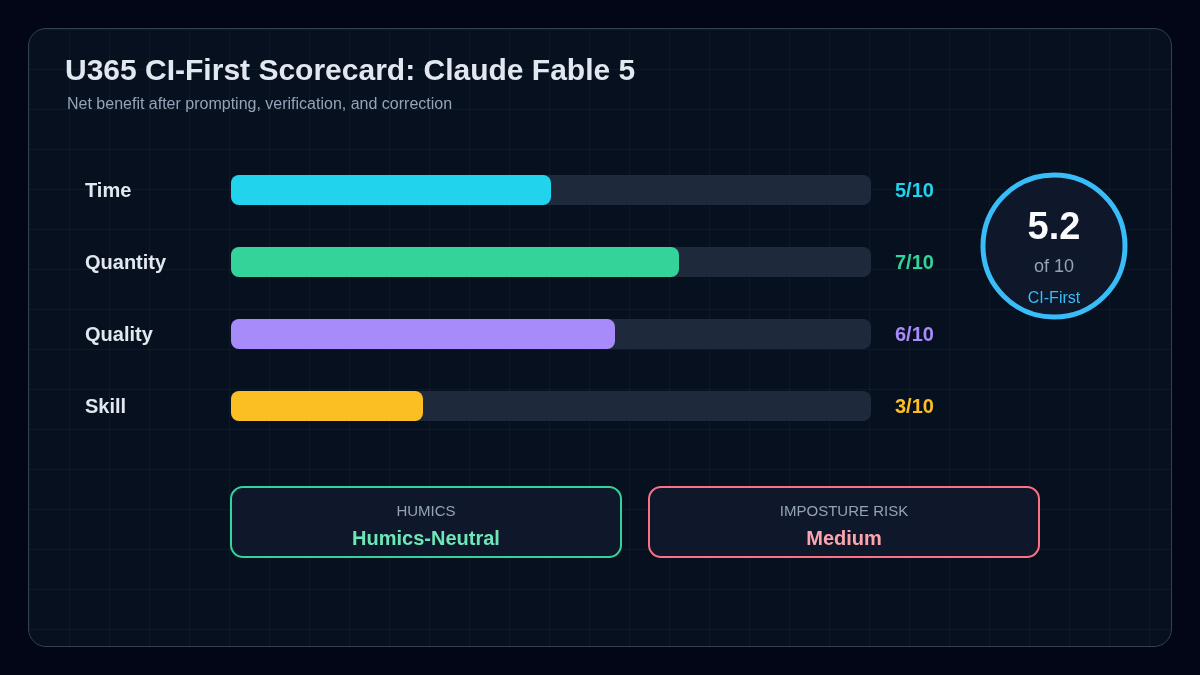
Time: 5 | Quantity: 7 | Quality: 6 | Skill: 3
Overall: (5 + 7 + 6 + 3) / 4 = 5.2/10
Band: CI-First Positive (4.1-6.0)
The model delivers genuine value for long-horizon tasks but does not build lasting skills. The high cost limits frequency of use, which paradoxically may protect against over-delegation.
Humics Protection Badge
Humics Protection Rating:
Creativity: 0 (Neutral) | Critical Thinking: -1 (Erodes) | Social Authenticity: 0 (Neutral)
Score: -1 | Badge: Humics-Neutral
The model's adaptive thinking mode can substitute for your own critical reasoning if you let it. The risk is that users delegate analysis entirely and lose the habit of independent thinking.
Superhuman Usage Guidance
Superhuman Usage Guidance:
When to invite the tool: long-horizon synthesis across many documents, extended coding sessions, complex multi-step research where context length matters.
When to keep the tool out: quick tasks (use Sonnet 5 or Haiku 4.5), tasks requiring data privacy (no local option), routine writing where cost matters.
U365 method integration: LIPS+CARE (load context into the model, verify with external sources), ULM+EVA (use for extended learning sessions but verify understanding independently).
Over-delegation warning: Do not use Fable 5 for tasks you do not understand. If you cannot evaluate the model's output, you are not co-creating; you are outsourcing. The high cost should prompt you to use the model only when the task complexity justifies it.
What Users Say
Aggregate Rating Table
Platform | Rating | Reviews |
Trustpilot | No reviews found for Anthropic or Claude Fable 5 specifically. | - |
G2 | No reviews found for Claude Fable 5 specifically. (Claude as a product has G2 presence but Fable 5 is too new for aggregated reviews.) | - |
Capterra | No reviews found. | - |
Product Hunt | No reviews found for Fable 5 specifically. | - |
Community discussion exists about the Claude model family. Sentiment is positive regarding capability and context length. Concerns focus on cost ($10/$50 per MTok is the most expensive in the Claude lineup) and speed (71 tokens/second is slower than average). Users praise the 1M context window for research and coding tasks. | Community threads | |
Artificial Analysis | Intelligence Index: 62 (rank 3 of 187). Speed: 71 tok/s (rank 79 of 187). Cost: $10/$50 per MTok (rank 79 of 187, expensive). The model is described as among the leading models in intelligence but particularly expensive and slower than average. | Aggregated metrics |
Ollama | Not available. Claude Fable 5 is proprietary and API-only. | - |
What Users Praise
What users praise: The 1M context window, sustained quality across long sessions, strong reasoning on complex tasks, and adaptive thinking that produces thoughtful responses.
What Users Complain About
What users complain about: High cost ($10/$50 per MTok), slower generation speed compared to Sonnet 5 and Haiku 4.5, verbosity that increases token costs, and lack of local deployment options.
Sentiment Summary
Sentiment summary: Positive but cost-conscious. Users who need the capability praise it. Users who try it for routine tasks find it overkill and too expensive.
U365 Editorial Note
U365 Editorial Note: User sentiment aligns with the CI-First evaluation. The model delivers genuine intelligence (CI-First Positive, 5.2/10) but at a cost that limits its applicability. The community's concern about cost matches our Time score of 5 (the model saves time on complex tasks but the verification overhead and cost reduce net time savings). The praise for context length and reasoning quality aligns with our Quantity (7) and Quality (6) scores. The lack of user complaints about skill erosion is notable but expected: the model is too new and too expensive for most users to have developed dependency patterns yet.
Comparison and Alternatives
Comparison with alternatives:
Claude Opus 5 ($5/$25 per MTok): Choose Opus 5 if you need complex agentic coding and enterprise work at a lower cost. Opus 5 has the same 1M context window and 128K max output but costs half as much. Fable 5 is better for: highest available capability, long-running agent trajectories. Opus 5 is better for: cost-sensitive complex work.
Claude Sonnet 5 ($2/$10 per MTok): Choose Sonnet 5 for the best combination of speed and intelligence. It is 5x cheaper on input and 5x cheaper on output than Fable 5. Sonnet 5 is better for: everyday tasks, real-time applications, high-volume use. Fable 5 is better for: tasks where the extra intelligence justifies 5x the cost.
Claude Haiku 4.5 ($1/$5 per MTok): Choose Haiku 4.5 for the fastest model with near-frontier intelligence. It is 10x cheaper than Fable 5. Haiku 4.5 is better for: high-volume, latency-sensitive tasks. Fable 5 is better for: tasks requiring deep reasoning that Haiku cannot provide.
GPT-5 (OpenAI, comparable pricing): Choose GPT-5 if you need the OpenAI ecosystem or specific integrations. Fable 5 is better for: long context (1M vs. GPT-5's context), Anthropic's safety approach. GPT-5 may be better for: specific benchmarks, OpenAI tool ecosystem.
Gemini 3 Pro (Google, comparable intelligence): Choose Gemini 3 Pro if you need Google Cloud integration or multimodal capabilities. Fable 5 is better for: writing quality, agent trajectories. Gemini 3 Pro may be better for: multimodal tasks, Google Workspace integration.
Verdict and Next Steps
Who should adopt: Advanced users who need the highest available model intelligence for long-horizon tasks. Graduate researchers, senior software engineers, and creative writers working on extended projects. Organizations that can justify the cost per token for high-value work.
When to adopt: When your current model (Opus 5 or Sonnet 5) produces outputs that degrade on long sessions or complex multi-step tasks. When context length is a bottleneck. When the cost of model errors exceeds the cost of the tokens.
For what: Research synthesis across many documents. Extended coding sessions with autonomous debugging. Long-form creative writing. Complex agent workflows requiring sustained reasoning.
UP-Context prompt pack:
Prompt 1 (Research synthesis): "I have loaded [N] documents about [topic]. Synthesize: (1) the three most significant findings, (2) areas of disagreement, (3) methodological gaps. Cite specific documents. Do not speculate beyond sources."
Prompt 2 (Code review): "I have loaded my codebase. Review for: (1) security vulnerabilities, (2) performance bottlenecks, (3) code style violations. For each issue, provide the file, line, and a fix. Prioritize by severity."
Prompt 3 (Long-form writing): "I have loaded my novel outline and character notes. Write chapter [N] maintaining: (1) consistent character voices, (2) the established plot thread, (3) the thematic tone. Match the writing style of my previous chapters."
Related U365 content: See the Claude Opus 5 and Claude Sonnet 5 INSIDE Tools reviews for cost-effective alternatives. See the U365 AI literacy micro-course for foundational prompt engineering skills.
U365's Recommendations to Learn More
This curated selection helps you go beyond this review. Every link was verified active as of 2026-09-03. We prioritize substance over volume: each resource teaches something this post does not.
Official learning resources
Anthropic Claude Fable 5 page: https://www.anthropic.com/claude/fable
Claude Fable 5 and Mythos 5 announcement: https://www.anthropic.com/news/claude-fable-5-mythos-5
Claude models documentation: https://docs.anthropic.com/en/docs/about-claude/models
Prompting guide for Claude Fable 5: https://platform.claude.com/docs/en/build-with-claude/prompt-engineering/prompting-claude-fable-5
Working with Claude Fable 5 in Claude Cowork: https://claude.com/blog/working-with-claude-fable-5-in-claude-cowork
Video tutorials and channels
Introducing Claude Fable 5 (official, Anthropic channel): https://www.youtube.com/watch?v=Y9Wz2PV404E
Claude Fable 5 Tutorial: The New AI King Is Finally Here! (community walkthrough by The AI Advantage): https://www.youtube.com/watch?v=g5gTUyMUmAs
Claude Fable 5 Loop Engineering Tutorial (community walkthrough by The Cutting Edge School): https://www.youtube.com/watch?v=piPGl4pSzd0
Why Everyone Is Freaking Out About Fable 5 (community breakdown by Matt Wolfe): https://www.youtube.com/watch?v=2lE1-5hBfKk
Written tutorials and deep-dive articles
How Powerful is Claude Fable (Mythos) 5 for Coding? (Towards Data Science): https://towardsdatascience.com/how-powerful-is-claude-fable-mythos-5-for-coding
Claude Fable is relentlessly proactive (Simon Willison): https://simonw.substack.com/p/claude-fable-is-relentlessly-proactive
AINews: Anthropic Claude Fable 5 - Mythos but Safe (Latent Space): https://www.latent.space/p/ainews-anthropic-claude-fable-5-mythos
Building on the Claude Platform: Claude Fable 5 and model orchestration (Anthropic webinar): https://www.anthropic.com/webinars/building-on-the-claude-platform-claude-fable-5-and-model-orchestration-patterns
Community and social
Artificial Analysis model page (benchmarks, pricing, speed): https://artificialanalysis.ai/models/claude-fable-5
Claude AI community on Reddit: https://www.reddit.com/r/ClaudeAI/
Claude Code community on Reddit: https://www.reddit.com/r/ClaudeCode/
We welcome individual creators and community experts. These resources were selected for content quality, not source type. Exclude only promotional or affiliate content.
Glossary
CI-First Benefit Score
A composite metric (0-10) that evaluates whether an AI tool genuinely builds human capability rather than creating dependency. It averages four dimensions: Time saved (net of verification overhead), Quantity of usable output, Quality improvement (verified, not surface polish), and Skill built (lasting capability, not outsourcing). For Claude Fable 5, the score is 5.2/10 (CI-First Positive), driven by strong Quantity (7) and Quality (6) but limited Skill (3) because the model does the reasoning for you.
CI-First Profile
A classification of how an AI tool collaborates with humans, drawn from five AI profiles: Co-Creator and Thought Partner (level 1), Co-Worker and Assistant (level 2), Coach and Tutor (level 3), Analyst and Tester (level 4), and Challenger and Devil's Advocate (level 5). Lower level numbers indicate higher AI autonomy in the collaboration. Claude Fable 5 is primarily a Co-Creator and Thought Partner (level 1) with a secondary Coach and Tutor (level 3) profile, excelling as a reasoning partner for complex tasks but too expensive for routine tutoring.
Humics Protection Badge
A rating (-3 to +3) assessing whether a tool protects or erodes distinctly human capabilities: Creativity, Critical Thinking, and Social Authenticity. Each dimension scores +1 (Protects), 0 (Neutral), or -1 (Erodes). Claude Fable 5 scores -1 (Humics-Neutral) with Critical Thinking at -1 (Erodes) because the adaptive thinking mode can substitute for independent reasoning if users delegate analysis entirely.
AI Imposture Risk
An assessment of whether a tool creates false impressions of capability in three dimensions: Time Illusion (fast generation masking slow verification), Quantity Illusion (surface volume vs. usable output), and Skill Illusion (mistaking model reasoning for personal understanding). Claude Fable 5 carries Medium overall risk: Time Illusion is Medium (128K tokens of output takes real time to verify), Quantity Illusion is Low (output is genuine), and Skill Illusion is Medium (extended reliance may weaken analytical skills).
User Sentiment
Aggregated community opinion from review platforms (Trustpilot, G2, Capterra, Product Hunt, Reddit, Artificial Analysis). For Claude Fable 5, sentiment is positive but cost-conscious: users praise the 1M context window and sustained reasoning quality, while concerns focus on the $10/$50 per MTok pricing and slower generation speed (71 tokens/second vs. median 75). No reviews found on most platforms because the model is too new for aggregated ratings.
Sources
Anthropic Claude Fable 5 official page: https://www.anthropic.com/claude/fable
Claude Fable 5 and Mythos 5 announcement: https://www.anthropic.com/news/claude-fable-5-mythos-5
Claude models documentation: https://docs.anthropic.com/en/docs/about-claude/models
Artificial Analysis model page: https://artificialanalysis.ai/models/claude-fable-5
Introducing Claude Fable 5 (YouTube, Anthropic): https://www.youtube.com/watch?v=Y9Wz2PV404E
Claude Fable 5 Tutorial (YouTube, The AI Advantage): https://www.youtube.com/watch?v=g5gTUyMUmAs
Claude Fable 5 Loop Engineering Tutorial (YouTube): https://www.youtube.com/watch?v=piPGl4pSzd0
Claude AI community (Reddit): https://www.reddit.com/r/ClaudeAI/
Claude Code community (Reddit): https://www.reddit.com/r/ClaudeCode/




Comments