
DeepSeek V4 Pro: Open-Weights Reasoning Giant at 1.6T Parameters

Updated: 6 days ago
Status: Active | Last tested: 2026-08-24 (DeepSeek-V4-Pro-0813) | Re-check: trigger-based (max 6 months)

Tool Snapshot
Tagline: DeepSeek's most capable reasoning model, built for complex problem-solving, coding, and long-context analysis with 1.6 trillion parameters and a 1-million-token context window.
Category: Large Language Model
Primary use cases:
Complex reasoning and multi-step problem solving with extended chain-of-thought
Code generation and software engineering with tool-calling support
Long-context document processing up to 1 million tokens
Self-hosted deployment via open weights for data-sensitive environments
Agent workflows with function calling and multi-step planning
Pricing summary: Paid API ($1.32 per 1M input tokens cache miss, $3.96 per 1M output tokens) + Free chat + Open weights (MIT license). Cache hit: $0.003625 per 1M input tokens.
Official links:
Website: https://www.deepseek.com
API Platform: https://platform.deepseek.com
API Documentation: https://api-docs.deepseek.com
Hugging Face Model Card: https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro
Artificial Analysis: https://artificialanalysis.ai/models/deepseek-v4-pro
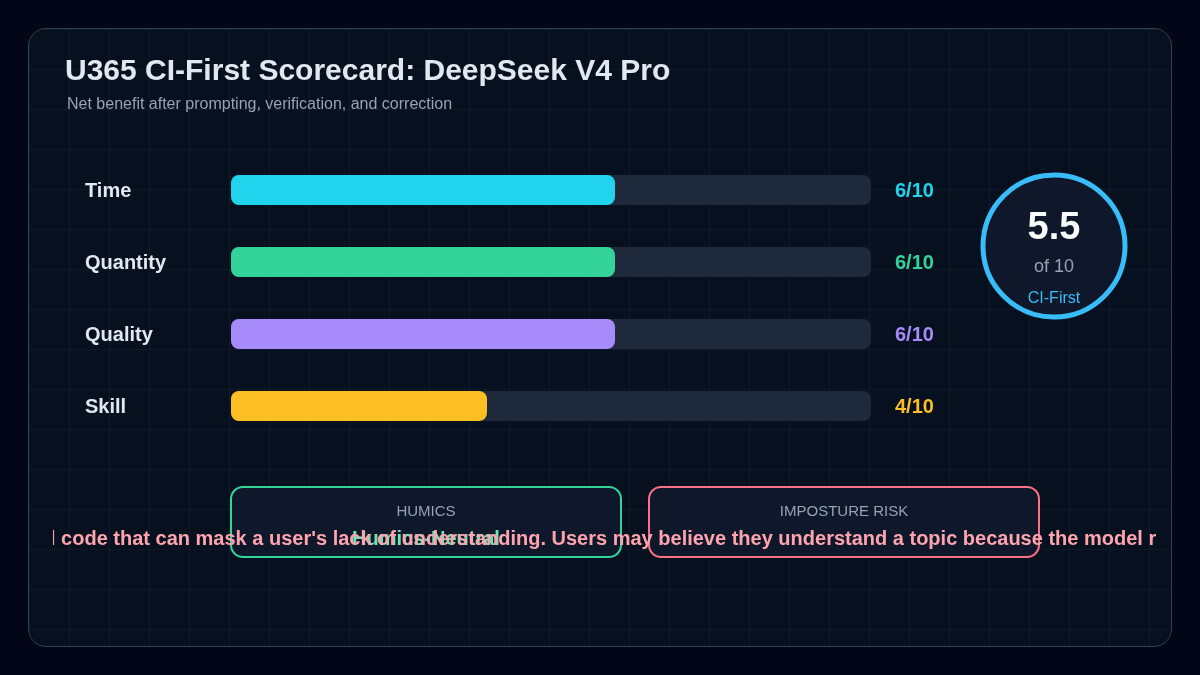
CI-First Benefit Score | 5.5 / 10 (Positive) |
Time / Quantity / Quality / Skill | 6 / 6 / 6 / 4 |
CI-First Profile | Co-Worker and Assistant |
Humics Protection | Humics-Neutral (-1) |
AI Imposture Risk | Medium |
User Sentiment | Positive developer adoption (10M HF downloads, 354.7K Ollama pulls) |
Pricing | Paid API + Free chat + Open weights (MIT) |
Platforms | API, Hugging Face, Ollama, 8 providers |
Context Window | 1M tokens |
For detailed explanations of the CI-First evaluation terms used in this review — including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary section at the end of this post.
LLM specifications
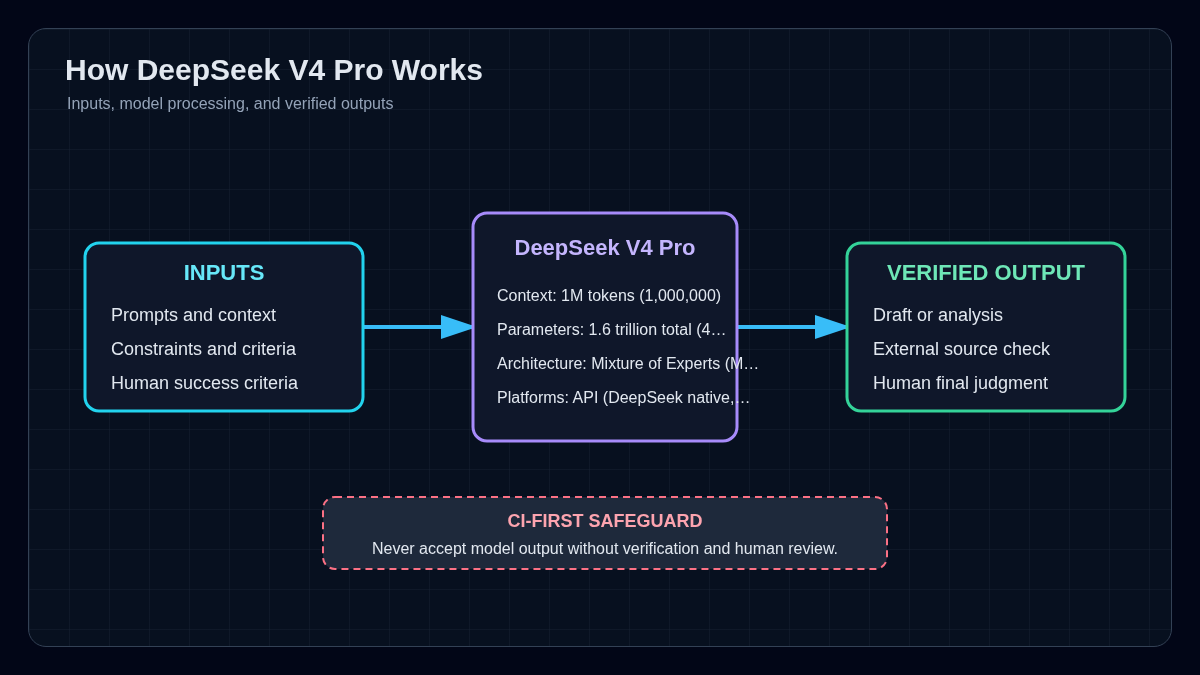
Context Window: 1M tokens (1,000,000)
Effort Levels: Reasoning model with max effort (chain-of-thought). Supports thinking and non-thinking modes. Max effort for hardest tasks, high for balanced reasoning.
Parameters: 1.6 trillion total (49 billion active per token during inference)
Architecture: Mixture of Experts (MoE). 1.6T total parameters with 49B activated. Hybrid CSA+HCA sparse attention. Manifold-constrained hyperconnections (MHC). μON optimizer.
Available Platforms: API (DeepSeek native, 8 providers including Together, Fireworks, Groq, NVIDIA NIM), Hugging Face, Ollama, self-hosted
Model Variants: DeepSeek-V4-Pro-0813 (current flagship, reasoning). DeepSeek-V4-Pro-Base (preview). DeepSeek-V4-Flash (284B total / 13B active, smaller sibling).
Benchmark Scores: Artificial Analysis Intelligence Index: 53 (ranked #3 of 107). MMLU: 90.1. MMLU-Pro: 73.5. SWE-bench Verified: 80.6%. Codeforces: 3006. GDPval-AA: 1554 (leading open-weights model).
Speed: 71.7 tokens per second (above average for open-weight large models)
Latency: Time to first token: 1.81s. Reasoning time: 27.88s. End-to-end response varies with effort level.
Modality: Text input only, text output only. Not multimodal. Vision input available via separate DeepSeek-VL model.
License: MIT (open weights, commercial use allowed)
Openness Index: 50/100 (Artificial Analysis Openness Index)

The Problem
Building production AI systems often forces a choice between three things you want at once: strong reasoning, low cost, and the ability to inspect or self-host the model. Proprietary models like Claude Opus 5 and GPT-5.6 Sol offer top intelligence but at high cost ($15 to $40 per 1M output tokens) with no access to the weights. Open-weight models are cheaper and transparent, but most lag significantly on reasoning quality.
For developers and researchers who need all three, the options are thin. You either pay premium rates for closed models, accept lower quality from open alternatives, or invest in complex multi-model pipelines that combine different models for different tasks.
DeepSeek V4 Pro targets this gap. It is a 1.6-trillion-parameter Mixture of Experts model with 49 billion active parameters per token, released under the MIT license. The weights are publicly available on Hugging Face. You can use it via the DeepSeek API, through 8 third-party providers, or self-host it on your own hardware.
The Outcome
You get a reasoning model that scores 53 on the Artificial Analysis Intelligence Index, ranked #3 of 107 open-weight large models tested. For comparison, Claude Opus 5 scores 63 at $15 per 1M output, and GLM-5.3 scores 60 at $4.40 per 1M output. DeepSeek V4 Pro costs $3.96 per 1M output tokens at peak rates, or $1.98 off-peak.
The 1-million-token context window lets you process entire codebases, long research papers, or extended conversation histories in a single request. The model supports both thinking and non-thinking modes, so you can toggle reasoning on for complex problems and off for simple tasks to save time and cost.
You also get the MIT license. This means you can inspect the model, fine-tune it, deploy it on your own infrastructure, and use it commercially without licensing fees. The model is available on Ollama (354.7K pulls), Hugging Face (10 million downloads), and 8 API providers.
Who Should Use DeepSeek V4 Pro
Learner categories:
Learner type | Difficulty | Typical ROI | Career path |
Students (Bachelor, Master) | Intermediate | Complex reasoning assistance, code generation for coursework | programs in AI, Data Science, Software Development |
Professionals (career upskilling) | Intermediate | Cost-effective API for production applications, self-hosted infrastructure | programs in Business Management, Digital Entrepreneurship |
Everyone (lifelong learners) | Beginner to Intermediate | Free access to frontier-grade reasoning via deepseek.com chat |
U365 Institutes Alignment
UIT (Technology, AI, Data Science): High. Direct relevance for code generation, MoE architecture study, LLM API integration, and self-hosting courses.
UIB (Business Management, Entrepreneurship): Medium. Useful for building cost-effective AI products and self-hosted infrastructure.
UIC (Digital Communication, Marketing): Medium. Long-context content analysis and research assistance.
UID (Digital Design, UX/UI): Low to Medium. Text-only model, but useful for design research and documentation tasks.
Skill level required: Intermediate. You need basic API knowledge or experience using a chat interface. For self-hosting, advanced infrastructure knowledge is required.
Prerequisites: Familiarity with LLM concepts. For API use, basic programming knowledge. For self-hosting, GPU infrastructure and deployment experience.
Typical time to first result: 5 minutes via the deepseek.com chat interface. 15 minutes for API integration. Several days for self-hosting setup.
Typical time to competence: 2 to 4 weeks for effective prompt design, reasoning mode selection, and output verification.
How DeepSeek V4 Pro Works
Inputs: Text prompts, conversation history, code snippets, documents (up to 1 million tokens total context). The model accepts text only. It does not accept images in the Pro variant.
Outputs: Text responses including reasoning traces, code, analysis, structured data, and tool-call plans. The model outputs text only.
Underlying technology
Model: DeepSeek-V4-Pro-0813, released August 13, 2026 by DeepSeek (Hangzhou, China).
Architecture: Mixture of Experts (MoE). 1.6 trillion total parameters with 49 billion active per token during inference. This means only 49B parameters are used for any given token, making the model more efficient than a dense model of equivalent total size.
Reasoning: Yes. DeepSeek V4 Pro is a reasoning model. It uses extended chain-of-thought reasoning to work through complex problems before providing an answer. The reasoning time averages 27.88 seconds before the first output token.
Thinking modes: Supports both thinking (default) and non-thinking modes. In thinking mode, the model reasons through the problem before answering. In non-thinking mode, it responds directly without extended reasoning. You can toggle this via the API with the thinking parameter.
Context window: 1 million tokens. This includes user input, model output, and reasoning tokens.
License: MIT. The model weights are publicly available on Hugging Face and can be downloaded for self-hosting. Commercial use is allowed.
Integrations: API access via DeepSeek (OpenAI-compatible and Anthropic-compatible formats). Also available through Together AI, Fireworks AI, DeepInfra, Baseten, Novita, and other providers. Ollama cloud deployment available. DeepSeek agent integration tools for developer preview. Compatible with Claude Code, GitHub Copilot, and OpenCode.
Pricing: $1.32 per 1M input tokens (cache miss, peak) and $3.96 per 1M output tokens (peak). Off-peak rates are half: $0.66 input, $1.98 output. Cache hit at $0.044 per 1M tokens (peak), a 97 percent discount. Blended rate approximately $0.69 per 1M tokens.
Speed: 71.7 tokens per second output. Time to first token: 1.81 seconds. Reasoning time: 27.88 seconds.
Benchmarks: Artificial Analysis Intelligence Index score of 53, ranked #3 of 107 open-weight large models. AA-Omniscience Index: 0.83. The Intelligence Index includes GDPval-AA v2, Terminal-Bench v2.1, SciCode, Humanity's Last Exam, GPQA Diamond, AA-Omniscience, and AA-LCR.
Availability: 8 API providers. Open weights on Hugging Face (10 million downloads, 5,477 likes). Cloud deployment via Ollama (354.7K pulls, 3 tags).
See ollama.com/search for local deployment options and artificialanalysis.ai for independent benchmark rankings.
Model variants
DeepSeek-V4-Pro-0813: Current flagship reasoning model (this post).
DeepSeek-V4-Pro-0424: Previous version (Intelligence Index 45.3, max effort).
DeepSeek-V4-Flash-0731: Efficient variant (284B total, 13B active, Intelligence Index 51.8, 125 t/s output).
DeepSeek-V4-Flash-Vision-Exp: Experimental model with image input support.
DeepSeek-R1: Previous reasoning family (671B parameters, 37B active).
Getting Started with DeepSeek V4 Pro
Required accounts: A free DeepSeek account for the chat interface at deepseek.com. A paid API account at platform.deepseek.com for programmatic access.
Installation: Web-based chat at deepseek.com. For API use, no installation required. Use HTTP requests or the OpenAI-compatible SDK. For self-hosting, download weights from Hugging Face and deploy with vLLM, SGLang, or similar frameworks.
First-time configuration
1. Create an account at deepseek.com for the free chat interface.
2. For API use, register at platform.deepseek.com and generate an API key.
3. Install the OpenAI SDK: pip install openai.
4. Set your API key as an environment variable.
5. Configure the base URL: https://api.deepseek.com (OpenAI format) or https://api.deepseek.com/anthropic (Anthropic format).
6. For Ollama cloud: ollama run deepseek-v4-pro.
First 15 minutes checklist
Create a DeepSeek account and open the chat at deepseek.com.
Ask DeepSeek V4 Pro a complex reasoning question (for example, a math or logic problem) to test its thinking mode.
Submit a coding task (for example, write a Python function with error handling) and review the output.
Paste a long document (at least 50 pages of text) and ask for a structured summary to test the context window.
If using the API, make your first API call with the OpenAI SDK and verify the response.
Result: You will have tested DeepSeek V4 Pro's core capabilities (reasoning, code generation, long context) and confirmed API or chat access.
Real Workflows
Workflow 1: Complex Code Analysis and Refactoring
Learner type: Professional
CI-First benefit tags: Time, Quality
Connects to: UIT Software Development and Digital Transformation programs. UIB Digital Entrepreneurship programs.
Time estimate: 30 to 45 minutes including verification.
Step 1: You identify a codebase section that needs refactoring. Gather the relevant code files and documentation.
Step 2: You paste the code into the DeepSeek chat interface or send it via the API (up to 1M tokens of context).
Step 3: DeepSeek V4 Pro analyzes the code, identifies issues (bugs, security risks, performance bottlenecks, maintainability problems), and produces a structured report with specific recommendations.
Step 4: You review the analysis, evaluate each recommendation, and ask follow-up questions about any suggestions you disagree with or do not understand.
Step 5: You implement the approved changes yourself, using the model's recommendations as guidance but writing or modifying the code with your own understanding.
Sample prompt:
You are a senior software engineer reviewing a codebase for refactoring. Context: I am providing you with a Python module (approximately 2000 lines) that handles user authentication and session management. The code was written 3 years ago and has known performance issues. Task: Analyze the code for bugs, security vulnerabilities, performance bottlenecks, and maintainability issues. For each issue, provide: (1) a severity rating (critical, high, medium, low), (2) a description of the problem, (3) a specific code fix. Constraints: Prioritize security issues first. Do not suggest changes to the overall architecture, only to the code provided. Flag any issue you are not confident about. Output format: Numbered list of issues with severity, description, and fix.
Verification checklist:
Multi-Model Check: Run the same code through Claude Sonnet 5 or GPT-5.6 and compare the identified issues. Focus on discrepancies where one model finds a security issue the other misses.
External Source: Verify any security vulnerability claims against OWASP guidelines or CVE databases. Run the suggested fixes through a linter or test suite.
Human Review: A senior developer reviews the analysis and your implemented changes before merging.
CI-First Test: Can you explain and defend each code change you made without referring to the model's analysis? [Y/N]
Workflow 2: Self-Hosted AI Assistant for Data-Sensitive Research
Learner type: Student
CI-First benefit tags: Time, Quantity, Quality
Connects to: UIT AI and Data Science programs. URC research methodology courses.
Time estimate: 2 to 4 hours for initial setup, then ongoing use.
Step 1: You assess your hardware. Self-hosting DeepSeek V4 Pro (1.6T parameters) requires significant GPU resources. Alternatively, use Ollama cloud deployment or a third-party provider like Together AI or DeepInfra.
Step 2: You set up the deployment using Ollama (ollama run deepseek-v4-pro) or via a provider API with your API key.
Step 3: You configure the model for your research use case: enable thinking mode for complex analysis, set the context window to accommodate your document sizes.
Step 4: You feed research papers, datasets, or documents into the model and ask for structured analysis, summaries, or comparisons.
Step 5: You verify all factual claims against original sources and write your own analysis using the model's output as a research aid, not a final product.
Sample prompt:
You are a research assistant helping me analyze academic papers. Context: I am providing 3 research papers about transformer architecture efficiency improvements. I am writing a literature review for my Master's thesis in AI. Task: Read all 3 papers and produce a structured comparison. For each paper, identify: (1) the core method proposed, (2) the efficiency improvement claimed, (3) the evaluation methodology, (4) limitations acknowledged by the authors, (5) relevance to my thesis on MoE efficiency. Constraints: Do not invent findings not present in the papers. If a paper does not address a category, state that explicitly. Flag any claim you are not confident about. Output format: Markdown table followed by a 300-word synthesis paragraph.
Verification checklist:
Multi-Model Check: Run the same prompt through GLM-5.3 or Gemini 3.7 Flash and compare the comparison tables for discrepancies in findings or methodology descriptions.
External Source: Verify at least 2 key findings from the summary by reading the relevant sections of the original papers yourself.
Human Review: Your thesis advisor reviews the summary for accuracy and completeness before you use it in your literature review.
CI-First Test: Can you explain and defend each finding in the summary without referring to the model's output? [Y/N]
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | Saves time on complex reasoning tasks. 71.7 t/s output and 1.81s TTFT. | Artificial Analysis: faster than the median for open-weight large models. |
Quantity | Moderate output volume. 130M tokens on benchmark evaluation, 1.3x median. | Artificial Analysis verbosity ranking. Useful for comprehensive output. |
Quality | Intelligence Index 53, ranked #3 of 107 open-weight large models. | Scores 53 vs GLM-5.3 at 60 (proprietary, $4.40/1M output), GPT-5.6 Luna at 52.3. |
Skill | Marginal. The model produces expert output but does not actively teach. | No built-in tutoring mode. Output is answers and reasoning, not scaffolding. |
Limits
Text only. The Pro variant does not accept or produce images. For multimodal tasks, use the experimental DeepSeek-V4-Flash-Vision-Exp model.
Long reasoning time. The model averages 27.88 seconds of reasoning before the first output token. This is slower than non-reasoning models and adds latency to simple tasks.
Verbose output. 130M tokens on benchmark evaluation is 30 percent above the 100M median. This means higher output costs and more reading time for users.
High self-hosting requirements. 1.6 trillion parameters require significant GPU infrastructure. Most users will use the API or cloud deployment rather than self-hosting.
Low Omniscience score. The AA-Omniscience Index is 0.83, which is low compared to Claude Opus 5 (37.1) or Grok 4.6 (30.5). This means the model has higher hallucination rates than top proprietary models.
Openness Index of 50/100. While the weights are MIT-licensed, not all training data and methods are fully disclosed.
High Skill Illusion risk. The model's strong reasoning can mask a user's lack of understanding, especially in coding and research tasks.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The model's reasoning time (27.88s before first token) and verbose output (130M tokens, 1.3x median) can make users feel thorough work was done when the reasoning may contain errors. |
Quantity Illusion | Medium | The model generates detailed reasoning traces that look thorough but may include unsupported claims masked by confident language. |
Skill Illusion | High | DeepSeek V4 Pro produces expert-level reasoning and code that can make users believe they understand the subject when they are merely accepting the model's output without critical evaluation. |
Overall Imposture Risk: Medium
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (2). The model's main value is executing complex text and reasoning tasks at high quality and competitive cost.
Secondary profiles: Co-Creator and Thought Partner (1) for brainstorming and ideation. Analyst and Tester (4) for code review and data analysis.
Collaboration Mode
Recommended mode: Centaur. Clear division of labor: the user defines tasks, reviews output, and makes final decisions. DeepSeek V4 Pro handles generation, reasoning, and drafting.
Alternative mode: Cyborg for rapid iterative prototyping where the user has domain expertise to evaluate output quickly.
Mode rationale: The model's 27.88s reasoning time, verbosity (130M tokens, 1.3x median), and high Skill Illusion risk make Centaur mode safer. The user must actively review and verify output rather than accepting it in a rapid iteration loop.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 6 | Above-average speed (71.7 t/s, 1.81s TTFT) but 27.88s reasoning time offsets gains for simple tasks. |
Quantity | 6 | 130M tokens on benchmark evaluation (1.3x median). Moderate volume increase, not transformative. |
Quality | 6 | Intelligence Index 53, ranked #3 of 107 open-weight large models. Strong for open weights, below proprietary top tier. |
Skill | 4 | The model produces expert output but does not teach. High Skill Illusion risk reduces lasting capability building. |
CI-First Benefit Score: (6+6+6+4)/4 = 5.5 / 10 (CI-First Positive)
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | The model can support ideation but does not actively strengthen creative capacity. |
Critical Thinking | Erodes (-1) | The model produces confident, well-reasoned answers that can reduce independent critical evaluation. |
Social Authenticity | Neutral (0) | The model is not primarily used for communication, so it does not significantly affect social authenticity. |
Humics Protection Score: 0 + (-1) + 0 = -1
Badge: Humics-Neutral (erodes 1 dimension, neutral on 2; no severe erosion)
Superhuman Usage Guidance
When to invite this tool:
Complex reasoning tasks where the 1M context window and extended thinking add value
Code analysis and refactoring where you can verify the output against tests
Long-document processing and research analysis where source verification is possible
Self-hosted deployments where data sensitivity requires on-premise processing
Cost-sensitive production workloads where open weights eliminate licensing fees
When to keep this tool out:
Tasks requiring factual accuracy without verification (low Omniscience score)
Tasks where the 27.88s reasoning time creates unacceptable latency
Communication requiring your authentic voice
Creative decisions where the model's reasoning replaces your own judgment
Production systems where you cannot verify or test the model's output
U365 method integration:
LIPS + CARE: Use DeepSeek V4 Pro in the Collect phase to process large documents and extract key information. In the Action Plan phase, use it to draft plans. In the Review phase, use it to check plans against sources. Do not let it replace the Execute step.
ULM + EVA: The model supports the Career domain through code generation and professional analysis. In the Explore phase, use it to research topics quickly. In the Visualize phase, use it to draft structured plans.
UP-Context: The model responds well to UP-Context prompting. Always provide context, role, task, constraints, and output format. The reasoning capability benefits from explicit constraints to control verbosity.
SL-OS: DeepSeek V4 Pro does not integrate directly with Microsoft 365. Use it alongside Microsoft 365 Copilot: Copilot for in-app assistance, DeepSeek V4 Pro for long-context tasks and self-hosted scenarios Copilot cannot handle. Export content from OneNote or SharePoint, process it, and bring results back.
UNOP: The model's reasoning mode can support spaced repetition generation and multi-modal explanation, but verify all factual content given the low Omniscience score.
Over-delegation warning: The most common over-delegation pattern is accepting DeepSeek V4 Pro's reasoning output as correct without verification. The model's low Omniscience score (0.83, far below Claude Opus 5 at 37.1) means factual claims are more likely to be wrong than with top proprietary models. The open-weights availability makes this worse: developers integrate the model into production systems without understanding its hallucination rate. If you stop verifying output, your HI drops, and CI-First drops with it. The Superhuman who stops questioning AI becomes Sub-human.
What Users Say
Aggregate Rating Table
Platform | Rating | Number of reviews | Link |
Hugging Face | 5,477 likes, 10M downloads | N/A | https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro |
Ollama | 354.7K pulls, 3 tags | N/A | https://ollama.com/library/deepseek-v4-pro |
Reddit sentiment | Unable to access via API. Sentiment not collected. | N/A | N/A |
G2 | No reviews found | 0 | N/A |
Trustpilot | No reviews found | 0 | N/A |
Product Hunt | No reviews found | 0 | N/A |
Futurepedia | No reviews found | 0 | N/A |
DeepSeek V4 Pro is an API and open-weights product, not a consumer SaaS application. Consumer review platforms (G2, Trustpilot, Capterra) do not typically accumulate reviews for model APIs. Developer sentiment appears on Hugging Face (5,477 likes, 10 million downloads) and Ollama (354.7K pulls), which indicate strong developer adoption.
What Users Praise
Based on Hugging Face download numbers (10 million) and Ollama pull counts (354.7K), the developer community has adopted DeepSeek V4 Pro rapidly. The model's main strengths based on benchmark data are its open MIT license (allowing commercial use and self-hosting), competitive intelligence-to-price ratio (Intelligence Index 53 at $3.96/1M output, vs proprietary models at $15 to $40), and the 1M token context window. The availability through 8 API providers gives developers deployment flexibility.
What Users Complain About
No user complaints are available from review platforms. Based on benchmark data, potential concerns include the low AA-Omniscience Index score (0.83, compared to Claude Opus 5 at 37.1), which indicates higher hallucination rates than top proprietary models. The text-only modality (no image support in the Pro variant) limits multimodal use cases. The long reasoning time (27.88s average) may create latency issues in interactive applications. Self-hosting 1.6 trillion parameters requires significant GPU infrastructure that most users do not have.
Sentiment Summary
Overall sentiment: Positive developer adoption. No consumer sentiment data available.
Key themes: Open MIT license, cost-effectiveness, 1M context window, strong reasoning for open-weight models, higher hallucination rate than top proprietary models, text-only limitation.
U365 Editorial Note
The developer adoption metrics (10M Hugging Face downloads, 354.7K Ollama pulls) are consistent with the CI-First Benefit Score of 5.5 (CI-First Positive). Developers value the open weights, MIT license, and cost-effectiveness, which align with the Time and Quantity benefit dimensions. However, the low Omniscience score (0.83) is a significant concern that the CI-First evaluation flagged through the High Skill Illusion risk rating. Users who adopt this model for production systems without understanding its hallucination rate may experience the Skill Illusion trap: the model's confident reasoning masks factual errors that only surface during verification. The U365 recommendation is to use DeepSeek V4 Pro in Centaur mode with mandatory verification, especially for factual claims. The open-weights advantage is real, but it does not compensate for the verification burden.
Comparison and Alternatives
Comparison and Alternatives
Alternative | When to Choose |
Anthropic Claude | You want the Meta platform and broader community support. |
Z.ai | You need stronger reasoning (Intelligence Index 53 vs Llama alternatives). |
OpenAI Platform | You need multimodal input, higher factual reliability, and ecosystem integration. |
DeepSeek | You want open MIT weights, 1M context, and cost-effective reasoning. |
Meta AI | You need fully open weights with broad community support and ecosystem tools. |
Where DeepSeek V4 Pro is clearly better
DeepSeek V4 Pro is the strongest open-weight reasoning model available. At Intelligence Index 53, it ranks #3 of 107 open-weight large models, ahead of DeepSeek V4 Flash (51.8), GLM-5.2 (52.6), and GPT-5.6 Luna (52.3). The MIT license is more permissive than most alternatives, allowing unrestricted commercial use. The 1M context window matches the best available. The availability through 8 API providers and Ollama cloud gives deployment flexibility that proprietary models cannot match. For developers who need open weights, strong reasoning, and a large context window, DeepSeek V4 Pro is the top choice.
Where DeepSeek V4 Pro is clearly worse
The model's factual reliability is significantly lower than top proprietary models. The AA-Omniscience Index of 0.83 is far below Claude Opus 5 (37.1), Grok 4.6 (30.5), and GLM-5.3 (14.3). This means the model produces more hallucinations and factual errors than these alternatives. The text-only modality limits use cases requiring image input. The 27.88s reasoning time creates latency for interactive applications. For tasks where factual accuracy is critical and verification is difficult, proprietary models with higher Omniscience scores are safer choices.
Verdict and Next Steps
Verdict:
Who should adopt it: Developers, researchers, and students who need strong reasoning with open weights. UIT learners building AI applications with self-hosting requirements. Professionals who need cost-effective API access to frontier-grade reasoning. Anyone who values the MIT license for commercial use without licensing fees.
When: Now, if your use case benefits from open weights, long context, and competitive reasoning quality. If you need the highest factual reliability, use Claude Opus 5 or GLM-5.3 instead and verify with DeepSeek V4 Pro as a second model.
For what: Complex reasoning, code analysis, long-context document processing, self-hosted AI deployment, and agent workflows with tool calling.
UP-Context prompt pack:
1. Code analysis: You are a senior software engineer. Context: I am reviewing a [language] codebase for [purpose]. The code is [lines] lines long. Task: Analyze the code for bugs, security issues, and improvement opportunities. Constraints: Prioritize issues by severity. Provide specific code fixes. Flag uncertain findings. Output format: Numbered list of issues with severity, description, and fix.
2. Research synthesis: You are a research assistant. Context: I am analyzing [N] research papers about [topic] for my [thesis/report]. Task: Read all papers and produce a structured comparison. Constraints: Do not invent findings. Flag uncertain claims. Output format: Markdown table with columns for paper, methodology, findings, limitations.
3. Agent workflow design: You are an AI agent architect. Context: I am building an automated workflow that uses tool calling to [task]. Task: Design the agent workflow with tool definitions, step-by-step execution, and error handling. Constraints: Include verification steps. Define maximum 5 tools. Output format: Workflow description with tool definitions and execution sequence.
Related U365 content:
[Insert relevant UIT AI and Data Science course link after confirming with academic team]
[Insert relevant URC research methodology course link after confirming with academic team]
U365's Recommendations to Learn More
This curated list helps you go deeper with DeepSeek V4 Pro. Every link below was verified active as of 2026-09-03. We include official documentation, community walkthroughs, video tutorials, and discussion threads — judged by content quality, not source type.
Official learning resources
DeepSeek API Documentation — https://api-docs.deepseek.com
DeepSeek V4 Pro on Hugging Face — https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro
DeepSeek-V4 Technical Report on arXiv — https://arxiv.org/abs/2606.19348
DeepSeek V4 Pro GA Release Notes — https://api-docs.deepseek.com/news/news260813
Video tutorials and channels
DeepSeek-V4-Pro-0813 Model Technical Overview and Implementation Guide (community walkthrough by Vinh Nguyen) — https://www.youtube.com/watch?v=7ToQdMuWzsE
DeepSeek-V4 Explained: How Million-Token Context LLMs Become Practical (by YanAITalk) — https://www.youtube.com/watch?v=DvG4E-nYHvI
Claude Code for FREE Using DeepSeek V4 Pro + NVIDIA API (community walkthrough by Code With Yousaf) — https://www.youtube.com/watch?v=ZVZ2lj9cY3g
Written tutorials and deep-dive articles
DeepSeek V4 Pro 101: The 1.6T-Parameter Open Model (Kie.ai) — https://kie.ai/blog/deepseek-v4-pro-release
DeepSeek V4 Pro on Artificial Analysis (independent benchmarks) — https://artificialanalysis.ai/models/deepseek-v4-pro
DeepSeek V4 Pro on OpenRouter (API pricing and providers) — https://openrouter.ai/deepseek/deepseek-v4-pro
Community and social
DeepSeek on GitHub — https://github.com/deepseek-ai
DeepSeek V4 Pro discussion on Reddit r/LocalLLaMA — https://www.reddit.com/r/LocalLLaMA/comments/1svbmnc/decreased_intelligence_density_in_deepseek_v4_pro
We curate these resources for content quality, not source type. Individual creators and community experts are included when their material teaches something the post itself does not cover. Exclude only promotional or affiliate content.
Glossary
CI-First Benefit Score
A 0-10 score measuring whether an AI tool genuinely builds lasting human capability (CI-First) or merely creates the illusion of competence. Sub-scores cover Time saved, Quantity of usable output, Quality of verified output, and Skill built. The average determines the interpretation band: 0-2.0 Negative, 2.1-4.0 Neutral, 4.1-6.0 Positive, 6.1-8.0 Strong, 8.1-10.0 Transformative.
CI-First Profile
One of five AI collaboration profiles: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy — the tool takes more initiative. Higher numbers mean the AI challenges and tests the human's thinking.
Humics Protection Badge
A rating from -3 to +3 measuring whether a tool protects or erodes distinctively human capacities across three dimensions: Creativity, Critical Thinking, and Social Authenticity. Each dimension scores +1 (protects), 0 (neutral), or -1 (erodes). The sum determines the badge: +2 to +3 Humics-Friendly, -1 to +1 Humics-Neutral, -2 to -3 Humics-Risky.
AI Imposture Risk
An assessment of how readily a tool can create the illusion of competence without genuine understanding. Three traps are evaluated: Time Illusion (does it feel faster than it is?), Quantity Illusion (does it produce more usable output than it does?), and Skill Illusion (does it build real skill or create dependency?). Overall: Low (all Low), Medium (1-2 Medium or 1 High with mitigations), High (2+ High).
User Sentiment
An aggregate assessment of real user feedback from review platforms (G2, Trustpilot, Capterra, Product Hunt, Futurepedia, Reddit, App Store, Google Play, GitHub). Ratings and review themes are collected without fabrication. When no reviews exist on a platform, the platform is recorded as "No reviews found." The sentiment summary connects community feedback to the CI-First evaluation.




Comments