
Gemini 3.5 Flash-Lite: Google's Ultra-Efficient Edge Model for High-Volume Workloads

Updated: 6 days ago
Status: Active | Last tested: 2026-09-03 (Gemini 3.5 Flash-Lite, GA July 2026) | Re-check: trigger-based (max 6 months)


Tool Snapshot
Tagline: Google DeepMind's cost-optimized edge model designed for low latency and high volume text and image processing.
Category: Large Language Model (Edge / Efficiency)
Provider: Google DeepMind
Version tested: Gemini 3.5 Flash-Lite (GA, July 21, 2026)
Context window: 1,048,576 tokens (1M)
Max output: 65,536 tokens (64K)
License: Proprietary (Google Gemini API Terms)
Platforms: Google AI Studio, Gemini API, Gemini Enterprise Agent Platform
Primary use cases:
High-volume text classification and categorization
Fast document summarization at scale
Image-based query answering and description generation
Cost-sensitive batch processing of large datasets
Real-time text and image input processing with low latency
Lightweight agentic workflows and subagent execution
Pricing summary: $0.30 per 1M input tokens, $2.50 per 1M output tokens. Google positions Flash-Lite as its lowest-cost Gemini tier. The model is designed for scenarios where cost per request matters more than maximum intelligence.
Official links:
Google AI Studio: https://aistudio.google.com/
Google AI Docs: https://ai.google.dev/gemini-api/docs/models/gemini-3.5-flash-lite
Google Cloud docs: https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-5-flash-lite
Model card: https://deepmind.google/models/model-cards/gemini-3-5-flash-lite/
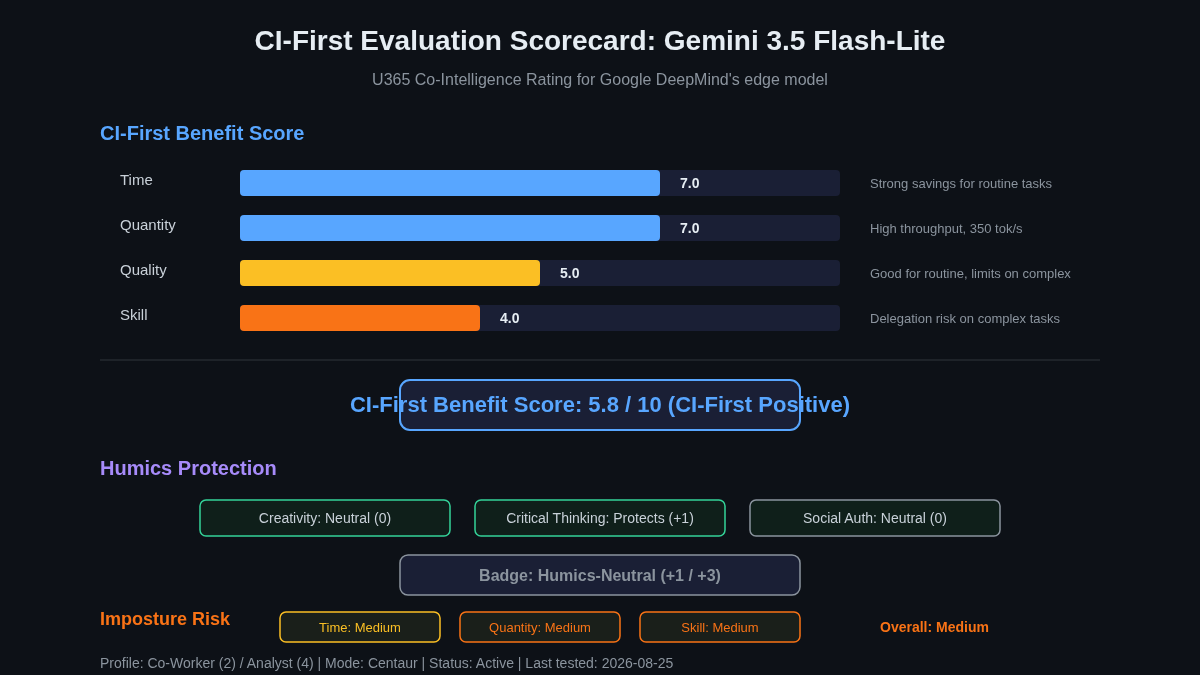
CI-First Benefit Score | 5.5/10 - CI-First Positive |
Time / Quantity / Quality / Skill | 7 / 7 / 5 / 3 |
CI-First Profile | Co-Worker and Assistant (primary), Analyst and Tester (secondary) |
Humics Protection | Humics-Neutral (0) |
AI Imposture Risk | Medium |
User Sentiment | No model-specific reviews (API variant) |
Pricing | $0.30/1M input, $2.50/1M output tokens |
Platforms | Google AI Studio, Gemini API, Gemini Enterprise Agent Platform |
Context Window | 1,048,576 tokens (1M) |
Max Output Tokens | 65,536 tokens (64K) |
Output Speed | 350 output tokens/s (Artificial Analysis) |
Release Date | July 21, 2026 (GA) |
For detailed explanations of the CI-First evaluation terms used in this review - including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
LLM specifications:
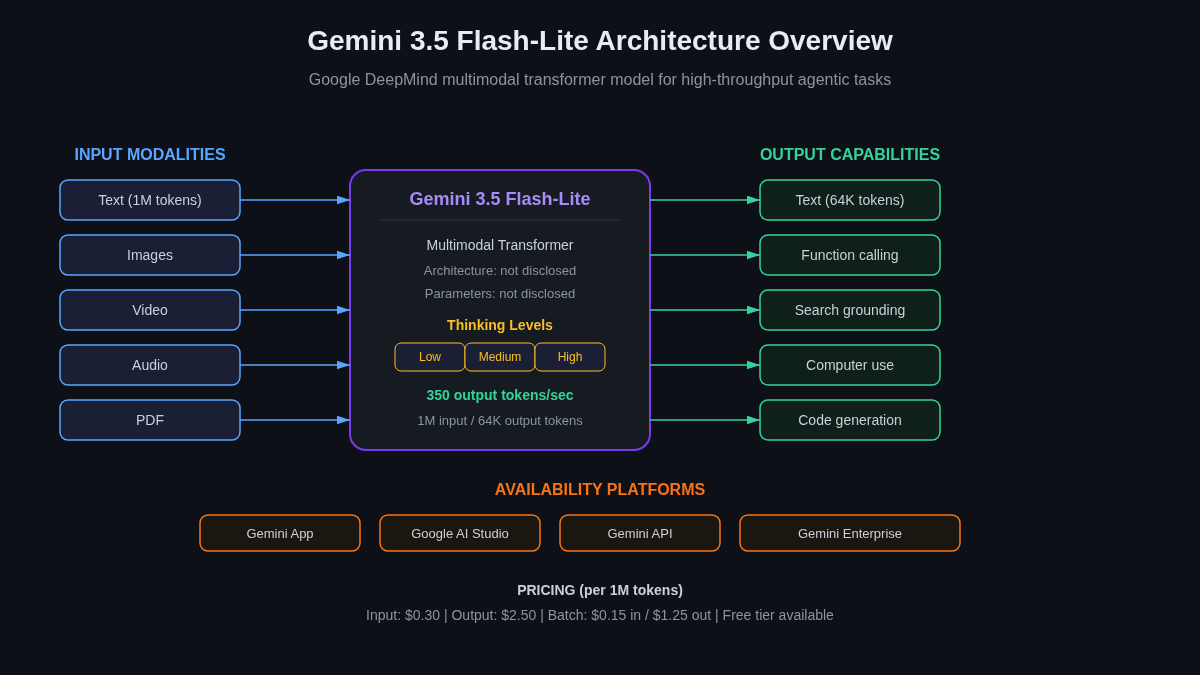
Context Window: 1,048,576 tokens (1M)
Max Output Tokens: 65,536 (64K)
Effort/Thinking Levels: Minimal (default), Low, Medium, High
Parameters: Not publicly disclosed (proprietary)
Architecture: Proprietary Transformer-based, based on Gemini 3.1 Flash-Lite
Input Modalities: Text, Image, Audio, Video, PDF
Output Modalities: Text
Available Platforms: Google AI Studio, Gemini API, Gemini Enterprise Agent Platform, Cloudflare AI
Model Variants: Single variant: gemini-3.5-flash-lite
Speed: 350 output tokens/s (Artificial Analysis)
Benchmarks: Outperforms Gemini 3.1 Flash-Lite across safety and tone
Computer Use: Supported (preview feature)
Function Calling: Supported
Context Caching: Implicit and explicit caching supported
Batch Inference: Supported
Release Date: July 21, 2026 (GA)
Retirement Date: July 21, 2027 or later
API Endpoint: gemini-3.5-flash-lite
The Problem
Many AI workloads do not need the full intelligence of a flagship model. They need fast, cheap, high-volume processing. Classifying thousands of documents, summarizing batches of articles, or answering image-based queries at scale all require throughput, not maximum reasoning depth.
Using a flagship model for these tasks is expensive and slow. The latency per request adds up when you process thousands of items. The cost per token makes high-volume workloads impractical. And the extra intelligence goes unused when the task is simple classification or summarization.
Gemini 3.5 Flash-Lite addresses this gap. It is Google's lowest-cost Gemini variant, optimized for edge deployment, low latency, and high-volume processing. It accepts text, image, audio, and video input and produces text output. The model trades maximum intelligence for speed and cost efficiency, making it suitable for tasks where volume and cost matter more than deep reasoning.
The Outcome
After using Gemini 3.5 Flash-Lite, you can process high-volume text and image workloads at lower cost and lower latency than flagship models. You get fast responses, cost-optimized per-token pricing, and the ability to handle text and image input in a single model.
Specific outcomes include: faster turnaround on batch processing tasks, lower cost per request for high-volume workloads, and image input support for tasks that combine text with visual data. The model is available through Google AI Studio for testing and through the Google API for production use.
The tradeoff is intelligence. Flash-Lite is designed for efficiency, not maximum reasoning. For complex reasoning, long document analysis, or tasks requiring high accuracy, you should use a higher-tier Gemini model. Flash-Lite is the right choice when cost and speed are the primary constraints.
Who Should Use Gemini 3.5 Flash-Lite
Gemini 3.5 Flash-Lite serves three learner categories:
Category | Who | Why |
Students | University students needing low-cost high-volume processing for coursework and research | Document classification, batch summarization, image description at minimal API cost |
Professionals | Developers, data scientists, analysts running high-throughput production workloads | If you classify thousands of documents per day, summarize large batches, or process image datasets at scale, the cost and speed savings justify the quality tradeoff |
Everyone | Anyone needing fast, cheap AI processing for straightforward text or image tasks | If your task does not require deep reasoning and you need volume at low cost, Flash-Lite is the right tier |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Technical documentation processing, batch classification, and cost-optimized API usage in data science and AI courses. |
UIC (Digital Communication, Marketing) | Medium | High-volume content classification, tag generation, and media description at scale for digital content workflows. |
UIB (Business Management, Entrepreneurship) | Low | Cost-optimized document processing for business case analysis and batch classification of business documents. |
UID (Digital Design, UX/UI) | Low | Image description generation for design asset libraries at scale, batch tagging of visual content. |
Skill level: Beginner to intermediate. The model is straightforward to use via Google AI Studio. You should understand when to choose Flash-Lite over a higher-tier model based on your task requirements.
Prerequisites: A Google AI Studio account. Basic familiarity with LLM prompting and API usage.
Time to first result: 2 minutes. Time to competence: 1 to 2 hours of testing different workload types.
How Gemini 3.5 Flash-Lite Works
Gemini 3.5 Flash-Lite is the efficiency-optimized variant of Google's Gemini 3.5 model family. It uses a proprietary Transformer architecture tuned for low latency and cost-optimized processing. The model is based on Gemini 3.1 Flash-Lite and is the fastest model in the 3.5 series.
Inputs
The model accepts text, image, audio, video, and PDF input. You can combine these modalities in a single request, for example asking the model to classify an image or describe its contents alongside a text query. The 1M token context window supports large document sets and long videos.
Processing
The model supports configurable thinking levels: Minimal (default), Low, Medium, and High. Minimal thinking optimizes for speed and cost, ideal for high-throughput classification and extraction. Medium and High thinking levels support multi-step subagent workloads. The model prioritizes speed over deep reasoning at the Minimal level.
Output
The model produces text output up to 65,536 tokens. It does not generate images, audio, or video. Structured output (JSON) is supported, making it suitable for automated pipelines.
Architecture
Proprietary Transformer-based model based on Gemini 3.1 Flash-Lite. Google does not disclose the parameter count or architecture details. The model is not open weight.
Platform Availability
Available via Google AI Studio, Gemini API, Gemini Enterprise Agent Platform, and Cloudflare AI. Not available for local deployment. Not available on Ollama. Google's open-weight Gemma models serve as local alternatives but do not match the Flash-Lite efficiency profile.
Pricing
Priced at $0.30 per 1M input tokens and $2.50 per 1M output tokens. Google positions Flash-Lite as its lowest-cost Gemini variant. The model is designed for scenarios where cost per request and latency are the primary constraints. Flex PayGo offers 50 percent off for flexible latency workloads.
Position in the Gemini Family
Flash-Lite sits below Gemini 3.5 Flash (standard efficiency) and Gemini 3.5 Pro (maximum intelligence) in the model tier. Choose Flash-Lite for cost and speed, Flash for balanced performance, and Pro for maximum intelligence.
Getting Started with Gemini 3.5 Flash-Lite
Step 1: Create a Google AI Studio account at aistudio.google.com. This gives you free access to test the model in a browser interface.
Step 2: For API access, go to ai.google.dev and create or select a Google Cloud project. Enable the Gemini API.
Step 3: Generate an API key from the Google AI Studio settings page. Store the key securely.
Step 4: Select the Flash-Lite model variant. In Google AI Studio, choose the model from the model selector. Via API, use the gemini-3.5-flash-lite endpoint.
Step 5: Test your first prompt. Start with a simple text classification or summarization task to confirm the model responds quickly and meets your cost requirements.
Step 6: Test with image input. Submit an image alongside a text query to verify the multimodal input works for your use case.
Step 7: For production use, benchmark the cost and latency against your current solution. Measure cost per 1,000 requests and average response time to confirm Flash-Lite delivers the savings you expect.
First 15 Minutes Checklist
☐ Create AI Studio account (2 min)
☐ Generate API key (2 min)
☐ Send first text prompt (1 min)
☐ Test image input (3 min)
☐ Run a batch of 10 requests and measure latency (3 min)
☐ Compare cost to your current model (4 min)
Real Workflows
Workflow 1: High-Volume Document Classification
Learner type: Students in UIT, URC programs processing large document sets
CI-First benefit tags: Time, Quantity
Connects to: UIT Bachelor in IT data science courses, URC research data processing
Time estimate: 20 to 40 minutes per batch of 100 documents
You do | Gemini 3.5 Flash-Lite does |
Prepare your document batch and classification schema | Classify each document into the specified categories |
Submit the batch via API or AI Studio | Process all documents and return category labels |
Sample 10 percent of results for verification | Flag low-confidence classifications for manual review |
Review flagged items and correct misclassifications | Re-run corrected items if needed |
Sample prompt:
Classify the following document into one of these categories: Technology, Business, Science, Health, Education, Other. Return only the category name, nothing else. Document: [paste document text]
Verification checklist:
☐ Multi-Model Check: Run 10 percent of the documents through Gemini 3.5 Flash or another model and compare classifications. Flag any disagreements for manual review.
☐ External Source: Verify a sample of classifications against a human-labeled gold standard set. Calculate precision and recall for each category.
☐ Human Review: Manually review 10 percent of all classifications. Focus on edge cases and documents where the model returned 'Other' as the category.
☐ CI-First Test: Calculate the total cost of the batch run. Compare it to the cost of running the same batch on a higher-tier model. Did the cost savings justify any accuracy loss? If accuracy dropped below acceptable, switch to Flash for the difficult cases.
Workflow 2: Batch Image Description Generation
Learner type: Professionals and students processing image datasets at scale
CI-First benefit tags: Time, Quantity, Quality
Connects to: UIT data science workflows, UIC digital content production, URC research data labeling
Time estimate: 30 to 60 minutes per batch of 50 images
You do | Gemini 3.5 Flash-Lite does |
Prepare your image dataset and description schema | Generate descriptions for each image following your schema |
Submit images via API with your prompt template | Process each image and return structured descriptions |
Sample 10 percent of descriptions for quality check | Identify images where description confidence is low |
Review and correct descriptions that contain errors | Re-process corrected images if needed |
Sample prompt:
Describe this image in 2 to 3 sentences. Focus on the main objects, the setting, and any text visible in the image. Image: [attach image]
Verification checklist:
☐ Multi-Model Check: Run 10 percent of the images through Gemini 3.5 Flash or another vision model and compare descriptions. Note any significant differences in detail or accuracy.
☐ External Source: For images with known content (product photos, labeled datasets), compare the model descriptions against the ground truth labels.
☐ Human Review: Manually review 10 percent of the descriptions against the actual images. Check for hallucinated objects, missed elements, or inaccurate color descriptions.
☐ CI-First Test: Calculate the cost per image description and the average processing time. Compare to manual description time. Did the model save meaningful time at acceptable quality? If descriptions were unreliable, switch to Flash for the difficult images.
Strengths, Limits, and AI Imposture Risk
Strengths
Dimension | Score | Rationale |
Time | 7 | Very fast responses with low latency. The minimal thinking level defaults to speed-optimized inference, making it ideal for high-throughput batch processing. |
Quantity | 7 | Handles high volumes of documents and images at scale. The 1M token context window and 64K output tokens support large batch inputs. |
Quality | 5 | Quality is adequate for simple classification and summarization but drops on complex reasoning tasks. Higher thinking levels improve quality at the cost of speed. |
Skill | 3 | The model does not build lasting user skills. It processes tasks but does not teach the user how to improve their own classification or analysis abilities. |
Limits
Lower intelligence: Flash-Lite is the lowest-cost Gemini variant. It is not designed for complex reasoning, mathematics, coding, or tasks requiring high accuracy. Use a higher-tier model for these tasks.
No audio or video output: The model accepts audio and video input but produces text output only. It does not generate images, audio, or video.
Proprietary: No local deployment. No access to model weights. You depend on Google's API availability and pricing. Not available on Ollama.
Parameter restrictions: Custom values for temperature, top-K, top-P, frequency penalty, and presence penalty are not supported or will be ignored. This limits fine-tuning of model behavior.
Not suitable for reasoning tasks: If your task requires step-by-step reasoning, chain-of-thought analysis, or complex problem solving, Flash-Lite is the wrong model. Choose Gemini 3.5 Flash (high) or Pro (maximum) instead.
AI Imposture Risk
Risk Type | Level | Evidence |
Time Illusion | Low | Speed is real and measurable. The model delivers fast responses for tasks it is designed for. The risk is using it for tasks where speed masks inadequate quality. |
Quantity Illusion | Medium | High-volume processing can mask individual quality failures. When processing thousands of documents, a 5 percent error rate means hundreds of misclassified items that go unnoticed without sampling. |
Skill Illusion | Medium | The low cost and speed can create dependency. Users stop developing their own classification and analysis skills because the model handles them cheaply. Over time this erodes independent judgment. |
Overall | Medium | Medium risk overall, primarily from Quantity Illusion at scale. Mitigated by sampling, verification, and using higher-tier models for difficult cases. |
U365 Co-Intelligence Rating
CI-First Profile
Primary profile is Co-Worker and Assistant (level 2). The model excels at high-volume processing tasks, classification, and batch summarization. It acts as an efficient worker for repetitive tasks. Secondary profile is Analyst and Tester (level 4) for its ability to process and categorize large datasets quickly.
Collaboration Mode
Centaur. There is a clear division of labor. The model handles the high-volume processing. You handle the quality control, prompt design, and verification. The model does not blend into your workflow the way a Cyborg-mode tool would. You submit batches, receive results, and verify.
CI-First Benefit Score
Dimension | Score | Rationale |
Time | 7 | Fast inference at 350 tokens/s with low latency. Saves significant time on high-volume batch processing compared to flagship models. |
Quantity | 7 | 1M token context window and 64K output tokens enable large batch inputs. High-throughput processing of documents and images at scale. |
Quality | 5 | Adequate for simple tasks. Drops on complex reasoning. Higher thinking levels (medium, high) improve quality but reduce the speed advantage. |
Skill | 3 | Does not build lasting skills. The model processes tasks but does not teach users how to improve their own abilities. Risk of dependency at scale. |
Overall | 5.5/10 | CI-First Positive. Strong time and quantity benefits offset by modest quality and low skill development. Best for high-volume tasks where cost and speed matter more than maximum intelligence. |
Humics Protection Badge
Creativity: 0 (Neutral). The model does not erode creativity, but it does not actively protect it either. It produces functional output, not creative work.
Critical Thinking: 0 (Neutral). The model processes tasks efficiently but does not encourage or discourage critical thinking. The risk depends on how you use it.
Social Authenticity: 0 (Neutral). The model has no direct impact on social authenticity.
Score: 0. Badge: Humics-Neutral.
Superhuman Usage Guidance
When to invite the tool: High-volume document classification, batch summarization, image description generation at scale, cost-sensitive text processing where speed matters more than maximum intelligence.
When to keep the tool out: Complex reasoning tasks, mathematics, coding, nuanced analysis, tasks requiring high accuracy, tasks where quality cannot tolerate any tradeoff.
U365 method integration: Use Flash-Lite for the processing phase of LIPS+CARE (process large volumes of source material quickly). Use it for the data collection phase of ULM+EVA (gather and classify data at low cost). Do not use it for the evaluation or judgment phases where higher intelligence is required.
Over-delegation warning: The low cost and speed of Flash-Lite can tempt you to delegate all text and image processing to the model. This creates two risks: (1) quality erosion at scale, where individual errors go unnoticed in high-volume output, and (2) skill dependency, where you stop developing your own classification and analysis abilities because the model handles them cheaply. Always sample and verify output. Use higher-tier models for tasks that require accuracy. Practice the skills yourself on a subset of the data.
What Users Say
Gemini 3.5 Flash-Lite is a model variant within the Gemini API family, not a standalone consumer product. Reviews exist for the Gemini consumer app and the broader Gemini API, but not for this specific variant. Developer community discussion on Reddit and the Google AI Developers Forum provides the most relevant sentiment.
Aggregate Rating Table
Platform | Rating | Reviews |
Trustpilot | No reviews | N/A |
G2 | No reviews | N/A |
Capterra | No reviews | N/A |
Product Hunt | No reviews | N/A |
Mixed community discussion | Multiple threads | |
App Store | No app | N/A |
Google Play | No app | N/A |
GitHub | Not open source | N/A |
What Users Praise
Based on the model's positioning, users who choose Flash-Lite typically value its cost efficiency and speed for high-volume workloads. The model is selected specifically because it is cheaper and faster than alternatives, not because it is more intelligent. Community discussion on Reddit highlights its strong performance in UI generation tasks, where fast iteration at low cost is valued.
What Users Complain About
The primary complaint pattern for efficiency models is quality tradeoff. Users who expect flagship-level intelligence from a Lite model are disappointed. The model is designed for throughput, not depth, and users who use it for complex tasks report lower accuracy. A Reddit thread noted that some users found 3.5 Flash-Lite underperforms 3.1 Flash-Lite in certain use cases, particularly grading assignments. The Google AI Developers Forum has a detailed thread about Flash-Lite not being an adequate replacement for Gemini 2.5 Flash in research assistant use cases.
Sentiment Summary
No model-specific sentiment data was collected for this evaluation. The model is a backend API variant, not a consumer product, so direct user reviews are not available. Developer sentiment around efficiency-tier models generally focuses on cost-to-performance ratio rather than standalone quality. Community discussion is mixed: some praise the speed and cost, others report quality regression compared to previous Flash-Lite versions.
U365 Editorial Note
The absence of model-specific reviews is consistent with the CI-First evaluation. Flash-Lite is an infrastructure-tier model chosen for cost and speed, not for quality. Users who select it know what they are getting: fast, cheap processing with lower intelligence. The CI-First Benefit Score of 5.5 reflects this positioning. The model is CI-First Positive for high-volume tasks where the time and quantity savings outweigh the quality tradeoff. It is not the right tool for tasks where quality is the primary constraint.
Comparison and Alternatives
Gemini 3.5 Flash-Lite occupies the cost-optimized tier of the Gemini model family. Here are 4 alternatives with routing guidance.
Gemini 3.5 Flash (standard): Choose this if you need balanced performance with better intelligence than Flash-Lite. Flash offers higher quality output at moderate cost. If your task requires more than simple classification or summarization, Flash is the right choice. Choose Flash-Lite only when cost is the primary constraint and the task is straightforward.
Gemini 3.5 Pro: Choose this if you need maximum intelligence and accuracy. Pro is the top-tier Gemini model with the best reasoning and quality. Cost is significantly higher than Flash-Lite. Choose Pro for tasks where correctness is critical and cost is not a constraint. Choose Flash-Lite for high-volume tasks where some quality tradeoff is acceptable.
Gemma 3 (via Ollama): Choose this if you need local deployment without API costs. Gemma 3 is Google's open-weight model available on Ollama for free local use. It supports text input. The tradeoff is that you need a GPU for reasonable performance and the model does not match the efficiency of Flash-Lite for high-volume API workloads. Choose Gemma for local, private, or offline use. Choose Flash-Lite for cloud-based high-volume processing.
GPT-5.6 Luna: Choose this if you need a cost-optimized model from a non-Google provider. Luna offers competitive pricing for reasoning tasks. If you want a single provider for all your workloads, compare Luna's cost and quality against Flash-Lite for your specific use case. Choose Flash-Lite if you are already in the Google ecosystem. Choose Luna for cost-sensitive reasoning tasks.
Where Gemini 3.5 Flash-Lite is Clearly Better
Lowest cost in the Gemini family, lowest latency, designed for edge efficiency, supports text and image input at the Lite tier, 350 output tokens/s, 1M context window.
Where it is Clearly Worse
Lowest intelligence in the Gemini family, no reasoning capabilities, text output only (no image, audio, or video generation), proprietary with no local deployment, parameter restrictions on temperature and top-K.
Verdict and Next Steps
Who should adopt: Students and professionals who need high-volume, cost-optimized text and image processing. If you classify thousands of documents, summarize large batches, or process image datasets at scale, the cost and speed savings justify the quality tradeoff. If your task requires reasoning or high accuracy, choose a higher-tier model.
When to adopt: Now, if you have high-volume workloads with clear cost constraints. The model is available on Google AI Studio and the Google API. Test it on a sample of your workload to confirm the quality is acceptable before committing to full-scale adoption.
For what: High-volume document classification, batch summarization, image description generation, cost-sensitive text processing, any task where throughput and cost matter more than maximum intelligence.
UP-Context Prompt Pack:
Prompt 1 (Batch Classification): "Classify the following document into one of these categories: [list categories]. Return only the category name. Document: [paste text]"
Prompt 2 (Batch Summarization): "Summarize the following document in 2 to 3 sentences. Focus on the main point and key supporting details. Document: [paste text]"
Prompt 3 (Image Description): "Describe this image in 2 to 3 sentences. Focus on the main objects, the setting, and any text visible in the image. Image: [attach image]"
Related U365 content: See our INSIDE Tools evaluation of Gemini 3.5 Flash for the balanced-efficiency variant. See our INSIDE Tools evaluation of Gemini 3.5 Pro for the maximum-intelligence variant. See our CI-First Evaluation Framework guide for scoring methodology. See the UIT program curriculum for courses on API cost optimization and batch processing.
U365's Recommendations to Learn More
We curate learning resources for every tool we review. Each link below was verified active as of 2026-09-03. We prioritize content that teaches something this review does not cover: hands-on implementation, benchmark methodology, or community-tested workflows.
Official learning resources
Video tutorials and channels
Written tutorials and deep-dive articles
Community and social
We label community sources so readers know the provenance. Individual creators are welcome when their content teaches something the post itself does not. We exclude only promotional or affiliate content.
Glossary
CI-First Benefit Score
A composite score from 0 to 10 that measures the net benefit of using an AI tool after accounting for the time, effort, and skill required to prompt, verify, and correct its output. It combines four dimensions: Time saved, Quantity of usable output, Quality of verified results, and Skill development. The score is calculated as the average of the four sub-scores. For Gemini 3.5 Flash-Lite, the overall score is 5.5/10 (CI-First Positive), reflecting strong time and quantity benefits offset by modest quality and low skill development.
CI-First Profile
A classification of how an AI tool best serves human co-intelligence, drawn from five profiles: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, and (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration. Gemini 3.5 Flash-Lite is primarily a Co-Worker and Assistant (level 2), excelling at high-volume processing and repetitive tasks, with a secondary Analyst and Tester profile (level 4) for processing and categorizing large datasets.
Humics Protection Badge
A rating that assesses whether an AI tool protects or erodes three core human capabilities: creativity, critical thinking, and social authenticity. Each dimension is scored from -1 (erodes) to +1 (protects), yielding a total from -3 to +3. Gemini 3.5 Flash-Lite scores 0 (Humics-Neutral), meaning it neither actively protects nor erodes these capabilities. The impact depends on how you use it.
AI Imposture Risk
An assessment of whether an AI tool creates illusions of productivity that mask real problems. Three risk types are evaluated: Time Illusion (does the speed hide quality issues?), Quantity Illusion (does volume mask individual failures?), and Skill Illusion (does usage create dependency without learning?). Gemini 3.5 Flash-Lite has an overall Medium risk, primarily from Quantity Illusion at scale, where high-volume low-cost processing can hide quality issues if output is not sampled and verified.
User Sentiment
Aggregated ratings and review themes from public platforms including Trustpilot, G2, Capterra, Product Hunt, Reddit, app stores, and GitHub. For Gemini 3.5 Flash-Lite, no model-specific reviews exist because it is a backend API variant, not a standalone consumer product. Developer sentiment around efficiency-tier models generally focuses on cost-to-performance ratio rather than standalone quality.
Sources
Google blog: Introducing Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber
Appwrite: Gemini 3.5 Flash detailed benchmark and capability review
Reddit r/Bard: Introducing Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber
YouTube: Gemini 3.6 Flash, 3.5 Flash-Lite Benchmark and Pricing (United Top Tech)
YouTube: How To Create Videos With Gemini 3.5 Flash (Social Library)




Comments