
Gemma 3: Practical Open-Weight Models for Local and Cloud Work

Updated: 6 days ago
Status: Active | Last tested: 2026-08-25 (Gemma 3 model family) | Re-check: trigger-based (max 6 months)

Tool Snapshot
Tagline: An open-weight model family with several sizes for local, hosted, text, and image-text work.
Category: Open-weight large language model family
Provider: Google DeepMind
Version tested: Gemma 3 model family (March 2025 release)
Parameters: 1B, 4B, 12B, and 27B variants
Context window: 32K tokens for 1B; 128K tokens for 4B, 12B, and 27B
License: Google Gemma terms (open weights, not standard open-source)
Platforms: Ollama, Hugging Face, cloud providers
Primary use cases:
Run private text assistance on suitable local hardware
Draft, revise, classify, and summarize text under human supervision
Inspect text and images with a supported larger variant
Prototype model-backed applications through local or cloud runtimes
Teach model evaluation, prompting, and verification in a controlled setting
Pricing summary: Model weights are available under Google Gemma terms. Local compute, storage, hosted inference, and managed cloud services can carry separate costs. Check current terms and provider pricing before deployment.
Official links:
Google Gemma documentation: https://ai.google.dev/gemma/docs/core/gemma-3
Hugging Face model collection: https://huggingface.co/google/gemma-3-27b-it
Ollama library: https://ollama.com/library/gemma3
LLM specifications:
Context Window: 32K tokens for 1B; 128K tokens for 4B, 12B, and 27B
Effort Levels: No named low, medium, or high effort controls were supplied in the source pack
Parameters: 1B, 4B, 12B, and 27B variants
Architecture: Decoder-only Transformer with Grouped-Query Attention, local/global sliding window attention (5:1 ratio), SigLIP vision encoder for multimodal variants
Available Platforms: Open weights, local use through Ollama and Hugging Face tooling, plus provider-dependent cloud deployment
Model Variants: 1B, 4B, 12B, and 27B; image-text support applies to the larger variants
Benchmark Note: No benchmark score is quoted because this draft does not include a verified benchmark table
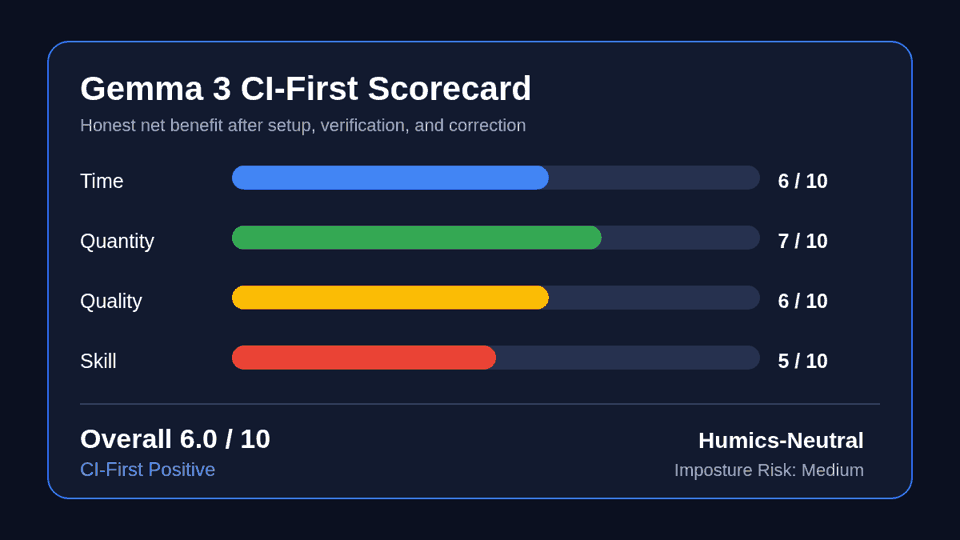
CI-First Benefit Score | 6.0/10 - CI-First Positive |
Time / Quantity / Quality / Skill | 6 / 7 / 6 / 5 |
CI-First Profile | Co-Worker and Assistant (2) |
Humics Protection | Humics-Neutral (+1) |
AI Imposture Risk | Medium |
User Sentiment | Not rated (no verified reviews) |
Pricing | Free (open weights, Google Gemma terms) |
Platforms | Ollama, Hugging Face, cloud providers |
For detailed explanations of the CI-First evaluation terms used in this review, including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.

The Problem
Open-weight model selection creates a practical decision problem. You must choose a model size, runtime, context capacity, input mode, and deployment setting before you can test whether the model suits your work. A cloud-only trial can hide local hardware limits, while a small local trial can underestimate what a larger or hosted variant can do.
You also need a reliable way to separate polished output and correct output. Gemma 3 can draft, classify, explain, and analyze, but the model cannot accept responsibility for factual accuracy, licensing decisions, privacy controls, or final academic and professional judgment.
The Outcome
Gemma 3 gives you one model family with 1B, 4B, 12B, and 27B choices. The 1B variant offers a 32K context window. The 4B, 12B, and 27B variants offer 128K context, and the larger variants support image-text input. This lets you match a trial to available hardware and task demands without treating every size as equivalent.
A disciplined user can produce a checked outline, study guide, code draft, document classification, or image-assisted analysis faster than a manual first pass. The useful outcome is a reviewed artifact that you can explain and defend, not an unchecked model response.
Who Should Use Gemma 3
Learner categories | Difficulty | Typical return | Career path |
Students in Bachelor or Master study | Intermediate | Faster first drafts, study materials, and technical experiments with explicit verification | Strongest fit with UIT technical learning and selected UIC content work |
Professionals | Intermediate | Private local trials, repeatable text processing, application prototypes, and controlled image-text tasks | IT engineering, AI operations, data work, knowledge work, and digital communication |
Lifelong learners | Beginner for hosted use, intermediate for local setup | Guided explanations and practical model literacy | Broad relevance when the learner keeps independent judgment |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Model deployment, AI application design, testing, data handling, and runtime comparison. |
UIB (Business Management, Entrepreneurship) | Medium | Drafting, classification, scenario preparation, and internal knowledge tasks with policy review. |
UIC (Digital Communication, Marketing) | Medium to High | Content analysis, revision, and image-text inspection with human editorial control. |
UID (Digital Design, UX/UI) | Medium | Image-text critique and design support, but Gemma 3 is not a dedicated design production suite. |
Skill level required: Intermediate for reliable use. Beginners can start with a hosted interface, but local deployment requires command-line, storage, memory, and model selection knowledge.
Prerequisites: A defined task, a verification source, an understanding of the data you may share, and hardware or hosted access suited to the selected model size.
Typical time to first result: 15 to 30 minutes after a working runtime is available.
Typical time to competence: Several focused sessions that include prompt revision, failure review, and independent checks.
How Gemma 3 Works
Inputs
Text prompts for every variant. Supported larger variants can also accept images with text instructions. Long documents may fit within the stated context capacity, but usable quality still depends on task design, document structure, and runtime limits.
Outputs
Generated text such as explanations, structured drafts, code, classifications, summaries, critique, and image-related descriptions. A runtime or application can request a chosen structure, but output validation remains your responsibility.
Model range
1B, 4B, 12B, and 27B. The 1B option has a 32K context window. The 4B, 12B, and 27B options have 128K context. Image-text support applies to the larger variants, so you must confirm that the exact model tag and runtime support your intended input.
Deployment
Ollama offers a practical local route. Hugging Face supplies model access and compatible tooling. Cloud options depend on the provider, region, model offering, access controls, and current service terms.
Technical caution
This draft does not quote architecture details or benchmark scores that were not verified in the supplied source pack. Read the official model card and current runtime documentation before you make a production decision. Benchmarks test defined tasks and do not prove reliability in your own workflow.
Getting Started with Gemma 3
Required accounts
Ollama local use may not require a hosted model account after installation. Hugging Face access can require an account and acceptance of Google Gemma terms. Managed cloud access requires the selected provider account and its billing setup.
Installation route A, Ollama
1. Install Ollama on a supported computer.
2. Open the current Gemma 3 library page and select a model size that fits available memory and storage.
3. Run a small test prompt with no private data.
4. Record the exact model tag, runtime version, response time, and test result.
Installation route B, Hugging Face or a compatible runtime
1. Review and accept the applicable Google Gemma terms.
2. Select the exact Gemma 3 model and instruction variant.
3. Configure a supported inference library or service.
4. Test token limits, image input if required, output structure, and failure handling.
Hardware requirements
They vary sharply by model size, precision, runtime, and acceleration. This draft does not provide a minimum RAM or GPU claim because no verified hardware table was supplied. Check the exact model card and runtime guidance before download.
First 15 minutes checklist
☐ Choose one narrow task with a known correct answer.
☐ Run it with a small, non-sensitive sample.
☐ Compare the output with the known answer and note every error.
☐ Save the prompt, model tag, runtime version, and corrected result.
Result
You should have one reproducible, checked test that shows whether the selected Gemma 3 variant and runtime suit your first task.
Real Workflows
Workflow 1: Build a Checked Study Guide with a Local Model
Learner type: Student or lifelong learner
CI-First benefit tags: Time, Quantity, Quality, and Skill when active recall remains human-led
Connects to: UIT - Bachelor in IT - BSc.IT
Time estimate: 45 to 75 minutes including source checks and revision
Step | You do | Gemma 3 does |
1 | Select one course chapter and write three learning objectives | Reads the supplied chapter extract and objectives |
2 | Mark required terms, formulas, and source page references | Proposes an organized study guide |
3 | Answer five recall questions before viewing model answers | Generates questions and a separate answer key |
4 | Check each claim and correction against the course source | Revises only the flagged sections |
5 | Write a short explanation in your own words | Critiques clarity and identifies unsupported statements |
Keep source text and model output separate. Do not ask the model to invent citations or page numbers.
Sample prompt:
Profile: Coach and Tutor. Context: I am studying [module] in UIT - Bachelor in IT - BSc.IT. The attached source is the only course source you may use. Task: Create a study guide with five core concepts, five active-recall questions, and a separate answer key. Constraints: Mark uncertain statements as NOT IN SOURCE.
Verification checklist:
☐ Multi-Model Check: Send the objectives and non-sensitive source extract to a second provider model and compare omissions, disputed claims, and question quality.
☐ External Source: Check every factual statement and formula against the assigned course material and one authoritative reference where the course permits it.
☐ Human Review: The learner reviews the guide, and an instructor or qualified peer checks any disputed technical point.
☐ CI-First Test: Explain each concept and answer each recall question without Gemma 3. Revise or remove any item you cannot defend.
Workflow 2: Review an Image and Text Evidence Pack
Learner type: Professional or advanced student
CI-First benefit tags: Time, Quantity, and Quality
Connects to: UIT - Bachelor in IT - BSc.IT and UIC content-analysis work [Confirm with academic team]
Time estimate: 60 to 90 minutes including independent evidence review
Step | You do | Gemma 3 does |
1 | Choose a supported larger variant and prepare a non-sensitive image with its source text | Accepts the image-text package |
2 | Define the exact question, decision boundary, and required evidence fields | Produces an observation table |
3 | Separate direct observations, interpretations, and unknowns | Rewrites entries under those three labels |
4 | Inspect the original image and source text line by line | Responds to targeted correction prompts |
5 | Approve, reject, or rewrite each conclusion | Produces a final structured draft that preserves your decisions |
Do not use image interpretation as the sole basis for medical, legal, safety, grading, hiring, or disciplinary decisions.
Sample prompt:
Profile: Analyst and Tester. Context: I am reviewing an image and its source note for [project]. Task: List direct visual observations, source-supported statements, interpretations, and unknowns. Constraints: Do not identify a person, infer sensitive traits, or add facts absent in the image or source.
Verification checklist:
☐ Multi-Model Check: Use a second image-capable provider model and compare direct observations, disputed details, and unsupported interpretations.
☐ External Source: Inspect the original high-resolution image, source note, metadata, and any authoritative domain reference required by the task.
☐ Human Review: A subject specialist checks the evidence labels, uncertainty, and decision boundary before use.
☐ CI-First Test: Explain why every retained statement belongs in observation, source-supported statement, interpretation, or unknown. Remove any statement you cannot defend.
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | Moderate net saving on first-pass drafting, classification, and source-bound restructuring | One prompt can produce a usable draft quickly, but checks and correction reduce the gross saving |
Quantity | Stronger output volume across repeated, well-defined tasks | Several model sizes support experimentation and repeated structured outputs |
Quality | Moderate improvement when prompts include sources, constraints, and a review loop | The user can ask for explicit unknowns, source boundaries, and revision of flagged sections |
Skill | Moderate potential when used as Coach and Tutor | Skill grows only when the learner explains, tests, and reproduces the work without the model |
Limits
Model output can state incorrect information with confident wording.
The 1B variant has a shorter 32K context window and does not carry every larger-variant capability.
Image-text support depends on the selected larger variant and runtime implementation.
Local performance depends on model size, precision, hardware, and software configuration.
Google Gemma terms are not the same as a standard permissive open-source license. Review them for your intended distribution and service model.
Cloud availability, pricing, and privacy controls vary by provider.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | Setup, model download, prompt revision, source checking, and local performance tuning can consume the saving on a small or poorly defined task |
Quantity Illusion | Medium | The model can produce many polished drafts, but repeated phrasing and factual defects can survive a quick scan |
Skill Illusion | High | A learner can submit competent-looking explanations or code without understanding how they work or how to detect errors |
Overall Imposture Risk | Medium | One high risk has clear mitigation through active recall, executed tests, source checks, and human review |
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (2)
Secondary profiles: Coach and Tutor (3), Analyst and Tester (4), and Challenger and Devil's Advocate (5) when prompted for those roles
Collaboration Mode
Recommended mode: Centaur
Alternative mode: Cyborg for experienced users during low-risk drafting and iterative code experiments
Mode rationale: Human control should define the task, data boundary, source set, acceptance criteria, and final judgment. Gemma 3 should handle draft production, restructuring, and bounded analysis.
CI-First Benefit Score
Dimension | Score | Rationale |
Time | 6/10 | Clear saving on repeatable first-pass work, reduced by setup and verification |
Quantity | 7/10 | Several sizes and local or hosted routes support more usable trials and drafts |
Quality | 6/10 | Source-bound prompting and correction can improve structure and coverage, but correctness remains uneven |
Skill | 5/10 | Teaching use can build working knowledge, while pure delegation creates dependency |
CI-First Benefit Score | 6.0/10 | CI-First Positive |
Humics Protection
Creativity | Neutral, 0 | The model can supply options, but human originality depends on the workflow |
Critical Thinking | Protects, +1 | A four-tier verification routine requires comparison, source checks, and defended judgment |
Social Authenticity | Neutral, 0 | The model can edit communication, but final voice must remain the user's own |
Humics Protection Score | +1 | |
Badge | Humics-Neutral |
Superhuman Usage Guidance
When to invite Gemma 3: bounded drafting, source-based restructuring, local model experiments, repeated classification, image-text observation with a supported larger variant, and tutoring that requires active recall.
When to keep Gemma 3 out: final ethical or disciplinary decisions, private data without approved controls, claims you cannot verify, authentic personal communication that requires your own voice, and work where local setup costs more time than manual completion.
LIPS + CARE: Store approved prompts, source boundaries, test results, and corrected outputs in the relevant LIPS location. Use CARE to collect the task, set the action plan, review output, and execute only after checks.
ULM + EVA: Use Gemma 3 during exploration and action planning, then require human choice and recorded action.
UP-Context: State the AI Profile, user context, task, constraints, evidence rules, and output structure in every serious prompt.
SL-OS: Save verified artifacts in approved Microsoft 365 locations. Do not assume a native Gemma 3 connection when none has been configured.
UNOP: Use active recall, explanation, spaced review, and independent reproduction so the learner practices the underlying skill.
Over-delegation warning: If Gemma 3 writes the explanation, code, or conclusion and you cannot reproduce, test, or defend it, Human Intelligence has dropped. Stop, study the source, perform the task without the model, and return only when you can supervise the output.
What Users Say
Aggregate Rating Table
Platform | Rating | Review count | Editorial status |
Trustpilot | Not reported | Not reported | No verified Gemma 3 model-family rating was supplied for this draft |
G2 | Not reported | Not reported | No verified Gemma 3 model-family rating was supplied for this draft |
Capterra | Not reported | Not reported | No verified Gemma 3 model-family rating was supplied for this draft |
Product Hunt | Not reported | Not reported | No verified launch count was supplied for this draft |
App Store and Google Play | Not applicable as a direct model-family rating | Not reported | Ratings for third-party applications must not be assigned to the underlying model |
Not rated | Not reported | No verified thread sample was supplied for this draft | |
Futurepedia and FutureTools | Not reported | Not reported | No verified directory rating was supplied for this draft |
What Users Praise
No user-praise summary is published because the supplied material does not contain verified review excerpts or a documented sample.
What Users Complain About
No complaint summary is published for the same reason. Local setup burden, output accuracy, and runtime support are evaluated elsewhere as product characteristics, not attributed to users.
Sentiment Summary
Not rated. The article does not convert general model attention, downloads, or third-party application reviews into a Gemma 3 satisfaction score.
U365 Editorial Note
The absence of verified crowd ratings neither supports nor contradicts the CI-First evaluation. The 6.0 score rests on task fit, deployment choice, model limits, and the cost of verification. Add a sentiment comparison only after a documented review sample and retrieval date are available.
Comparison and Alternatives
Alternative | Choose the alternative if | Choose Gemma 3 if |
Meta Llama | Your organization has standardized on Llama tooling, terms, and supported services | You want Gemma 3 model sizes, Google Gemma terms, and its stated context options |
Mistral models | Your selected runtime, region, or provider has stronger Mistral support | Gemma 3 has the better tested fit for your local or hosted task |
Qwen models | Your task, language set, or existing application stack has been validated with Qwen | You need a controlled Gemma 3 trial with 1B, 4B, 12B, or 27B choices |
Microsoft Phi models | Your deployment is centered on Microsoft-supported small-model workflows | Gemma 3's size range or larger-variant image-text support matches your test |
Where Gemma 3 is clearly better
It offers a clear size range and stated context split, with 32K on 1B and 128K on 4B, 12B, and 27B. Local routes through Ollama and Hugging Face make direct trials practical. Larger variants add image-text work within one model family.
Where Gemma 3 is clearly worse
It may be the wrong choice when your organization requires a different license, provider support, runtime, language performance, or established production history. Multimodal support is not uniform across every size. A model-family label does not remove the need to test the exact variant, precision, and runtime.
Routing rule: Do not choose by reputation alone. Run the same non-sensitive evaluation set on two suitable models, record quality and total task time, review applicable terms, then choose the model with the best verified fit.
Verdict and Next Steps
Who should adopt it: UIT learners, technical professionals, educators, and controlled application teams that can test an open-weight model and verify its output.
When: At the start of a model evaluation, local AI experiment, private drafting trial, or image-text prototype where the team can define acceptance criteria.
For what: Bounded text generation, document restructuring, tutoring, code assistance, classification, and supported image-text analysis.
Verdict: Gemma 3 is a credible practical choice when its model sizes, context limits, deployment routes, and terms fit your task. Adopt it through a measured test, not a general assumption of quality. Keep source checks, executed tests, and human approval in the workflow.
UP-Context prompt pack
1. Profile: Co-Worker and Assistant. Context: I am preparing [artifact] for [audience] using only the attached approved sources. Task: Produce a first draft. Constraints: Mark missing facts as NOT IN SOURCE, do not invent citations, and list uncertain statements. Output: draft, source map, uncertain list.
2. Profile: Coach and Tutor. Context: I am learning [topic] and have this current level: [level]. Task: Teach one concept, ask me to explain it, then correct my explanation. Constraints: Do not give the final answer until I attempt it. Output: short lesson, active-recall question, feedback, and next step.
3. Profile: Challenger and Devil's Advocate. Context: I propose [decision] based on [evidence]. Task: Test the decision. Constraints: Separate evidence gaps, alternative explanations, operational risks, and ethical concerns. Output: challenge table, three questions I must answer, and a clear statement of what would change my mind.
Related U365 content: Use current UP-Context, CI-First, LIPS + CARE, ULM + EVA, and UNOP learning materials. Select the exact catalog links during academic review rather than inserting an unverified course URL.
Migration Path
Current requirement: No migration is recommended because Gemma 3 is marked Active.
Re-check triggers: a change to Google Gemma terms, removal of a required model or runtime tag, a security notice, loss of provider support, a major quality regression on the saved evaluation set, or a replacement that produces a clearly better verified result at lower total cost.
If migration becomes necessary, preserve the evaluation set, prompts, source boundaries, acceptance criteria, corrected artifacts, and reviewer notes. Re-run the same tests on the replacement. Do not assume prompt behavior, context handling, image support, safety controls, or output structure will transfer.
Replacement: Not selected. Choose one only after terms review, privacy review, runtime validation, total-time measurement, and human approval.
U365's Recommendations to Learn More
This curated selection gives Fellows verified starting points for deeper work with Gemma 3. Every link was verified as active on 2026-09-03.
Official learning resources
Google Gemma 3 model card - Official model card with architecture, training data, and evaluation details
Gemma 3 Technical Report on arXiv - Full technical paper by the Google DeepMind Gemma Team
Run Gemma with Hugging Face Transformers - Official tutorial for text and image inference
Hugging Face Gemma 3 documentation - Transformers library integration guide
Video tutorials and channels
Gemma 3 Explained: Google's Open-Source AI Beast (Full Guide) - community walkthrough by proflead covering AI Studio, Hugging Face, and Google API setup
Fine Tune Gemma 3 with Hugging Face and Datawizz - step-by-step fine-tuning tutorial for the 270M variant
Written tutorials and deep-dive articles
Google Gemma 3 announcement blog post - Official Google blog announcing Gemma 3 with feature overview
Hugging Face model collection page - Model card, usage snippets, and community discussions
Gemma 3 full guide by proflead - Community walkthrough covering local setup, API access, and a web interface demo
Community and social
Gemma 3 on r/LocalLLaMA - Community discussion thread on local deployment experiences
Google DeepMind Gemma model page - Official DeepMind page with model family overview and Gemmaverse ecosystem
Ollama Gemma 3 library page - Local deployment instructions and available model tags
Google Gemma cookbook on GitHub - Official tutorials, notebooks, and example applications
Every link was verified active (HTTP 200 or 403 for bot-blocking) on 2026-09-03. Individual creators are included because their content teaches practical skills the post itself does not cover. Exclude only promotional or affiliate content.
Glossary
CI-First Benefit Score
A composite score from 0 to 10 that measures how much a tool genuinely helps under the Co-Intelligence framework. It averages four dimensions: Time saved, Quantity of usable output, Quality improvement, and Skill built. A score of 6.0 places Gemma 3 in the CI-First Positive band, meaning it provides genuine, verified benefits when used with discipline, but it is not transformative. Each sub-score is rated independently and then averaged.
CI-First Profile
One of five roles that describe how a human and AI tool collaborate. Gemma 3's primary profile is Co-Worker and Assistant (level 2), meaning it handles delegated drafting, restructuring, and bounded analysis while the human retains task definition, source control, and final judgment. Secondary profiles include Coach and Tutor (level 3), Analyst and Tester (level 4), and Challenger and Devil's Advocate (level 5). The five levels are: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration.
Humics Protection Badge
A rating of how well a tool protects human creativity, critical thinking, and social authenticity. The badge ranges from Humics-Friendly to Humics-Risky. Gemma 3 earns a Humics-Neutral badge with a score of +1, because its critical thinking dimension is protected through the four-tier verification routine, while creativity and social authenticity remain neutral. The badge helps users understand whether a tool strengthens or erodes the human capacities that matter most for genuine work.
AI Imposture Risk
An assessment of how easily a tool can create a false sense of competence in three areas: Time Illusion, Quantity Illusion, and Skill Illusion. Gemma 3 has an overall Medium risk. The Skill Illusion is rated High because a learner can submit competent-looking explanations or code without understanding how they work or how to detect errors. The Time and Quantity Illusions are Medium because setup and verification costs reduce the apparent time savings, and polished output can hide factual defects. Mitigation requires active recall, source checks, and human review.
User Sentiment
Aggregated ratings and qualitative feedback from review platforms such as Trustpilot, G2, Capterra, Product Hunt, Reddit, and others. For Gemma 3, no verified user sentiment data was available at the time of evaluation. The absence of crowd ratings neither supports nor contradicts the CI-First score. User sentiment becomes meaningful only when a documented sample with a retrieval date is collected and compared against the CI-First evaluation.




Comments