
GLM-5.3: Zhipu AI's Bilingual Reasoning Model at 753B Parameters

Updated: 6 days ago
Status: Active | Last tested: 2026-09-03 (GLM-5.3 max) | Re-check: trigger-based (max 6 months)

Tool Snapshot
Tagline: The latest generation of Zhipu AI's General Language Model, built for bilingual reasoning, long-horizon tasks, and agentic engineering.
Category: Large Language Model
Provider: Z.ai (formerly Zhipu AI)
Version tested: GLM-5.3 (max effort)
Parameters: 753 billion (MoE, ~40B active per token)
Context window: 1M tokens (1,048,576)
License: Custom GLM-5.3 License (not MIT). Weights available on Hugging Face.
Platforms: API (Z.ai, bigmodel.cn, OpenRouter). Open weights on Hugging Face.
Primary use cases:
Bilingual text generation and reasoning in English and Chinese
Complex problem-solving with extended chain-of-thought reasoning
Code generation and software engineering tasks
Long-context document processing up to 1 million tokens
Agentic workflows with tool calling and multi-step planning
Pricing summary: Paid - $1.40 per 1M input tokens, $4.40 per 1M output tokens. Cache hit at $0.26 per 1M. Blended rate approximately $0.90 per 1M tokens. Free tier available on z.ai with usage limits.
Official links:
Website: https://z.ai
API Platform: https://z.ai/pricing
Documentation (EN): https://docs.z.ai/
Documentation (CN): https://open.bigmodel.cn/
Hugging Face: https://huggingface.co/zai-org/GLM-5.3
Artificial Analysis: https://artificialanalysis.ai/models/glm-5-3
Migration Guide: https://open.bigmodel.cn/dev/howuse/migrate-to-glm-5-3
LLM specifications:
Context Window: 1M tokens (1,000,000)
Effort Levels: Reasoning model with max effort (chain-of-thought). Disabling thinking is no longer supported. Levels: low, high, max (default max).
Parameters: 753 billion (MoE, ~40B active per token, same base as GLM-5.2)
Architecture: Mixture-of-Experts, 256 routed experts, 8 per token, 1 shared expert, 78 layers, hidden size 6,144. Post-training upgrade of GLM-5.2 base.
Available Platforms: API (Z.ai, bigmodel.cn, OpenRouter). Open weights on Hugging Face (zai-org/GLM-5.3). Not available on Ollama.
Model Variants: GLM-5.3 (flagship), GLM-5.3-Flash (320B/18B multimodal), GLM-5.3-BF16 (full precision)
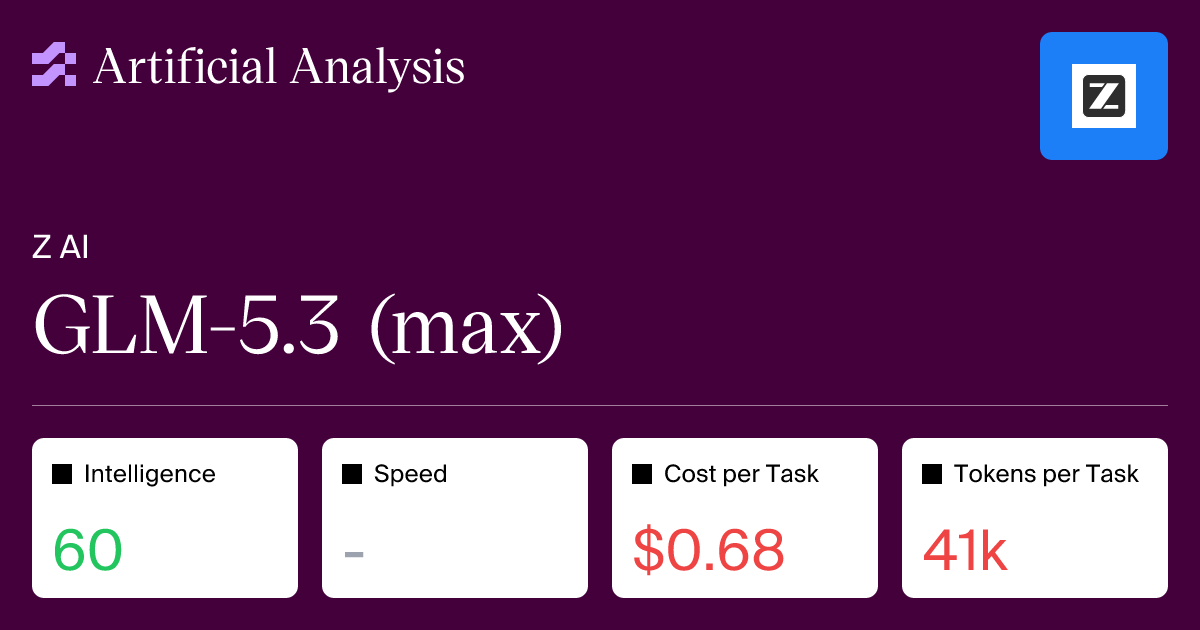
Benchmark Scores: Artificial Analysis Intelligence Index: 60 (ranked #9 of 187). Terminal-Bench 3.0: 28.3. DeepSWE v1.1: 66.9. CyberGym: 84.5%. Agents' Last Exam: 28.5.
Speed: 90 tokens per second (above average, median 75)
Latency: Time to first token: 1.22s (very competitive, median 2.92s)
Modality: Text input only, text output only. Not multimodal. GLM-5.3-Flash supports image and video.
CI-First Benefit Score | 5.8/10 (CI-First Positive) |
Time / Quantity / Quality / Skill | 6 / 7 / 6 / 4 |
CI-First Profile | Co-Worker and Assistant (2) |
Humics Protection | Humics-Neutral (-1/+3) |
AI Imposture Risk | Medium-High |
User Sentiment | No data (released 2026-08-18) |
Pricing | Paid ($1.40/$4.40 per 1M tokens) |
Platforms | API (Z.ai, bigmodel.cn, OpenRouter) |
Context Window | 1M tokens |
For detailed explanations of the CI-First evaluation terms used in this review, including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
The Problem
Working with large language models often forces a tradeoff: you get either strong reasoning or low cost, but rarely both. Models that reason well tend to be expensive and slow. Models that are fast and cheap tend to struggle with complex, multi-step problems.
For bilingual users, the problem is worse. Most top-tier models are optimized for English. Chinese-language reasoning, code generation, and academic writing often produce lower quality output, even on models that claim multilingual support.
GLM-5.3 from Zhipu AI targets this gap. It is a 753-billion-parameter reasoning model with a 1-million-token context window, built by a Chinese AI lab with deep bilingual training. Released August 18, 2026, it competes on intelligence with models costing 2 to 3 times more.
The Outcome
You get a reasoning model that scores 60 on the Artificial Analysis Intelligence Index (ranked #9 of 187 models tested), at $1.40 per 1M input tokens and $4.40 per 1M output tokens. For comparison, Claude Opus 5 (max) scores 63 at $15 per 1M output, and GPT-5.6 Sol (max) scores 61 at $40 per 1M output.
The 1-million-token context window lets you process entire codebases, long research papers, or extended conversation histories in a single request. The model's bilingual training means Chinese and English tasks get similar quality, which matters for academic work, international business, and cross-language research.
You also get competitive speed: 90 tokens per second output and 1.22 seconds to first token. This is faster than GPT-5.6 Sol (74 t/s), Grok 4.6 (62 t/s), and Kimi K3 (35 t/s).
Who Should Use GLM-5.3
Learner categories:
Learner type | Difficulty | Typical ROI | Career path |
Students (Bachelor, Master) | Intermediate | Bilingual research assistance, code generation for coursework, long-context document analysis | programs in AI, Data Science, Software Development |
Professionals (career upskilling) | Intermediate | Cost-effective API for production applications, bilingual customer service, agentic workflows | programs in Business Management, Digital Entrepreneurship |
Everyone (lifelong learners) | Beginner to Intermediate | Affordable access to frontier-grade reasoning, personal knowledge management with 1M context |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Direct relevance for code generation, agentic engineering, and LLM API integration courses. |
UIB (Business Management, Entrepreneurship) | Medium | Useful for building bilingual AI applications and cost-effective API products. |
UIC (Digital Communication, Marketing) | Medium | Bilingual content generation and long-context analysis for research. |
UID (Digital Design, UX/UI) | Low to Medium | Text-only model, but useful for design research and documentation tasks. |
Skill level required: Intermediate. You need basic API knowledge or experience using a chat interface.
Prerequisites: Familiarity with LLM concepts. For API use, basic programming knowledge.
Typical time to first result: 5 minutes via the z.ai chat interface. 15 minutes for API integration.
Typical time to competence: 2 to 4 weeks for effective prompt design and output verification.
How GLM-5.3 Works
Inputs: Text prompts, conversation history, code snippets, documents (up to 1 million tokens total context). The model accepts text only. It does not accept images.
Outputs: Text responses including reasoning traces, code, analysis, structured data, and tool-call plans. The model outputs text only.
Underlying technology
Model: GLM-5.3 (max), a 753-billion-parameter proprietary model from Zhipu AI (branded as Z.ai).
Architecture: Not publicly disclosed. Transformer-based with extended chain-of-thought reasoning. The model uses reasoning tokens (time spent thinking before answering) which contribute to its verbosity.
Reasoning: Yes. GLM-5.3 is a reasoning model. It works through complex problems before providing an answer, similar to OpenAI's o-series or DeepSeek's reasoning models.
Context window: 1 million tokens. This includes user input, model output, and reasoning tokens generated during thinking.
Bilingual training: The model is trained with strong Chinese and English capabilities, making it one of the few frontier-grade models with genuine bilingual fluency.
Integrations: API access via Z.ai (international) and bigmodel.cn (China). OpenAI SDK compatible. LangChain integration available. Python and Java SDKs provided.
Pricing: $1.40 per 1M input tokens, $4.40 per 1M output tokens. Cache hit at $0.26 per 1M tokens (81 percent discount). Blended rate approximately $0.90 per 1M tokens.
Speed: 90 tokens per second output. Time to first token: 1.22 seconds.
Benchmarks: Artificial Analysis Intelligence Index score of 60, ranked #9 of 187 models. The index includes GDPval-AA v2, Terminal-Bench v2.1, SciCode, Humanity's Last Exam, GPQA Diamond, AA-Omniscience, and AA-LCR.
Availability: 2 API providers. Open weights now available on Hugging Face (zai-org/GLM-5.3). Not yet available for local deployment via Ollama (GLM-5.1 and GLM-5.2 are available on Ollama but GLM-5.3 is not yet listed).
See ollama.com/search for local deployment options and artificialanalysis.ai for independent benchmark rankings.
Getting Started with GLM-5.3
Required accounts: A free Z.ai account for the chat interface. A paid API account at z.ai/pricing for programmatic access. A bigmodel.cn account for the Chinese platform.
Installation
Web-based chat at z.ai. For API use, no installation required. Use HTTP requests or the OpenAI-compatible SDK.
First-time configuration
1. Create an account at z.ai for the chat interface or API access.
2. For API use, generate an API key in the Z.ai dashboard.
3. Install the Python SDK: pip install zhipuai (or use the OpenAI SDK with the Z.ai base URL).
4. Set your API key as an environment variable.
5. For OpenAI SDK compatibility, set the base URL to the Z.ai endpoint.
First 15 minutes checklist
☐ Create a Z.ai account and open the chat interface.
☐ Ask GLM-5.3 a bilingual question (English and Chinese) to test its fluency.
☐ Submit a coding task (for example, write a Python function) and review the output.
☐ Paste a long document (at least 50 pages of text) and ask for a summary to test the context window.
☐ If using the API, make your first API call with a simple prompt and verify the response.
Result: You will have tested GLM-5.3's core capabilities (bilingual fluency, code generation, long context) and confirmed API access if needed.
Real Workflows
Workflow 1: Bilingual Academic Research Assistant
Learner type: Student
CI-First benefit tags: Time, Quality
Connects to: UIT AI and Data Science programs. URC research methodology courses.
Time estimate: 30 to 45 minutes including verification.
Step 1: You identify a research topic and gather source materials in both English and Chinese.
Step 2: You paste the sources into the Z.ai chat interface (up to 1M tokens of context).
Step 3: GLM-5.3 reads the sources, identifies key themes across both languages, and produces a structured summary with citations.
Step 4: You review the summary, identify gaps or misinterpretations, and ask follow-up questions to refine the analysis.
Step 5: You verify key claims against the original sources and write your own analysis using the model's output as a starting point, not a final product.
Sample prompt:
You are a bilingual academic research assistant. I am providing you with 3 research papers (2 in English, 1 in Chinese) about large language model evaluation methods. Context: I am writing a literature review for my Master's thesis in AI. Task: Read all 3 papers and produce a structured comparison table with columns for: paper title, methodology, key findings, limitations, and relevance to bilingual evaluation. Constraints: Keep the table concise. Do not invent findings not present in the papers. Flag any claim you are not confident about. Output format: Markdown table followed by a 200-word synthesis paragraph.
Verification checklist:
☐ Multi-Model Check: Run the same prompt through Claude Sonnet 5 or GPT-5.6 and compare the comparison tables for discrepancies.
☐ External Source: Verify at least 2 key findings from the summary against the original papers by reading the relevant sections yourself.
☐ Human Review: Your thesis advisor reviews the summary for accuracy and completeness before you use it in your literature review.
☐ CI-First Test: Can you explain and defend each finding in the summary without referring to the model's output? [Y/N]
Workflow 2: Cost-Effective API Product Development
Learner type: Professional
CI-First benefit tags: Time, Quantity, Quality
Connects to: UIT Software Development and Digital Transformation programs. UIB Digital Entrepreneurship programs.
Time estimate: 2 to 3 hours including testing and verification.
Step 1: You define the product requirements: a bilingual customer support chatbot that handles English and Chinese queries.
Step 2: You set up the Z.ai API with your API key and configure the OpenAI-compatible endpoint.
Step 3: GLM-5.3 processes user queries, using its reasoning capability to handle complex support tickets that require multi-step problem solving.
Step 4: You implement caching to reduce costs (cache hit at $0.26 per 1M tokens, an 81 percent discount over input price).
Step 5: You test the chatbot with 50 bilingual support scenarios and verify response quality, accuracy, and cost per interaction.
Sample prompt:
You are a bilingual customer support agent for a SaaS company. Context: A customer is reporting a billing error where they were charged twice for their subscription. Task: Analyze the billing issue, identify the likely cause, and provide a step-by-step resolution in the customer's language (Chinese). Constraints: Do not make assumptions about the billing system you cannot verify. If you need more information, ask the customer. Output format: A response message to the customer (in Chinese) plus an internal note (in English) for the billing team.
Verification checklist:
☐ Multi-Model Check: Run 10 test queries through both GLM-5.3 and another model (for example, Gemini 3.7 Flash) and compare response quality and accuracy.
☐ External Source: Verify the billing resolution steps against your actual billing system documentation.
☐ Human Review: A bilingual support team member reviews 10 random responses for cultural appropriateness and accuracy.
☐ CI-First Test: Can your team handle the same support tickets manually without the model? [Y/N]
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | Saves time on complex reasoning tasks. 1.22s TTFT and 90 t/s output speed are above average for reasoning models. | Artificial Analysis: faster than GPT-5.6 Sol (74 t/s), Grok 4.6 (62 t/s), and Kimi K3 (35 t/s). |
Quantity | High output volume. The model generated 170M tokens during benchmark evaluation, well above the 72M median. | Artificial Analysis verbosity ranking. Useful for generating multiple drafts or extensive analysis. |
Quality | Intelligence Index score of 60, ranked #9 of 187 models. Near-frontier performance at a fraction of the cost. | Scores 60 vs Claude Opus 5 at 63 ($15/1M output), GPT-5.6 Sol at 61 ($40/1M output). |
Skill | Marginal. The model produces expert-level output but does not actively teach the user. Standard Skill Illusion risk for strong LLMs. | No built-in tutoring mode. Output is answers, not explanations designed to build capability. |
Limits
Text only. The model does not accept or produce images. For multimodal tasks, you need a different model.
Proprietary. No open weights. You cannot self-host or inspect the model architecture. This limits research and customization.
Very verbose. 170M tokens on benchmark evaluation is more than double the median. This means higher output costs and more reading time for users.
Not on Ollama. GLM-5.3 is not available for local deployment. GLM-5.1 and GLM-5.2 are on Ollama but are older versions.
High Skill Illusion risk. The model's strong reasoning can mask a user's lack of understanding, especially in coding and academic tasks.
Limited review data. Released August 18, 2026. No user reviews on any platform yet. Performance claims are based on benchmarks, not sustained user experience.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The model's verbosity (170M tokens, 2.4x median) means users spend significant time reading and filtering output. Net time savings are real for complex tasks but can shrink when concise output would suffice. |
Quantity Illusion | Medium | High-volume, polished output that requires spot-checking. The reasoning trace is long, which can mask quality issues in the final answer. |
Skill Illusion | High | Expert-level reasoning and code generation can create the appearance of competence in users who lack the underlying skill. The model does not teach, it produces. Standard risk for strong reasoning LLMs. |
Overall Imposture Risk: Medium-High
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (2). The model's main value is executing complex text and reasoning tasks at high quality and low cost.
Secondary profiles: Co-Creator and Thought Partner (1) for brainstorming and ideation. Analyst and Tester (4) for data analysis and code review.
Collaboration Mode
Recommended mode: Centaur. Clear division of labor: the user defines tasks, reviews output, and makes final decisions. GLM-5.3 handles generation, reasoning, and drafting.
Alternative mode: Cyborg for rapid iterative prototyping where the user has domain expertise to evaluate output quickly.
Mode rationale: The model's verbosity and high Skill Illusion risk make Centaur mode safer. The user must actively review and verify output rather than accepting it in a rapid iteration loop.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 6 | Above-average speed (90 t/s, 1.22s TTFT) but verbosity increases reading time. Net savings are moderate. |
Quantity | 7 | 170M tokens on benchmark evaluation. High output volume at low cost ($0.90/1M blended). Clear quantity benefit. |
Quality | 6 | Intelligence Index 60, ranked #9 of 187. Near-frontier quality at low cost. Text-only and not multimodal, which limits quality in some tasks. |
Skill | 4 | The model produces expert output but does not teach. Skill Illusion risk is high. Users gain marginal skill benefit from direct use. |
CI-First Benefit Score: 5.8 / 10 (CI-First Positive)
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | The model can support ideation but does not actively strengthen the user's creative thinking. Standard for a text generation LLM. |
Critical Thinking | Erodes (-1) | The model produces confident, well-reasoned answers that can discourage independent verification. The verbosity creates the illusion of thoroughness. |
Social Authenticity | Neutral (0) | The model drafts communication but does not replace genuine human voice. Bilingual capability helps users express ideas across languages. |
Humics Protection Score: -1 / +3
Badge: Humics-Neutral
Superhuman Usage Guidance
When to invite this tool:
Bilingual research and analysis tasks (English and Chinese)
Code generation and review for UIT programs
Long-context document processing (up to 1M tokens)
Cost-sensitive API applications where frontier-grade quality is needed at low cost
Complex reasoning tasks where chain-of-thought helps (math, logic, multi-step planning)
When to keep this tool out:
Tasks requiring image or multimodal input (the model is text-only)
Creative writing where your authentic voice matters most
Tasks where you cannot verify the output (high Skill Illusion risk)
Tasks where the model's verbosity would slow you down more than help
U365 method integration:
LIPS + CARE: GLM-5.3 can process collected information in the Collect phase and draft action plans. Use it to summarize long documents for your Digital Second Brain.
ULM + EVA: The model supports the Career domain through code generation and professional writing. Use it in the Explore phase for bilingual research and the Action phase for code generation.
UP-Context: The model responds well to UP-Context prompting. Provide context, role, task, constraints, and output format for best results.
SL-OS: The model fits as an API endpoint in your SL-OS workflow. Use it for long-context tasks that Microsoft 365 Copilot cannot handle.
UNOP: The model does not teach, which weakens UNOP alignment. Use it as a production tool, not a learning tool. Pair it with a coaching model for UNOP workflows.
Over-delegation warning: GLM-5.3's strong reasoning and low cost make it tempting to delegate entire workflows. If you delegate reasoning without verifying, your HI drops. When HI drops, CI drops even if the model is strong. The model's verbosity creates the illusion of thoroughness: long output looks complete but may contain subtle errors. Always verify key claims independently. The Executive Safeguard applies: assume you are working with the worst AI available.
What Users Say
Aggregate Rating Table
Platform | Rating | Number of reviews | Link |
Trustpilot | No reviews found | 0 | N/A |
G2 | No reviews found | 0 | N/A |
Capterra | No reviews found | 0 | N/A |
Product Hunt | No reviews found | 0 | N/A |
Reddit sentiment | Unable to access via API. Sentiment not collected. | N/A | N/A |
Futurepedia | No reviews found | 0 | N/A |
FutureTools | No reviews found | 0 | N/A |
No reviews found on any platform. GLM-5.3 was released on August 18, 2026, six days before this evaluation. The model is an API product, not a SaaS application, so consumer review platforms are unlikely to accumulate reviews. Developer sentiment may appear on Reddit, Hacker News, and X (Twitter) in the coming weeks.
What Users Praise
No user reviews are available yet. Based on the Artificial Analysis benchmark data, the model's strengths are its intelligence-to-price ratio (score 60 at $1.40/$4.40 per 1M tokens), competitive speed (90 t/s), and 1M token context window. These are benchmark-measured attributes, not user-reported experiences.
What Users Complain About
No user complaints are available yet. Potential concerns based on benchmark data include the model's high verbosity (170M tokens on evaluation, 2.4x the median), which increases output costs and reading time. The text-only modality (no image support) may also limit use cases for users who need multimodal capabilities.
Sentiment Summary
Overall sentiment: No data. The model is too new for aggregated user sentiment.
Key themes: No user-reported themes available. Benchmark data suggests cost-effectiveness, bilingual capability, and reasoning quality are the model's main differentiators.
U365 Editorial Note
The absence of user reviews is consistent with the model's release date (August 18, 2026). GLM-5.3 is six days old at the time of this evaluation. The CI-First Benefit Score of 5.8 (CI-First Positive) is based entirely on benchmark data from Artificial Analysis, not user experience. The Medium-High Imposture Risk rating reflects the standard risk profile of strong reasoning models: high Skill Illusion risk because the model produces expert output without teaching. Users should treat this evaluation as a benchmark-based assessment, not a user-experience-based one. Re-test after 60 to 90 days when user reviews and community feedback become available.
Comparison and Alternatives
Alternative | When to Choose |
You need a Chinese-developed model with open weights. You need multimodal capabilities. | |
You need higher intelligence (60 vs 58). You prefer the Z.ai platform and 1M context window. | |
You need multimodal capabilities (Gemini supports image input). You prefer integrated Google Workspace access. | |
You need open weights for self-hosting. You prefer a lower-cost alternative for production use. | |
You need open-weight bilingual models. You want local deployment via Ollama. |
Where GLM-5.3 is clearly better
Where GLM-5.3 is clearly better: GLM-5.3 offers the best intelligence-to-price ratio in its tier. At Intelligence Index 60 and $4.40 per 1M output tokens, it delivers near-frontier quality at a fraction of the cost of Claude Opus 5 ($15) or GPT-5.6 Sol ($40). For bilingual English-Chinese tasks, it is one of the few frontier-grade options. The 1M token context window matches or exceeds most competitors.
Where GLM-5.3 is clearly worse
Where GLM-5.3 is clearly worse: The model is text-only. Claude Opus 5, GPT-5.6 Sol, Gemini 3.7 Flash, and Qwen3.8 Max all support image input. If you need multimodal capabilities, GLM-5.3 cannot serve you. The model is also proprietary with no open weights, unlike DeepSeek and Qwen which offer open-weight variants. Finally, the model is not yet available on Ollama for local deployment, unlike GLM-5.1 and GLM-5.2 which are.
Verdict and Next Steps
Verdict:
Who should adopt it: Students, professionals, and developers who need frontier-grade reasoning at low cost, especially for bilingual English-Chinese tasks. UIT learners building AI applications. UIB entrepreneurs creating cost-effective API products.
When: Now, if your use case is text-only and bilingual capability matters. If you need multimodal input, wait for a vision variant or use a different model.
For what: Complex reasoning, code generation, long-context document processing, and bilingual text tasks.
UP-Context prompt pack:
1. Bilingual research analysis: You are a bilingual academic research assistant. Context: I am analyzing research papers in English and Chinese about [topic]. Task: Read the provided papers and produce a structured comparison. Constraints: Do not invent findings. Flag uncertain claims. Output format: Markdown table with columns for paper, methodology, findings, limitations.
2. Code review and improvement: You are a senior software engineer. Context: I am reviewing a [language] codebase for [purpose]. Task: Analyze the code for bugs, security issues, and improvement opportunities. Constraints: Prioritize issues by severity. Provide specific code fixes. Output format: Numbered list of issues with severity, description, and fix.
3. Cost-effective API design: You are an API architect. Context: I am building a bilingual customer support system using GLM-5.3. Task: Design the API integration with caching to minimize costs. Constraints: Target under $0.01 per interaction. Use the cache hit price ($0.26/1M). Output format: Architecture description with cost estimate.
Related U365 content:
Insert relevant UIT AI and Data Science course link after confirming with academic team
Insert relevant URC research methodology course link after confirming with academic team
U365's Recommendations to Learn More
We curate the best resources to go beyond this review. Each link has been verified as active as of 2026-09-03. We prioritize substantive content that teaches something this post does not cover.
Official learning resources
Z.ai GLM-5.3 blog post: https://z.ai/blog/glm-5.3
GLM-5.3 on Hugging Face (model card, weights, benchmarks): https://huggingface.co/zai-org/GLM-5.3
Z.ai developer documentation: https://docs.z.ai
Artificial Analysis model page (independent benchmarks): https://artificialanalysis.ai/models/glm-5-3
Video tutorials and channels
How to Use GLM 5.3 for FREE (community walkthrough by Julian Goldie SEO): https://www.youtube.com/watch?v=2WsksmRYB6g
Written tutorials and deep-dive articles
GLM 5.3: Specs, Download and Hardware (Kingy AI): https://kingy.ai/blog/glm-5-3-specs-benchmarks-api-how-to-use/
GLM 5.3: Zhipu's Open-Weight Model Excels at Coding and Cyber (DEV Community): https://dev.to/jamilxt/glm-53-zhipus-open-weight-model-excels-at-coding-and-cyber-1m86
GLM 5.3 Review: API, Pricing, Coding, and Agents (WaveSpeed): https://wavespeed.ai/blog/ai-models/glm-5-3-review
GLM-5.3 on DocsBot (specs, benchmarks, FAQ): https://docsbot.ai/models/glm-5-3
Community and social
GLM-5.3 on Hugging Face (community discussions): https://huggingface.co/zai-org/GLM-5.3
GLM-5.3-Flash on Hugging Face (multimodal variant): https://huggingface.co/zai-org/GLM-5.3-Flash
Hacker News discussion on GLM-5.3 weights: https://news.ycombinator.com/item?id=49449507
We label community sources so readers know the provenance. We exclude promotional or affiliate content. Individual creators are welcome when their content is substantive and teaches something the post itself does not.
Glossary
CI-First Benefit Score
A 0-10 score measuring how much a tool benefits human co-intelligence across four dimensions: Time (net time saved after verification), Quantity (usable output volume), Quality (durable quality improvement), and Skill (genuine lasting capability built). The score is the average of the four dimensions. For GLM-5.3, the score is 5.8/10 (CI-First Positive), driven by strong Quantity (7) and moderate Time (6) and Quality (6) but limited Skill (4) because the model produces expert output without teaching.
CI-First Profile
A classification of how a tool collaborates with human intelligence, ranging from Co-Creator and Thought Partner (level 1) to Challenger and Devil's Advocate (level 5). Lower level numbers indicate higher AI autonomy in the collaboration. The five levels are: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. GLM-5.3 is classified as Co-Worker and Assistant (level 2) because its primary value is executing complex text and reasoning tasks at high quality and low cost, with secondary profiles as Co-Creator (level 1) for brainstorming and Analyst (level 4) for code review.
Humics Protection Badge
A rating from -3 to +3 measuring how a tool affects three human faculties: Creativity, Critical Thinking, and Social Authenticity. Each dimension is rated as Protects (+1), Neutral (0), or Erodes (-1). GLM-5.3 scores -1/+3 (Humics-Neutral) because it Erodes Critical Thinking (-1) by producing confident, verbose answers that can discourage independent verification, while being Neutral on Creativity (0) and Social Authenticity (0).
AI Imposture Risk
An assessment of three traps: Time Illusion (output looks fast but reading/verifying takes time), Quantity Illusion (high volume of polished output masks quality issues), and Skill Illusion (expert output creates false competence in the user). Each is rated Low, Medium, or High. GLM-5.3 has Medium-High overall risk: Time Illusion (Medium) due to verbosity, Quantity Illusion (Medium) due to 170M token output volume, and Skill Illusion (High) because the model produces expert-level answers without teaching the underlying skill.
User Sentiment
Aggregated ratings and review themes from consumer and developer platforms (Trustpilot, G2, Capterra, Product Hunt, Reddit, Futurepedia, FutureTools). For GLM-5.3, no user reviews exist on any platform because the model was released on August 18, 2026, only six days before this evaluation. As an API product rather than a SaaS application, consumer review platforms are unlikely to accumulate reviews. Developer sentiment may emerge on Reddit, Hacker News, and X in the coming weeks.




Comments