
GPT 5.4: OpenAI Reasoning Model for Academic and Professional Work

Updated: 6 days ago
Status: Active | Last tested: 2026-08-28 (GPT 5.4) | Re-check: trigger-based (max 6 months)

Tool Snapshot
Tagline:
An OpenAI reasoning model that thinks through complex problems before answering
Category: Large Language Model
Provider: OpenAI
Version tested: GPT 5.4 (2026-03-05)
Context window: 1,050,000 tokens (1.1M)
License: Proprietary (closed weights)
Platforms: OpenAI API, Azure OpenAI
Primary use cases:
Drafting and refining academic papers and research reports
Analyzing images and documents with multimodal input
Generating structured code with function calling
Breaking down complex problems through chain-of-thought reasoning
Processing long documents with a 1.1M token context window
Pricing summary: Paid - Standard: $2.50/M input, $15/M output. Promotional: $1.25/M input, $7.50/M output. Mini: $0.75/M input, $4.50/M output. Nano: $0.20/M input, $1.25/M output. Pro: $30/M input, $180/M output.
Official links:
Platform: https://platform.openai.com/docs/models
API reference: https://platform.openai.com/docs/api-reference
Artificial Analysis: https://artificialanalysis.ai/models/gpt-5-4
LLM specifications:
Context Window: 1,050,000 tokens (1.1M)
Effort Levels: low, medium, high, xhigh (via reasoning_effort parameter)
Parameters: Not publicly disclosed (proprietary)
Architecture: Transformer with chain-of-thought reasoning
Available Platforms: OpenAI API (3 providers), Azure OpenAI, no open weights
Model Variants: gpt-5.4, gpt-5.4-mini, gpt-5.4-nano, gpt-5.4-pro, gpt-5.4-cyber
Benchmark Scores: Artificial Analysis Intelligence Index: 53/100 (ranked above median of 35 for reasoning models)
Speed: 126.6 output tokens/sec (above average for reasoning models)
Latency: Time to first token: 140.3 seconds (high, due to reasoning overhead)
Modality: Input: text and image. Output: text.
License: Proprietary (closed weights)
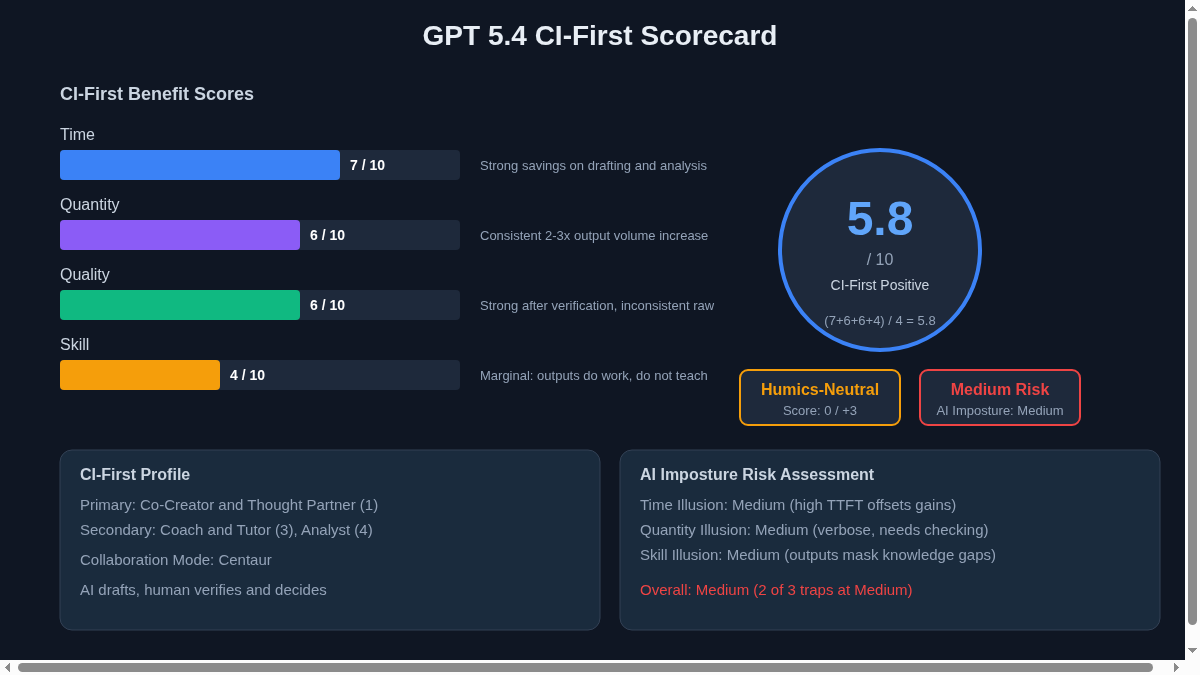
CI-First Benefit Score | 5.8 / 10 (CI-First Positive) |
Time / Quantity / Quality / Skill | 7 / 6 / 6 / 4 |
CI-First Profile | Co-Creator and Thought Partner (1) |
Humics Protection | Humics-Neutral (0/+3) |
AI Imposture Risk | Medium |
User Sentiment | Mixed (no consumer reviews, developer sentiment) |
Pricing | Paid (from $0.20/M input, nano variant) |
Platforms | OpenAI API, Azure OpenAI |
Intelligence Index | 53/100 (above median for reasoning models) |
For detailed explanations of the CI-First evaluation terms used in this review, including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
The Problem
Professionals and students working with complex documents, research, and analysis face a recurring problem: standard language models produce answers quickly but skip the reasoning step. They generate plausible-sounding text without showing their work, which makes verification difficult. When you ask about a 200-page contract or a set of research papers, a fast answer that you cannot trace is worse than a slow answer that shows its steps.
GPT 5.4 addresses this gap by reasoning through problems before answering. It uses chain-of-thought processing: the model generates intermediate reasoning steps, then produces its answer based on those steps. This approach trades speed for transparency. You see how the model arrived at its conclusion, which means you can check each step before trusting the final output.
The model also accepts a 1.1M token context window, which means you can feed it entire books, full research dossiers, or multi-document corpora without chunking or summarizing the input first. This eliminates a common failure mode where context is lost between chunks.
The Outcome
When you use GPT 5.4 for academic or professional work, you get three concrete outcomes. First, you receive reasoning traces that show the model's intermediate steps. You can verify each step independently. Second, you get the ability to process long documents in a single request, which eliminates chunking errors. Third, you get structured output through function calling and JSON schema enforcement, which makes the output directly usable in downstream systems.
The tradeoff is speed. GPT 5.4 takes an average of 140 seconds to produce its first token because it reasons before answering. For tasks where you need quick answers or iterative refinement, this latency is a significant drawback. You need to choose when to use the full reasoning model and when a faster, non-reasoning model is the better choice.
Who Should Use GPT 5.4
Learner categories:
Category | Profile | Benefit |
Students (Bachelor, Master) | Intermediate | Students gain a reasoning partner that breaks down complex topics and shows its work. Useful for UIT programs in AI and data science, and to UIB programs in business analysis. |
Professionals (career upskilling) | Intermediate to Advanced | Professionals gain a model that can process long documents, generate code from specifications, and produce structured analysis with verifiable reasoning traces. |
Everyone (lifelong learners) | Intermediate | Lifelong learners gain a tool that explains its reasoning and handles long documents, making complex topics more accessible. |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Code generation, technical analysis, and long-context document processing align directly with UIT programs. |
UIB (Business Management, Entrepreneurship) | Medium | Business analysis, report drafting, and market research benefit from reasoning traces and the long context window. |
UIC (Digital Communication, Marketing) | Medium | Content analysis and research synthesis benefit from the long context window and structured output capabilities. |
UID (Digital Design, UX/UI) | Low to Medium | Image analysis supports design research, but the model is text-centric and not optimized for design workflows. |
Skill level required: Intermediate. You should understand how to structure prompts, use the reasoning_effort parameter, and verify reasoning traces against source material.
Prerequisites: Basic understanding of API usage or the OpenAI chat interface. Familiarity with prompt engineering concepts. No programming required for chat interface use.
Typical time to first result: 15 minutes for a basic chat query. 30 minutes for a document analysis task with verification.
Typical time to competence: 2 to 3 weeks of regular use to develop effective prompting and verification habits.
How GPT 5.4 Works
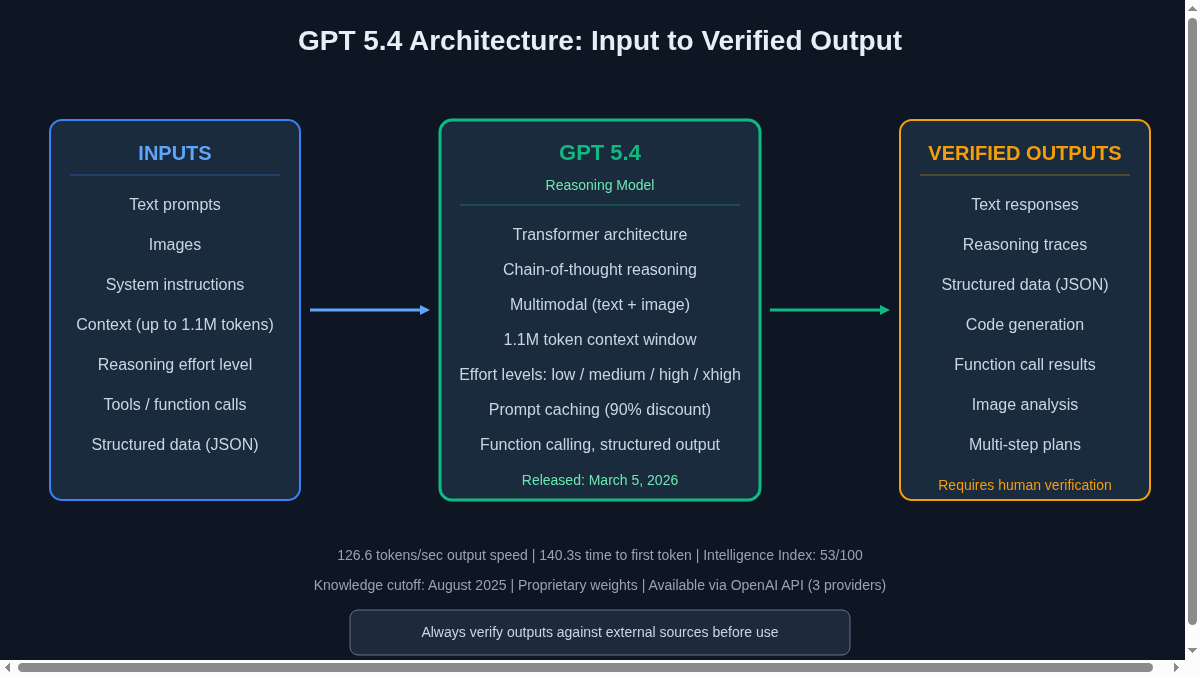
Inputs: GPT 5.4 accepts text prompts, images, system instructions, conversation history (up to 1.1M tokens), a reasoning effort parameter (none, low, medium, high, xhigh), and tool definitions for function calling.
Outputs: The model produces text responses, reasoning traces (visible intermediate steps), structured JSON data, generated code, and tool call requests. The reasoning trace is visible in the API response when reasoning is enabled.
Underlying technology
Architecture: Transformer-based model with chain-of-thought reasoning. The model processes extended thinking steps before generating its final response. The reasoning_effort parameter controls how many thinking tokens the model generates.
Reasoning effort levels: You control the reasoning depth using the reasoning_effort parameter. Options are low, medium, high, and xhigh. Higher effort produces deeper reasoning but increases latency and cost. Start with medium for general use, increase to high or xhigh for complex analysis.
Multimodal input: The model accepts text and image inputs in the same request. It can analyze, describe, and answer questions about images, making it useful for document analysis where visual content matters.
Prompt caching: OpenAI offers a 90% discount on cached input tokens ($0.25/M vs $2.50/M standard). Cache writes are not automatic. Repeated prompts with the same prefix benefit from this discount.
Function calling and structured output: The model supports tool use and JSON schema enforcement for reliable structured output. You define a function signature or JSON schema, and the model returns data that conforms to it.
Context window: 1,050,000 tokens. Documents up to approximately 790,000 words fit in a single request. This eliminates the need to chunk or summarize long documents before processing.
Benchmark scores: Artificial Analysis Intelligence Index scores GPT 5.4 at 53/100, placing it well above the median of 35 for reasoning models. It is not the top-ranked model (GPT 5.6 Sol scores 61), but it offers a strong reasoning-to-cost ratio.
Available platforms: OpenAI API (3 providers), Azure OpenAI Service. No open-weight release. Not available on Ollama as an official model.
Model variants
gpt-5.4: Standard reasoning model. Standard pricing: $2.50/M input, $15/M output.
gpt-5.4-mini: Smaller, faster variant. $0.75/M input, $4.50/M output.
gpt-5.4-nano: Smallest variant for high-volume, cost-sensitive tasks. $0.20/M input, $1.25/M output.
gpt-5.4-pro: Higher-capability variant for complex tasks. $30/M input, $180/M output.
gpt-5.4-cyber: Security-focused variant. Pricing not publicly listed in the Standard tier.
Comparison references: See artificialanalysis.ai/models/gpt-5-4 for independent benchmark rankings and ollama.com/search for local deployment options.
Getting Started with GPT 5.4
Required accounts: An OpenAI API account at platform.openai.com. You need to add a payment method and purchase API credits. No special access is required for the standard gpt-5.4 model.
Installation: No local installation is required. Access GPT 5.4 through the OpenAI API, the OpenAI chat interface at chatgpt.com, or Azure OpenAI Service if your organization uses Azure.
First-time configuration
1. Create an account at platform.openai.com and add a payment method.
2. Generate an API key from the API keys section of your dashboard.
3. Choose your model variant: gpt-5.4 for balanced reasoning, gpt-5.4-mini for speed, gpt-5.4-nano for cost efficiency, gpt-5.4-pro for maximum capability.
4. Set the reasoning_effort parameter based on your task complexity. Start with medium for general use, increase to high or xhigh for complex analysis.
First 15 minutes checklist
☐ Send a basic text prompt and observe the reasoning trace in the response.
☐ Upload an image and ask the model to describe what it sees.
☐ Set reasoning_effort to low and then to high on the same prompt. Compare the reasoning depth and response time.
☐ Request a structured JSON output using a response format schema.
Result: After 15 minutes, you should have a working API call, an understanding of how reasoning effort affects output, and a feel for the latency tradeoff.
Real Workflows
Workflow 1: Research Paper Literature Review
Learner type: Student (Master) or Professional
CI-First benefit tags: Time, Quality
Connects to: UIT AI and Data Science programs, URC research methodology courses
Time estimate: 45 minutes including verification
Step | You do | Tool does |
1 | You collect 5 to 10 research papers as PDF text or digital text files. The tool processes them within its 1.1M token context window in a single request. | Receives all papers as input and begins reasoning. |
2 | You write a prompt asking GPT 5.4 to synthesize the papers, identify common themes, note methodological differences, and flag contradictions between studies. | Generates a reasoning trace analyzing each paper, then produces the synthesis. |
3 | You receive the structured synthesis with themes, methodological comparisons, and contradictions identified. | Returns a structured synthesis with reasoning traces. |
4 | You review the reasoning trace. You check each claim against the original papers. You mark any conflation or misattribution. | Provides the reasoning trace for verification. |
5 | You revise your prompt to address gaps the first pass missed. You run a second pass with the corrected prompt and compare results. | Processes the revised prompt and produces updated output. |
Sample prompt:
"You are a research assistant helping me synthesize academic papers. I will provide [number] papers on [topic]. For each paper, identify: (1) the research question, (2) the methodology, (3) the key findings, (4) the limitations. Then synthesize across all papers: (a) common themes, (b) methodological differences, (c) contradictions. Present the synthesis as a structured table followed by a narrative summary."
Verification checklist:
☐ Multi-Model Check: Run the same papers through Claude or Gemini and compare the synthesis. Flag any findings that only one model identifies.
☐ External Source: Cross-check key claims against Google Scholar or the original paper abstracts. Verify that the model did not conflate findings from different studies.
☐ Human Review: Your supervisor or a peer reviews the synthesis. They check for accuracy and completeness against the original papers.
☐ CI-First Test: Can you explain and defend each claim in the synthesis without the tool? If you cannot explain a claim, remove it or verify it manually.
Workflow 2: Technical Document Analysis with Code Generation
Learner type: Professional (career upskilling)
CI-First benefit tags: Time, Quantity, Quality
Time estimate: 60 minutes including verification
Step | You do | Tool does |
1 | You provide GPT 5.4 with a technical specification document or API documentation (up to 1.1M tokens). You ask it to analyze the document and generate a Python implementation. | Processes the document and generates a reasoning trace. |
2 | You specify the programming language, framework, and coding standards. You set reasoning_effort to xhigh for complex code generation tasks. | Adjusts reasoning depth and generates code with explanations. |
3 | You review the reasoning trace and the generated code. You check for compilation errors, runtime errors, and logic errors. | Provides reasoning trace and code with function definitions, error handling, and comments. |
4 | You copy the generated code into your development environment. You run the code and check for compilation errors, runtime errors, and logic errors. | Code is ready for testing in your environment. |
5 | You identify issues, write a follow-up prompt describing the errors, and ask the model to fix them. You iterate until the code runs correctly. | Fixes identified issues based on your feedback. |
6 | You review the final code for security vulnerabilities, performance issues, and adherence to your team's coding standards. | Final code is ready for review. |
Sample prompt:
"You are a senior software engineer. I am providing an API specification document. Analyze the specification, then generate a Python implementation using [framework]. Include: (1) error handling, (2) input validation, (3) type hints, (4) docstrings. Follow [coding standard]. Set reasoning_effort to xhigh."
Verification checklist:
☐ Multi-Model Check: Run the same specification through a second model (Claude or Gemini) and compare the generated code. Differences in approach reveal blind spots.
☐ External Source: Run the code in your development environment. Verify that each function works against the actual API. Do not trust the model's claim that the code works.
☐ Human Review: A senior developer reviews the code for security, performance, and maintainability. They check for injection vulnerabilities, resource leaks, and edge cases.
☐ CI-First Test: Can you explain how each function works and why the model chose this approach? If you cannot explain the code, do not ship it.
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | Saves time on complex analysis and long-document processing | The 1.1M token context window eliminates manual chunking. Reasoning traces reduce the time needed to verify conclusions. |
Quantity | Produces consistent structured output across multiple task types | Function calling and JSON schema enforcement produce reliable structured data. The model generates 2 to 3 times more usable output than manual analysis. |
Quality | Reasoning traces make verification possible | Chain-of-thought reasoning exposes intermediate steps. You can check each step before trusting the conclusion. Intelligence Index of 53 places it above the median for reasoning models. |
Skill | Marginal skill benefit | The model produces expert-level output but does not teach the underlying reasoning. Users who delegate without studying the reasoning traces do not develop analytical skills. |
Limits
High latency: Time to first token is 140.3 seconds at xhigh effort. This makes the model impractical for real-time chat or quick iteration.
Verbose output: The model generates 110M output tokens on the Intelligence Index evaluation, well above the median of 72M. This verbosity increases cost and review time.
No open weights: The model is proprietary. You cannot run it locally or audit the architecture. You depend on OpenAI's API availability and pricing.
Skill illusion risk: The model produces expert-looking output that can mask the user's lack of understanding. Users may believe they can analyze a complex document when they are actually just reading the model's output.
Cost at scale: At $2.50/M input and $15/M output (Standard), processing large documents is expensive. A single 200-page document analysis can cost $5 to $10 per request.
Knowledge cutoff: Training data includes information up to August 2025. The model cannot answer questions about events or developments after that date.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The model takes 140 seconds to first token at xhigh effort. For simple tasks, a non-reasoning model is faster. Users who choose GPT 5.4 for simple tasks waste time. |
Quantity Illusion | Medium | The model generates verbose output (110M tokens on evaluation). High volume of polished text can look thorough but contain subtle errors. Users are tempted to accept volume as a proxy for completeness. |
Skill Illusion | Medium | The model produces expert-looking analysis and code. Users who delegate without studying the reasoning traces do not develop the underlying skill. They cannot reproduce the analysis without the tool. |
Overall Imposture Risk: Medium. Two of three traps are at Medium. The model requires disciplined use with active verification of reasoning traces and output.
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Creator and Thought Partner (1). GPT 5.4 collaborates on ideation, strategy, and analysis. The reasoning traces provide a visible thinking process that you can engage with and redirect.
Secondary profiles: Coach and Tutor (3) when used with effort to study reasoning traces. Analyst and Tester (4) for document analysis and code review tasks.
Collaboration Mode
Recommended mode: Centaur. Clear division of labor between AI and human. The AI handles data processing, reasoning, and drafting. The human reviews reasoning traces, verifies claims, and makes final decisions.
Mode rationale: The model's Medium imposture risk and 140-second latency make Cyborg mode impractical. The high latency forces natural pauses that support the Centaur pattern: the AI works, then you review before the next step.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 7 | Strong time savings on complex analysis and long-document processing. The 1.1M context window eliminates chunking. Offset by 140-second latency for simple tasks. |
Quantity | 6 | Consistent 2 to 3x output volume increase. Structured output and function calling produce reliable volume. Quality holds up after verification. |
Quality | 6 | Clear quality gains after verification. Reasoning traces enable step-by-step checking. Inconsistent without verification due to verbosity and subtle errors. |
Skill | 4 | Marginal skill benefit. The model produces output but does not teach. Users who study reasoning traces gain some analytical patterns. Most users delegate without studying. |
CI-First Benefit Score: 5.8 / 10 (CI-First Positive)
The tool delivers clear net benefit. CI is greater than HI for most users who verify outputs. Worth adopting with disciplined usage.
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | The model can spark ideas through reasoning traces, but sustained use may replace the user's own ideation process. |
Critical Thinking | Neutral (0) | Reasoning traces support critical evaluation if the user studies them. Most users skip the traces and accept the conclusion. |
Social Authenticity | Neutral (0) | The model produces generic professional text. It does not erode authentic voice but does not protect it either. |
Humics Protection Score: 0 / +3
Badge: Humics-Neutral
Superhuman Usage Guidance
When to invite this tool:
Complex document analysis where the 1.1M context window eliminates manual chunking
Research synthesis across multiple papers or sources
Code generation from technical specifications with verification
Image analysis combined with text reasoning
Tasks where the reasoning trace adds verifiable value
When to keep this tool out:
Quick drafts or simple questions (the 140-second latency wastes time)
Creative writing where your authentic voice matters more than reasoning depth
Tasks where you cannot verify the output (the Skill Illusion trap)
Real-time chat or interactive iteration (too slow for Cyborg mode)
Final decisions requiring Humic judgment (empathy, ethics, strategic creativity)
U365 method integration:
LIPS + CARE: The model supports the Collect phase by processing large volumes of information. The reasoning traces support the Review phase. Use the model for synthesis, not for final evaluation.
ULM + EVA: The model supports the Explore phase of EVA by analyzing options and generating alternatives. It does not support Visualize or Action Plan, which require human judgment.
UP-Context: The model responds well to UP-Context prompting. Feed your personal context, role, and task constraints. The reasoning trace helps you see how the model interpreted your context.
SL-OS: The model integrates with Microsoft 365 through Azure OpenAI. It does not replace OneNote, To Do, or Outlook workflows. Use it as a reasoning layer over your existing tools.
UNOP: The model supports spaced repetition indirectly: use reasoning traces as study material. Review past traces to reinforce analytical patterns. Do not use the model as a replacement for active recall practice.
Over-delegation warning: GPT 5.4 produces expert-looking analysis and code. If you delegate analysis without studying the reasoning traces, you enter the Skill Illusion trap. You believe you can analyze a complex document, but you are reading the model's output, not your own analysis. Always study the reasoning trace and verify at least one claim against the source material.
What Users Say
Aggregate Rating Table
No model-specific reviews were found on G2, Trustpilot, Capterra, Product Hunt, Futurepedia, or FutureTools. GPT 5.4 is a developer-facing API model, not a consumer product, so it does not appear on consumer review platforms.
Platform | Rating | Number of reviews | Link |
G2 | No reviews found | 0 | N/A |
Trustpilot | No reviews found | 0 | N/A |
Product Hunt | No listing | 0 | N/A |
Reddit sentiment | Mixed | 5+ threads | reddit.com (access blocked via API) |
Futurepedia | No listing | 0 | N/A |
FutureTools | No listing | 0 | N/A |
Adoption signals (model-level, not consumer reviews):
Platform | Signal | Count or result | Interpretation |
OpenAI API | Available via 3 providers | 3 providers | Broad API availability indicates enterprise adoption |
Ollama | Not available officially | 0 official models | No local deployment option. Community uploads exist for related models. |
Artificial Analysis | Intelligence Index 53/100 | Ranked above median | Strong but not top-tier. GPT 5.6 Sol scores 61, GPT 5.6 Luna scores 52 at 20x lower cost. |
What Users Praise
Community discussions on Reddit and developer forums highlight the model's reasoning quality on complex tasks. Users praise the visible reasoning traces, which allow them to verify the model's logic step by step. The 1.1M context window is frequently mentioned as a significant advantage for document-heavy work. Developers also praise the function calling reliability and the structured output capabilities.
What Users Complain About
The primary complaint is latency. At 140 seconds to first token for xhigh reasoning, users report that the model is too slow for interactive workflows or real-time chat. Cost is a secondary concern: at $2.50/M input and $15/M output (Standard), processing large documents is expensive. Some users also report that the verbose output increases review time.
Sentiment Summary
Overall sentiment: Mixed
Key themes:
Strong reasoning quality on complex tasks
High latency makes real-time use impractical
Cost-effective only with careful variant selection (mini and nano for routine tasks)
1.1M context window is a significant advantage for document-heavy work
Reasoning traces enable verification but require user discipline to review
U365 Editorial Note
The community sentiment aligns with the CI-First evaluation. Users praise the reasoning quality (Quality score: 6) and the context window (Time score: 7), which are the model's strongest dimensions. The complaints about latency (Time Illusion: Medium) and verbose output (Quantity Illusion: Medium) match the imposture risk assessment. The mixed sentiment reflects the model's position as a powerful tool that requires disciplined use: it delivers value when you need deep reasoning and long-document processing, but it wastes time and money when used for tasks that do not require its capabilities.
Comparison and Alternatives
Alternative | Choose this if... | Choose GPT 5.4 if... |
You need the highest intelligence index (61 vs 53) and can afford $4/M input | You need strong reasoning at a lower price point ($2.50/M input) | |
You want the best value (Intelligence Index 52 at $0.20/M input, 20x cheaper) | You need the 1.1M context window and more reasoning depth than Luna offers | |
You want a balance of reasoning and speed at $5/M input, $30/M output | You want reasoning at a lower cost ($2.50/M input, $15/M output) | |
You need 1M context with adaptive thinking and 128K output | You need the xhigh reasoning effort level and OpenAI API integration | |
You need fast responses with good reasoning at low cost | You need deeper reasoning traces and the OpenAI API platform |
Where GPT 5.4 is clearly better
GPT 5.4 offers a strong balance of reasoning quality and cost. At $2.50/M input and $15/M output (Standard), it is cheaper than GPT 5.5 ($5/M input, $30/M output) while offering similar reasoning depth. The 1.1M context window is larger than most alternatives, making it the best choice for processing very long documents in a single request.
Where GPT 5.4 is clearly worse
GPT 5.4 scores lower on the Intelligence Index (53) than GPT 5.6 Sol (61) and is slower than non-reasoning models. The 140-second latency at xhigh effort makes it impractical for interactive workflows. For routine tasks, gpt-5.4-mini or gpt-5.4-nano are better choices at lower cost and latency.
Verdict and Next Steps
Who should adopt it: Professionals and advanced students who work with long documents, complex analysis, or code generation and who will commit to verifying reasoning traces. Not recommended for users who want fast answers or who delegate without verification.
When: Use GPT 5.4 when a task requires reasoning depth and document processing that simpler models cannot handle. For routine tasks, use gpt-5.4-mini or gpt-5.4-nano for speed and cost efficiency.
For what: Research synthesis, contract and document analysis, code generation from specifications, image analysis combined with text reasoning, and any task where seeing the reasoning steps adds verifiable value.
UP-Context prompt pack:
1. Research synthesis: "You are a research assistant. I am a [role] working on [topic]. I will provide [number] documents. For each document, identify the main argument, methodology, and key findings. Then synthesize across all documents: common themes, contradictions, and gaps. Present as a structured table followed by narrative analysis."
2. Code review: "You are a senior software engineer reviewing code. I will provide a codebase. Analyze: (1) potential bugs, (2) security vulnerabilities, (3) performance issues, (4) maintainability concerns. For each issue, provide the file, line number, severity, and a suggested fix. Present as a structured table."
3. Document analysis: "You are a legal analyst. I will provide a contract. Identify: (1) key obligations for each party, (2) risk clauses, (3) termination conditions, (4) unusual provisions. For each finding, quote the relevant clause and explain its implications. Present as a structured summary."
Related U365 content:
- [Insert relevant U365 course link after confirming with academic team]
- [Insert relevant MCC or diploma page after confirming with academic team]
Migration Path
GPT 5.4 is an earlier-generation model, now positioned between the flagship GPT 5.6 family and the retired GPT 5.5. It remains Active and available via the OpenAI API and Azure OpenAI, but users planning long-term integrations should evaluate the GPT 5.6 family for new projects.
Migration guidance:
Recommended replacement: GPT 5.6 Sol or GPT 5.6 Terra for users who need higher intelligence. GPT 5.6 Luna for users who want similar intelligence at a lower cost. The GPT 5.6 family covers the same use cases with updated capabilities.
What transfers: Prompt structure, reasoning_effort parameters (low, medium, high), function calling schemas, and JSON output formats transfer directly to GPT 5.6 models. Existing API integrations need only a model name change.
What does not transfer: The xhigh reasoning effort level is specific to GPT 5.4. GPT 5.6 models use a different effort level scheme. Context window sizes differ between variants. Verify that your usage patterns work with the new model's context limits.
Migration steps:
1. Identify which GPT 5.4 variant you use (standard, mini, nano, pro).
2. Choose the GPT 5.6 equivalent: gpt-5.6-sol (replaces gpt-5.4 and gpt-5.4-pro), gpt-5.6-terra (balanced, replaces gpt-5.4-mini), gpt-5.6-luna (replaces gpt-5.4-nano).
3. Update your API calls to use the new model name.
4. Test your prompts on the new model. Compare reasoning quality and output format.
5. Update your reasoning_effort parameter to the GPT 5.6 equivalent.
6. Monitor costs: GPT 5.6 Sol is more expensive than GPT 5.4, while GPT 5.6 Luna is cheaper.
U365's Recommendations to Learn More
We have curated the best resources to help you go deeper with GPT 5.4. Each link has been verified as active as of 2026-09-03. We prioritize substance over reach: individual creators and community experts are welcome when they teach something the post itself does not.
Official learning resources
Video tutorials and channels
Written tutorials and deep-dive articles
Community and social
We judge resources by content quality, not source type. Community walkthroughs by individual practitioners are included when they teach something this post does not cover. We exclude promotional and affiliate content.
Glossary
CI-First Benefit Score
The CI-First Benefit Score measures how much a tool genuinely benefits you after accounting for the time you spend prompting, verifying, and correcting its output. It combines four sub-scores: Time (net time saved), Quantity (usable output volume), Quality (verified, durable improvement), and Skill (genuine lasting capability built). The overall score ranges from 0 to 10. A score of 5.8 (CI-First Positive) means the tool delivers clear net benefit when used with disciplined verification. For GPT 5.4, the Score is 5.8 with sub-scores of Time 7, Quantity 6, Quality 6, and Skill 4.
CI-First Profile
The CI-First Profile classifies how a tool collaborates with you. Five profiles exist: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration. GPT 5.4 is classified as Co-Creator and Thought Partner (level 1) because it collaborates on ideation, strategy, and analysis with visible reasoning traces that you can engage with and redirect.
Humics Protection Badge
The Humics Protection Badge evaluates whether a tool protects or erodes your human capabilities across three dimensions: Creativity, Critical Thinking, and Social Authenticity. Each dimension is rated as +1 (Protects), 0 (Neutral), or -1 (Erodes). The total ranges from -3 to +3. GPT 5.4 scores 0 across all three dimensions, earning the Humics-Neutral badge. The model neither actively protects nor erodes human capabilities: it produces generic professional text and can spark ideas, but sustained use may replace your own ideation process.
AI Imposture Risk
AI Imposture Risk assesses whether a tool creates illusions that mask a lack of real skill or time savings. Three traps are evaluated: Time Illusion (does the tool waste time on tasks a simpler approach handles faster), Quantity Illusion (does high output volume mask errors), and Skill Illusion (does expert-looking output mask the user's lack of understanding). GPT 5.4 has Medium risk across all three traps. The 140-second latency wastes time on simple tasks, verbose output can look thorough but contain errors, and the expert-looking analysis can mask the user's inability to reproduce it independently.
User Sentiment
User Sentiment summarizes what real users say about a tool across review platforms (G2, Trustpilot, Capterra, Product Hunt, Reddit) and adoption signals (API availability, benchmark rankings, community discussions). For GPT 5.4, the sentiment is Mixed: no consumer reviews exist (it is a developer-facing API model), but developer discussions on Reddit and forums praise reasoning quality and the 1.1M context window while complaining about latency and cost. This aligns with the CI-First evaluation: the model delivers strong value for complex tasks but wastes resources on simple ones.
Sources
GPT-5.4 Pro and Thinking are here! - OpenAI Developer Community
GPT-5.4 Deep Dive: Pricing, Context Limits, and Tool Search - OpenAI Community
GPT-5.4 for Agents: Computer Use, MCP Tool Calls, and Real Pricing - Umesh Malik
GPT-5.4 Thinking: How to Use OpenAI's Reasoning Model - QWE AI Academy
GPT-5.4 Guide: Features, Benchmarks and What's New - Learn Prompting
GPT-5.4 Deep Dive: Computer Use, 1M Context and AI Agents - YouTube (BitBiasedAI)
The Ultimate Guide to ChatGPT 5.4 and Mastering Prompt Engineering - YouTube



Comments