
Kimi K2.7 Code: Moonshot AI's Coding-Focused Open-Weight Model

Updated: Oct 16
Status: Active | Last tested: 2026-08-25 (Kimi K2.7 Code) | Re-check: trigger-based (max 6 months)
Active: the tool is current and recommended.


In this Tool Review
Tool Snapshot
Tagline: A coding-focused agentic model built upon Kimi K2.6, with substantial improvements on real-world long-horizon coding tasks and roughly 30% lower thinking-token usage.
Category: Large Language Model - Coding
Provider: Moonshot AI
Version tested: Kimi K2.7 Code (released June 12, 2026)
Parameters: 1T total, 32B activated per token (MoE)
Context window: 256K tokens (262,144)
License: Modified MIT (open weights)
Platforms: API, HuggingFace, Ollama, vLLM, SGLang, KTransformers
Primary use cases:
End-to-end software engineering across complex codebases
Agentic coding workflows with tool use and MCP integration
Code generation across 10+ programming languages
Recreating program behavior from compiled binaries and documentation
Long-horizon multi-day coding and debugging tasks
Pricing summary: Paid API - $0.95 per 1M input tokens, $4.00 per 1M output tokens (Kimi API). Open weights available for self-hosting at no cost.
Official links:
Website: https://www.kimi.com/code
HuggingFace: https://huggingface.co/moonshotai/Kimi-K2.7-Code
API Platform: https://platform.moonshot.ai
Discord: https://discord.gg/TYU2fdJykW
LLM specifications:
Context Window: 256K tokens
Effort/Thinking Levels: Forced thinking mode (always on, cannot be disabled)
Parameters: 1T total, 32B activated per token
Architecture: Mixture-of-Experts (MoE) with Multi-head Latent Attention (MLA), 384 experts, 8 selected per token, 1 shared expert, MoonViT vision encoder (400M params)
Available Platforms: API (Kimi Platform), Open Weights (HuggingFace), Local (Ollama), Self-hosted (vLLM, SGLang, KTransformers)
Model Variants: Coding-specialized variant of Kimi K2.6. Series also includes Kimi K2.6 (general) and Kimi K3 (flagship).
Quantization: Native INT4 (compressed-tensors format)
License: Modified MIT (open weights, non-commercial restrictions may apply)
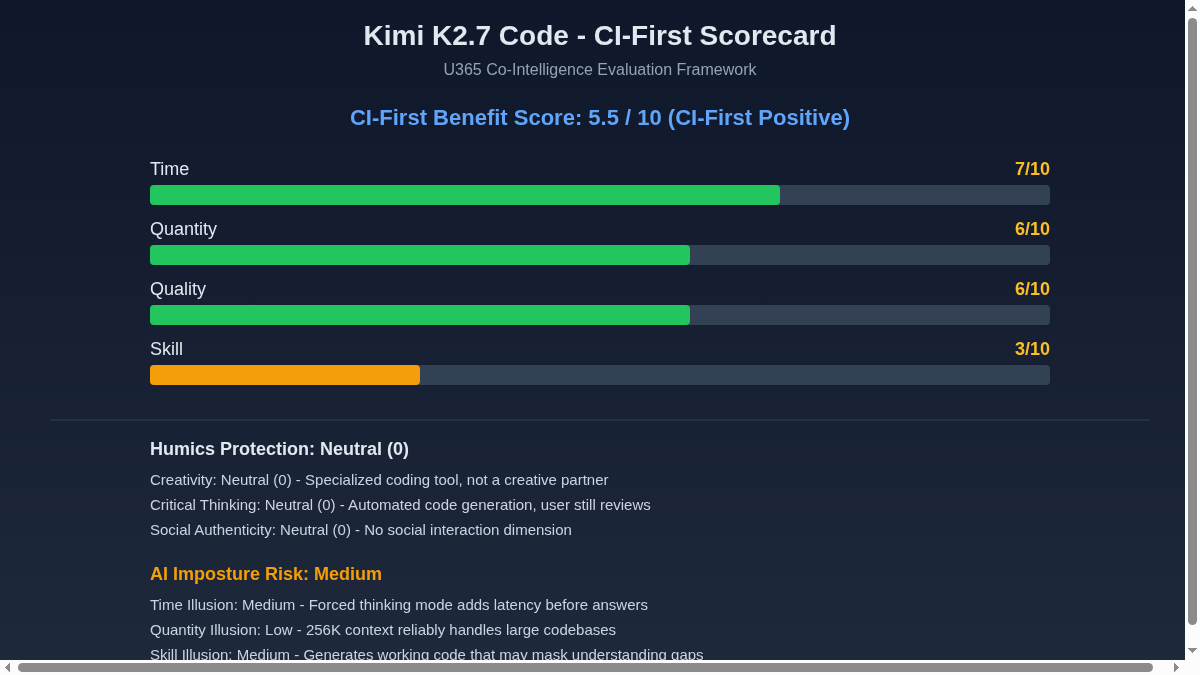
CI-First Benefit Score | 5.5/10 - CI-First Positive |
Time / Quantity / Quality / Skill | 7 / 6 / 6 / 3 |
CI-First Profile | Co-Worker and Assistant (2) / Analyst and Tester (4) |
Humics Protection | Humics-Neutral (0) |
AI Imposture Risk | Medium |
User Sentiment | 412,917 downloads, 1,370 likes (HuggingFace) |
Pricing | $0.95/1M in, $4.00/1M out (API). Open weights free. |
Platforms | API, HuggingFace, Ollama, vLLM, SGLang, KTransformers |
Intelligence Index | 43.0 (rank #12 of 107) |
For detailed explanations of the CI-First evaluation terms used in this review, including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
The Problem
Building and maintaining production software is slow and expensive. Developers spend significant time on repetitive coding tasks, debugging, and navigating large codebases. The gap between writing code and shipping working software is filled with trial and error, especially for long-horizon tasks that span multiple files, dependencies, and systems.
Existing coding assistants handle short snippets well but struggle with end-to-end tasks that require understanding an entire codebase, making multi-step decisions, and using external tools. When a coding task requires 20 steps across 5 files, most models lose track of the context or produce code that does not integrate.
Kimi K2.7 Code targets this gap. It is built specifically for agentic coding workflows where the model must plan, execute, verify, and iterate over long sessions. Moonshot AI designed it to maintain coherence across multi-day coding tasks and to use tools through the Model Context Protocol (MCP).
The Outcome
With Kimi K2.7 Code, a developer working on a complex software engineering task gets a model that can reason through the full task, write code across multiple files, run tests, and iterate based on results. The 256K token context window means you can load large codebases and documentation without chunking.
The model's forced thinking mode means it plans before acting, which reduces the number of wrong turns. Moonshot AI reports roughly 30% lower thinking-token usage compared to Kimi K2.6, which means faster responses and lower API costs for the same quality of work.
For U365 fellows and students in the UIT institute, the concrete outcome is: you can give the model a real software engineering task (not just a snippet request) and get a working implementation that you then review, test, and deploy. The model handles the heavy lifting of initial implementation, letting you focus on architecture decisions and verification.
Who Should Use Kimi K2.7 Code
Learner categories:
Fellow Category | Skill Level | What They Learn | U365 Program |
Students (Bachelor, Master) | Intermediate | Learn agentic coding patterns and how to structure complex coding tasks | UIT Software Developer and AI Developer Specialist |
Professionals (career upskilling) | Advanced | Accelerate production coding workflows with tool-integrated AI | UIT and UIC programs for professional development |
Everyone (lifelong learners) | Intermediate | Understand how coding agents work and when to trust them | General technology literacy |
U365 Institutes Alignment
Rating. High
Why. Directly relevant to software engineering, AI, and data science workflows. This is a primary tool for UIT fellows.
The limit that holds the row. The model writes implementations and runs agentic coding sessions; it teaches no engineering discipline of its own, and the review's own limits record that it is expensive against other open-weight models and below average on speed, so cost and latency judgement has to come from measured runs. The competencies that remain are the review of the generated implementation, the tests and the deployment decision. A word-start accent-folded search over the title and full description of all 79 published programme descriptions returns zero matches for code review, refactoring, version control, debugging and test design, so the row stands at High for measured engineering work under review and not for the generated code itself.
Rating. Low
Why. Relevant only for technical founders building prototypes. Most business users do not need a coding-specialized model.
The limit that holds the row. The model is a coding tool; it teaches no management, finance or entrepreneurship content, and the live reason confines it to technical founders building prototypes. The competency that remains is the product decision a founder owns: what to build, how to cost it, and when a prototype is ready for users. A word-start accent-folded search over the title and full description of all 79 published programme descriptions returns zero matches for procurement, total cost of ownership, unit economics, business case and market analysis, so the row stays at Low on its own measurement.
Rating. Low
Why. Web development tasks may benefit, but the model is overpowered for content work.
The limit that holds the row. The model writes code and web deliverables; it composes no register, no audience analysis and no editorial standard, and the live reason records that it is a mismatched instrument for content work. The competency that remains, if any, sits in web delivery rather than in communication craft, and the publication judgement around a coded surface stays with the Fellow. A word-start accent-folded search over the title and full description of all 79 published programme descriptions returns zero matches for editorial, disclosure, brand voice, tone and provenance, so the row stays at Low.
Rating. Medium
Why. Useful for design engineers who code interactive prototypes and need automated frontend implementation.
The limit that holds the row. The model generates implementation from a description; it produces no design decision, judges no layout and evaluates nothing against a brief. The competency that remains is the specification and the review of a coded prototype: what the interaction is meant to be, whether the generated front end matches it, and where a design engineer takes over. A word-start accent-folded search over the title and full description of all 79 published programme descriptions returns two documents each for interaction design and prototyping, and zero matches for design system, user research, critique and accessibility, so the row stands at Medium for the engineering side of design work and not for design authorship.
Skill level required: Intermediate to Advanced. You need programming knowledge to evaluate generated code and set up API access or local deployment.
Prerequisites: Basic programming in at least one language. Familiarity with API calls or command-line tools for deployment. Understanding of what a coding agent does versus a code completion tool.
Typical time to first result: 15 minutes (set up API key, send first coding prompt).
Typical time to competence: 2 to 4 weeks of regular use across different coding tasks.
How Kimi K2.7 Code Works
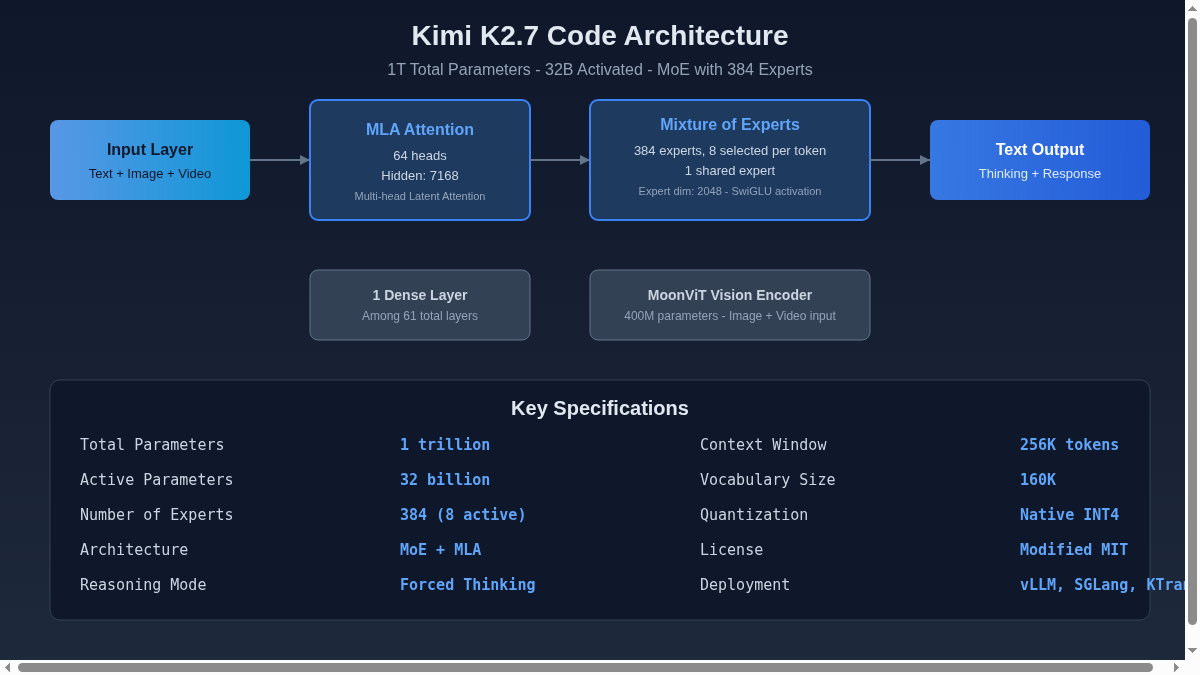
Kimi K2.7 Code is a Mixture-of-Experts (MoE) model with 1 trillion total parameters, of which 32 billion are activated per token during inference. This means each token is processed by only 8 of 384 available experts plus 1 shared expert, keeping inference efficient despite the large total parameter count.
The architecture uses Multi-head Latent Attention (MLA) with 64 attention heads and a hidden dimension of 7168. MLA compresses the key-value cache, reducing memory usage for long contexts. The model has 61 layers (1 dense, 60 MoE layers) and uses SwiGLU activation.
A MoonViT vision encoder (400M parameters) processes image and video input, making the model multimodal. You can share screenshots of UI designs, error messages, or documentation pages, and the model can reason about them alongside text.
The model ships with native INT4 quantization, which reduces memory requirements by roughly 75% compared to FP16 without significant quality loss. This makes self-hosting more practical on high-end GPU configurations.
Forced thinking mode is a defining feature. Unlike models where reasoning can be toggled on or off, Kimi K2.7 Code always thinks before answering. The preserve_thinking feature retains full reasoning content across multi-turn conversations, which helps the model maintain context in agentic coding sessions.
The model supports the Model Context Protocol (MCP) for tool use, meaning it can call external tools, search files, run commands, and interact with APIs during a coding session. This is what enables agentic workflows rather than simple code completion.
Deployment options: API access through platform.moonshot.ai (OpenAI-compatible and Anthropic-compatible endpoints), self-hosting with vLLM, SGLang, or KTransformers, and local deployment through Ollama.
Getting Started with Kimi K2.7 Code
Installation
Step 1: Get API access. Visit platform.moonshot.ai and create an account. Generate an API key. The API is OpenAI-compatible, so you can use the standard OpenAI Python SDK or any compatible client.
Step 2: Install the OpenAI Python package. Run: pip install openai. Set your API key as an environment variable: export MOONSHOT_API_KEY="your-key-here".
Step 3: Make your first API call. Create a Python script that initializes an OpenAI client with the Moonshot base URL (https://api.moonshot.ai/v1). Send a coding prompt and print the response. The model name is "kimi-k2.7-code".
Step 4: For local deployment via Ollama. Run: ollama pull kimi-k2.7-code. Then use: ollama run kimi-k2.7-code. Note that running a 1T parameter model locally requires significant hardware. The INT4 quantized version is recommended for local use.
Step 5: For self-hosting with vLLM or SGLang. Download the model weights from HuggingFace (moonshotai/Kimi-K2.7-Code). Follow the deployment guide in the model card. You need transformers version 4.57.1 or later (but below 5.0.0).
First 15 minutes checklist
API key generated, first API call returns a coding response, you understand that thinking mode is always on, you can parse the reasoning_content field in the API response, you know the pricing ($0.95/1M input, $4.00/1M output).
Real Workflows
Workflow 1: Building a REST API from a Specification
Learner type: UIT student or professional developer
CI-First benefit tags: Time: 7/10, Quality: 6/10
Connects to: UIT Bachelor in IT - Software Development track. U365 SUPERHUMAN program for professional developers.
Time estimate: 30 to 60 minutes (vs 3 to 5 hours manually)
Step | You do | Tool does |
1 | Write a clear specification document describing the REST API endpoints, data models, and business logic. Include the target framework (FastAPI, Express, etc.). | |
2 | Thinks through the architecture, then generates the complete project structure including route handlers, data models, validation, and error handling. | |
3 | Review the generated code for architectural decisions the model made. Check if the file structure matches your project conventions. Identify any missing edge cases. | |
4 | Writes integration tests for the API. Generates test cases based on the specification, including edge cases and error scenarios. | |
5 | Run the tests. Fix any failures by either correcting the generated code or asking the model to fix specific issues. Deploy to a staging environment. | |
6 | Generates API documentation from the code. Reads the implementation and produces OpenAPI documentation or markdown docs. |
Sample prompt:
I need to build a REST API for a task management application using FastAPI. Here are the requirements: 1) CRUD operations for tasks (title, description, status, due_date, priority). 2) User authentication with JWT tokens. 3) Task assignment to users. 4) Filtering and pagination for task lists. 5) PostgreSQL database with SQLAlchemy ORM. Please generate the complete project structure with all necessary files, including models, schemas, routes, authentication, and a basic test suite.
Verification checklist:
Multi-Model Check: Run the same specification through Claude or GPT-5.5 and compare the architecture decisions, code quality, and test coverage.
External Source: Run the generated tests against a real PostgreSQL database. Check if the API handles edge cases (empty payloads, invalid JWT, non-existent task IDs).
Human Review: Read every generated file. Verify the authentication implementation is secure. Check that the ORM models match the database schema you intend to use.
CI-First Test: Ask: did writing the specification myself and reviewing the output teach me something about API design, or did I just outsource the thinking? If you cannot explain the architecture decisions, you have created a dependency, not a capability.
Workflow 2: Debugging a Production Incident with MCP Tool Use
Learner type: Professional developer or UIT fellow
CI-First benefit tags: Time: 8/10, Quantity: 7/10, Quality: 6/10
Connects to: UIT programs in DevOps and Site Reliability. U365 SUPERHUMAN program for senior developers.
Time estimate: 20 to 45 minutes (vs 2 to 4 hours manually)
Step | You do | Tool does |
1 | Reproduce the production incident locally or in a staging environment. Collect error logs, stack traces, and relevant configuration files. | |
2 | Uses forced thinking mode to analyze the error, form hypotheses, and propose a debugging plan. | |
3 | Using MCP tool integration, searches log files, queries the database for recent changes, and inspects configuration files to narrow down the root cause. | |
4 | Review the model's analysis. Verify its hypotheses by checking the actual system state. The model may suggest checking specific files, database records, or environment variables. | |
5 | Writes a fix for the identified root cause. Generates the code change and an explanation of why the fix addresses the root cause. | |
6 | Apply the fix in a branch, run the test suite, and deploy to staging. If the fix works, deploy to production. If not, feed the new error information back to the model for the next iteration. | |
7 | Writes a postmortem document summarizing the incident, root cause, fix, and preventive measures. |
Sample prompt:
Our production API started returning 500 errors at 14:30 UTC. Here are the error logs from the last 30 minutes: [paste logs]. The service is a Python FastAPI application using PostgreSQL and Redis. No deployments happened in the last 4 hours. The last database migration was 2 days ago. Please analyze the error, identify the likely root cause, and propose a debugging plan. Use the available tools to check log files and configuration.
Verification checklist:
Multi-Model Check: Share the same error logs with another coding model (Claude Opus, GPT-5.5) and compare the root cause analysis. Different models may identify different causes.
External Source: Check the actual system metrics (CPU, memory, database connections, error rates) against the model's hypotheses. Do not apply a fix based on the model's analysis alone.
Human Review: The developer who knows the system best must validate the root cause. The model does not have context about recent changes, known issues, or system-specific quirks.
CI-First Test: Ask: after this debugging session, can I diagnose a similar incident faster next time without the model? If not, I have learned to depend on the tool rather than developing debugging skills. Write down the debugging steps the model used so you can apply them yourself next time.
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Strengths (what the model genuinely delivers):
Dimension | Score | Evidence |
Time | 7/10 | The model reduces time on implementation tasks significantly. The 30% reduction in thinking tokens compared to K2.6 means faster responses. However, forced thinking mode adds latency (45 seconds average time to first token) that offsets some gains for simple tasks. |
Quantity | 6/10 | The model generates complete project structures and multi-file implementations. The 256K context window handles large codebases. However, the output volume still requires human review and correction. |
Quality | 6/10 | On Moonshot AI's internal benchmarks (Kimi Code Bench v2), K2.7 Code scores 62.0, up from K2.6's 50.9. On independent benchmarks (Artificial Analysis Intelligence Index), it scores 43.0, which is above average for open-weight models of similar size but well below frontier models like Claude Opus 5 (63.1) or GPT-5.6 Sol (60.9). |
Skill | 3/10 | The model generates working code, but using it does not build lasting coding skills. Developers who rely on it for implementation without understanding the output will develop dependency, not capability. The forced thinking mode helps because the model's reasoning is visible, but the user must actively study it. |
Limits
Limits:
The model is expensive relative to other open-weight models. At $0.95/1M input and $4.00/1M output, it costs more than DeepSeek V4 Pro ($0.14/1M input, $0.28/1M output) or GPT-5.6 Luna ($0.20/1M input, $0.80/1M output).
Speed is below average. At 49.5 tokens per second, it is slower than most competitors (median 68.2 t/s for similar models).
The AA-Omniscience Index does not list Kimi K2.7 Code, suggesting knowledge reliability data is not yet available independently.
The model forces thinking mode. You cannot disable it for simple tasks where reasoning is unnecessary, which adds latency and cost.
Chat with video content is experimental and only available through the official API, not through third-party deployments.
AI Imposture Risk
AI Imposture Risk:
Time Illusion
Level. Medium
Evidence. The forced thinking mode means the model spends 45 seconds on average thinking before responding. For complex tasks this is justified. For simple tasks (write a function, fix a typo), the thinking time is wasted and creates an illusion of thoroughness when a quick answer would suffice. Artificial Analysis reports 45.05 seconds average reasoning time before first token, compared to 0 seconds for non-reasoning models like Grok 4.6.
Quantity Illusion
Level. Low
Evidence. The 256K context window is real and handles large codebases. The model generates complete implementations, not just snippets. Output volume is verified and usable. HuggingFace reports 412,917 downloads and 1,370 likes, indicating real adoption and testing by the community.
Skill Illusion
Level. Medium
Evidence. The model generates working code that may run correctly, but the developer who deploys it without understanding may face issues when the code needs modification or debugging. The visible thinking process mitigates this because the developer can study the model's reasoning, but only if they choose to. The model scores 43.0 on the Intelligence Index, well below frontier models. Generated code for novel or complex problems will have errors that require human review.
U365 Co-Intelligence Rating
CI-First Profile
Primary: Co-Worker and Assistant (2). The model functions as a coding assistant that handles implementation tasks. Secondary: Analyst and Tester (4). The forced thinking mode and MCP tool use make it effective for analysis and debugging.
CI-First Benefit Score
Time: 7/10. Significant time savings on implementation, offset by thinking latency for simple tasks. Quantity: 6/10. Complete multi-file output, but requires review and correction. Quality: 6/10. Above average for open-weight models, below frontier models. Benchmark scores (43.0 Intelligence Index, 62.0 Kimi Code Bench v2) show real but not exceptional quality. Skill: 3/10. The model generates code but does not teach coding. Users who rely on it without studying the output develop dependency. Overall: (7 + 6 + 6 + 3) / 4 = 5.5/10. CI-First Positive.
Humics Protection Badge
Creativity: 0 (Neutral). The model is a specialized coding tool, not a creative partner. It does not erode or protect creative thinking in coding because it handles implementation, not design. Critical Thinking: 0 (Neutral). The forced thinking mode makes the model's reasoning visible, which can support critical thinking if the user studies it. But the model also does the thinking for you, which can erode it if you let it. Social Authenticity: 0 (Neutral). No social interaction dimension. Coding is an individual or small-team activity. Score: 0. Humics-Neutral.
AI Imposture Risk Assessment
Time Illusion: Medium. 45 seconds thinking time for simple tasks creates an illusion of depth. Quantity Illusion: Low. Output volume is real and verified by community adoption. Skill Illusion: Medium. Working code may mask understanding gaps. Overall: Medium.
Superhuman Usage Guidance
When to invite the tool: complex multi-file implementation tasks, debugging production incidents with log analysis, generating test suites from specifications, building project scaffolding from requirements, any task where the model's 256K context and MCP tool use provide genuine value.
When to keep the tool out: simple code snippets where thinking latency is wasted, architectural decisions that require domain knowledge the model lacks, security-critical code where you must understand every line, learning exercises where the goal is to build the skill yourself.
U365 method integration: Use within LIPS+CARE for coding tasks that require documentation and verification. In ULM+EVA, the model's forced thinking mode can serve as an evaluation tool: compare your own thinking process with the model's. In UP-Context-Engineering, use it for tasks where context depth (256K tokens) provides an advantage.
Over-delegation warning: Kimi K2.7 Code generates code that often works on the first try. This is seductive. If you deploy generated code without understanding it, you create technical debt you cannot pay back. Always read every line. If you cannot explain why the code works, do not deploy it. The model's thinking output is your learning material: study it, do not skip it.
What Users Say
Aggregate Rating Table
Adoption signals (model-level, not company-level reviews):
Platform | Signal | Count or result | Interpretation |
HuggingFace | Downloads | 412,917 | Strong community adoption for a coding-specialized model |
HuggingFace | Likes | 1,370 | High community approval rating |
HuggingFace | Last modified | June 15, 2026 | Recently updated, actively maintained |
Ollama | Availability | Available (kimi-k2.7-code) | Official Ollama library listing, not just community upload |
Artificial Analysis | Intelligence Index | 43.0 (rank #12 of 107) | Above average for open-weight models, below frontier |
Artificial Analysis | Speed | 49.5 t/s (rank #46 of 107) | Below average speed for similar models |
Artificial Analysis | Cost | $0.22 per task (rank #22 of 107) | Moderate cost, cheaper than frontier models but expensive for open-weight |
Trustpilot | No reviews found | - | No model-specific reviews on Trustpilot |
G2 | No reviews found | - | No model-specific reviews on G2 |
Capterra | No reviews found | - | No model-specific reviews on Capterra |
Product Hunt | No reviews found | - | No model-specific listing on Product Hunt |
Not accessible via API | - | No Reddit sentiment reported |
What Users Praise
The model's ability to handle long-horizon coding tasks without losing context. The 256K context window is frequently mentioned as a practical advantage. The open-weight license with INT4 quantization makes self-hosting feasible for organizations with GPU infrastructure. The MoonViT vision encoder is noted as useful for UI-to-code workflows.
What Users Complain About
The forced thinking mode cannot be disabled, which adds latency for simple tasks. The pricing is higher than competing open-weight models. Speed (49.5 t/s) is below average. The model is not competitive with frontier models like Claude Opus 5 or GPT-5.6 Sol on overall intelligence benchmarks.
Sentiment Summary
User adoption signals (412K downloads, 1,370 likes) indicate genuine community interest, which aligns with the CI-First Positive rating (5.5/10). However, the model's position in the benchmark rankings (#12 of 107 on Intelligence Index) and its below-average speed suggest it is a strong specialist tool, not a general-purpose leader.
U365 Editorial Note
User adoption signals (412K downloads, 1,370 likes) indicate genuine community interest, which aligns with the CI-First Positive rating (5.5/10). However, the model's position in the benchmark rankings (#12 of 107 on Intelligence Index) and its below-average speed suggest it is a strong specialist tool, not a general-purpose leader. The adoption is driven by the coding specialization and open-weight availability, not by raw intelligence. Users who need the best possible coding model may still prefer Claude Opus 5 or GPT-5.5. Users who need open weights and local deployment will find Kimi K2.7 Code compelling. The gap between community enthusiasm (high downloads) and benchmark performance (mid-tier intelligence) is the key tension in this evaluation.
Comparison and Alternatives
Comparison with Alternatives
Comparison with alternatives:
Model | Context | Intelligence Index | Speed (t/s) | Cost per 1M tokens | Open Weights |
Kimi K2.7 Code | 256K | 43.0 | 49.5 | $0.95 in / $4.00 out | Yes (Modified MIT) |
Claude Opus 5 (max) | 1M | 63.1 | 58.8 | $15.00 in / $75.00 out | No |
GPT-5.6 Sol (max) | 400K | 60.9 | 74.4 | $2.00 in / $8.00 out | No |
DeepSeek V4 Pro 0813 | 128K | 53.2 | 73.9 | $0.14 in / $0.28 out | Yes (MIT) |
Kimi K2.6 | 256K | 45.1 | 49.5 | $0.95 in / $4.00 out | Yes (Modified MIT) |
Where Kimi K2.7 Code is clearly better
Open-weight availability with coding specialization, native INT4 quantization for practical self-hosting, MCP tool integration for agentic workflows, multimodal input (text, image, video) in an open-weight model.
Where Kimi K2.7 Code is clearly worse
Overall intelligence (43.0 vs 63.1 for Claude Opus 5), speed (49.5 vs 371.0 for Gemini 3.7 Flash), cost efficiency ($0.22 per task vs $0.047 for GPT-5.6 Luna), benchmark coverage (fewer independent benchmarks than frontier models).
Choose Kimi K2.7 Code if: you need an open-weight coding-specialized model with large context, you want local deployment with INT4 quantization, your tasks are agentic coding workflows with tool use, you are already using Kimi products.
Choose Claude Opus 5 if: you need the highest intelligence available, cost is not a constraint, you need 1M context window, you want the best general-purpose reasoning model.
Choose GPT-5.6 Sol if: you want a balance of high intelligence and reasonable cost, you need reliable API access with high uptime, you are in the OpenAI developer platform.
Choose DeepSeek V4 Pro if: cost is your primary concern, you need open weights with permissive licensing, you want the best price-to-performance ratio among open-weight models.
Verdict and Next Steps
Who should adopt: UIT fellows and students who want to understand how agentic coding models work. Professional developers who need an open-weight coding model for self-hosting or data-sensitive environments. Teams already using Kimi products (K2.6 or K3).
When to adopt: Now, if you have a specific need for open-weight coding models with tool use. Wait, if you are evaluating general-purpose LLMs and do not specifically need the coding specialization or open weights.
For what: End-to-end implementation tasks from specifications, debugging with log analysis, test suite generation, agentic coding workflows with MCP tools.
UP-Context-Engineering prompt pack:
Prompt 1 (Architecture review): Context: I have a project structure and I want the architectural issues found before they are built into more code. Role: AI as an Analyst and Tester (Profile 4) reviewing the structure I paste. I own the refactor decision; you identify and explain. Profile: Act as an Analyst and Tester, finding issues and explaining why each is a problem rather than rewriting the code. Task: review this project structure and identify the architectural issues, focused on separation of concerns, error handling patterns and test coverage. Constraints: do not rewrite the code, give the reason behind each issue rather than a preference, and name the part of the structure each issue touches. Output format: the issues, each with its location and the reason it matters. Memory: the review and the refactor decisions I take belong in my own project record, because the structure will outlive the conversation. UP-Context-Engineering verification: I open the relevant files and confirm each issue myself before scheduling any change, I rank the issues by my own risk view, and I can explain each accepted finding without the tool. Data safety: this pack carries no personal data. I do not paste proprietary source, a production credential or an unannounced architecture plan into it, and I keep the review in my own store.
Prompt 2 (Debugging assistant): Context: I have error logs from a production incident and I need the cause identified before anything is changed. Role: AI as an Analyst and Tester (Profile 4) reasoning over the evidence I supply. I own the incident decision; you propose hypotheses and the evidence each needs. Profile: Act as an Analyst and Tester, separating a hypothesis from a proven cause rather than jumping to a fix. Task: think through the possible root causes systematically, and for each hypothesis tell me what evidence would confirm or rule it out. Constraints: do not propose a fix until the root cause is identified with evidence, rank the hypotheses by how well the logs support them, and name the log line behind each hypothesis. Output format: the ranked hypotheses, each with the evidence for and against it, then the next check. Memory: the incident record, the hypothesis I confirmed and the fix belong in my own operations record, because the incident will be reviewed afterwards. UP-Context-Engineering verification: I gather the evidence myself before any change is made, I confirm the root cause against the logs rather than adopting the first plausible story, and I can explain the causal chain without the tool. Data safety: this pack carries no personal data. I do not paste production logs carrying customer identifiers, a credential or an unreleased incident report into it, and I keep the incident record in my own store.
Prompt 3 (Code review for learning): Context: I wrote this code and I want to improve it as a developer rather than receive a corrected copy. Role: AI as a Professor, Coach and Tutor (Profile 3) reviewing my code as a learning exercise. I own the code and every change to it. Profile: Act as a Professor, Coach and Tutor, explaining the principle behind each suggestion so I can apply it elsewhere. Task: review this code and explain what I could improve, focused on readability, error handling and performance, and for each suggestion explain the principle behind it. Constraints: do not rewrite the code, give me actionable feedback I can implement myself, and keep each point to one principle. Output format: the suggestions, each with its principle and the line range it touches. Memory: my revised code and the principles I applied belong in my own learning record, because the skill is the point of the exercise. UP-Context-Engineering verification: I implement each accepted suggestion myself, I check the revised code still passes its tests, and I can explain each principle a day later without the tool. Data safety: this pack carries no personal data. I do not paste proprietary source, a colleague's unpublished code or a credential into it, and I keep my practice record in my own store.
Related U365 content: INSIDE Tools posts on Claude Opus 5, GPT-5.6 Sol, DeepSeek V4 Pro, and GLM-5.3 for comparison. UIT curriculum modules on software engineering and AI-assisted development.
U365's Recommendations to Learn More
The following resources were curated and verified as of 2026-09-03. They complement this review with hands-on tutorials, official documentation, and community perspectives that go beyond what this post covers.
Official learning resources
Video tutorials and channels
Written tutorials and deep-dive articles
Community and social
These resources were selected for their content quality and relevance. Individual creators and community experts are included alongside official documentation to give you the most complete learning path. Every link was verified active as of 2026-09-03.
Glossary
CI-First Benefit Score
A composite metric that evaluates how much genuine, durable benefit a user gains from working with an AI tool, measured across four dimensions: Time saved, Quantity of usable output, Quality improvement, and Skill development. Each dimension is scored 0-10 and averaged. For Kimi K2.7 Code, the overall score is 5.5/10 (CI-First Positive), meaning the tool provides real but not transformative value. The tool saves time on implementation and produces reasonable output volume, but the skill dimension (3/10) is low because using the model does not inherently build lasting coding capability.
CI-First Profile
A classification of how an AI tool fits into human work, drawn from five profiles: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Professor, Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration: level 1 tools act as creative equals, while level 5 tools push back and challenge your thinking. Kimi K2.7 Code is classified as Co-Worker and Assistant (primary, level 2) because it handles implementation tasks, and Analyst and Tester (secondary, level 4) because its forced thinking mode and MCP tool use make it effective for debugging and analysis. This profile tells you what role the tool plays in your workflow, not how good it is.
Humics Protection Badge
A rating that assesses whether an AI tool protects or erodes three distinctly human capabilities: Creativity, Critical Thinking, and Social Authenticity. Each dimension is scored +1 (protects), 0 (neutral), or -1 (erodes), for a total range of -3 to +3. Kimi K2.7 Code scores 0 (Humics-Neutral) across all three dimensions. As a specialized coding tool, it neither erodes nor protects creative thinking, critical thinking, or social authenticity. The forced thinking mode could support critical thinking if the user studies the reasoning, but the tool does not enforce this.
AI Imposture Risk
An assessment of whether an AI tool creates illusions that mask real limitations, evaluated across three dimensions: Time Illusion (does the tool create an illusion of time savings that evaporate on closer inspection), Quantity Illusion (does the output volume mask quality issues), and Skill Illusion (does using the tool create a false sense of competence). Kimi K2.7 Code has Medium overall risk: Time Illusion is Medium (45 seconds of thinking for simple tasks creates an illusion of depth), Quantity Illusion is Low (output volume is real and verified), and Skill Illusion is Medium (working code may mask understanding gaps).
User Sentiment
Aggregated signals from community platforms that indicate how real users perceive and adopt an AI tool. For Kimi K2.7 Code, the primary signals come from HuggingFace (412,917 downloads, 1,370 likes), Ollama (official library listing), and Artificial Analysis (Intelligence Index 43.0, rank #12 of 107). No reviews were found on Trustpilot, G2, Capterra, or Product Hunt, which is expected for an open-weight model rather than a commercial product. The sentiment indicates genuine community interest driven by coding specialization and open-weight availability, not by raw intelligence leadership.



Comments