
Llama 4 Scout: A 10M-Token Multimodal Open-Weight Model

Updated: 6 days ago
Status: Active | Last tested: 2026-08-24 (Llama-4-Scout-17B-16E-Instruct) | Re-check: trigger-based (max 6 months)
TOC_PLACEHOLDER

Tool Snapshot
Tagline: Meta's 17B-active Mixture of Experts model for long-context text and image work.
Category: Large Language Model
Provider: Meta
Version tested: Llama-4-Scout-17B-16E-Instruct
Parameters: 109B total, 17B active per token, 16 experts
Context window: 10,000,000 tokens
License: Llama 4 Community License (commercial use up to 700M MAU)
Platforms: Open weights, Hugging Face, Ollama, hosted providers
Primary use cases:
Review very large document collections within one context window
Analyze text and images in the same request
Build private or controlled deployments with open weights
Create source-bound summaries, comparisons, and extraction tables
Prototype multimodal assistants with local or hosted inference
Pricing summary: The model weights do not carry a per-token list price. Download and use are subject to the Llama 4 Community License. Hosted inference is available through providers such as Together AI, Groq, and OpenRouter, each with its own pricing.
Official links:
Meta announcement: https://ai.meta.com/blog/llama-4-multimodal-intelligence/
Official model card: https://huggingface.co/meta-llama/Llama-4-Scout-17B-16E-Instruct
Llama documentation: https://www.llama.com/docs/model-cards-and-prompt-formats/llama4/
Llama downloads: https://www.llama.com/llama-downloads/
Ollama library: https://ollama.com/library/llama4:scout
Acceptable use policy: https://www.llama.com/llama4/use-policy/
LLM specifications:
Release Date: 2025-04-05
Context Window: 10,000,000 tokens
Parameters: 109B total, 17B active per token, 16 experts
Architecture: Decoder-only Mixture of Experts with native multimodal early fusion and iRoPE positional encoding
Modalities: Text and image input, text output
Effort Levels: No separate low, medium, or high thinking controls are documented
Available Platforms: Downloadable open weights, hosted inference providers, Hugging Face, Ollama
Model Variant: Llama-4-Scout-17B-16E-Instruct
License: Llama 4 Community License, subject to eligibility, attribution, and acceptable use terms
Local Deployment Note: Meta describes Int4 deployment on one NVIDIA H100 GPU. Other quantization paths exist through Ollama and community builds.
Comparison References: Use the official model card for specifications, Ollama for local packaging, and the Meta announcement for benchmarks.
CI-First Benefit Score | 5.5/10 - CI-First Positive |
Time / Quantity / Quality / Skill | |
6 / 7 / 5 / 4 | |
CI-First Profile | Co-Worker and Assistant |
Humics Protection | Humics-Neutral (-1) |
AI Imposture Risk | Medium |
User Sentiment | Insufficient model-specific review data |
Pricing | Open weights (Llama 4 Community License) |
Platforms | Open weights, Hugging Face, Ollama, hosted providers |
Context Window | 10M tokens |
For detailed explanations of the CI-First evaluation terms used in this review, including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
The Problem
Long research packs, policy archives, code repositories, and mixed text-image collections often exceed the context limits of most open-weight models. Splitting documents across calls introduces boundary errors, loses cross-references, and increases the time spent on preparation and checking.
Llama 4 Scout addresses this problem with a 10M-token context window and native multimodal early fusion. It is designed to hold very large evidence sets and process text and images in a single model call.
The long context does not guarantee reliable recall, citation accuracy, or sound reasoning across the entire window. The model still requires source-bound methods, verification, and human review.
The Outcome
You can place a much larger evidence set into one working context and ask Scout to extract, compare, and summarize with explicit source references. The 10M-token window reduces manual splitting for tasks that fit the effective context.
A strong result is a source-bound work product, such as an evidence table that preserves source IDs, page references, and uncertainty labels. The model supports both text and image inputs, which broadens the range of document types you can process in one pass.
The model offers the most value when you measure net time saved after preparation, verification, and correction. Large inputs reduce splitting but increase upload, inference, and checking time.
Who Should Use Llama 4 Scout
Learner type | Difficulty | Typical return | Career path |
Students | Intermediate | Large reading-pack comparison, visual document analysis, and source-bound extraction practice | UIT technical programs and research practice in other institutes |
Professionals | Intermediate to advanced | Controlled long-context review, internal knowledge processing, and multimodal document workflows | UIT AI and data work, UIB operational analysis, UIC content workflows, and UID design evaluation |
Everyone | Intermediate | Personal archive summaries and study support | Lifelong learning through LIPS and CI-First practice |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Model deployment, evaluation, coding, and multimodal AI systems work |
UIB (Business Management, Entrepreneurship) | Medium | Document-heavy analysis and operational intelligence from long evidence sets |
UIC (Digital Communication, Marketing) | Medium | Source-bound communication and visual content analysis workflows |
UID (Digital Design, UX/UI) | Medium | Design critique and mixed image-text research support |
Skill level required: Intermediate for hosted or Ollama use. Advanced for production self-hosting with quantization and memory management.
Prerequisites: Basic prompt design, source evaluation, output checking, and understanding of model limitations for long-context tasks.
Time to first result: About 15 to 30 minutes through an available hosted route or Ollama package.
Time to competence: Several weeks of repeated use with a fixed evaluation set and consistent verification practice.
How Llama 4 Scout Works
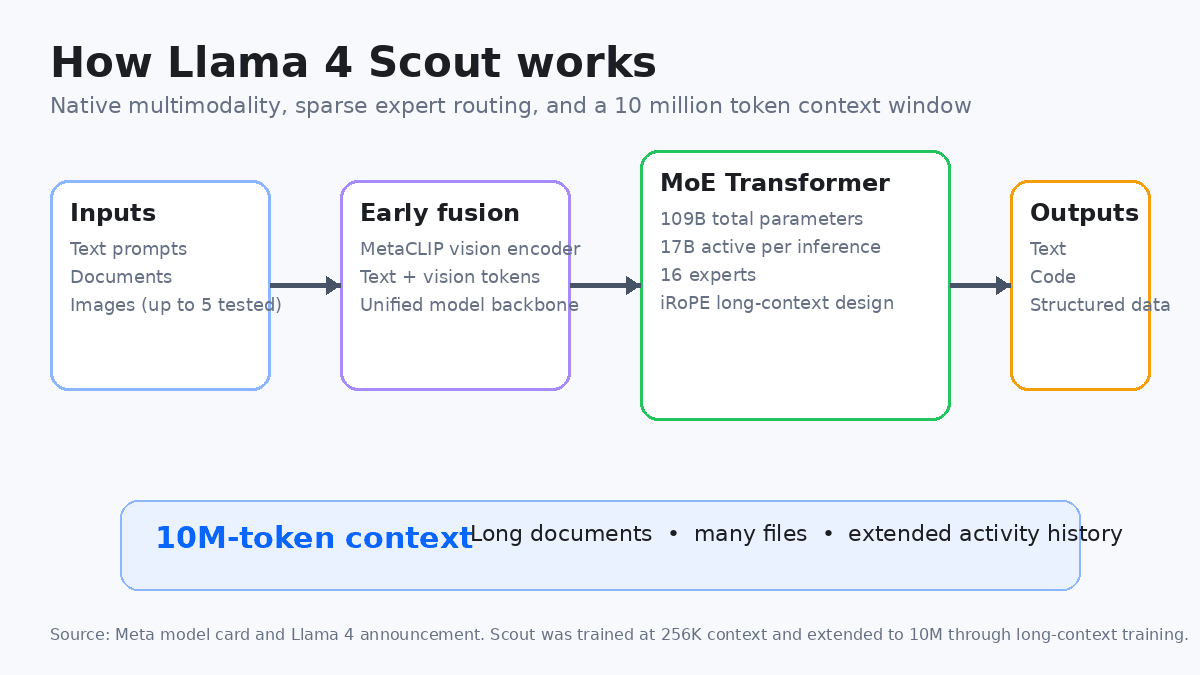
Inputs | Text prompts, long documents, code, tables represented as text, and images |
Outputs | Text responses, structured extraction, summaries, comparisons, and code |
Architecture | Scout is a decoder-only Mixture of Experts model. It has 16 experts with 17B active parameters per forward pass out of 109B total. Only 2 experts activate per token. |
Native multimodality | Meta trained text and vision through early fusion rather than bolting on a separate vision encoder. The model processes text and images through the same MoE routing. |
Long context | The published context window is 10M tokens. iRoPE combines positional encoding with inference-time temperature scaling. Effective recall may vary with input length and task type. |
Availability | The official weights are available under the Llama 4 Community License through Meta, Hugging Face, and Ollama. Hosted inference is available through several providers. |
Benchmarks | Meta reports benchmark results in its announcement and model card. Independent testing is recommended for specific use cases. |
Getting Started with Llama 4 Scout
Required access | Accept the Llama 4 Community License for official downloads, or create an account with a hosted provider that offers Llama 4 Scout. Ollama provides a local packaging route for supported systems.
Installation paths
1. Hosted route: select a provider that documents Llama 4 Scout, its 10M context support, and pricing. Verify the model identifier before sending production traffic.
2. Official weights: request access through Meta or Hugging Face, read the license terms, and download the checkpoint. Confirm the model variant and precision before deployment.
3. Ollama route: confirm the package name, quantization, download size, memory requirements, and context settings. Run a short test before longer sessions.
4. Production route: add authentication, access control, logging, rate limits, prompt templates, and monitoring before exposing the model to end users.
First 15 minutes checklist
☐ Confirm that the endpoint or package identifies Llama 4 Scout 17B 16E Instruct specifically.
☐ Read the license and data handling terms that apply to your route.
☐ Send a short text prompt with a required output format.
☐ Send one image and ask for a factual description with uncertainty labels.
☐ Test one source-bound extraction and compare it with the original source.
☐ Record model identifier, runtime, quantization, context setting, latency, and errors.
Result | You have one verified text result, one verified image result, and a deployment route that you can repeat with confidence.
Real Workflows
Workflow 1: Review a Large Academic Evidence Pack
Learner type: Graduate student, researcher, policy analyst, or consultant
CI-First benefit tags: Time, Quantity, Quality
Connects to: LIPS Digital Second Brain, CARE review practice, and research work across UIT, UIB, UIC, or UID
Time estimate: 60 to 120 minutes, including source checks
Step 1 | You define the question, inclusion rules, source hierarchy, and output format. | Scout waits for the source plan. |
Step 2 | You label every file with a source ID, title, author, date, and page range. | Scout receives the labeled evidence pack. |
Step 3 | You request extraction before synthesis. | Scout creates a table with claim, source ID, exact location, and confidence. |
Step 4 | You select the highest-impact claims and conflicts. | Scout proposes alternative interpretations and marks missing evidence. |
Step 5 | You open the original files and check every high-impact entry. | Scout revises the table using your corrections. |
Step 6 | You write or approve the conclusion. | Scout formats the verified evidence and lists unresolved questions. |
Sample prompt:
Profile: Act as an Analyst and Tester. Context: I am reviewing a labeled academic evidence pack. Task: Extract claims with source IDs and page references. Do not synthesize until extraction is complete. Output format: Table with columns for claim, source ID, location, and confidence. Constraint: Flag any claim that lacks a direct source reference.
Verification checklist:
☐ Multi-Model Check: Give the five highest-impact claims to a second model from a different family and compare the results.
☐ External Source: Open each original source and verify quotations, dates, authors, and page references.
☐ Human Review: A subject specialist reviews the evidence rules, important claims, and unresolved conflicts.
☐ CI-First Test: Explain and defend every retained claim without Scout, including the correction process.
Workflow 2: Test a Multimodal Document Intake Process
Learner type: UIT learner, developer, records specialist, or operations professional
CI-First benefit tags: Time, Quality, Skill
Connects to: UIT AI systems practice, LIPS Collect and Review steps, and U.Copilot technical orchestration.
Time estimate: 90 to 180 minutes, including test design and human review
Step 1 | You select 20 representative pages with text, charts, screenshots, and mixed layouts. | Scout does nothing until the test set is fixed. |
Step 2 | You define required fields, allowed uncertainty labels, and output rules. | Scout receives the schema and output rules. |
Step 3 | You send each page with its source ID. | Scout extracts fields, describes relevant visual evidence, and assigns confidence labels. |
Step 4 | You compare output with the known answers and record false positives and false negatives. | Scout receives only the correction notes, not the answer key. |
Step 5 | You revise the prompt once and repeat the test on a held-out set. | Scout processes the held-out pages under the fixed prompt. |
Step 6 | You approve or reject deployment based on measured accuracy and error patterns. | Scout produces a test summary without making the release decision. |
Sample prompt:
Profile: Act as a Co-Worker and Assistant under strict extraction rules. Context: Each supplied image is a document page. Task: Extract the specified fields, describe relevant visual evidence, and assign a confidence label. Do not infer missing data. Output format: JSON with field, value, confidence, and evidence reference. Constraint: Mark every uncertain field as UNKNOWN rather than guessing.
Verification checklist:
☐ Multi-Model Check: Run the held-out pages through a second multimodal model and compare field-level accuracy.
☐ External Source: Compare every extracted field with the original document or a trusted reference.
☐ Human Review: A records or domain specialist checks errors, privacy handling, and edge cases.
☐ CI-First Test: Reproduce the scoring method, explain the main failure modes, and propose a mitigation plan.
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence | Practical value |
Time | One context can hold a very large evidence set | Published 10M-token context window | Less manual splitting for suitable tasks |
Quantity | Mixed text and images can be processed in one model | Native multimodal early fusion with MetaCLIP | More source types in one workflow |
Quality | Source-bound review can preserve wider context | Large capacity reduces some chunk-boundary problems | Better comparisons when evidence checks pass |
Skill | Open weights support inspection and deployment practice | Community license and multiple inference routes | Useful for advanced UIT evaluation and operations work |
Limits
The 10M-token capacity does not prove uniform recall or reliable citation across the entire window.
A 109B-parameter model remains expensive to host even though only 17B parameters activate per token.
Provider implementations may expose smaller practical context limits or different quantization paths.
The Llama 4 Community License carries conditions and does not use an OSI-approved open source license.
Vendor benchmarks do not replace independent task testing.
Generated analysis can contain unsupported claims, missed evidence, coding defects, or hallucinated references.
Data governance depends on the selected runtime and provider, not on the model name alone.
AI Imposture Risk
Time illusion | Medium | Large inputs reduce splitting but increase upload, inference, and verification time. |
Quantity illusion | Medium | A broad summary can appear complete while missing evidence across the long context. |
Skill illusion | High | Technical output may exceed the user's ability to evaluate its accuracy independently. |
Overall | Medium | Use source IDs, held-out tests, measurable thresholds, and quality checks on every output. |
U365 Co-Intelligence Rating
CI-First Profile
Primary | Co-Worker and Assistant. Scout processes large and multimodal evidence sets, extracts claims, and prepares structured outputs for human review. |
Secondary | Analyst and Tester. It can compare sources, identify conflicts, and flag missing evidence when prompted with explicit rules. |
Collaboration Mode
Recommended | Centaur. Define a firm boundary between model processing and human judgment. |
Alternative | Cyborg only for low-risk prototypes when the user can catch errors in real time. |
Rationale | Long, convincing outputs make rapid acceptance unsafe. A staged review process protects against quantity and skill illusions. |
CI-First Benefit Score
Dimension | Score | Reason |
Time | 6/10 | The long context can reduce document splitting, but setup and verification add time. |
Quantity | 7/10 | The model can process unusually large mixed evidence sets and produce structured outputs. |
Quality | 5/10 | Wider context can improve source comparison, but quality depends on verification and prompt design. |
Skill | 4/10 | Open weights support technical learning, yet routine use can build dependency rather than capability. |
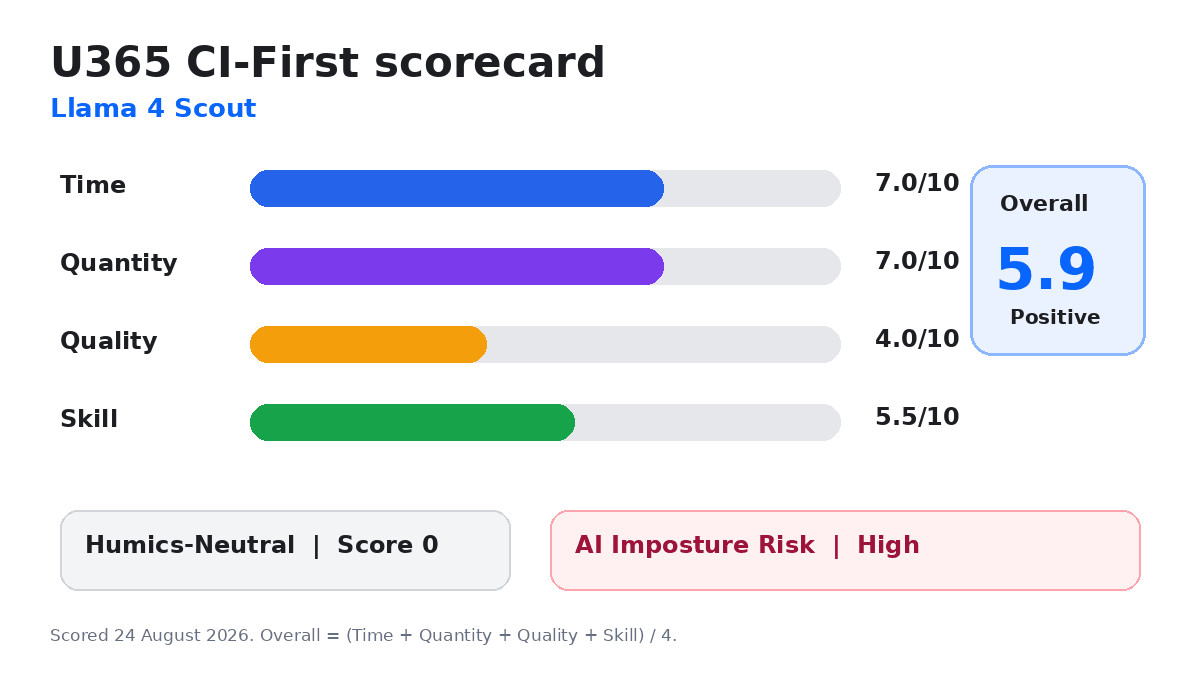
Overall | 5.5/10 | CI-First Positive. Calculation: (6 + 7 + 5 + 4) / 4 = 5.5. |
Humics Protection
Creativity | 0 | Scout can provide options, but it does not guarantee stronger creative choices. |
Critical Thinking | -1 | Large, fluent answers can discourage direct source reading without disciplined prompting. |
Social Authenticity | 0 | The model has no necessary effect on human relationships unless used to mediate them. |
Total | -1 | Humics-Neutral. |
Superhuman Usage Guidance
Invite Scout for source-bound extraction, long-pack comparison, multimodal document intake, and structured summary tasks where verification is built into the workflow.
Keep Scout out of final ethical decisions, confidential work without approved controls, and tasks where the user cannot evaluate the output independently.
LIPS + CARE | Store sources, source IDs, prompts, evidence tables, corrections, and verification records. |
ULM + EVA | Use Scout to examine options and test plans. Keep goals, values, and final choices human-owned. |
UP-Context | Provide role, context, task, evidence rules, constraints, and output format in every prompt. |
SL-OS | Connect through an approved service layer and record the model identifier, version, and routing. |
UNOP | Use active recall after model use and require learners to explain key claims without the model. |
Over-delegation warning | A 10M-token answer can look comprehensive while weakening your own reading and evaluation skills. Measure net time saved, not gross output volume. |
What Users Say
Aggregate Rating Table
Platform | Verified model-specific evidence at evaluation time |
Trustpilot | No model-specific reviews found |
G2 | No model-specific reviews found |
Capterra | No model-specific reviews found |
Product Hunt | No verified model-specific launch rating found |
App Store | No model-specific app rating applies |
Google Play | No model-specific app rating applies |
No defensible aggregate score recorded for this evaluation | |
Futurepedia | No verified model-specific rating found |
FutureTools | No verified model-specific rating found |
Hugging Face | Official model card and community activity exist, but these do not constitute a review score |
Ollama | Scout availability exists, but package availability is not a review score |
What Users Praise
No cross-platform rating set supports a reliable model-specific summary. Technical community discussions on Reddit note that Scout performs well on coding and technical questions when run on CPU with quantization, and that the long context is useful for personal research workflows.
What Users Complain About
No review aggregate supports a defensible complaint ranking. The practical concerns raised in community discussions include memory requirements for self-hosting, the gap between the theoretical 10M context and effective recall, and the Llama 4 Community License terms compared to Apache 2.0 alternatives.
Sentiment Summary
Insufficient model-specific review data for a numerical or directional verdict. Community discussions suggest cautious optimism for long-context tasks with appropriate hardware, tempered by deployment complexity.
U365 Editorial Note
The limited review evidence supports a conservative score. Specification strength does not substitute for verified workflow outcomes. The CI-First Benefit Score of 5.5/10 reflects genuine capability with clear deployment and verification costs.
Comparison and Alternatives
Alternative | Choose the alternative if | Choose Llama 4 Scout if |
Llama 4 Maverick | You need the larger Llama 4 sibling and can accept greater deployment cost | You prioritize the 10M context and the smaller Scout design |
Llama 3.3 70B | You need a mature text-only Llama deployment and do not need multimodal input | You need native multimodality and much longer context |
Qwen multimodal models | You need a different open-weight multimodal family, language coverage, or license terms | Your tests favor Scout and the Llama deployment stack fits your infrastructure |
Gemma multimodal models | You need a smaller deployment target and can work with a shorter context window | You need Scout's larger context and 16-expert MoE design |
Closed hosted multimodal models | You need managed operations, stronger enterprise controls, or simpler compliance | You need open weights, deployment choice, and license terms you can inspect |
Where Llama 4 Scout is better
The 10M-token context is unusual, and native multimodality supports text and image inputs in one model. Open weights allow inspection, local deployment, and fine-tuning under the Llama 4 Community License. The 17B active parameter footprint keeps inference cost lower than a comparably sized dense model.
Where Llama 4 Scout is worse
Self-hosting remains technically demanding. The license is not an OSI-approved open source license and carries a 700M MAU threshold. Effective context may be shorter than the theoretical maximum, and quality depends heavily on prompt design and verification. Closed hosted alternatives may offer better compliance, monitoring, and ease of use for production teams.
Verdict and Next Steps
Adopt Llama 4 Scout when your work genuinely needs very large context, native multimodal input, and open-weight deployment. The model is best suited for source-bound extraction, long-pack comparison, and multimodal document workflows where verification is built into the process.
Who should adopt it | Advanced learners, researchers, developers, and teams that can manage deployment and verification. |
When | At the start of a long-document or multimodal project, after confirming the effective context and accuracy on your test set. |
For what | Source-bound evidence extraction, large-pack comparison, multimodal document intake, and structured summary tasks. |
UP-Context prompt pack
Prompt 1 | Profile: Analyst and Tester. Context: These files form a labeled evidence pack. Task: Extract claims with source IDs and page references. Do not synthesize. Output: Table with claim, source ID, location, confidence.
Prompt 2 | Profile: Co-Worker and Assistant. Context: Each supplied image is a document page. Task: Extract the specified fields with uncertainty labels. Do not infer missing data. Output: JSON with field, value, confidence, evidence.
Prompt 3 | Profile: Challenger and Devil's Advocate. Context: I have drafted a conclusion from the evidence. Task: Identify the three strongest objections, missing evidence, and alternative interpretations. Output: Numbered list with reasoning.
Next step | Run one workflow on low-risk material. Record corrections and calculate your net time saved after preparation and verification.
Migration Path
Current status | Active. No immediate replacement is required. This section documents the migration process if you switch models later. |
Migration triggers | Replace Scout if the selected package loses support, license terms change, or a stronger model emerges for your task. |
What transfers | Source labels, prompts, output schemas, held-out test sets, and verification workflows. |
What may not transfer | Tokenization, image preprocessing, context behavior, prompt formatting, and provider-specific settings. |
Migration steps
1. Pin the current Scout model and runtime.
2. Preserve a representative text-image test set and expected results.
3. Select a candidate based on privacy, quality, context, cost, license, and operational fit.
4. Run both models against the same tests.
5. Compare errors, review time, infrastructure use, and total cost.
6. Obtain technical, academic, and governance approval.
7. Change routing gradually and keep a tested rollback path.
U365's Recommendations to Learn More
These curated resources help you go deeper into Llama 4 Scout, its architecture, deployment, and community usage. All links were verified as active on 2026-09-03.
Official learning resources
Meta Llama 4 announcement: https://ai.meta.com/blog/llama-4-multimodal-intelligence/
Llama 4 Scout model card on Hugging Face: https://huggingface.co/meta-llama/Llama-4-Scout-17B-16E-Instruct
Llama 4 model card on GitHub: https://github.com/meta-llama/llama-models/blob/main/models/llama4/MODEL_CARD.md
Llama 4 documentation: https://www.llama.com/models/llama-4/
Hugging Face Transformers Llama 4 docs: https://huggingface.co/docs/transformers/en/model_doc/llama4
Hugging Face Llama 4 release blog: https://huggingface.co/blog/llama4-release
Video tutorials and channels
Llama 4 Scout overview by OpenNotebook: https://www.youtube.com/watch?v=F-_xGoMz6GY
Meta AI 2026: Everything New in Llama 4 by Developer's Needs & Stuffs: https://www.youtube.com/watch?v=ZjrYDC_16tU
Written tutorials and deep-dive articles
Llama 4 Scout and Maverick complete guide by ChatGPT AI Hub: https://chatgptaihub.com/llama-4-scout-maverick-guide
Meta Llama 4 Scout and Maverick open-source analysis: https://aiautomationglobal.com/blog/meta-llama-4-scout-maverick-open-source-multimodal-2026
Llama 4 indie maker guide by ShareUHack: https://shareuhack.com/en/posts/llama4-indie-maker-guide-2026
Tutorial: Fine-tune Llama 4 Scout by CallMissed: https://www.callmissed.com/blog/tutorial-fine-tune-llama-4-scout
Llama 4 complete guide by AIMadeTools: https://www.aimadetools.com/blog/llama-4-complete-guide/
Community and social
Reddit r/LocalLLaMA Llama 4 Scout discussion: https://reddit.com/r/LocalLLaMA/comments/1jvbhlp/i_actually_really_like_llama_4_scout
Meta Llama GitHub repository: https://github.com/meta-llama/llama-models
Meta Llama cookbook on GitHub: https://github.com/meta-llama/llama-cookbook
Hugging Face Meta Llama organization: https://huggingface.co/meta-llama
We curate these resources for content quality, not source type. Individual creators and community experts are included when their work teaches something the post itself does not cover. We exclude promotional and affiliate content.
Glossary
CI-First Benefit Score
The CI-First Benefit Score measures how much a tool genuinely improves human work after accounting for prompting, verifying, and correcting its output. It combines four sub-scores: Time (net time saved), Quantity (usable output volume), Quality (verified improvement), and Skill (lasting capability built). The overall score is the average of the four, rounded to one decimal. Bands: 0 to 2.0 CI-First Negative, 2.1 to 4.0 CI-First Neutral, 4.1 to 6.0 CI-First Positive, 6.1 to 8.0 CI-First Strong, 8.1 to 10.0 CI-First Transformative. For Llama 4 Scout, the overall score is 5.5/10, CI-First Positive.
CI-First Profile
The CI-First Profile classifies how a tool collaborates with a human across five levels: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration. Llama 4 Scout is classified as level 2 (Co-Worker and Assistant) as primary profile and level 4 (Analyst and Tester) as secondary profile.
Humics Protection Badge
The Humics Protection Badge rates how a tool affects human creativity, critical thinking, and social authenticity. Each dimension scores +1 (Protects), 0 (Neutral), or -1 (Erodes). The total ranges from -3 to +3. Scores of +2 to +3 earn the Humics-Friendly badge, -1 to +1 earn Humics-Neutral, and -2 to -3 earn Humics-Risky. Llama 4 Scout scores -1 total (Creativity: 0, Critical Thinking: -1, Social Authenticity: 0), earning the Humics-Neutral badge.
AI Imposture Risk
AI Imposture Risk assesses whether a tool creates illusions that mislead users about the time saved, the quantity of useful output, or the skill developed. Each dimension is rated Low, Medium, or High with cited evidence. The overall rating is Low when all are Low, Medium when one or two are Medium, and High when two or more are High. Llama 4 Scout carries Medium overall risk: Time illusion Medium (large inputs reduce splitting but increase total processing time), Quantity illusion Medium (broad summaries can appear complete while missing evidence), and Skill illusion High (technical output may exceed the user's evaluation ability).
User Sentiment
User Sentiment aggregates verified ratings from public review platforms including Trustpilot, G2, Capterra, Product Hunt, App Store, Google Play, Reddit, Futurepedia, FutureTools, Hugging Face, and Ollama. When no model-specific review data exists on a platform, the post records that gap honestly rather than fabricating a score. For Llama 4 Scout, insufficient model-specific review data was found across all platforms at evaluation time. Community discussions on Reddit suggest cautious optimism for long-context tasks with appropriate hardware.
Sources
Meta Llama 4 announcement: https://ai.meta.com/blog/llama-4-multimodal-intelligence/
Llama 4 Scout model card on Hugging Face: https://huggingface.co/meta-llama/Llama-4-Scout-17B-16E-Instruct
Llama 4 model card on GitHub: https://github.com/meta-llama/llama-models/blob/main/models/llama4/MODEL_CARD.md
Meta Llama models GitHub repository: https://github.com/meta-llama/llama-models
Llama 4 on llama.com: https://www.llama.com/models/llama-4/
Llama 4 Community License: https://www.llama.com/llama4/license/
Hugging Face Transformers Llama 4 documentation: https://huggingface.co/docs/transformers/en/model_doc/llama4
Hugging Face Llama 4 release blog: https://huggingface.co/blog/llama4-release
Hugging Face Meta Llama organization: https://huggingface.co/meta-llama
Meta developer documentation: https://developer.meta.com/ai/docs/overview/
Meta Llama cookbook on GitHub: https://github.com/meta-llama/llama-cookbook
Reddit r/LocalLLaMA Llama 4 Scout discussion: https://reddit.com/r/LocalLLaMA/comments/1jvbhlp/i_actually_really_like_llama_4_scout
Llama 4 Scout and Maverick complete guide by ChatGPT AI Hub: https://chatgptaihub.com/llama-4-scout-maverick-guide
Meta Llama 4 Scout and Maverick open-source analysis: https://aiautomationglobal.com/blog/meta-llama-4-scout-maverick-open-source-multimodal-2026
Llama 4 indie maker guide by ShareUHack: https://shareuhack.com/en/posts/llama4-indie-maker-guide-2026
Tutorial: Fine-tune Llama 4 Scout by CallMissed: https://www.callmissed.com/blog/tutorial-fine-tune-llama-4-scout
Llama 4 complete guide by AIMadeTools: https://www.aimadetools.com/blog/llama-4-complete-guide/
Llama 4 Scout overview video by OpenNotebook on YouTube: https://www.youtube.com/watch?v=F-_xGoMz6GY
Meta AI 2026 Llama 4 video by Developer's Needs & Stuffs on YouTube: https://www.youtube.com/watch?v=ZjrYDC_16tU
Llama 4 Scout vs Maverick single A100 guide by SofTechInfra: https://softechinfra.com/blog/llama-4-scout-vs-maverick-single-a100-indian-startup-self-host




Comments