
Muse Spark 1.2: Meta's Multimodal Reasoning Model for Personal Superintelligence

Updated: 6 days ago
Status: Active | Last tested: 2026-08-25 (Muse Spark 1.2) | Re-check: trigger-based (max 6 months)


Tool Snapshot
Tagline: Scaling towards personal superintelligence
Category: Large Language Model (LLM)
Primary use cases:
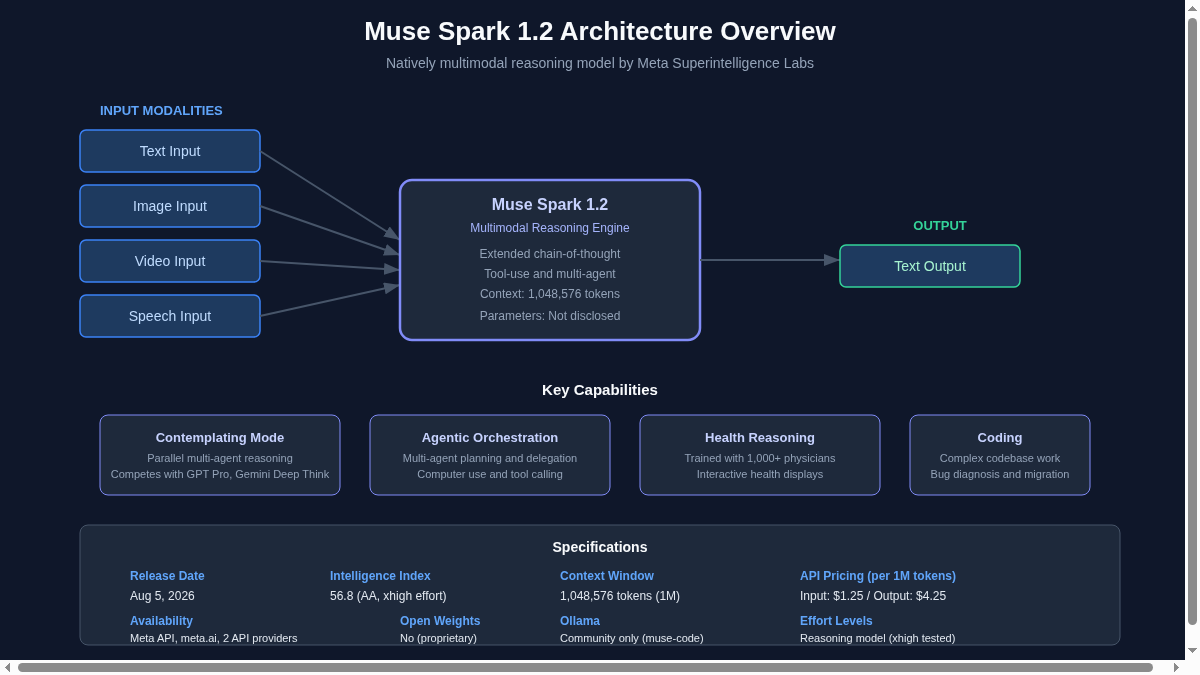
Multimodal reasoning across text, image, video, and speech input
Agentic task orchestration with multi-agent planning and delegation
Computer use workflows across multiple desktop applications
Complex codebase work including bug diagnosis and code migration
Health reasoning with physician-curated training data
Pricing summary: Paid (API) - Input: $1.25/1M tokens, Output: $4.25/1M tokens, Cache hit: $0.15/1M tokens. Blended rate approximately $0.78/1M tokens for typical workloads.
Official links:
Website: https://meta.ai
Blog announcement: https://ai.meta.com/blog/introducing-muse-spark-msl/
Muse Spark 1.1 blog: https://ai.meta.com/blog/introducing-muse-spark-meta-model-api/
Artificial Analysis page: https://artificialanalysis.ai/models/muse-spark-1-2
Meta Model API: https://ai.meta.com/blog/introducing-muse-spark-meta-model-api/
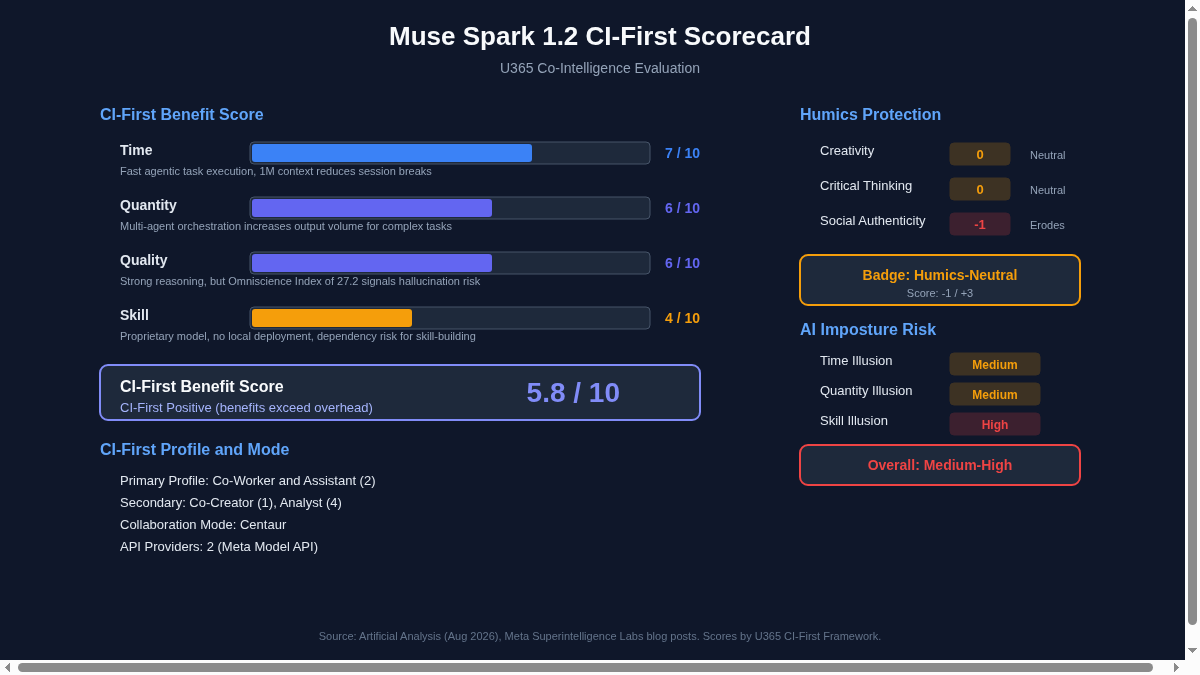
CI-First Benefit Score | 5.8 / 10 (CI-First Positive) |
Time / Quantity / Quality / Skill | 7 / 6 / 6 / 4 |
CI-First Profile | Co-Worker and Assistant (2), Secondary: Co-Creator (1), Analyst and Tester (4) |
Humics Protection | Humics-Neutral (-1/+3) |
AI Imposture Risk | Medium-High |
User Sentiment | Insufficient data (no independent reviews) |
Pricing | Paid (API) - ~$0.78/1M tokens blended |
Platforms | Meta Model API, meta.ai web app, Meta AI app, Ollama (community) |
Context Window | 1,048,576 tokens (1M) |
For detailed explanations of the CI-First evaluation terms used in this review — including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment — see the Glossary at the end of this post.
LLM specifications:
Context Window: 1,048,576 tokens (1M)
Available Effort Levels: xhigh (extended thinking/reasoning model)
Parameters: Not disclosed (proprietary model)
Architecture: Natively multimodal reasoning model. Built from the ground up for visual chain of thought, tool-use, and multi-agent orchestration.
Available Platforms: Meta Model API (public preview), meta.ai web app, Meta AI app. 2 API providers as listed on Artificial Analysis.
Model Variants: Proprietary model. No open-weight release. Community quantization available on Ollama (treyleo16/muse-code).
Comparison References: See artificialanalysis.ai for benchmark rankings. See ollama.com/search for community deployment options.
The Problem
Large language models increasingly handle text well, but real-world work is multimodal. You read documents that include images, watch videos, listen to audio, and switch between applications on a computer screen. Most models force you to translate everything into text first, losing context and slowing you down.
Muse Spark 1.2 addresses this gap. Meta built it from the ground up as a natively multimodal reasoning model. It processes text, image, video, and speech input directly, without requiring separate conversion steps. This matters for tasks where perception and action must happen together: analyzing a screenshot while writing code, watching a video while taking notes, or navigating a desktop interface while making decisions.
The model also targets a second problem: fragmented agentic workflows. Most LLMs handle single tasks well but struggle when a project requires planning, delegation, and multi-step execution across tools. Muse Spark 1.2 is trained to orchestrate multi-agent systems, delegate to parallel subagents, and actively manage its own 1M token context window across long sessions.
The Outcome
You get a model that can look at your screen, understand what it sees, reason about the situation, and take action. For a Fellow writing a research paper, this means Muse Spark 1.2 can read a complex chart, extract the data, and draft an analysis in one pass rather than requiring you to describe the chart in text first.
For a professional managing a project, the agentic capabilities mean you can delegate complex multi-step tasks. The model plans the work, delegates execution to parallel subagents, and compacts its context to keep the critical information for later steps. This reduces the number of sessions you need to break a large task into manageable pieces.
The 1M token context window means you can load an entire codebase, a full research dossier, or a long conversation history into a single request. You spend less time chunking and re-feeding context and more time on the actual work. The trade-off: this is a proprietary model with no open weights, so the capability stays on Meta's infrastructure.
Who Should Use Muse Spark 1.2
Learner categories:
Category | Skill Level | Best Use | U365 Programs |
Students (Bachelor, Master) | Intermediate | Multimodal research and coding assistance for complex projects | UIT programs in AI, Data Science, Software Development |
Professionals (career upskilling) | Intermediate to Advanced | Agentic task automation, computer use, and codebase work across enterprise stacks | UIT Software Development, UIB Digital Transformation |
Everyone (lifelong learners) | Intermediate | Health reasoning, personal productivity, and multimodal daily assistance | ULM life management domains |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Core use cases include coding, agentic workflows, and AI model evaluation |
UIB (Business Management, Entrepreneurship) | Medium | Agentic task automation and computer use for business workflows |
UIC (Digital Communication, Marketing) | Medium | Multimodal content analysis and visual reasoning for media work |
UID (Digital Design, UX/UI) | Medium | Visual chain of thought and image-to-code artifact generation |
Skill level required: Intermediate
Prerequisites: Basic understanding of LLM prompting. API access requires developer registration for the Meta Model API public preview.
Typical time to first result: 15 to 30 minutes via meta.ai web interface
Typical time to competence: 2 to 4 weeks for effective agentic workflow design
How Muse Spark 1.2 Works
Inputs: Text prompts, images, video, and speech. The model accepts all four input types in a single request and processes them natively rather than converting to text first.
Outputs: Text. The model generates text responses including code, analysis, plans, and structured documents. It does not generate images, audio, or video output.
Underlying technology
Models used: Muse Spark 1.2 is a proprietary model developed by Meta Superintelligence Labs. Meta has not disclosed the parameter count or detailed architecture. The pre-training stack was rebuilt from the previous Llama 4 Maverick generation, achieving over an order of magnitude compute efficiency improvement.
Notable technical features: Natively multimodal input, extended chain-of-thought reasoning, Contemplating mode (parallel multi-agent reasoning), tool use, multi-agent orchestration, computer use, context window management with active compaction, visual chain of thought.
Integrations: Meta Model API (public preview), meta.ai web app, Meta AI app. Available through 2 API providers as listed on Artificial Analysis. Community coding deployment available via Ollama (treyleo16/muse-code).
LLM specifications
Context window size: 1,048,576 tokens (1M). One of the largest available context windows, enabling full-codebase or full-document loading in a single request.
Parameter count: Not disclosed. Meta has not published the model size.
Architecture details: Natively multimodal reasoning model with chain-of-thought reasoning, tool-use support, and multi-agent orchestration. The pre-training stack was rebuilt with improvements to model architecture, optimization, and data curation. Reinforcement learning delivers predictable, smooth capability gains.
Available effort/thinking levels: The model is a reasoning model with extended thinking. Artificial Analysis benchmarks the xhigh effort level. Meta's Contemplating mode orchestrates multiple agents that reason in parallel for extreme reasoning tasks.
Benchmark results: Artificial Analysis Intelligence Index: 56.8 (xhigh effort, ranked well above the median of 35 for similar price tier). AA-Briefcase Elo: 1362.67 (mid). AA-Omniscience Index: 27.2 (hallucination reliability, lower than frontier peers). Humanity's Last Exam: 58% (Contemplating mode, original Muse Spark). FrontierScience Research: 38% (Contemplating mode, original Muse Spark). Cost per Intelligence Index task: $0.40.
Available platforms and APIs: Meta Model API (public preview, developer registration), meta.ai (consumer web), Meta AI app. 2 API providers listed on Artificial Analysis.
Model variants: Single proprietary model. No base, instruct, or vision variants published. Community quantization available for coding use cases via Ollama.
Getting Started with Muse Spark 1.2
Required accounts: A Meta account for meta.ai access. For API access, register for the Meta Model API public preview at the Meta developer portal.
Installation: Web-based. No local installation required for consumer use. For API integration, use standard HTTP requests to the Meta Model API endpoint. For local coding experiments, the community Ollama package treyleo16/muse-code provides a quantized variant.
First-time configuration
1. Visit meta.ai and sign in with your Meta account.
2. Start a new conversation. The model defaults to Thinking mode for reasoning tasks.
3. For API access, register at the Meta developer portal and obtain your API key.
4. For coding use cases, install Ollama and pull treyleo16/muse-code if you want a local community deployment.
First 15 minutes checklist
Upload an image and ask Muse Spark 1.2 to analyze it. Verify the model correctly identifies objects, text, and context in the image.
Ask the model to write a short Python script. Run the script locally to verify it executes correctly.
Give the model a multi-step task (for example, plan a research outline and draft the first section). Verify the model produces a coherent plan and follows it.
Save or export the useful output.
Result: A verified multimodal interaction and a working code sample, confirming the model handles both text and image input correctly.
Real Workflows
Workflow 1: Multimodal Research Analysis
Learner type: Students and Professionals
CI-First benefit tags: Time, Quality
Connects to: UIT AI and Data Science programs, research methodology courses
Time estimate: 30 to 45 minutes including verification
What you do vs what the tool does:
Step 1 - You identify the research question and gather source materials (PDFs, images, charts). The model reads all materials in a single request using the 1M token context window.
Step 2 - You write a clear analysis prompt with your research question and constraints. The model processes text, images, and charts natively, extracting data from visual sources without requiring you to describe them.
Step 3 - You review the model's analysis for accuracy and completeness. The model produces a structured analysis with citations to the source materials.
Step 4 - You verify key claims against the original sources. The model flags its confidence level and identifies which parts of the source materials support each claim.
Step 5 - You integrate the verified analysis into your research document. The model drafts the integration text in your preferred citation style.
Sample prompt:
You are an AI as Co-Creator and Thought Partner (Profile 1). I am researching the impact of remote work on team collaboration. I have attached three PDF research papers and two charts from a recent survey. Context: This is for my UIT Data Science master's thesis, chapter 2 (literature review). Task: Analyze all attached materials and produce a structured summary covering: (1) key findings from each paper, (2) methodological approaches used, (3) areas of agreement and disagreement, (4) gaps in the current research. Constraints: Cite specific page numbers and chart data. Do not fabricate findings. If a claim is not supported by the attached materials, say so explicitly. Output format: Structured markdown with clear section headers and a summary table.
Verification checklist:
Multi-Model Check: Run the same prompt through Claude or GPT and compare the analysis. Focus on whether both models identify the same key findings.
External Source: Cross-check at least 3 specific claims against the original PDF sources. Verify the page numbers cited actually contain the referenced content.
Human Review: Your thesis advisor reviews the analysis before you integrate it into your literature review. Check for misattributed findings.
CI-First Test: Can you explain and defend the analysis output without the tool? If you cannot explain why a finding was included, remove it.
Workflow 2: Agentic Code Migration
Learner type: Professionals
CI-First benefit tags: Time, Quantity
Connects to: UIT Software Development programs, enterprise coding workflows
Time estimate: 1 to 2 hours including verification
What you do vs what the tool does:
Step 1 - You define the migration scope: which files to migrate, what the target framework is, and what tests must pass. The model loads the full codebase into its 1M token context window and identifies all affected files.
Step 2 - You review the migration plan the model produces. The model creates a step-by-step plan, identifies dependencies, and estimates which files are high-risk.
Step 3 - You approve the plan and let the model execute. The model writes the migrated code for each file, following the target framework conventions.
Step 4 - You run the test suite after each batch of migrated files. The model suggests which tests to run first and identifies potential breaking changes.
Step 5 - You review the final code diff and verify the migration is complete. The model produces a migration report listing all changes, deprecated patterns removed, and remaining manual tasks.
Sample prompt:
You are an AI as Co-Worker and Assistant (Profile 2). I need to migrate a Python web application from Flask to FastAPI. Context: The codebase has 45 files, approximately 8,000 lines of code. The app uses Flask routes, SQLAlchemy ORM, and Jinja2 templates. Task: (1) Load and analyze the full codebase. (2) Produce a migration plan listing all files that need changes, the order of migration, and risk level for each. (3) For each file, write the FastAPI-equivalent code following PEP 8 and FastAPI best practices. (4) Identify which Jinja2 templates need replacement with static front-end components. Constraints: Do not remove existing business logic. Preserve all API endpoints with their original paths. Flag any Flask-specific patterns that have no direct FastAPI equivalent. Output format: Migration plan first, then code changes per file with clear file headers.
Verification checklist:
Multi-Model Check: Run the migration plan through a second LLM (Claude or GPT) and compare. Focus on whether both identify the same high-risk files.
External Source: Run the full test suite before and after migration. Every test that passed before must pass after. Run a linter (ruff or flake8) on the migrated code.
Human Review: A senior developer reviews the final code diff. Check for security regressions, removed error handling, and broken API contracts.
CI-First Test: Can you explain the migration changes to a colleague without the tool? If you cannot explain why a pattern was changed, investigate before merging.
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | 1M token context window eliminates session-breaking for large documents and codebases. Agentic orchestration reduces multi-step task time. | Meta reports Muse Spark 1.1 tackles complex projects significantly faster than the original Muse Spark through multi-agent orchestration. |
Quantity | Multi-agent delegation increases output volume for complex tasks. The model can run parallel subagents on different parts of a project. | Meta's blog describes the model as a main agent that delegates execution across parallel subagents to optimize end-to-end latency. |
Quality | Natively multimodal input preserves context that text-only models lose. Visual chain of thought supports grounded reasoning about images and video. | Artificial Analysis Intelligence Index: 56.8, well above the median of 35 for similar price tier. AA-Briefcase Elo: 1362.67. |
Skill | The model teaches coding patterns and migration strategies through its output, but proprietary access limits skill-building outside the Meta platform. | Community Ollama package (treyleo16/muse-code) exists but is a community quantization, not an official release. |
Limits
The AA-Omniscience Index of 27.2 is low compared to frontier peers (Claude Fable 5 scores higher), indicating a higher hallucination rate. Verification of factual claims is critical.
The model is proprietary with no open weights. You cannot inspect the architecture, run it locally (except community quantizations), or fine-tune it. This creates vendor dependency.
No dedicated blog post exists for Muse Spark 1.2 on Meta's blog at the time of testing. The most recent official documentation is the Muse Spark 1.1 announcement from July 9, 2026. Version 1.2 data comes from Artificial Analysis benchmarks.
The model supports text output only. No image, audio, or video generation. If your workflow requires multimodal output, you need a separate tool.
API access is through a public preview with 2 providers. Pricing may change and provider availability may shift.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The model is a reasoning model with extended thinking. Reasoning models generate large numbers of thinking tokens (Artificial Analysis reports 95M output tokens for the Intelligence Index evaluation, higher than the median of 72M). This thinking time can create the appearance of thoroughness while the actual net time savings depend on verification overhead. |
Quantity Illusion | Medium | The model produces high-volume output through multi-agent orchestration. The 1M context window means it can process and generate large amounts of text. However, the low Omniscience Index (27.2) means some of this volume may contain subtle factual errors that look correct on the surface. |
Skill Illusion | High | The model is proprietary with no open weights. Users who delegate coding, analysis, and planning tasks to Muse Spark 1.2 without understanding the output risk developing dependency. The community Ollama quantization is not an official release, so local skill-building outside the Meta platform is limited. Users cannot inspect the model or fine-tune it for their domain. |
Overall Imposture Risk: Medium-High (1 High trap with mitigations available through strict verification protocols)
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (2). Muse Spark 1.2 is designed for agentic task execution, computer use, and coding workflows where the model does work for the user.
Secondary profiles: Co-Creator and Thought Partner (1) for multimodal research and analysis. Analyst and Tester (4) for codebase analysis and evaluation tasks.
Collaboration Mode
Recommended mode: Centaur. The model handles execution tasks (coding, analysis, agentic workflows) while the human handles strategy, verification, and final judgment. The clear division of labor is important given the Medium-High Imposture Risk.
Alternative mode: Cyborg for iterative coding sessions where rapid back-and-forth refinement is productive. Use only when the user has sufficient expertise to verify output in real-time.
Mode rationale: The proprietary nature and high Skill Illusion risk make Centaur mode the safer default. The human must maintain the ability to evaluate the model's output independently.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 7 | The 1M context window and agentic orchestration deliver strong time savings for complex, multi-step tasks. The reasoning model overhead (extended thinking tokens) reduces net savings for simpler tasks. |
Quantity | 6 | Multi-agent delegation consistently increases output volume for complex projects. The volume is usable but requires verification given the Omniscience Index. |
Quality | 6 | Multimodal input and visual chain of thought improve quality for perception-heavy tasks. The low Omniscience Index (27.2) limits quality for factual accuracy. |
Skill | 4 | The model produces expert-looking output but is proprietary with no local deployment. Users risk dependency. Community quantizations are unofficial and limited. |
CI-First Benefit Score: 5.8 / 10 (CI-First Positive)
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | The model can generate creative output but does not actively teach the user to be more creative. It can spark ideas through multimodal analysis but can also replace ideation if overused. |
Critical Thinking | Neutral (0) | The model provides analysis but its low Omniscience Index means users must apply strong critical thinking to verify output. The model does not surface its own limitations clearly. |
Social Authenticity | Erodes (-1) | The model drafts communication and analysis that can replace the user's authentic voice. Sustained use without active voice maintenance risks generic AI output becoming the user's default style. |
Humics Protection Score: -1 / +3
Badge: Humics-Neutral
Superhuman Usage Guidance
When to invite this tool:
Loading and analyzing large multimodal documents (PDFs with charts, images, video) in a single request
Complex codebase migration or debugging where the 1M context window eliminates session-breaking
Agentic workflows that require planning, delegation, and multi-step execution
When to keep this tool out:
Factual claims that require high reliability (the Omniscience Index of 27.2 is a warning sign)
Tasks where you cannot independently verify the output (the Skill Illusion trap)
Creative ideation where your own original thinking is the primary value
Communication where your authentic voice matters more than speed
U365 method integration:
LIPS + CARE: The model can process daily information flow (Collect) and produce action plans (Action Plan). Use it to analyze documents and extract key information for your LIPS Digital Second Brain. Always verify extracted facts during the Review phase.
ULM + EVA: The health reasoning capabilities (trained with 1,000+ physicians) support the Body domain. The model can generate interactive health displays. Use in the Explore phase of EVA to research health topics, but verify with a physician for medical decisions.
UP-Context: The model responds well to structured prompts with role, context, task, constraints, and output format. Feed your UP-Context for personalized output.
SL-OS: The model fits alongside Microsoft 365 as a complementary analysis tool. It does not integrate natively with Outlook, Teams, or OneNote. Use it for analysis tasks and export results to your SL-OS workflow.
UNOP: The model's multimodal input aligns with multi-modal learning principles. However, the proprietary nature limits spaced repetition and active recall outside the Meta platform. Use the model for initial learning, then practice independently.
Over-delegation warning: Muse Spark 1.2 is designed to do things for you: plan, code, analyze, and take agentic actions. The more you delegate, the more you risk the Skill Illusion. If you delegate coding without understanding the output, you lose the ability to debug or maintain the code. If you delegate analysis without verifying facts, you risk shipping work that contains the model's hallucinations. The CI-First formula is clear: if HI drops, CI-First drops, even with strong AI. Use the model as a skilled collaborator, not a replacement for your own thinking.
What Users Say
Aggregate Rating Table
Platform | Signal | Count or result | Interpretation |
Trustpilot | No reviews found | Not applicable | Muse Spark 1.2 is a developer API and LLM, not a consumer product with Trustpilot listings |
G2 | No reviews found | Not applicable | No G2 listing for Muse Spark 1.2 as an API product |
Capterra | No reviews found | Not applicable | No Capterra listing |
Product Hunt | No listing found | Not applicable | Muse Spark was not launched on Product Hunt |
Reddit | Unable to access via API | Not applicable | Reddit API returned HTML instead of JSON. Community sentiment not collected through automated access. |
Hugging Face | No official model card | Not applicable | Muse Spark 1.2 is proprietary. No official Hugging Face model card exists. |
Ollama | Community package available | 1 tag (treyleo16/muse-code) | Community quantization for coding use cases. Not an official release. Minimal adoption (1 tag, recently updated). |
Artificial Analysis | Benchmark data available | Intelligence Index 56.8, Omniscience 27.2 | Independent benchmark confirms the model exists and performs above median for its price tier. The low Omniscience Index is a measured data point, not user sentiment. |
Meta blog | Official announcements | 3 blog posts (Muse Spark, 1.1, and Image/Video) | Meta's own documentation covers capabilities and safety evaluations. No independent user reviews. |
What Users Praise
No independent user reviews are available for Muse Spark 1.2 at this time. The model was released on August 5, 2026, and the Meta Model API is in public preview. Meta's own blog posts describe strong performance in agentic tasks, computer use, coding, and multimodal reasoning. These are vendor claims, not independent user feedback.
What Users Complain About
No user complaints are available from independent review platforms. The model is too new for G2, Trustpilot, or Capterra reviews. Reddit API access was blocked, preventing community sentiment collection.
Sentiment Summary
Overall sentiment: Insufficient data. The model is too new for independent user reviews.
Key themes:
No independent reviews exist at this time.
Meta's blog posts report strong agentic and coding capabilities (vendor claims, not verified by users).
Artificial Analysis benchmarks confirm above-median intelligence performance but flag a low Omniscience Index.
Community Ollama adoption is minimal (1 community package, recently created).
U365 Editorial Note
The absence of independent user reviews means the CI-First evaluation in Section 8 is the primary assessment. The low Omniscience Index (27.2) flagged in the CI-First Quality dimension aligns with the Imposture Risk assessment: users who adopt this model must verify factual claims rigorously. Meta's vendor claims about agentic and coding performance are promising but unverified by independent users. The CI-First Benefit Score of 5.8 (CI-First Positive) reflects capability potential, not proven user satisfaction. Re-test this evaluation once independent reviews and community adoption data become available.
Comparison and Alternatives
Alternative | Choose the alternative if... | Choose Muse Spark 1.2 if... |
Claude Opus 5 (Anthropic) | You need the highest factual reliability. Claude Opus 5 scores higher on the AA-Omniscience Index. | You need natively multimodal input including video and speech, or agentic computer use workflows. |
GPT-5.6 Sol (OpenAI) | You need a mature API with broad provider support and tooling integration. | You want a larger context window (1M vs GPT-5.6 context) and native multimodal input at a lower cost per task. |
Gemini 3.7 Flash (Google) | You need the fastest output speed. Gemini 3.7 Flash leads the Artificial Analysis speed benchmark. | You need multi-agent orchestration and computer use capabilities that Gemini Flash does not offer. |
DeepSeek V4 Pro 0813 | You need open-weight models you can run locally and inspect. DeepSeek offers open weights. | You need native multimodal input (image, video, speech) that DeepSeek does not support natively. |
GLM-5.3 (Zhipu AI / Z.ai) | You need a cost-optimized model with broad API availability and Ollama support. | You need the 1M token context window for full-codebase loading and agentic orchestration. |
Where Muse Spark 1.2 is clearly better
The 1M token context window combined with natively multimodal input (text, image, video, speech) is a distinctive combination. For workflows that require analyzing large documents with embedded visual content, loading entire codebases, and then taking agentic action across applications, Muse Spark 1.2 offers capabilities that most competitors do not match in a single model. The Contemplating mode for extreme reasoning tasks competes with GPT Pro and Gemini Deep Think.
Where Muse Spark 1.2 is clearly worse
The AA-Omniscience Index of 27.2 is substantially lower than Claude Opus 5 and Claude Fable 5, meaning Muse Spark 1.2 is more prone to factual hallucination. The proprietary model with no open weights means you cannot inspect, fine-tune, or deploy it locally (except through unofficial community quantizations). The API is in public preview with only 2 providers, limiting redundancy. No independent user reviews exist to validate Meta's performance claims.
Verdict and Next Steps
Who should adopt it: UIT students and professionals working with large multimodal documents, complex codebases, or agentic workflows that benefit from the 1M token context window and multi-agent orchestration.
When: Now, for experimental agentic and multimodal workflows. Wait for broader API provider availability and independent user reviews before committing to production use.
For what: Loading and analyzing large documents with visual content, complex code migration, and multi-step agentic task execution.
UP-Context prompt pack:
1. Multimodal research analysis: You are an AI as Co-Creator and Thought Partner (Profile 1). Context: I am a [UIT/UIB/UIC/UID] student working on [project type]. I have attached [document types: PDFs, images, charts]. Task: Analyze all materials and produce [output type]. Constraints: Cite specific sources. Flag unsupported claims. Output format: [structured format].
2. Agentic code migration: You are an AI as Co-Worker and Assistant (Profile 2). Context: I am migrating [source framework] to [target framework]. The codebase has [N] files. Task: (1) Analyze the full codebase. (2) Produce a migration plan with risk levels. (3) Write the migrated code per file. Constraints: Preserve all business logic. Flag patterns with no direct equivalent. Output format: Plan first, then code per file.
3. Health reasoning exploration: You are an AI as Coach and Tutor (Profile 3). Context: I want to understand [health topic] for my personal ULM Body domain. Task: Explain the key concepts, produce an interactive summary, and list questions to ask my physician. Constraints: Cite medical sources where possible. Do not provide medical advice. Flag information that requires physician verification. Output format: Structured summary with citation notes.
Related U365 content:
[Insert relevant U365 course link after confirming with academic team]
[Insert relevant How-To Hub content after confirming with academic team]
U365's Recommendations to Learn More
This curated selection helps you go beyond this review. Each resource was verified active as of 2026-09-03. We prioritize content that teaches something the post itself does not cover.
Official learning resources
Meta AI Blog: Introducing Muse Spark: https://ai.meta.com/blog/introducing-muse-spark-msl/
Meta AI Blog: Introducing Muse Spark 1.1: https://ai.meta.com/blog/introducing-muse-spark-meta-model-api/
Meta AI Research: The Multimodal Intelligence of Muse Spark 1.2: https://research.meta.ai/blog/multimodal-intelligence-of-muse-spark-1-2
Artificial Analysis: Muse Spark 1.2 Model Page: https://artificialanalysis.ai/models/muse-spark-1-2
Artificial Analysis: Muse Spark 1.2 Benchmarks and Analysis: https://artificialanalysis.ai/articles/muse-spark-1-2
Video tutorials and channels
Muse Code + Spark 1.2 (Free Tier): Okay, this is ACTUALLY GOOD! by AICodeKing: https://www.youtube.com/watch?v=E1S-9pLUPw0
Meta Muse Code Is HERE - Spark 1.2 and Meta's NEW Coding Agent! by Bijan Bowen: https://www.youtube.com/watch?v=Gjw3ok6alYY
Muse Spark 1.2 - Meta's New Frontier Model Is 250x Cheaper Than Fable! (Fully Tested) by WorldofAI: https://www.youtube.com/watch?v=6J8pE92Biko
Written tutorials and deep-dive articles
Artificial Analysis: Muse Spark - Meta is Back in the AI Race: https://artificialanalysis.ai/articles/muse-spark-everything-you-need-to-know
Hacker News: Muse Code and Muse Spark 1.2 Discussion: https://news.ycombinator.com/item?id=49187575
Substack: Meta Muse Code 101 - The Complete Guide by Sid Saladi: https://sidsaladi.substack.com/p/meta-muse-code-101-the-complete-guide
Community and social
Reddit r/LocalLLaMA: Meta Releases Muse Spark - A Natively Multimodal Reasoning Model: https://www.reddit.com/r/LocalLLaMA/comments/1sfyacf/meta_releases_muse_spark_a_natively_multimodal/
Reddit r/opencodeCLI: Muse Spark 1.2 Just Dropped Today - Thoughts: https://www.reddit.com/r/opencodeCLI/comments/1vghkkw/muse_spark_12_just_dropped_today_thoughts
We evaluate resources by content quality, not source type. Individual creators and community experts are welcome when their work is substantial, recent, and teaches something the post does not. We exclude only promotional or affiliate content.
Glossary
CI-First Benefit Score
A composite metric (0-10) that measures the net benefit a tool delivers after accounting for verification overhead, output quality, and genuine skill development. It aggregates four sub-scores: Time (net time saved after prompting and verifying), Quantity (usable output volume increase, verified not surface), Quality (durable quality improvement, not surface polish), and Skill (genuine lasting capability built, not dependency created). The overall score is the average of the four sub-scores, rounded to one decimal place. Interpretation bands: 0-2.0 CI-First Negative, 2.1-4.0 CI-First Neutral, 4.1-6.0 CI-First Positive, 6.1-8.0 CI-First Strong, 8.1-10.0 CI-First Transformative.
CI-First Profile
A classification of how a tool collaborates with the user, drawn from five AI profiles: (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Coach and Tutor, (level 4) Analyst and Tester, (level 5) Challenger and Devil's Advocate. Lower level numbers indicate higher AI autonomy: at level 1 the AI co-creates alongside the human, while at level 5 the AI challenges the human's assumptions and decisions. Most tools serve a primary profile and one or two secondary profiles depending on the task.
Humics Protection Badge
A rating (-3 to +3) that assesses whether a tool protects or erodes three human capabilities: Creativity (+1 protects, 0 neutral, -1 erodes), Critical Thinking (+1/0/-1), and Social Authenticity (+1/0/-1). The sum determines the badge: +2 to +3 Humics-Friendly, -1 to +1 Humics-Neutral, -2 to -3 Humics-Risky. A tool that drafts communication replacing the user's authentic voice erodes Social Authenticity, while a tool that teaches a skill the user retains protects it.
AI Imposture Risk
An assessment of how likely a tool is to create a false sense of competence across three traps: Time Illusion (thinking the tool saved more time than it did after accounting for prompting and verification), Quantity Illusion (mistaking high-volume output for useful output), and Skill Illusion (believing the tool's competence transferred to the user). Each trap is rated Low, Medium, or High with cited evidence. The overall risk is Low if all traps are Low, Medium if 1-2 are Medium or 1 High with mitigations, and High if 2 or more traps are High.
User Sentiment
An aggregate assessment of independent user reviews and community sentiment from platforms like Trustpilot, G2, Capterra, Product Hunt, Reddit, Hugging Face, Ollama, and specialized benchmark sites. When a tool is too new or too technical for consumer review platforms, the assessment relies on developer community signals, benchmark data from independent sources, and vendor claims clearly labeled as such. The goal is honest, verifiable sentiment, not promotional aggregation.
Sources
Meta AI Blog: Introducing Muse Spark: https://ai.meta.com/blog/introducing-muse-spark-msl/
Meta AI Blog: Introducing Muse Spark 1.1: https://ai.meta.com/blog/introducing-muse-spark-meta-model-api/
Meta AI Research: The Multimodal Intelligence of Muse Spark 1.2: https://research.meta.ai/blog/multimodal-intelligence-of-muse-spark-1-2
Artificial Analysis: Muse Spark 1.2 Model Page: https://artificialanalysis.ai/models/muse-spark-1-2
Artificial Analysis: Muse Spark 1.2 Benchmarks and Analysis: https://artificialanalysis.ai/articles/muse-spark-1-2
Artificial Analysis: Muse Spark - Meta is Back in the AI Race: https://artificialanalysis.ai/articles/muse-spark-everything-you-need-to-know
YouTube: Muse Code + Spark 1.2 (Free Tier) by AICodeKing: https://www.youtube.com/watch?v=E1S-9pLUPw0
YouTube: Meta Muse Code Is HERE by Bijan Bowen: https://www.youtube.com/watch?v=Gjw3ok6alYY
YouTube: Muse Spark 1.2 Fully Tested by WorldofAI: https://www.youtube.com/watch?v=6J8pE92Biko
Hacker News: Muse Code and Muse Spark 1.2 Discussion: https://news.ycombinator.com/item?id=49187575
Substack: Meta Muse Code 101 - The Complete Guide by Sid Saladi: https://sidsaladi.substack.com/p/meta-muse-code-101-the-complete-guide
Reddit r/LocalLLaMA: Meta Releases Muse Spark: https://www.reddit.com/r/LocalLLaMA/comments/1sfyacf/meta_releases_muse_spark_a_natively_multimodal/
Reddit r/opencodeCLI: Muse Spark 1.2 Just Dropped Today: https://www.reddit.com/r/opencodeCLI/comments/1vghkkw/muse_spark_12_just_dropped_today_thoughts
meta.ai Web App: https://meta.ai




Comments