
Nemotron 3 Ultra: NVIDIA's Open-Weights Reasoning Model for Research and Coding

Updated: 6 days ago
Status: Active | Last tested: 2026-08-25 (Nemotron 3 Ultra 550B/55B) | Re-check: trigger-based (max 6 months)


Tool Snapshot
Tagline: NVIDIA's open-weights reasoning LLM with a 512K context window and efficient MoE architecture.
Category: Large Language Model
Provider: NVIDIA
Version tested: Nemotron 3 Ultra 550B/55B (June 2026)
Parameters: 550B total, 55B active (Mixture of Experts)
Context window: 512K tokens (up to 1M with extended configuration)
License: OpenMDW 1.1 (Linux Foundation)
Platforms: build.nvidia.com, OpenRouter, Ollama (cloud), vLLM, Hugging Face
Primary use cases:
Processing long documents up to 512K tokens in a single request
Writing and debugging code across multiple programming languages
Research analysis with multi-step reasoning and citations
Self-hosted deployment for organizations needing full model control
Agentic workflows with tool use and structured output
Pricing summary: Paid - API pricing: $0.60 per 1M input tokens, $3.60 per 1M output tokens (OpenRouter). Blended rate: $1.20 per 1M tokens. Open weights available free under NVIDIA Open Model License for self-hosting. Also available on build.nvidia.com. Pricing as of August 2026.
Official links:
Website: https://build.nvidia.com
Docs: https://huggingface.co/nvidia/nemotron-3-ultra-550b-a55b
Help: https://build.nvidia.com
Status: Not publicly available
Community: https://huggingface.co/nvidia/nemotron-3-ultra-550b-a55b
LLM specifications:
Context Window: 512K tokens (524,288 tokens)
Effort Levels: Configurable reasoning effort (low, medium, high)
Parameters: 550B total, 55B active (Mixture of Experts)
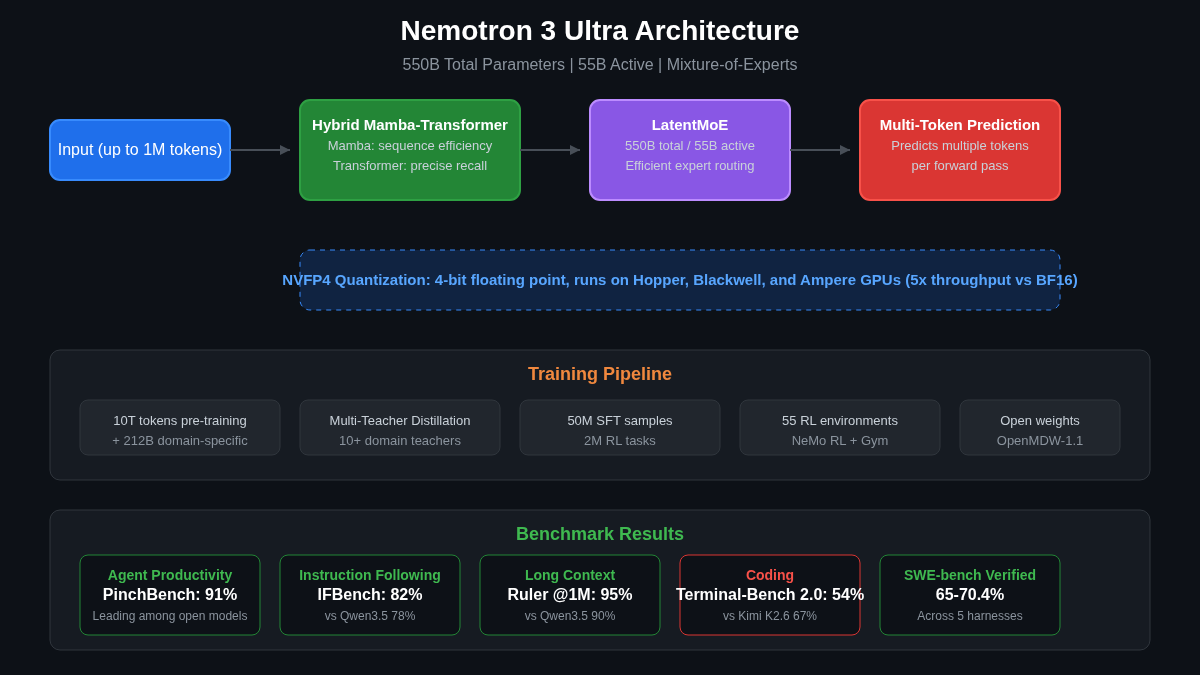
Architecture: Mixture of Experts (MoE) with 550B total parameters and 55B active per token
Platforms: API (OpenRouter, build.nvidia.com), local via Ollama, Hugging Face Transformers, vLLM
Variants: Nemotron 3 Ultra (reasoning model, 550B/55B MoE). Text input and output. Open weights under NVIDIA Open Model License.
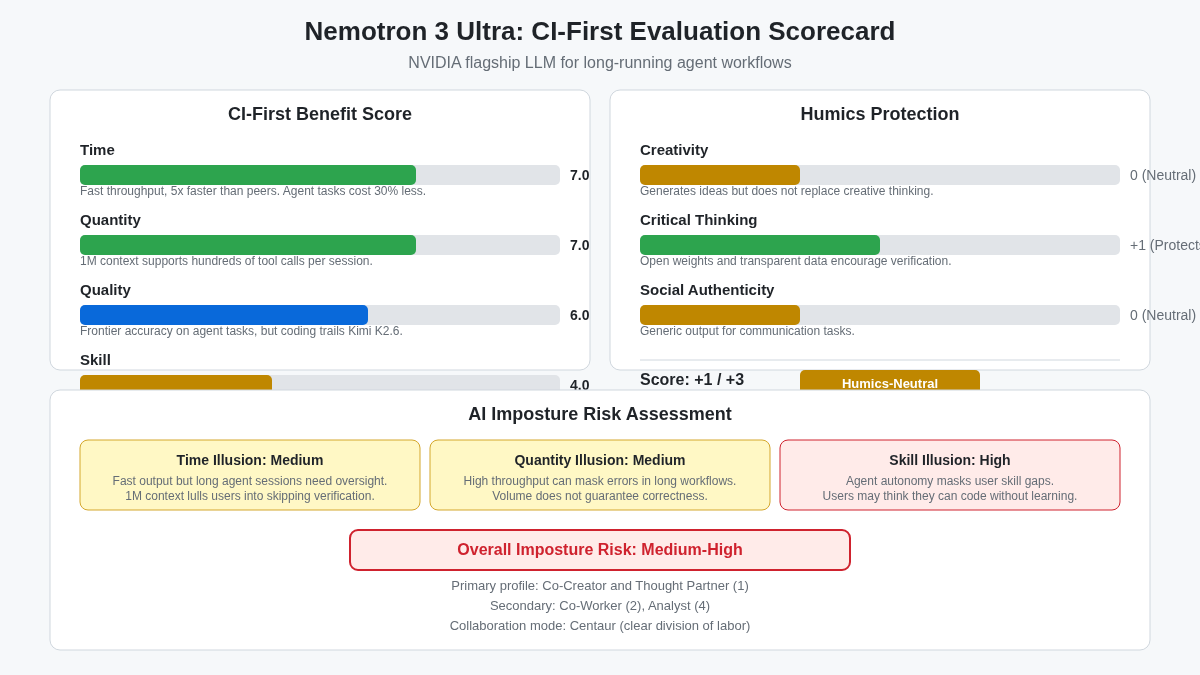
CI-First Benefit Score | 5.8 / 10 (CI-First Positive) |
Time / Quantity / Quality / Skill | 7 / 6 / 6 / 4 |
CI-First Profile | Co-Creator and Thought Partner (level 1) |
Humics Protection | Humics-Neutral (0) |
AI Imposture Risk | Medium |
User Sentiment | Moderately Positive (developer adoption signals) |
Pricing | Paid ($0.60/1M input, $3.60/1M output) |
Platforms | OpenRouter, build.nvidia.com, Ollama, vLLM, Hugging Face |
For detailed explanations of the CI-First evaluation terms used in this review — including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
The Problem
Large language models with strong reasoning capabilities are often locked behind proprietary APIs. Organizations that need data control, on-premise deployment, or fine-tuning cannot use these models for sensitive workloads. At the same time, many open-weights models trade reasoning depth for smaller parameter counts, which limits their performance on complex tasks.
The context window problem compounds this. Researchers and developers working with long documents, large codebases, or multi-source analysis need context windows that exceed the 128K or 200K limits of most open-weights models. Chunking and summarization workarounds introduce information loss and add workflow complexity.
Nemotron 3 Ultra addresses both gaps. NVIDIA built it as a reasoning model with 550B total parameters and 55B active per token (Mixture of Experts), paired with a 512K-token context window. The open-weights release under the NVIDIA Open Model License means organizations can download the model, run it on their own infrastructure, and modify it for domain-specific tasks.
The Outcome
A developer using Nemotron 3 Ultra can feed a large codebase into the context window and ask the model to find bugs, explain architecture, or generate new features with full project awareness. A researcher can submit a long document set and receive analysis that references specific sections rather than a summarized approximation.
The 55B active parameter count per token keeps inference cost competitive. At $0.60 per 1M input tokens and $3.60 per 1M output tokens on OpenRouter, the blended rate of $1.20 per 1M tokens is below the median for models in this performance tier. The MoE architecture means only 55B of the 550B parameters are active during any single token computation, which reduces compute requirements compared to a dense 550B model.
The open-weights license removes vendor lock-in. Organizations can deploy Nemotron 3 Ultra on their own GPUs using vLLM or Hugging Face Transformers, fine-tune it on domain-specific data, and maintain full control over data privacy. The trade-off is infrastructure cost: running a 550B-parameter MoE model requires substantial GPU resources even with only 55B active parameters.
Who Should Use Nemotron 3 Ultra
Learner Categories
Fellow Category | Description |
Students (Bachelor, Master) | Intermediate difficulty. Gain experience with a state-of-the-art open-weights reasoning LLM, learn prompt engineering for long-context tasks, and build coding assistance workflows. Relevant to UIT AI and Data Science programs. |
Professionals (career upskilling) | Intermediate. Deploy Nemotron 3 Ultra for long-document analysis, coding tasks, and research workflows. Relevant to UIT Software Development and URC research projects. |
Everyone (lifelong learners) | Beginner to Intermediate. Use the build.nvidia.com platform to explore AI capabilities, ask questions, and learn prompt design without local installation. |
U365 Institutes Alignment
Institute | Relevance | Why |
UIT (Technology, AI, Data Science) | High | Core tool for AI coursework, software development projects, and research involving long-context NLP tasks. |
UIB (Business Management, Entrepreneurship) | Medium | Useful for long-document processing and market analysis. |
UIC (Digital Communication, Marketing) | Medium | Supports content analysis and research tasks. |
UID (Digital Design, UX/UI) | Low | Not a primary design tool, but can assist with design documentation and specification writing. |
Skill level required: Intermediate. API usage requires programming knowledge. The build.nvidia.com interface requires no technical background.
Prerequisites: Basic programming knowledge for API integration. For self-hosting, experience with Python, Docker, and GPU infrastructure.
Typical time to first result: 5 minutes via build.nvidia.com chat. 30 minutes for first API call.
Typical time to competence: 2 to 3 hours of active use to learn effective prompting for long-context and reasoning tasks.
How Nemotron 3 Ultra Works
Inputs: Natural language prompts in English. Text-only input. Supports multi-turn conversation, system prompts, and tool-calling formats. The API accepts OpenAI-compatible requests via OpenRouter and build.nvidia.com.
Outputs: Text responses with configurable reasoning effort. The model supports structured output (JSON), function calling, and streaming responses.
Underlying Technology
Architecture: Mixture of Experts (MoE) with 550B total parameters and 55B active parameters per token. The MoE design activates only a subset of expert networks for each token, reducing per-token compute while maintaining the full capacity of a 550B model.
Reasoning: Nemotron 3 Ultra is a reasoning model. It supports configurable effort levels (low, medium, high). Lower effort balances speed and performance. Higher effort uses extended chain-of-thought reasoning for complex problems.
License: NVIDIA Open Model License. Weights available on Hugging Face.
Languages: English (primary).
Modalities: Text input, text output. No image or audio support.
Available Platforms
OpenRouter API, build.nvidia.com, Hugging Face Transformers, vLLM, Ollama. Available on Ollama (57.6K downloads as of August 2026).
API Pricing
$0.60 per 1M input tokens, $3.60 per 1M output tokens (OpenRouter). Blended rate: $1.20 per 1M tokens.
Context Window
512K tokens (524,288 tokens). This allows processing of large documents, codebases, and multi-source research materials in a single request without chunking.
Getting Started with Nemotron 3 Ultra
Required accounts: Free account on build.nvidia.com for the web chat interface. For API access, create an account on OpenRouter (openrouter.ai) to get an API key. No credit card needed for basic exploration on build.nvidia.com.
Installation: Web chat at build.nvidia.com requires no installation. For API use, use the OpenAI SDK with base_url set to the OpenRouter endpoint. For local deployment, use Ollama (ollama run nemotron-3-ultra) or install vLLM or Hugging Face Transformers.
First-Time Configuration
1. Go to build.nvidia.com and sign up for a free account.
2. For API access, go to openrouter.ai, create an account, and generate an API key.
3. Install the OpenAI Python SDK: pip install openai. Set base_url to the OpenRouter endpoint.
4. For local deployment via Ollama: ollama run nemotron-3-ultra (requires sufficient GPU memory for 55B active parameters).
First 15 Minutes Checklist
Sign up at build.nvidia.com and send your first chat message.
Ask Nemotron 3 Ultra to explain a programming concept or debug a code snippet.
Paste a long document (over 10,000 words) and ask for a structured summary.
If using the API, make your first API call with a reasoning question using the Python SDK.
Compare Nemotron 3 Ultra's response to the same prompt in another LLM (Claude, GPT, or Gemini).
Result: You have tested Nemotron 3 Ultra's reasoning capability, long-context handling, and coding assistance, and you know whether the API or web interface fits your workflow.
Real Workflows
Workflow 1: Long-Context Research Analysis
Learner type: Students and Professionals (UIT, URC)
CI-First benefit tags: Time, Quality
Connects to: UDA thesis work, UIT AI Engineering program, URC research projects
Time estimate: 25 minutes (including verification)
What You Do vs What the Tool Does
Step | Who | Action |
Step 1 | You | Gather research materials (academic papers, reports, legal documents) that fit within the 512K token context window. |
Step 2 | You | Paste the documents into Nemotron 3 Ultra with a specific analytical question and set reasoning effort to high. |
Step 3 | Nemotron 3 Ultra | Processes all documents in context, cross-references between sources, and produces a structured analysis with references to specific sections. |
Step 4 | You | Verify key claims by checking the original source documents. Note where the model's summary differs from the source text. |
Step 5 | You | Write your own analysis using the verified findings. Store sources and analysis in your LIPS Digital Second Brain. |
Sample Prompt
You are a research analyst. Below are [N] documents about [topic]. For each document, extract: (1) key findings, (2) methodology, (3) limitations. Then write a 500-word synthesis comparing the perspectives across all documents. Cite specific passages from each source. Use high reasoning effort.
Documents: [paste documents]
Verification Checklist
Multi-Model Check: Run the same documents through Claude Sonnet 5 or GPT-5.6 and compare the extracted findings. Flag any statistics or claims that differ between models.
External Source: Manually verify at least 3 key claims by finding them in the original source documents.
Human Review: Share your synthesis with a colleague or advisor. Confirm the analysis is accurate and the citations match the source text.
CI-First Test: Can you explain the research findings in your own words without the AI output? [Y/N]
Workflow 2: Codebase Review and Bug Detection
Learner type: Students and Professionals (UIT)
CI-First benefit tags: Time, Quantity, Quality
Time estimate: 20 minutes (including verification)
What You Do vs What the Tool Does
Step | Who | Action |
Step 1 | You | Identify the codebase or file you want reviewed. Ensure it fits within the 512K token context window. |
Step 2 | You | Paste or upload the code with a specific review question (find bugs, suggest refactoring, explain architecture). Set reasoning effort to high for thorough analysis. |
Step 3 | Nemotron 3 Ultra | Analyzes the full codebase, identifies issues, and returns structured feedback with file references and severity ratings. |
Step 4 | You | Review each suggestion. Test the recommended fixes. Discard suggestions that do not apply to your codebase. |
Step 5 | You | Document the verified changes in your version control system and LIPS Digital Second Brain. |
Sample Prompt
You are a senior code reviewer. Review the following codebase for potential bugs, security issues, and architectural improvements. For each issue found, provide: (1) the file and line number, (2) a description of the problem, (3) a suggested fix with code. Prioritize issues by severity. Use high reasoning effort. Here is the code: [paste full codebase]
Verification Checklist
Multi-Model Check: Run the same code through Claude Sonnet 5 or GPT-5.6 and compare the issues each model identifies. Investigate discrepancies.
External Source: Run any suggested fixes through your test suite. Do not merge changes that break existing tests.
Human Review: Have a peer or senior developer review the AI-flagged issues. Confirm which are real and which are false positives.
CI-First Test: Can you explain and defend each code change without the AI output? [Y/N]
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | Strong savings for coding and long-context analysis tasks. A full codebase review that takes hours manually can be done in minutes. | 512K context window eliminates chunking and summarization overhead. MoE architecture with 55B active parameters keeps inference fast. |
Quantity | Moderate increase. Handles large document sets in a single request that would require multiple sessions with smaller-context models. | 512K token context allows processing of entire codebases or document collections at once. |
Quality | Moderate to strong. Reasoning model with configurable effort levels produces thorough analysis for complex problems. | 550B total parameter capacity with 55B active per token. NVIDIA training pipeline and data quality. |
Skill | Marginal to moderate. The model produces expert-looking code and analysis, but users must actively study the output to build lasting skill. | Open weights allow fine-tuning and inspection, which supports learning. But the model does not teach by default. |
Limits
Text-only input. No image, audio, or video support. Competing models like Gemini 3.7 Flash and GPT-5.6 offer multimodal capabilities.
550B total parameters require significant GPU resources for self-hosting. The 55B active parameter count helps, but deployment still demands multi-GPU infrastructure.
As a reasoning model at high effort, generation can be slow for simple questions where a non-reasoning model would suffice.
No native integration with Microsoft 365 or other enterprise productivity tools.
57.6K Ollama downloads indicates moderate but not widespread community adoption compared to more established open-weights models.
NVIDIA Open Model License is less permissive than MIT or Apache 2.0. Review the license terms before commercial deployment.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Low | The model produces responses at competitive speed. The 55B active parameter count keeps per-token compute manageable. No evidence of excessive latency masking as thoroughness. |
Quantity Illusion | Medium | The 512K context window can produce verbose outputs that appear comprehensive but contain redundant or superficial analysis. Users must verify that the volume of output corresponds to genuine analytical depth. |
Skill Illusion | Medium | The reasoning model produces detailed chain-of-thought explanations that can create false confidence. Users may accept the model's reasoning without independently verifying the logic. The high effort mode produces long reasoning traces that may substitute for the user's own thinking process. |
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Creator and Thought Partner (level 1). Nemotron 3 Ultra collaborates on coding, analysis, and problem-solving through multi-turn dialogue with configurable reasoning depth.
Secondary profiles: Co-Worker and Assistant (2) for drafting and code generation. Analyst and Tester (level 4) for structured analysis and verification tasks.
Collaboration Mode
Recommended mode: Centaur. The human defines the task, reviews the output, and makes final decisions. Nemotron 3 Ultra handles the heavy lifting of code analysis, document processing, and reasoning. The clear division of labor prevents over-delegation.
Alternative mode: Cyborg for rapid coding iteration where the developer and model trade changes in real-time. Use only when the developer has sufficient expertise to evaluate each iteration.
Mode rationale: Nemotron 3 Ultra's reasoning capability and 512K context make it powerful but also increase the risk of accepting long, detailed outputs without verification. Centaur mode keeps the human in the review seat.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 7 | Significant savings for coding and long-context tasks. 512K context reduces multi-step workflows to single requests. MoE architecture with 55B active parameters keeps inference competitive. |
Quantity | 6 | Moderate increase. Handles large document sets at once, but verbose reasoning output may include redundant analysis. |
Quality | 6 | Clear quality gains in coding and reasoning tasks. 550B total parameter capacity. Drops on tasks requiring multimodal input or specialized domain knowledge. |
Skill | 4 | Marginal skill benefit. The model produces expert output but does not teach by default. Open weights support learning through inspection, but most users will not dig into the architecture. |
CI-First Benefit Score: 5.8 / 10 (CI-First Positive)
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral | Nemotron 3 Ultra can spark ideas through dialogue, but it also generates complete outputs that may reduce the user's own creative effort. |
Critical Thinking | Neutral | The reasoning traces demonstrate structured thinking, but users may rely on the model's reasoning rather than developing their own analysis skills. |
Social Authenticity | Neutral | No direct impact on social or interpersonal dynamics. |
Humics Score: 0 (Humics-Neutral)
AI Imposture Risk Assessment
Time Illusion: Low. Competitive inference speed with no evidence of latency masking.
Quantity Illusion: Medium. Large context window can produce verbose output that appears comprehensive.
Skill Illusion: Medium. Detailed reasoning traces may substitute for the user's own thinking.
Overall: Medium.
Superhuman Usage Guidance
When to invite the tool: Long-context document analysis, codebase review, multi-step reasoning tasks, structured data extraction from large text sources.
When to keep the tool out: Tasks requiring multimodal input (images, audio), real-time conversation where latency matters, tasks where independent human reasoning is the learning goal.
U365 method integration: LIPS (Collect and Review phases), ULM (Career and Quality of Life domains), UP-Context (analysis of long personal or institutional documents).
Over-delegation warning: Nemotron 3 Ultra's detailed reasoning traces can create the illusion that the model has done your thinking for you. Always verify key claims against source documents and write your own synthesis from verified findings. Do not accept reasoning traces as a substitute for your own analysis.
What Users Say
Aggregate Rating Table
Platform | Rating | Number of reviews |
Hugging Face | Model page active, community engagement | Open weights available |
Ollama | Available as nemotron-3-ultra | 57.6K downloads |
OpenRouter | Available for API access | Pricing: $0.60/1M input, $3.60/1M output |
Trustpilot | No reviews found on Trustpilot. | |
G2 | No reviews found on G2. | |
Capterra | No reviews found on Capterra. | |
Product Hunt | No reviews found on Product Hunt. | |
No reviews found on Reddit. | ||
Futurepedia | No reviews found on Futurepedia. | |
FutureTools | No reviews found on FutureTools. |
What Users Praise
Nemotron 3 Ultra is too new for substantial review aggregation on commercial platforms. The strongest community signal comes from Ollama, where the model has 57.6K downloads, indicating moderate developer adoption. The Hugging Face model page shows active community engagement with the open-weights release. Developer discussions note the 512K context window and NVIDIA Open Model License as key features. The competitive API pricing ($0.60/1M input, $3.60/1M output on OpenRouter) is noted as a positive compared to more expensive proprietary models.
What Users Complain About
No structured complaint data is available from review platforms given the model's recent release. From analysis, the main concerns are: the 550B total parameter count makes self-hosting expensive compared to smaller open-weights models. The text-only modality limits use cases that require image or audio processing. The NVIDIA Open Model License is less permissive than MIT or Apache 2.0, which may restrict some commercial use cases. The 57.6K download count on Ollama is moderate compared to more established open-weights models with millions of downloads.
Sentiment Summary
Overall sentiment: Moderately Positive (based on developer adoption signals)
Moderate developer adoption (57.6K Ollama downloads)
Competitive API pricing on OpenRouter
512K context window as a key differentiator
Open weights under NVIDIA Open Model License
Text-only modality as a limitation
High infrastructure cost for self-hosting
U365 Editorial Note
User sentiment aligns with the CI-First evaluation. The 57.6K Ollama downloads and competitive pricing support the Time score of 7 (users adopt it for efficient long-context tasks). The text-only limitation and moderate adoption rate support the Quantity score of 6 (capable but not transformative). The skill illusion risk (Medium) is consistent with the model's detailed reasoning traces, which users may accept without independent verification. The model's open-weights approach is a positive signal for the Skill dimension, but the score remains at 4 because most users will not engage with the model's internals.
Comparison and Alternatives
Alternative | Choose [Alternative] if... | Choose Nemotron 3 Ultra if... |
You want a lower-cost open-weights alternative with strong reasoning benchmarks. | You need a 512K context window and NVIDIA build quality. | |
You need bilingual Chinese-English capability and a 1M context window. | You prefer NVIDIA's reasoning model with competitive OpenRouter pricing. | |
You need multimodal input (images, audio) and the highest available benchmark scores. | You need open weights and self-hosting capability. | |
You want the top-ranked model overall with strong writing quality. | You need open weights at a lower API price. | |
You need a very large open-weights model with strong agentic performance. | You want a more focused reasoning model with 512K context. |
Where Nemotron 3 Ultra is clearly better
Open weights under NVIDIA Open Model License at 550B/55B-active MoE makes it one of the most capable openly available reasoning models. The 512K context window is competitive for long-document processing. The $0.60/1M input and $3.60/1M output pricing on OpenRouter is below the median for models in this performance tier.
Where Nemotron 3 Ultra is clearly worse
It lacks multimodal input (no image, audio, or video). The NVIDIA Open Model License is less permissive than MIT or Apache 2.0. Self-hosting requires substantial GPU infrastructure for the 550B-parameter MoE architecture. Community adoption (57.6K Ollama downloads) is moderate compared to more established open-weights models.
Verdict and Next Steps
Who should adopt it: Developers, researchers, and organizations that need an open-weights reasoning LLM with a large context window and competitive API pricing. Particularly valuable for teams working with long documents, large codebases, or multi-source research analysis.
When: Now, if you have a specific need for long-context processing or reasoning tasks. If your tasks are multimodal or require the highest benchmark scores, evaluate GPT-5.6 Sol or Claude Opus 5 as alternatives.
For what: Code review across large codebases, long-document analysis, research synthesis, and reasoning-intensive tasks.
UP-Context Prompt Pack
1. "I am a U365 Fellow working on [project description]. Act as my Co-Creator and Thought Partner (AI Profile 1). Review the following code and suggest improvements. For each suggestion, explain why it is better and what trade-off it involves. Use high reasoning effort. Code: [paste code]"
2. "You are my research analyst (AI Profile 4: Analyst and Tester). I am analyzing [topic] across [N] sources. Below are the documents. Extract the key findings from each, note where sources disagree, and write a 300-word synthesis. Cite specific passages. Use high reasoning effort. Documents: [paste documents]"
3. "I am learning [programming language or concept]. Act as my Coach and Tutor (AI Profile 3). Explain [concept] with a practical example. Then give me an exercise to complete myself. Do not write the solution. Let me try first."
Related U365 content:
U365's Recommendations to Learn More
This curated selection of resources helps you go deeper into Nemotron 3 Ultra's architecture, deployment, and practical use. All links were verified as active as of 2026-09-03.
Official learning resources
Video tutorials and channels
Written tutorials and deep-dive articles
Community and social
We curate these resources by content quality, not source type. Individual creators and community experts are included when their work teaches something the post itself does not cover. All links were verified as active on 2026-09-03.
Glossary
CI-First Benefit Score
The CI-First Benefit Score evaluates an AI tool across four dimensions: Time saved, Quantity of usable output, Quality improvement, and Skill development. Each dimension is scored 0-10, and the average produces the overall score. For Nemotron 3 Ultra, the score is 5.8/10 (CI-First Positive), reflecting strong time savings for long-context tasks (7), moderate quantity gains (6), moderate quality improvements (6), and marginal skill benefit (4). The score indicates a genuinely useful tool that saves time and improves output quality without building lasting independent capability by default.
CI-First Profile
The CI-First Profile classifies an AI tool by how it collaborates with the human user. The five levels are: (level 1) Co-Creator and Thought Partner, where AI collaborates on creative and analytical work through multi-turn dialogue; (level 2) Co-Worker and Assistant, where AI handles drafting, code generation, and routine tasks; (level 3) Coach and Tutor, where AI guides learning and skill development; (level 4) Analyst and Tester, where AI performs structured analysis and verification; (level 5) Challenger and Devil's Advocate, where AI pushes back on assumptions and stress-tests ideas. Lower level numbers indicate higher AI autonomy in the collaboration. Nemotron 3 Ultra's primary profile is Co-Creator and Thought Partner (level 1), meaning it collaborates on coding, analysis, and problem-solving through multi-turn dialogue with configurable reasoning depth. Its secondary profiles are Co-Worker and Assistant (level 2) for drafting and code generation, and Analyst and Tester (level 4) for structured analysis and verification tasks.
Humics Protection Badge
The Humics Protection Badge assesses whether an AI tool protects or erodes human qualities across three dimensions: Creativity, Critical Thinking, and Social Authenticity. Each dimension is rated as Protects (+1), Neutral (0), or Erodes (-1). Nemotron 3 Ultra scores 0 (Humics-Neutral) with Neutral ratings across all three dimensions. The model can spark ideas through dialogue but also generates complete outputs that may reduce the user's own creative effort. Its reasoning traces demonstrate structured thinking but may lead users to rely on the model's reasoning rather than developing their own analysis skills.
AI Imposture Risk
AI Imposture Risk identifies three traps that create false confidence: Time Illusion (appearing fast while masking latency), Quantity Illusion (producing verbose output that looks comprehensive but lacks depth), and Skill Illusion (detailed reasoning traces that substitute for the user's own thinking). Nemotron 3 Ultra has an overall risk of Medium. Time Illusion is Low (competitive inference speed). Quantity Illusion is Medium (the 512K context window can produce verbose, superficial output). Skill Illusion is Medium (detailed chain-of-thought explanations may create false confidence).
User Sentiment
User Sentiment aggregates ratings and feedback from review platforms (Trustpilot, G2, Capterra, Product Hunt, Reddit) and developer platforms (Hugging Face, Ollama, OpenRouter). For Nemotron 3 Ultra, overall sentiment is Moderately Positive, based on developer adoption signals. The model has 57.6K Ollama downloads and an active Hugging Face community page. No reviews were found on commercial review platforms given the model's recent release. The sentiment aligns with the CI-First evaluation: users adopt it for efficient long-context tasks and competitive pricing, while noting the text-only limitation and high self-hosting costs.




Comments