
Phi-4: A 14B Open-Weight Model for Local and Azure Reasoning Work

Updated: 6 days ago
Status: Active | Last tested: 2026-08-24 (phi4) | Re-check: trigger-based (max 6 months)

Tool Snapshot
Tagline: Microsoft's compact 14B text model for reasoning, coding, and controlled deployment.
Category: Large Language Model
Primary use cases:
Draft and check solutions for structured math or logic problems
Explain technical concepts with a requested teaching format
Generate and review code under executable test conditions
Run private text workflows on approved local hardware
Deploy a managed chat-completion endpoint through Microsoft Foundry
Pricing summary: The downloadable weights use the MIT license and have no per-token license fee, but local compute, storage, electricity, and operations still cost money. Artificial Analysis reported Microsoft API pricing of $0.125 per 1M input tokens and $0.50 per 1M output tokens, with a $0.16 blended rate, on 2026-08-24 [4]. The Microsoft Foundry catalog links to pricing but did not expose one fixed Phi-4 price in the retrieved page [2]. Confirm current regional and deployment pricing before use.
Official links:
Official model card: https://huggingface.co/microsoft/phi-4
Microsoft Foundry catalog: https://ai.azure.com/catalog/models/Phi-4
Ollama library: https://ollama.com/library/phi4
Independent model page: https://artificialanalysis.ai/models/phi-4
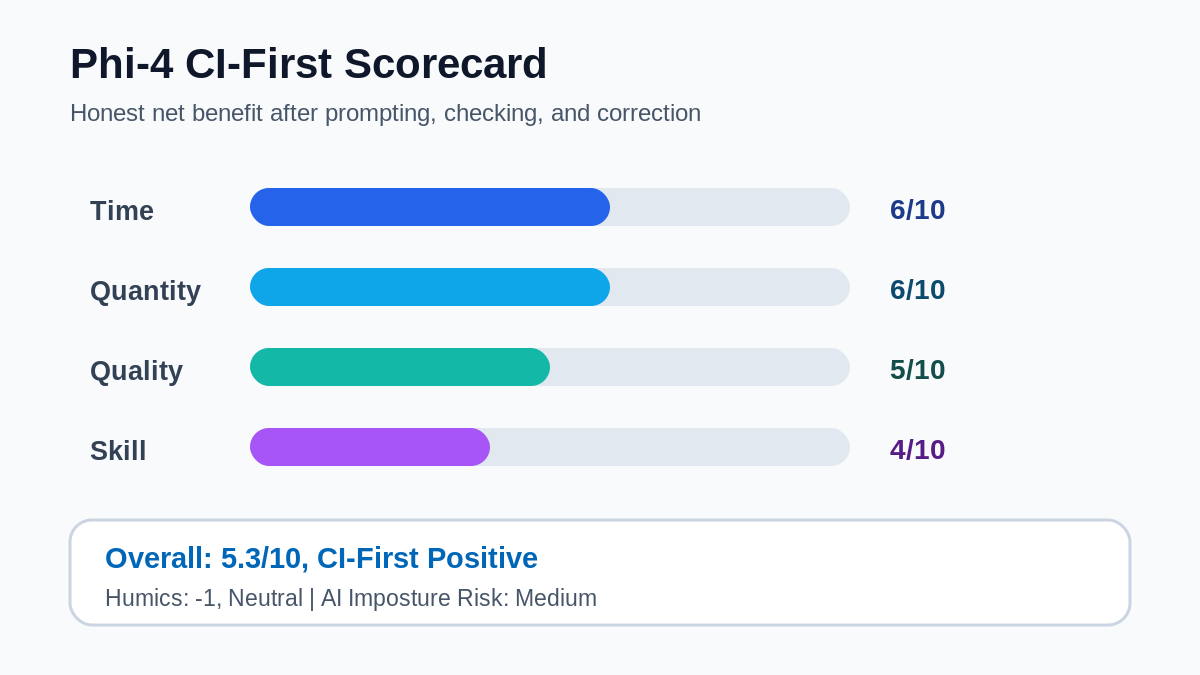
CI-First Benefit Score | 5.3/10 CI-First Positive |
Time / Quantity / Quality / Skill | 6 / 6 / 5 / 4 |
CI-First Profile | Co-Worker and Assistant |
Humics Protection | Neutral (-1) |
AI Imposture Risk | Medium |
User Sentiment | Insufficient review data for rating |
Pricing | MIT (free weights), API $0.125/$0.50 per 1M tokens |
Platforms | Hugging Face, Ollama, Microsoft Foundry, Transformers |
Context / Parameters | 16K tokens / 14B parameters (MIT license) |
For detailed explanations of the CI-First evaluation terms used in this review — including CI-First Benefit Score, CI-First Profile, Humics Protection Badge, AI Imposture Risk, and User Sentiment, see the Glossary at the end of this publication.
LLM specifications:
Release Date: 2024-12-12
Context Window: 16K tokens, reported as 16,384 tokens in Microsoft Foundry
Parameters: 14B class; Hugging Face safetensors metadata reports 14,659,507,200 parameters
Architecture: Dense decoder-only Transformer, exposed through Phi3ForCausalLM in Transformers
Modalities: Text input and text output
Effort Levels: No separate low, medium, or high thinking controls are documented for this checkpoint
Available Platforms: Open weights through Hugging Face, local use through Ollama or Transformers, hosted inference providers, and managed deployment through Microsoft Foundry
Model Variant: Phi-4 text-generation chat checkpoint; Ollama tags include phi4:latest and phi4:14b
License: MIT
Local Deployment Note: Ollama lists a 9.1GB package with a 16K context window. Runtime memory depends on quantization, context use, and hardware.
Benchmark Claims: Official model-card results include MMLU 84.8, GPQA 56.1, MGSM 80.6, MATH 80.4, HumanEval 82.6, SimpleQA 3.0, and DROP 75.5 [1].
Independent Results: Artificial Analysis reports an Intelligence Index near 5, 41.9 output tokens per second, 2.44 seconds to first token, and an Omniscience Index of -55.7 [4].
Knowledge Cutoff: June 2024 for publicly available training data
Comparison References: Use the official model card for vendor benchmark claims, Ollama for the reviewed local package, and Artificial Analysis for current independent measurements.
The Problem
Many learners and small teams need a language model for reasoning, coding, and explanation, but they cannot justify a very large local model or a closed service for every task. They also need deployment choice when privacy, latency, or cost rules differ by project.
Phi-4 addresses this need with a 14B dense decoder-only Transformer, a 16K context window, text input and output, and MIT-licensed weights [1]. Microsoft Foundry lists the model as a chat-completion model in Preview with a 16,384-token window [2]. Ollama packages it as a 9.1GB local model [3].
Compact size does not remove model risk. The official card reports strong selected math, science, and coding results, but it also reports SimpleQA at 3.0 [1]. Artificial Analysis gives Phi-4 an Intelligence Index near 5 and an Omniscience Index of -55.7 [4]. You need a workflow that checks facts, calculations, code, and sources rather than trusting fluent output.
The Outcome
You can use Phi-4 to create a first draft, explain a technical concept, test an argument, or produce code without committing every task to a large hosted model. A local route can keep approved data inside your own runtime. Microsoft Foundry can reduce deployment work when your organization accepts its service terms and regional controls.
A useful outcome is a verified work product: a solved problem with checked steps, a code change that passes tests, a source table that matches original documents, or a lesson that the learner can explain without the model. These results can save time and increase usable output when you define an acceptance test before prompting.
Do not judge success by response fluency. Measure review time, error rate, source accuracy, test pass rate, and what the learner can reproduce independently. If those measures do not improve, use a different model or complete the task without AI.
Who Should Use Phi-4
Learner type | Difficulty | Typical return | Career path |
Students | Intermediate | Faster worked examples, code review, and guided practice after independent attempt | UIT technical study and research work in other institutes |
Professionals | Intermediate | Local drafting, structured analysis, coding support, and controlled endpoint deployment | UIT AI and software work, UIB operations, UIC technical communication |
Everyone | Beginner for basic chat, intermediate for safe use | Explanations, planning support, and personal knowledge processing | Lifelong learning with LIPS and CI-First practice |
U365 Institutes Alignment
UIT (Technology, AI, Data Science): High for model evaluation, local inference, coding, and deployment.
UIB (Business Management, Entrepreneurship): Medium for structured analysis and internal drafting.
UIC (Digital Communication, Marketing): Medium for technical explanations and content review.
UID (Digital Design, UX/UI): Low to Medium because Phi-4 is text-only and does not produce or inspect images.
Skill level required | Beginner for a short, low-risk chat. Intermediate for reliable learning and professional work. Advanced for self-hosting, security, monitoring, and Azure operations. |
Prerequisites | Basic prompt design, source checking, data classification, and the ability to test the requested output. Coding use requires a runnable test environment. |
Time to first result | About 10 to 20 minutes when Ollama or a Microsoft Foundry workspace already exists. |
Time to competence | Two to four weeks of repeated tasks with an error log, fixed checks, and independent practice. |
How Phi-4 Works
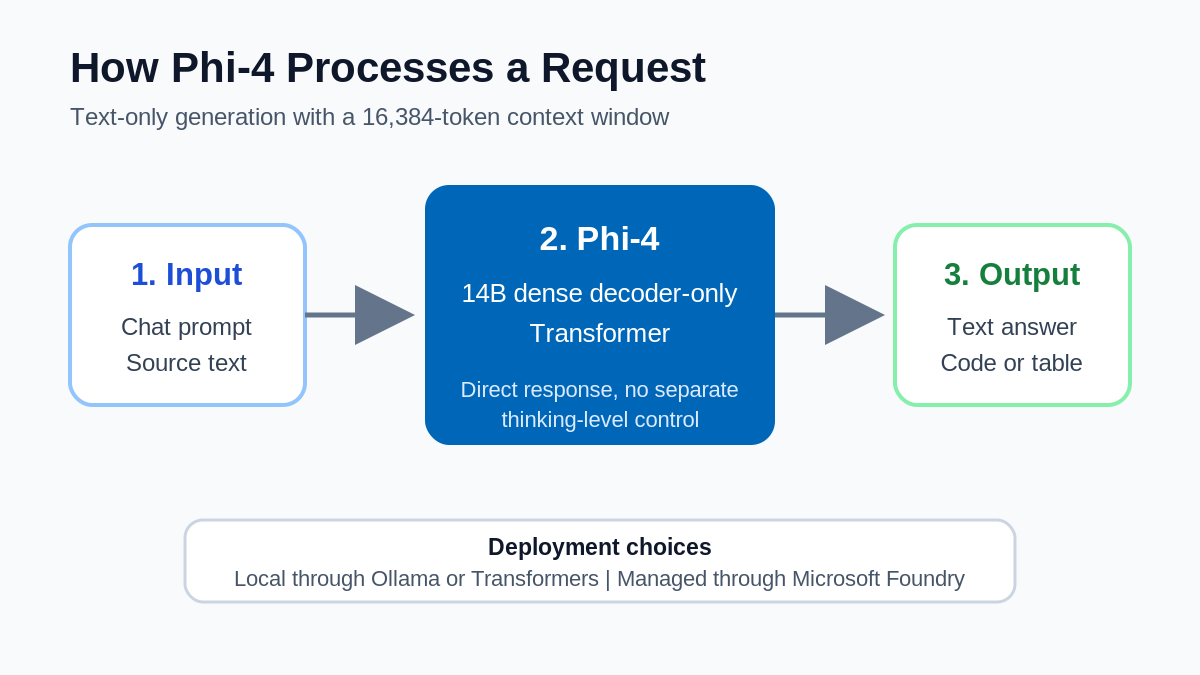
Inputs | Text prompts, chat history, source excerpts, code, equations expressed as text, and structured data represented in text. Phi-4 does not accept image input [4]. |
Outputs | Text answers, explanations, tables, code, classifications, summaries, and test plans. The serving layer may add JSON formatting or endpoint controls, but these are runtime features rather than model intelligence. |
Architecture | The official model card describes a 14B dense decoder-only Transformer. Hugging Face identifies the Transformers class as Phi3ForCausalLM and reports 14,659,507,200 parameters in the safetensors metadata [1]. Dense means all model parameters participate in inference rather than routing each token through a subset of experts. |
Context | The reviewed checkpoint accepts 16K tokens. Microsoft Foundry gives the exact value as 16,384 tokens [2]. Keep the prompt, source text, conversation history, and requested output within that limit. Shorter, relevant context usually reduces review work. |
Thinking controls | Phi-4 gives a direct response. The reviewed sources do not document separate low, medium, or high thinking settings [1][4]. You can request step checks or alternative solutions, but that prompting does not create a separate reasoning tier. |
Deployment | Download the open weights through Hugging Face and run them with a compatible Transformers stack, use the Ollama phi4 package locally, or deploy the catalog model through Microsoft Foundry [1][2][3]. Record the exact model, quantization, runtime, context setting, region, and data policy. |
Official benchmark claims | MMLU 84.8, GPQA 56.1, MGSM 80.6, MATH 80.4, HumanEval 82.6, SimpleQA 3.0, and DROP 75.5 [1]. These results use selected evaluations and settings. They do not prove quality on your task. |
Independent measurements | Artificial Analysis reports an Intelligence Index near 5, 41.9 output tokens per second, 2.44 seconds to first token, and an Omniscience Index of -55.7 based on its tested provider route [4]. Treat provider speed and price as time-sensitive measurements. |
Getting Started with Phi-4
Required access | Local use needs a computer approved for model downloads and enough storage and memory. Microsoft Foundry use needs an Azure account, a project with permission to deploy catalog models, and an approved billing path. Hugging Face use needs acceptance of the MIT terms and a compatible runtime.
Installation
Installation paths 1. Ollama: install the current Ollama release, then run ollama run phi4. Confirm that the downloaded tag identifies phi4 or phi4:14b, uses the intended quantization, and exposes the required context setting [3]. 2. Transformers: use the official microsoft/phi-4 repository with a supported Transformers release. Pin package and model revisions. Do not run unreviewed remote code. 3. Microsoft Foundry: open the Phi-4 catalog entry, review lifecycle, license, region, price, data controls, content filters, and quota, then deploy through an approved project [2]. 4. Production: add authentication, least privilege, rate limits, logging, retention rules, prompt-injection defenses, evaluation tests, and a rollback process.
Hardware note | Ollama lists a 9.1GB model artifact [3]. Plan additional memory for the runtime, context cache, and operating system. Actual CPU or GPU memory depends on quantization and context length. Test on the target machine before committing to local deployment.
First 15 minutes checklist
First 15 minutes checklist ☐ Record the exact model tag, runtime, quantization, and context setting. ☐ Read the MIT license and the selected provider's data terms. ☐ Send one short prompt with a required answer format. ☐ Test one factual claim against an external source. ☐ Run one code or calculation result in an independent tool. ☐ Save the prompt, output, correction, latency, and final decision.
Result | You have one verified Phi-4 result and a deployment record. You also know whether local or Microsoft Foundry use fits your privacy, cost, and operations requirements.
Real Workflows
Workflow 1: Build a Verified Technical Explanation
Learner type: Student, instructor, analyst, or professional learner
CI-First benefit tags: Time, Quality, Skill
Connects to: UP-Context prompting, UNOP active recall, LIPS evidence storage, and UIT technical learning
Time estimate: 35 to 60 minutes, including independent checks
Step 1 | You attempt the problem and record what you understand, what is uncertain, and the exact learning goal. | Phi-4 does nothing until your attempt is complete. |
Step 2 | You provide your attempt, a trusted source excerpt, and a required teaching format. | Phi-4 diagnoses gaps and explains one step at a time. |
Step 3 | You answer three recall questions without assistance. | Phi-4 checks the answers against the supplied source and labels uncertainty. |
Step 4 | You ask for one counterexample and one alternative method. | Phi-4 proposes candidates that you test independently. |
Step 5 | You write a short explanation in your own words. | Phi-4 compares it with the acceptance criteria but does not rewrite your final answer. |
Step 6 | You approve, correct, or reject each claim. | Phi-4 formats the verified notes for LIPS. |
Sample prompt:
Profile: Act as a Coach and Tutor. Context: I attempted this technical problem and included a trusted source excerpt. My attempt is: [paste]. My uncertainty is: [state it]. Task: Diagnose the first incorrect step, ask me one question, then explain only the concept needed for the next step. Constraints: Use only the supplied source for factual claims. Do not give the final solution until I submit a corrected attempt. Output: diagnosis, one question, one short explanation, and one practice item.
Verification checklist:
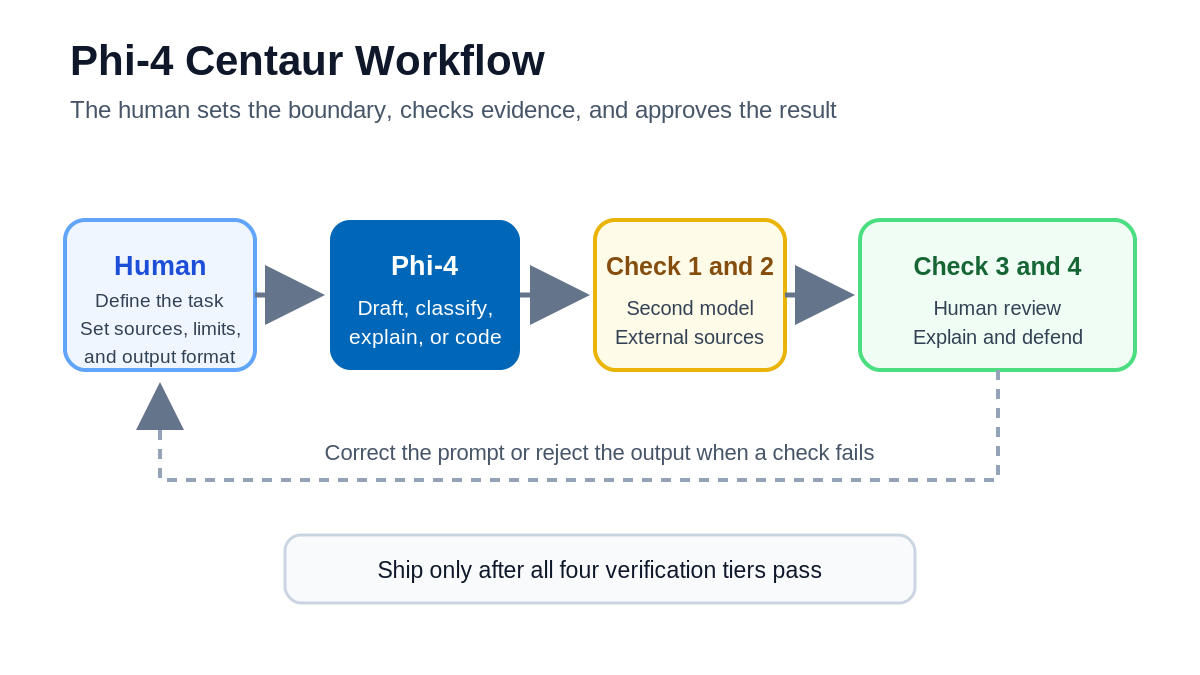
☐ Multi-Model Check: Ask a second model from a different provider to inspect the final explanation and identify any disputed step.
☐ External Source: Check definitions, equations, and claims against the course text, official documentation, or a primary source.
☐ Human Review: An instructor or qualified peer checks the learning objective, technical accuracy, and whether the explanation matches your level.
☐ CI-First Test: Close Phi-4 and explain the concept, solve a similar item, and defend each step without the model.
Workflow 2: Compare Local and Microsoft Foundry Deployment
Learner type: UIT learner, developer, AI engineer, or IT operations professional
CI-First benefit tags: Time, Quantity, Quality
Connects to: UIT AI systems practice, CARE Review, Microsoft 365 governance, and U.Copilot orchestration
Time estimate: 90 to 180 minutes after access and installation are ready
Step 1 | You create 20 representative prompts, expected properties, forbidden outputs, and pass thresholds. | Phi-4 does nothing until the test set is fixed. |
Step 2 | You deploy one pinned local build and one pinned Microsoft Foundry endpoint when policy permits. | Each route processes the same prompts under matched settings. |
Step 3 | You measure latency, input and output volume, review time, factual accuracy, code-test results, and policy failures. | Phi-4 produces outputs only. It does not grade itself. |
Step 4 | You review false statements, unsafe responses, formatting errors, and provider differences. | Phi-4 may classify your error notes after you verify them. |
Step 5 | You calculate total cost and choose a route based on quality, privacy, support, and operations. | Phi-4 formats the comparison but does not make the deployment decision. |
Step 6 | You document approval, monitoring, and rollback conditions. | Phi-4 creates a draft runbook for human review. |
Sample prompt:
Profile: Act as a Co-Worker and Assistant under a fixed evaluation protocol. Context: This is test case [ID] for Phi-4. Task: Answer the prompt using the required schema. Constraints: Do not mention or infer the expected answer. Use NOT KNOWN when the evidence is insufficient. Do not add fields. Output: valid JSON with test_id, answer, evidence_used, uncertainty, and refusal_reason.
Verification checklist:
☐ Multi-Model Check: Run the disputed test cases through a second model from a different provider and compare facts, refusals, and code behavior.
☐ External Source: Check factual cases against primary sources and execute every code case in an isolated test environment.
☐ Human Review: Security, domain, academic, and operations reviewers inspect data handling, error classes, cost, and release thresholds.
☐ CI-First Test: Explain the evaluation method, reproduce the score calculation, and defend the deployment choice without relying on Phi-4's own claims.
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence | Practical value |
Time | A 14B model can run through local or managed routes with less operational demand than much larger models | Ollama lists a 9.1GB package; Foundry supplies managed deployment [2][3] | Faster setup for suitable teams after controls exist |
Quantity | One model can draft explanations, code, tables, and test plans | Text-generation checkpoint and chat format [1] | More candidate work under one prompt interface |
Quality | Official results are strong on selected math, science, and code tasks | MATH 80.4, GPQA 56.1, HumanEval 82.6 [1] | Useful first-pass reasoning when checks pass |
Skill | Coach-style prompts can support guided practice | The model can explain steps and respond to learner attempts | Moderate value only when the learner recalls and reproduces the work |
Limits
Limits Phi-4 is text-only and cannot inspect images, audio, or video. The 16K context window is short beside current long-context models. The knowledge cutoff is June 2024, so current facts need external retrieval. The official SimpleQA score is 3.0, which warns against unsupported factual use [1]. Artificial Analysis reports an Intelligence Index near 5 and an Omniscience Index of -55.7 [4]. The reviewed checkpoint has no separate thinking-level controls. Local privacy depends on your runtime, access controls, logging, and data handling. Microsoft Foundry deployment cost and availability vary by region, lifecycle, quota, and deployment type.
AI Imposture Risk
Trap | Rating | Evidence and control |
Time Illusion | Medium | Fast drafting can be offset by prompt repair and verification. Use a time budget and stop when review cost exceeds the saving. |
Quantity Illusion | Medium | Fluent output can hide factual or reasoning defects. Limit volume, require source labels, and test a sample before expansion. |
Skill Illusion | High | The model can produce solved problems and working-looking code for users who cannot judge them. Require an independent attempt, executable tests, active recall, and a human assessor. |
Overall | Medium | One trap is High and two are Medium, but staged verification and Centaur boundaries provide clear controls. |
U365 Co-Intelligence Rating
CI-First Profile
Primary | Co-Worker and Assistant. Phi-4 drafts, classifies, explains, and codes under human direction. |
Secondary | Coach and Tutor; Analyst and Tester. It can guide a learner or inspect a candidate result when the human supplies checks. |
Collaboration Mode
Recommended | Centaur. You define the task, evidence, test, and decision. Phi-4 handles the bounded generation step. |
Alternative | Cyborg for low-risk brainstorming or prompt iteration by a user who can identify defects quickly. |
Rationale | The model's compact deployment and fluent text support rapid work, but factual and independent evaluations do not justify unsupervised acceptance. |
CI-First Benefit Score
Dimension | Score | Reason |
Time | 6/10 | Local or managed generation can reduce drafting and explanation time, but checking remains material. |
Quantity | 6/10 | Phi-4 can produce several useful text formats, but only verified outputs count. |
Quality | 5/10 | Strong official selected-task results support moderate value, while factual and independent results require caution. |
Skill | 4/10 | Tutor use can support learning, yet answer delegation easily replaces practice. |
Overall | 5.3/10 | CI-First Positive. Calculation: (6 + 6 + 5 + 4) / 4 = 5.25, rounded half-up to 5.3. |
Humics Protection
Creativity | 0 | Phi-4 can propose options, but sustained use does not reliably strengthen original human work. |
Critical Thinking | -1 | Fluent answers can reduce source reading and independent problem solving when accepted too quickly. |
Social Authenticity | 0 | The model has no necessary social effect unless generated messages replace personal voice or human discussion. |
Total | -1 | Humics-Neutral. |
Superhuman Usage Guidance
Invite Phi-4 for bounded technical explanations, first drafts, code candidates with tests, source-labeled extraction, local experiments, and provider comparisons.
Keep Phi-4 out of final ethical decisions, confidential work without approved controls, current factual claims without retrieval, assessment that measures unaided competence, and tasks you cannot verify.
LIPS + CARE | Store prompts, sources, model version, output, corrections, and approval state as separate records. Apply Collect, Action Plan, Review, and Execute in order. |
ULM + EVA | Use the model to examine options and test an action plan, while you retain values, relationship, health, career, and financial decisions. |
UP-Context | State the AI Profile, your context, the bounded task, constraints, evidence rules, and output format. |
SL-OS | Route only approved content through the selected runtime and save verified outputs in OneNote, OneDrive, or SharePoint with their evidence. |
UNOP | Require independent attempts, active recall, spaced review, and reproduction without the model. |
Over-delegation warning | If Phi-4 writes every explanation, solution, or code change, your Human Intelligence can decline while output volume rises. That reduces CI-First. Keep regular unaided practice, explain every accepted result, and reject work you cannot defend. |
What Users Say
Aggregate Rating Table
Platform | Verified model-specific evidence at evaluation time | Interpretation |
Hugging Face | 699,640 recent downloads and 2,290 likes on 2026-08-24 [1] | Adoption signal, not a satisfaction rating |
Ollama | 7.7M downloads shown on the phi4 page; 9.1GB package and 16K context [3] | Strong local distribution signal, not a quality score |
Artificial Analysis | Intelligence Index near 5, 41.9 output tokens per second, 2.44 seconds to first token, and Omniscience Index -55.7 [4] | Independent measurement, not user sentiment |
Trustpilot | No model-specific reviews found at evaluation time | No rating claimed |
G2 | No model-specific reviews found at evaluation time | No rating claimed |
Capterra | No model-specific reviews found at evaluation time | No rating claimed |
Product Hunt | No model-specific reviews found at evaluation time | No rating claimed |
App Store | No model-specific reviews found at evaluation time | No rating claimed |
Google Play | No model-specific reviews found at evaluation time | No rating claimed |
No model-specific aggregate review rating found at evaluation time | No rating claimed | |
Futurepedia | No model-specific reviews found at evaluation time | No rating claimed |
FutureTools | No model-specific reviews found at evaluation time | No rating claimed |
What Users Praise
What Users Praise | No verified cross-platform review set supports a defensible praise ranking. The adoption signals show substantial interest in the official weights and Ollama package. Do not translate download counts into satisfaction. |
What Users Complain About | No verified cross-platform review set supports a defensible complaint ranking. The evidence-based concerns are the 16K context limit, text-only modality, 9.1GB local package, weak official SimpleQA result, and low independent factual-reliability measure. |
Sentiment Summary | Insufficient model-specific review data for a numerical or directional user-sentiment verdict. Adoption is strong, but satisfaction is unmeasured in this evaluation. |
U365 Editorial Note | The available signals support a conservative CI-First Positive rating rather than a Strong rating. Local availability and official selected-task results support Time and Quantity value. The factual and independent results support Medium AI Imposture Risk and a lower Quality score. User satisfaction data would not remove the need for task-level verification. |
Comparison and Alternatives
Where Phi-4 is clearly better
Where Phi-4 is better | Phi-4 combines a compact 14B design, MIT-licensed open weights, a standard Transformers route, an Ollama package, and a Microsoft Foundry catalog entry. This mix supports local experiments and managed deployment without changing the base checkpoint. |
Where Phi-4 is worse | The model is text-only, limited to 16K context, and has no separate thinking controls. Its official SimpleQA result is weak, and Artificial Analysis places its composite intelligence below many current models [1][4]. A larger or newer model may produce better verified quality, support more modalities, or accept much longer evidence sets. |
Routing rule | Choose the smallest model that passes your representative quality, safety, latency, privacy, and cost tests. Do not choose Phi-4 only because it is local or inexpensive. |
Alternative | Choose the alternative if | Choose Phi-4 if |
Phi-3 14B | You need an earlier Microsoft model with an established deployment and your tests favor it | You want Microsoft's newer 14B checkpoint and its stronger official comparison results [1] |
Qwen 2.5 14B Instruct | Your language, tool, or task tests favor Qwen and its runtime fits policy | You prefer the MIT-licensed Microsoft checkpoint and its local or Foundry deployment options |
Llama 3.3 70B Instruct | You can support a much larger model and need quality that your tests prove | You need a smaller 14B model with lower local resource demand |
GPT-4o-mini | You want a managed closed API and your tests favor its code or factual behavior | You need downloadable weights, an MIT license, local control, or Microsoft Foundry deployment |
Verdict and Next Steps
Adopt Phi-4 for bounded text tasks when you value MIT-licensed weights, local use, or Microsoft Foundry deployment and can verify every important result. Start with math, code, explanation, or structured analysis tasks that have clear tests. Choose a different model when you need current factual reliability, image input, a long context, separate reasoning controls, or higher measured task quality.
Who should adopt it | Intermediate learners, developers, educators, and teams that can define tests and control the selected runtime. |
When | At the start of a low-risk pilot after data classification, acceptance criteria, and a comparison model are ready. |
For what | Verified technical explanation, code candidates with tests, structured text analysis, and deployment experiments. |
UP-Context prompt pack
Prompt 1 | Profile: Coach and Tutor. Context: I attempted [problem] and included my work. Task: Diagnose the first wrong step and ask one question. Constraints: Do not give the final answer until I submit a correction. Output: diagnosis, question, explanation, practice item.
Prompt 2 | Profile: Analyst and Tester. Context: These labeled sources support a decision. Task: Extract claims, contradictions, and missing evidence. Constraints: Use only supplied text, cite source IDs, and write NOT FOUND for missing support. Output: evidence table and open questions. |
Prompt 3 | Profile: Challenger and Devil's Advocate. Context: This is my proposed code or plan. Task: Identify failure cases and assumptions. Constraints: Separate verified defects, possible defects, and tests needed. Output: risk, evidence, test, and human decision. |
Next step | Run one prompt pack item through a local build and a Microsoft Foundry endpoint when permitted. Compare verified quality, total review time, privacy controls, and total cost before selecting a route. |
Source note | Specifications and official benchmark claims use the Microsoft model card and Foundry catalog. Local package facts use Ollama. Current speed, cost, and independent measurements use Artificial Analysis. Provider measurements and prices can change.
Glossary
CI-First Benefit Score
A 0-to-10 score that measures net benefit after accounting for prompting, verifying, and correcting. It combines four dimensions: Time saved, Quantity of usable output, Quality of verified results, and Skill built. The arithmetic mean of the four dimension scores gives the overall. For Phi-4, the overall is 5.3/10, placing it in the CI-First Positive band (4.1-6.0).
CI-First Profile
One of five AI collaboration patterns: Co-Creator and Thought Partner, Co-Worker and Assistant, Coach and Tutor, Analyst and Tester, or Challenger and Devil's Advocate. Phi-4's primary profile is Co-Worker and Assistant, with secondary roles as Coach and Tutor and Analyst and Tester. The profile defines how the model participates in your work and what checks it requires.
Humics Protection Badge
A rating from -3 to +3 that measures whether a tool protects or erodes human creativity, critical thinking, and social authenticity. Each dimension is scored +1 (Protects), 0 (Neutral), or -1 (Erodes). Phi-4 scores -1 total (Critical Thinking -1, Creativity 0, Social Authenticity 0), placing it in the Humics-Neutral band (-1 to +1).
AI Imposture Risk
An assessment of how easily a tool's output can mislead users about real time saved, real output quality, or real skill built. Three traps are rated: Time Illusion, Quantity Illusion, and Skill Illusion, each Low, Medium, or High. Phi-4 has an overall Medium risk, with Skill Illusion rated High because the model can produce solved problems and working-looking code for users who cannot judge them.
User Sentiment
U365's Recommendations to Learn More
This curated set of resources helps you go deeper with Phi-4. Every link was verified as of 2026-09-03.
Official learning resources
Video tutorials and channels
Written tutorials and deep-dive articles
Community and social
These resources were selected for content quality, not source type. Individual creators and community experts are welcome when their tutorials teach something the post itself does not.




Comments