
AI-Driven Customer Segmentation
Updated: 3 days ago

UIB University 365 Institute of Business
Series Business AI Series
Duration 25 minutes
Business Management, Digital Entrepreneurship, Innovation, Finance, Leadership

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture
The Hook: Your Question, Answered
You have 10,000 customers in your CRM. You know they are not all the same, but you cannot manually sort them into meaningful groups. Who are your high-value customers? Who is at risk of churning? Who has untapped potential?
In this lecture, you will learn how to use AI to tackle this challenge in 15 minutes. The AI handles the data processing and pattern recognition. You handle the judgment and decisions. This is the CI-First approach: human intelligence orchestrates, AI amplifies.

What AI Customer Segmentation Actually Does
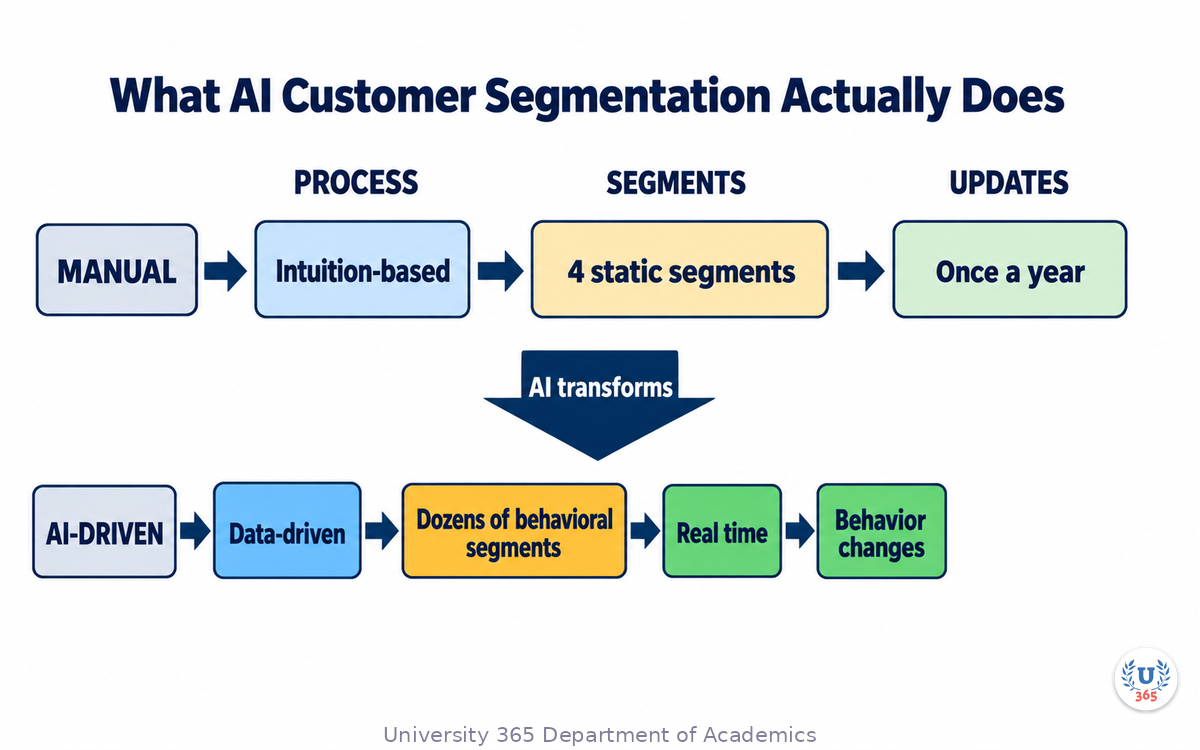
AI transforms customer segmentation from a manual, intuition-based process into a data-driven, continuously updated system. Instead of sorting customers into 4 static segments once a year, AI can identify dozens of behavioral segments that update in real time as customer behavior changes.
Step 1: Collect and Prepare Customer Data
Before AI can segment customers, you need data. The quality of your segments depends entirely on the quality of your data. AI can help you identify which data points are most useful for segmentation.
Step 2: Choose Your Segmentation Approach
AI supports multiple segmentation approaches: demographic (age, location, income), behavioral (purchase history, engagement, usage patterns), psychographic (values, attitudes, lifestyle), and value-based (CLV, revenue, profitability).
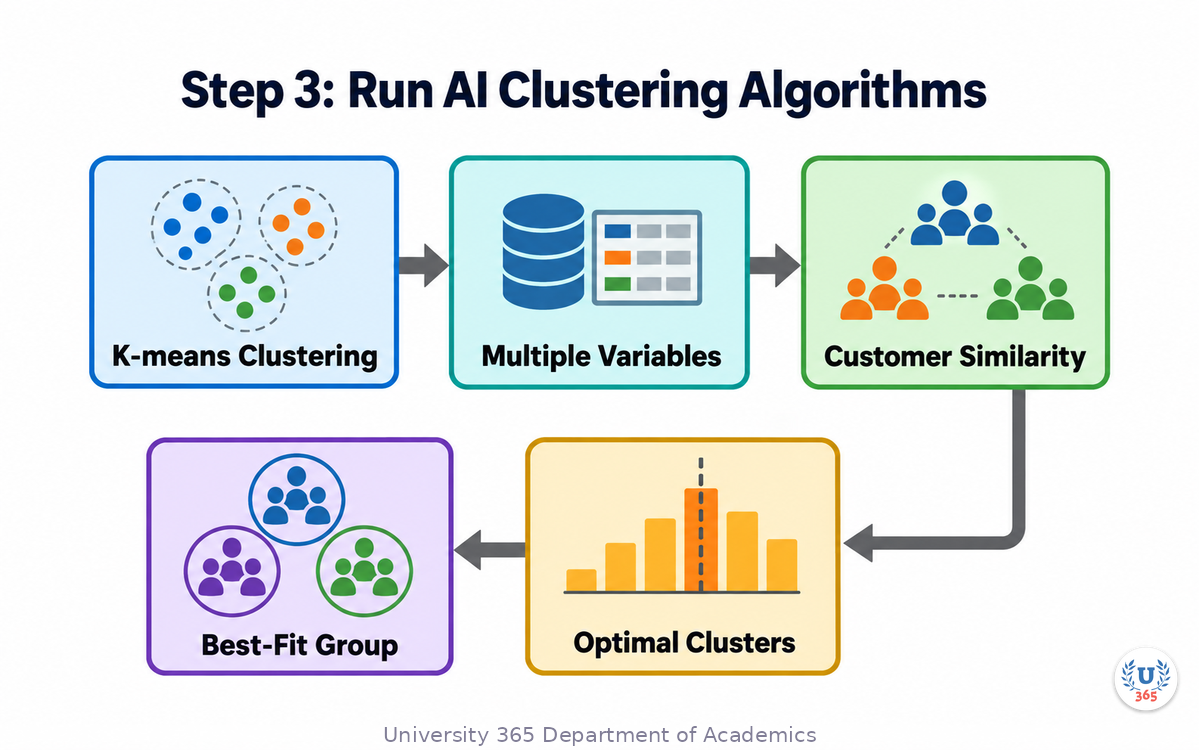
Step 3: Run AI Clustering Algorithms
K-means clustering is the most common AI segmentation technique. It groups customers into clusters based on similarity across multiple variables. AI determines the optimal number of clusters and assigns each customer to the best-fit group.
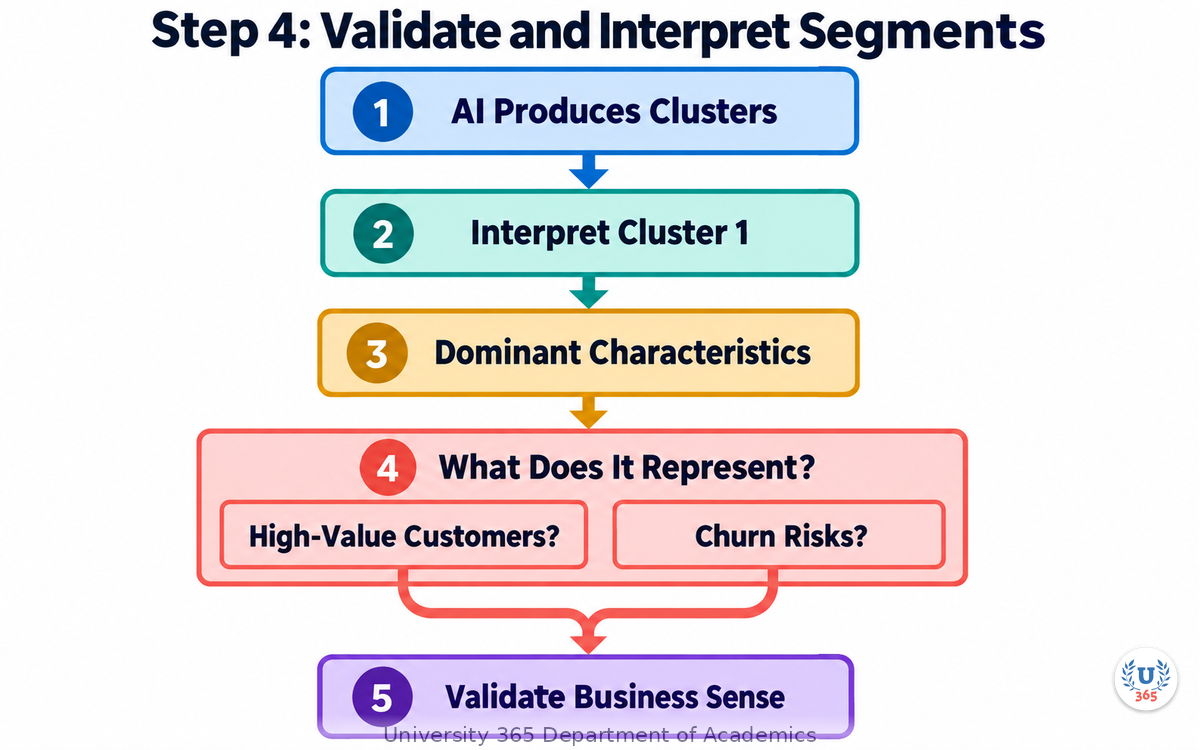
Step 4: Validate and Interpret Segments
AI produces clusters, but you must interpret them. What does Cluster 1 represent? Is it your high-value customers? Your churn risks? AI names clusters by their dominant characteristics, but you must validate whether the segments make business sense.
Step 5: Act on Segments with Targeted Strategy
Segments are useless without action. Each segment needs a specific strategy: acquisition, retention, upsell, cross-sell, or win-back. AI can recommend strategies based on segment characteristics, but you decide which strategies to execute.
Step 6: Turn Segments into a Plan Someone Can Run
A segmentation that ends in a chart of coloured clusters has not changed anything. Segmentation only pays when each group gets a decision attached to it: what you will offer them, what you will say, and what you will stop doing.
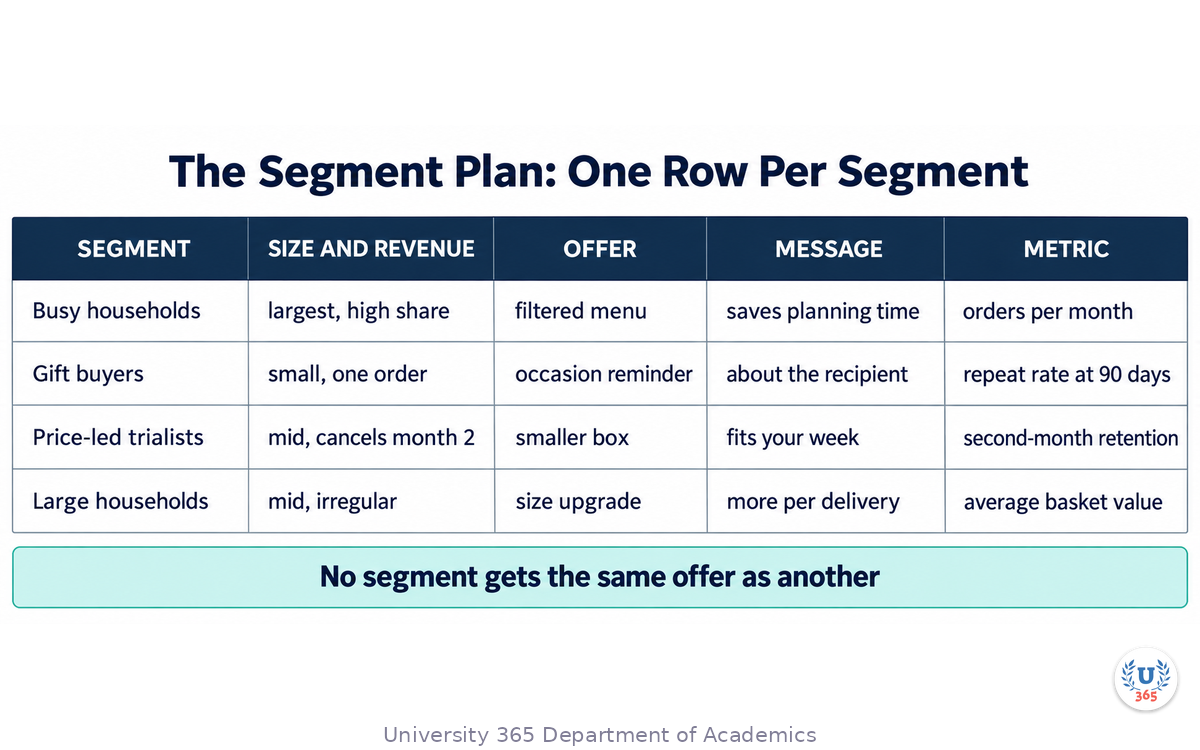
Build a segment plan with one row per segment and five columns. The segment name, in the customer's words rather than a cluster label. Its size and its share of revenue. The offer it should see. The message it should hear. And the metric that tells you the plan is working.
The fifth column is the one teams skip, and it is the one that turns segments into management. A segment plan without a metric per row becomes a slide, and slides do not get reviewed.
Worked example, figures illustrative. A subscription meal-kit business clusters its customers and names four segments. The first is busy households ordering weekly with two or more dietary constraints; they receive a filtered menu option and the message is about saving planning time, measured by orders per month. The second is gift buyers who order once and never return; they receive a gift reminder before the next occasion and the message is about the recipient, measured by repeat rate at ninety days. The third is price-led trialists who cancel in month two; the offer is a smaller box rather than a discount, measured by second-month retention. The fourth is large households ordering irregularly; they receive a size-upgrade prompt, measured by average basket value.
Notice what the fourth column does. Nobody is offered the same promotion. Each message exists because a segment behaves differently, and each metric exists because a different behaviour is the point.
Two tests before you commit the plan. Every segment must be large enough to be worth a distinct treatment, or it belongs inside a neighbouring segment. And every treatment must be something you will actually run, or the plan is a wish list with colours.
Choosing the Variables That Actually Separate Customers
Clustering will happily group customers on whatever you feed it, which is why the choice of variables decides whether the output is useful or merely tidy.
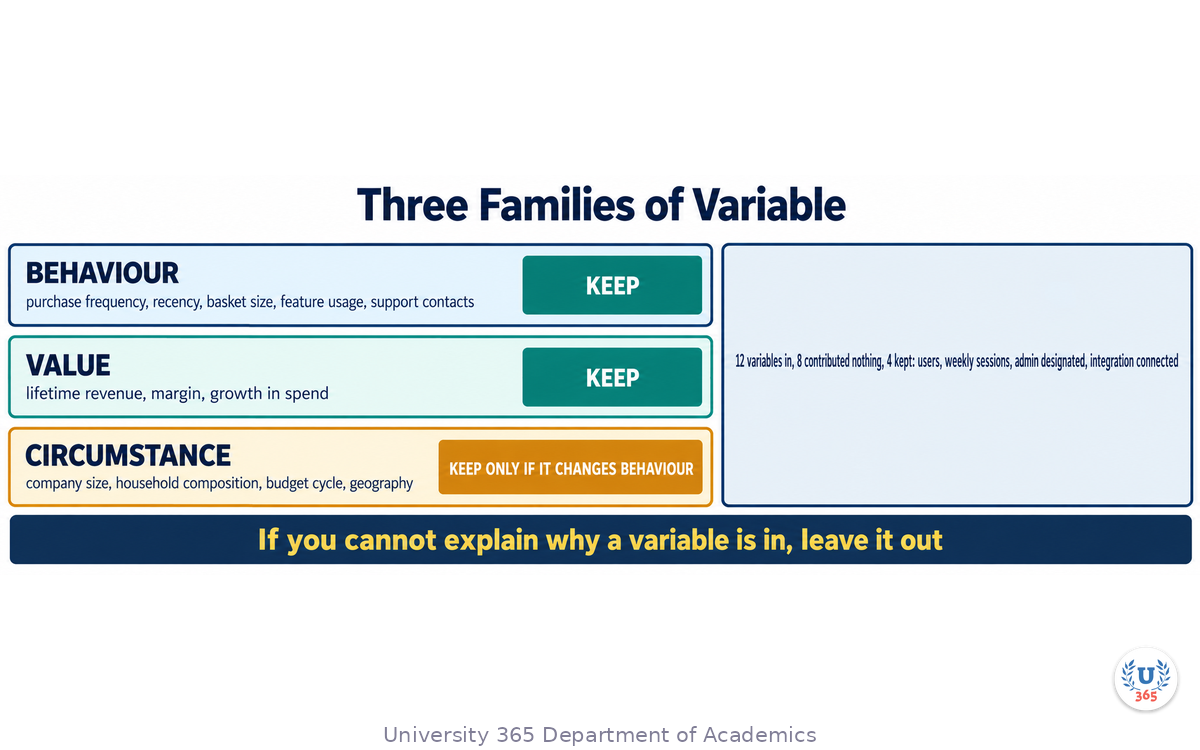
Three families of variable cover most commercial segmentation. Behaviour, which is what people did: purchase frequency, recency, basket size, feature usage, support contacts. Value, which is what they are worth: lifetime revenue, margin, growth in spend. And circumstance, which is what constrains them: company size, household composition, budget cycle, geography.
Leave demographic variables in only when they change behaviour. Age alone rarely separates customers in a way that changes what you would offer; age combined with a purchase pattern often does.
Worked example, figures illustrative. A business software team starts with twelve variables and finds that eight of them contribute nothing to the separation. Removing them leaves four: number of users, weekly active sessions, whether an administrator has been designated, and whether the account has connected an integration. Those four produce five interpretable groups, and each group maps to a different onboarding action. The original twelve produced a technically valid clustering that nobody could act on.
Two rules. Scale your variables before clustering, or a revenue figure in the thousands will dominate a session count in the tens. And prefer variables you can also observe for a new customer at signup, because a segment you cannot assign a new customer to is an analysis rather than a strategy.
Keep the variable list to a number you can defend in a sentence each. If you cannot explain why a variable is in the model, it probably should not be.
Choosing the Number of Segments
Most teams either accept whatever number the algorithm suggests or pick a number that sounds manageable. Both approaches skip the actual question, which is how many groups you can serve differently.
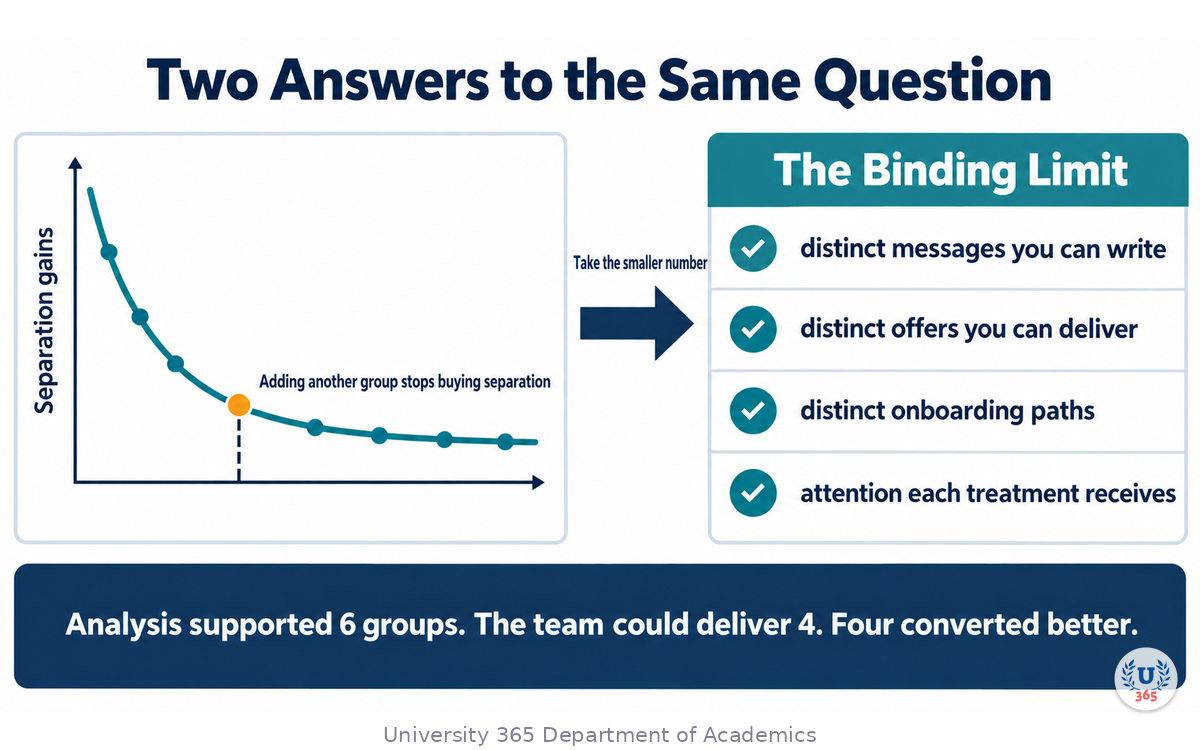
The technical answer comes from a measure of how tightly customers sit inside their group compared with how far apart the groups are. Read that curve for the point where adding another cluster stops buying much separation. When the improvement flattens, the extra cluster is splitting a group that behaves the same way.
The commercial answer is more binding. Count the distinct treatments you can actually deliver this quarter: distinct messages, distinct offers, distinct onboarding paths. That number is your ceiling, whatever the algorithm says.
Worked example, figures illustrative. A retail team's analysis supports six clusters. They can deliver four: two tailored email tracks, one onboarding change and one pricing option for a large-volume group. They merge the two weakest clusters into their nearest neighbours, and the four-group version converts better than the six-group version did, because each treatment received enough attention.
A useful test on the result. Name each segment in a sentence a colleague would recognise without seeing the analysis. If a segment can only be described by quoting the variables, it is a sub-group rather than a segment.
Revisit the number at a fixed interval rather than continuously. Clusters drift as the customer base changes, and re-running every month produces churn in the segments themselves, which makes the trends unreadable.
Dynamic Segmentation: When Membership Changes
Static segmentation assigns a customer once and stops. Most businesses have customers who move between groups, and the movement carries more information than the assignment.
Dynamic segmentation tracks each customer's group over time, and treats a change of group as an event worth responding to. A customer who moves from the low-engagement group into the high-engagement group is a signal. A customer who moves the other way is a warning.
Define the transitions you care about before you instrument them. Three cover most cases. Promotion, from a lower-value group to a higher one. Demotion, the reverse. And reactivation, from a dormant group back into an active one.
Worked example, figures illustrative. A software team tracks five groups and finds that accounts which designate an administrator within thirty days almost never demote in the following six months. That single transition makes administrator designation the target of the onboarding sequence, and the onboarding metric changes from activation to administrator designation.
Two operational requirements. Keep a dated record of every membership change, because the transition history is the analysis. And make the response automatic only where it is obvious, such as triggering an onboarding sequence; a demotion usually deserves a human review rather than an automated message.
Then keep the model current. A segmentation built on last year's behaviour will drift, and a segment plan built on a stale model produces messages that are subtly wrong in a way nobody can trace.
Testing a Segment Strategy
A segment plan is a set of claims: this group responds to this message better than the default. Claims get tested, and the test is cheaper than most teams assume.
Test one treatment at a time against a control, and hold everything else constant. If you change the message and the offer together, you learn nothing about which one moved the result.
Choose the metric before you run, and choose one that a result can move inside the test window. Orders per month and second-month retention are usable; lifetime value is not, because it arrives too late to inform the decision.
Worked example, figures illustrative. A team wants to test whether the price-led segment responds better to a smaller box than to a discount. They split the segment into three: control, smaller-box offer, and discount offer. Over eight weeks, smaller box retains better in month two while the discount produces more first orders and no improvement in the second. The plan adopts the smaller box for retention and keeps a discount only for the acquisition moment that needs it.
Two cautions on reading results. Check the sample size before you believe a difference, because two small numbers can differ by chance. And watch for the segment itself changing during the test, since a treatment that alters who joins a segment invalidates the comparison.
Write the result down whether it worked or not. A record of which treatments failed is what stops the next cycle from repeating them.
What Segmentation Cannot Tell You
Segmentation describes how your existing customers differ. It says nothing about customers you have never had, and that limitation is where most of the value in the analysis is quietly lost.
The first gap is the non-customer. Your data contains people who bought, not people who considered and declined. A segment model built on customers will describe your current market and miss the market you could reach, which is usually the larger one.
The second gap is causation. A group that buys more often is a description, not an explanation. It may buy more because of who they are, or because of how they arrived, or because of something you did. Clustering shows the difference and not the reason.
The third gap is the future. Groups are defined by past behaviour, and behaviour changes when your product, your pricing or your market changes. A segmentation is a snapshot and should carry the date it was taken.
The fourth gap is the individual. A segment is an average, and averages hide the customers at the edges, who are often the ones worth calling.
Close the gaps with small, cheap additions. Talk to a handful of people who did not buy, and record why. Read the support tickets of the largest accounts individually rather than as a group. And on every segmentation output, state the data window and the customer basis so a reader knows what they are looking at.
That combination, statistical grouping for the many and direct conversation for the few, is the CI-First pattern applied to segmentation: the model compresses thousands of records into patterns, and a named person decides what those patterns mean.
Data Quality: The Work Before the Model
Most segmentation projects that disappoint were decided before any algorithm ran, in the state of the customer data.
Check four things first, in this order. Is the identity of a customer consistent, so that the same person is one record rather than three. Is the timeline intact, so you can tell what happened and in what order. Are the numeric fields complete enough to cluster on, and is the missingness itself meaningful. And are the labels accurate, so a cancelled subscription is not still marked active.
The third check matters more than it appears. Missing data is rarely random: a customer with no support contacts may be perfectly happy or may have never been able to reach you. Treating those as identical collapses two different groups into one.
Worked example, figures illustrative. A subscription business discovers that its customer table holds one row per email address, and that a meaningful share of customers hold several. Merging them changes the size of the highest-value group, because a household appearing as four separate accounts was reading as four low-value customers. The same fix reveals that a group previously read as highly engaged was one person across four records.
Two practical rules. Build a documented definition of what one customer means, and apply it consistently, because segmentation inherits every inconsistency in that definition. And record the state of the data alongside the output, so a reader can tell whether a change in segments came from the customers or from the clean-up.
Budget for this work explicitly. In practice it consumes more of the calendar than the modelling, and a project that plans only for the modelling will either skip the cleaning or take twice as long as expected.
Reading a Cluster Result Without Fooling Yourself
Clustering always returns groups. Whether those groups mean anything is a separate question, and the answer comes from checking rather than from the chart.
Four checks catch most false results. Stability: does the same grouping appear when you rerun the model on a random half of the data? Separation: are the groups actually distinct, or does the algorithm split one continuous spread into bands? Interpretability: can each group be described in a sentence about behaviour? And usefulness: does a group suggest a different action?
A useful rule for the last two. If two groups would receive the same treatment, they are one group for commercial purposes, whatever the analysis says.
Worked example, figures illustrative. A team reruns their five-group model on half the data and gets a four-group result in which two of the original groups have merged. The merged pair turns out to differ mainly by a variable the team had included by habit, and they would have received identical treatment. The team keeps four groups and drops the variable.
Two traps to avoid. Do not name a cluster from the variable with the highest loading, because a cluster named for usage may differ from the others chiefly in tenure. And do not read a cluster's average as its behaviour: the median and the spread tell you whether the group is coherent or is two groups wearing one label.
Then write the interpretation down before you present, in plain sentences about what each group does. If the sentences cannot be written without quoting the variables, the result is not yet ready to act on.
Where Segmentation Fits in the Customer Lifecycle
Segmentation is most useful when it is applied at the point where the customer is, not as one model applied everywhere.
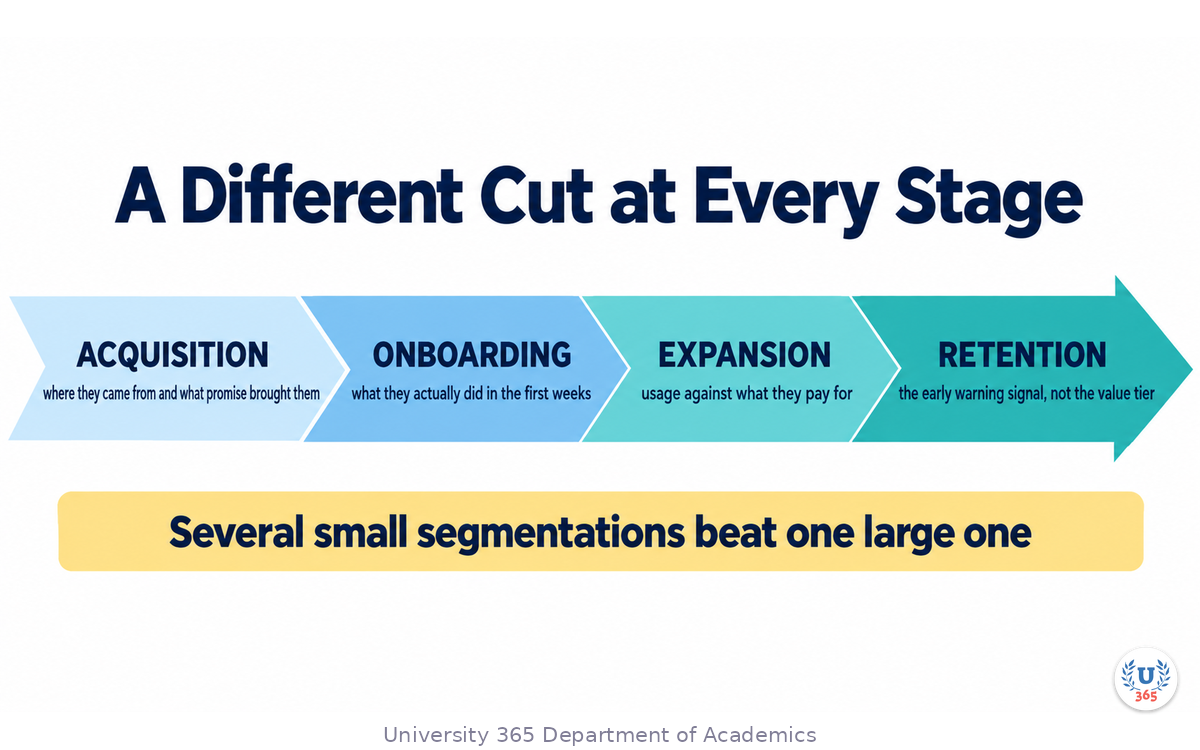
At acquisition, the useful cut is where customers came from and what promise brought them. Two customers who bought the same product through different channels usually behave differently afterwards, and a segment model built only on post-purchase behaviour will merge them.
At onboarding, the useful cut is what the customer has actually done in the first weeks. Designating an administrator, connecting a data source, inviting a colleague: each of those predicts later retention in ways that a demographic label does not.
At expansion, the useful cut is usage against entitlement. A customer using most of what they pay for is a different conversation from one using a fraction, and the second is a downgrade risk before it is an expansion opportunity.
At retention, the useful cut is the early warning signal rather than the value tier. A high-value customer in a decline pattern needs a different response from a high-value customer holding steady.
The practical consequence is that most businesses end up with several small segmentations rather than one large one, each fitted to the decision at that lifecycle stage. That is not a failure of ambition; it is what usable segmentation looks like, because each model is answering a specific question rather than describing the whole base.
Building the Habit: From Project to Operating Routine
Most segmentation work is a project with a start and an end, and most of its value is lost when the project ends.
Turn it into a routine by fixing the cadence, the owner and the output. A monthly refresh of the model, an owner who reviews the changes, and an output that is one page of movement rather than a full re-presentation.
The output should answer four questions each cycle. Which groups grew or shrank. Which transitions increased. Which treatment produced the movement. And what changes as a result of this month's read.
Worked example, figures illustrative. A team's monthly page shows two groups stable, one shrinking as customers graduate into a higher-value segment, and one growing because a new onboarding path is working. The action is to extend the onboarding path to a second cohort that has not yet received it.
Two habits make the routine survive. Put the numbers somewhere that does not need to be rebuilt each month, because regeneration is what kills recurring analysis. And attach the read to a decision meeting that already exists, rather than creating a separate one, so the review does not become a meeting people stop attending.
Keep the model honest about its age. A segmentation that has not been re-fitted for a year is still useful for describing behaviour, and its age should be stated whenever the output is used, because behaviour moves and a stale grouping produces messages that are almost right.
Segmenting on Value Without Ignoring Cost to Serve
Value segmentation usually ranks customers by revenue, and revenue is the wrong single number because it ignores what it costs to earn.
Build a contribution view instead: revenue minus the direct cost of serving that customer. Direct costs include support contacts, onboarding effort, account management time and any per-use platform cost. Those differ enormously between customers paying similar amounts.
The result is usually a four-way grid rather than a ranking. High revenue and low cost is the group to protect. High revenue and high cost is the group to re-engineer, often by moving the customer onto a self-service path. Low revenue and low cost is the group to automate growth into. Low revenue and high cost is the group to change or, occasionally, to stop serving.
Worked example, figures illustrative. A software team ranks accounts by revenue and finds a large customer at the top. Adding support contacts, onboarding hours and account management time reveals that the account consumes more service than it pays for, while a mid-ranked customer with a self-service configuration contributes more. The action is not to drop the large account but to change its service model, and the analysis makes that a deliberate decision rather than a drift.
Two cautions. Do not allocate shared costs to individual customers, because the allocations decide the answer rather than reporting it; keep the analysis to direct costs. And re-run the cost side at least twice a year, because service costs move as the product changes.
State the method next to the result. A contribution view that hides which costs were included invites the reader to assume none were.
Segmenting B2B Accounts When One Customer Is Several People
Business customers break the single-person assumption in most segmentation models, because the account and the people inside it behave differently.
Segment on three levels, and keep them separate. The account, which holds the commercial relationship and the contract value. The team within the account, which holds the usage pattern. And the individual user, whose engagement predicts whether the account renews.
The middle level is where most of the insight sits. A large account in which usage is concentrated in one team is a different risk from an account with the same total usage spread across four teams, because the first can lose its champion and collapse.
Worked example, figures illustrative. Two accounts each pay the same amount. In the first, ninety percent of usage comes from one department and one administrator. In the second, usage is spread across four departments with three administrators. The first is treated as a concentration risk with an action to broaden adoption before renewal; the second is treated as an expansion candidate. A revenue-only segmentation would have merged them.
Two operational rules. Make administrator count and breadth of usage first-class variables rather than derived notes. And review the account-level grouping and the team-level grouping separately, because an account that looks healthy in aggregate can hold a team that has stopped using the product entirely.
Keep the individual level for action rather than for grouping. Individual engagement is what you act on in a retention sequence, and treating individuals as segments produces a model too large to use.
The Privacy Rules That Apply to Segmentation
Segmentation uses personal data about identifiable people, and the analysis does not sit outside data protection law because it happens inside your own systems.
Three requirements carry most of the weight. First, a lawful basis for the processing you are doing, which is usually legitimate interests for analysis on your own customer base, written out rather than assumed. Second, transparency: your privacy notice should say that you analyse customer behaviour to group customers and tailor what you offer. A notice that says nothing about profiling does not cover it.
Third, the limits on automated decisions. Grouping customers for marketing and service is not the same as making a decision with a legal or similarly significant effect. Where a segment assignment does drive a consequential decision, such as eligibility for credit or a price that a person cannot contest, the safeguards for automated decision-making apply and a human route must exist.
Two practical rules for the analysis itself. Minimise: cluster on what the grouping needs rather than on everything available, and delete the intermediate extracts once the model is fitted. And watch the sensitive edge, because variables that look innocuous can act as proxies: a postcode or a device type may correlate strongly with a protected characteristic, and a segment built on such a proxy can reproduce a pattern you did not intend.
Write the segment definitions into your processing record. The definitions are the part of the analysis a reviewer will want, because they are what determine who is treated how.
None of this argues against segmentation. It argues for doing it deliberately: name the purpose, tell people, minimise the inputs, and keep a human decision where the consequence is significant.
From Segments to Offers Without Over-Personalising
There is a limit past which segmentation stops helping, and it is usually crossed in the direction of more personalisation rather than less.
The limit appears in three places. When segment sizes become too small to measure a result. When the number of messages exceeds what the team can maintain. And when personalisation starts to feel intrusive to the customer, because it reveals how much you know about them.
The third is the one that damages relationships. A message that references a customer's exact behaviour at a suspiciously precise level reads as surveillance rather than service. The same insight delivered at a slightly coarser grain reads as attentiveness.
Worked example, illustrative. A subscription business knows that a customer's orders dropped from weekly to monthly. A message that says so directly is unsettling. A message that offers a smaller, cheaper box for a period, without naming the drop, addresses the same situation and lands as helpful.
Two rules keep personalisation on the right side of the line. Use the data to decide what to offer, not what to say about the customer. And keep the number of distinct messages small enough that each one is genuinely maintained, because a personalisation programme with twenty templates degrades into twenty generic emails.
Choose a small number of treatments, test them against a control, and let the segments determine who receives which. That is a structure a small team can run, and it captures most of the value of a much larger programme.
Measuring Whether Segmentation Changed Anything
Segmentation work is easy to justify and hard to evaluate, because the benefit arrives as a difference between two paths you cannot both take.
Fix that with a holdout. Keep a small share of customers in each segment on the default treatment, and compare the segment-specific treatment against it on the metric you chose in advance. Without a holdout you can measure activity and not effect.
Choose metrics that move inside the test window and that matter to the business. Repeat rate, upgrade rate, second-month retention and average order value all qualify. Revenue per customer over a year does not, because you cannot wait for it.
Worked example, illustrative. A team runs a segment treatment on the price-led group and holds back a fifth of it. After eight weeks, the treated group's second-month retention is meaningfully higher while first-order volume is slightly lower. The plan adopts the treatment and records the trade-off explicitly, because a leader looking only at order volume would have read the same result as a decline.
Two cautions. Test one change at a time, or you learn which combination worked and not which component did. And re-run the test periodically, because a treatment that worked on last year's customers may not work on this year's, particularly if the acquisition channel has changed.
Record the result either way. A documented failure is the cheapest form of institutional learning available, and the alternative is repeating it in eighteen months with a different name.
A One-Page Segment Brief You Can Hand Over
Segment work usually lives inside one person's analysis environment, and it stops being useful the moment that person is unavailable.
Write a one-page brief per segment, and keep them together as the record of how you treat customers. Six lines are enough: what the segment is, how it is defined, how big it is, what it receives, what it is measured by, and what is still unknown about it.
The last line is the one that keeps the record honest. Every segment has a gap: customers at the edge who do not quite fit, a behaviour you have not observed because the data window is short, a channel that is under-represented. Naming the gap stops the next reader from treating the definition as more complete than it is.
Worked example, illustrative. A segment described as customers who have not reordered in ninety days is defined by a recency rule, sized at a specific count, receives a re-engagement offer, is measured by reactivation rate, and its unknown is whether the ninety-day window is the right threshold, because the analysis has not tested shorter and longer windows against reactivation.
Two habits make the briefs durable. Keep them in a place that a colleague would find without being told, and date each one, because a segment definition that is three years old is a description of customers who may no longer exist.
Then treat the set of briefs as the operating manual for your customer base. It is the document that lets someone new make a decision on their third day rather than their third month.
Choosing Your Tooling Without Locking Yourself In
The tooling question arrives early and dominates the conversation more than it should, because the analysis is straightforward and the platforms are not.
Three routes cover most needs. A spreadsheet with a scripting layer, which is free and slow and entirely sufficient under a few thousand customers for anything except the clustering itself. A general-purpose notebook environment with standard data libraries, which handles clustering properly and requires someone comfortable with code. And a customer platform with segmentation built in, which is fastest to start and hardest to leave.
Choose on three criteria rather than on features. Whether the analysis can be reproduced by someone else, because a segmentation nobody can re-run is a one-off. Whether your customer data has to leave your environment, because that decision has compliance consequences. And what happens to the definitions when you change tools, because segment definitions embedded in a platform are the expensive part to migrate.
Worked example, illustrative. A team starts in a platform because it is quick, defines six segments inside it, and eighteen months later finds that exporting the definitions requires reconstructing them by hand. The lesson is not that the platform was wrong; it is that writing the definitions down in a tool-independent document at the start would have cost an afternoon and saved a fortnight.
Two habits. Keep the segment definitions in a plain document that is not inside any tool, so they survive a migration. And keep the input data in a form you control, even if the analysis runs elsewhere, so the model can be re-fitted after the platform changes underneath it.
Then resist changing tools for the sake of features. The analysis is not the constraint; the ability to act on the segments inside the business is, and no platform solves that.
Working With an Analyst or an Agency
Most businesses run part of this work with someone else, and the handover is where the value is usually lost.
Give a written brief before any analysis starts, with four parts. The decision the segmentation must inform. The behaviours that matter commercially. The data available and its known problems. And the deadline, with the reason it is the deadline.
The second part is the one that outsiders cannot supply. An analyst can cluster on whatever variables exist; only you know which behaviours are commercially meaningful, and a segmentation organised around the wrong behaviour is technically sound and useless.
Then agree the deliverable shape in advance. Ask for the segment definitions in plain language, the size and contribution of each segment, the variable list with the reason each variable is in, and the stability check on a split of the data. A deliverable that is a chart of clusters without definitions cannot be used or reviewed.
Worked example, illustrative. A brief asks whether a change in onboarding should be targeted at a subset of customers. The analyst returns four segments with definitions, sizes, a stability check and the reason each variable was included. The onboarding decision follows from the definitions, and the same definitions can be assigned to new customers at signup, which is what makes the work operational rather than interesting.
Two rules for the relationship. Insist that the analysis is reproducible on your own data, with the code or the configuration handed over. And ask for the two weakest findings alongside the strongest, because a deliverable that presents only solid conclusions has hidden the uncertainty you most need to see.
Feynman Summary: Explain It Like You Are 12
Imagine you have a problem to solve at work. It usually takes a long time and a lot of effort. Now imagine you have a super-smart robot friend who can do the boring parts in seconds.
That is what AI does for customer segmentation. The robot reads all the information, finds the patterns, and shows you the results. You look at what the robot found and decide what to do.
The robot does not make the final decision. You do. The robot just does the hard work of gathering and organizing information so you can focus on thinking and deciding.
That is the CI-First way: you are the boss, the AI is your helper. Together, you get better results faster.
Mindmap: The Complete Picture
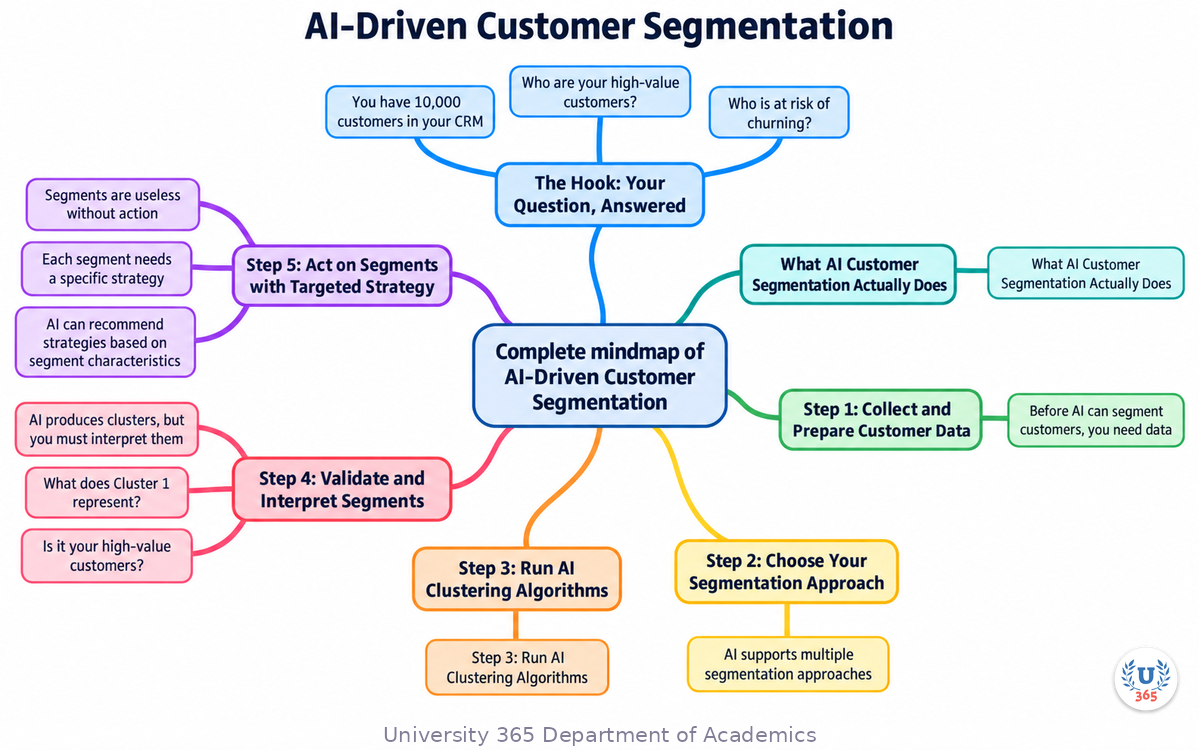
The mindmap shows the complete workflow: defining your objective leads to gathering and preparing data, which feeds into AI analysis and processing, which produces insights and recommendations, which you validate with human judgment before taking action. The CI-First principle wraps the entire process: you start with human-defined goals and end with human-validated decisions.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Apply What You Learned
Exercise: 15-Minute Application Sprint
Identify a real scenario: Think of a situation in your work or business where this topic applies.
Define your objective: What specific outcome do you want to achieve in 15 minutes?
Use an AI tool: Open ChatGPT, Claude, or Gemini and apply the framework from this lecture.
Analyze the output: Did AI produce useful results? What needs verification? What needs human judgment?
Make a decision: Based on AI output plus your judgment, what action will you take?
What to Look For
Did AI produce specific, actionable output or generic statements? Generic output means your prompt needs more context.
Did AI invent any data or make unsupported claims? Always verify critical facts against primary sources.
What would you do differently from what AI suggested? The gap between AI output and your judgment is where your value lies.
The CI-First formula is CI = HI + (AI x HI). Your intelligence is the foundation. AI multiplies it. But the final decision is yours.
Applied AI Connection
This exercise demonstrates the CI-First workflow in practice. You defined the objective (human intelligence). AI processed and analyzed (AI amplification). You validated and decided (human intelligence). The speed gain from AI lets you iterate faster and explore more options than you could manually.
Glossary
Term | Definition |
Customer Segmentation | The process of dividing customers into groups based on shared characteristics for targeted marketing and service strategies. |
K-Means Clustering | An AI algorithm that partitions data into K clusters where each data point belongs to the cluster with the nearest mean. |
Behavioral Segmentation | Grouping customers based on their actions: purchase history, engagement patterns, product usage, and interaction frequency. |
Customer Lifetime Value (CLV) | The total revenue a business expects from a customer over the entire relationship duration. |
Churn Risk | The probability that a customer will stop doing business with you. AI identifies churn risk factors and flags at-risk customers. |
Dynamic Segmentation | Segments that update automatically as customer behavior changes, unlike static segments that are set once. |
RFM Analysis | Recency, Frequency, Monetary value: a segmentation method that scores customers on how recently and frequently they purchase and how much they spend. |
Cluster Centroid | The center point of a cluster in K-means, representing the average characteristics of all customers in that group. |
CI-First | Co-Intelligence First: the U365 principle that human intelligence orchestrates and AI amplifies. CI = HI + (AI x HI). |
5M2S | 5 Minutes to Success: the U365 principle of using AI to compress time-intensive tasks into minutes. |
UNOP | University 365 Neuroscience-Oriented Pedagogy: the pedagogical framework behind all U365 lectures. |
Feature Engineering | The process of selecting and transforming data variables that AI uses for clustering and segmentation. |
Quiz: TEST YOUR UNDERSTANDING
1. What is the key advantage of AI-driven customer segmentation over manual segmentation?
A) AI processes thousands of data points across multiple variables simultaneously
B) AI is cheaper
C) AI does not require any data
D) AI segments are always correct
2. What does K-means clustering do?
A) Partitions customers into K groups based on similarity across multiple variables
B) Predicts customer churn
C) Calculates customer lifetime value
D) Generates marketing copy
3. Why must you validate AI-generated segments?
A) Because AI may produce clusters that are statistically valid but not business-relevant
B) Because AI is always wrong
C) Because validation is required by law
D) Because clusters change daily
4. What is dynamic segmentation?
A) Segments that update automatically as customer behavior changes
B) Segments that change based on weather
C) Segments created by AI without human input
D) Segments that only apply to new customers
5. What is the CI-First approach to customer segmentation?
A) AI identifies patterns and clusters, humans interpret and decide on strategies
B) AI replaces all marketing decisions
C) Humans do all the clustering manually
D) AI segments are used without validation
Answers: 1-B, 2-B, 3-B, 4-B, 5-B
Related Resources
U365 INSIDE Publications
Book Essential: Co-Intelligence by Ethan Mollick: The Centaur model and human-AI collaboration
Lecture 1: AI for Market Research: First lecture in the Business AI Series
External Resources
Harvard Business Review: AI in Business: How AI is transforming business operations: hbr.org
McKinsey: The State of AI: Annual report on AI adoption: mckinsey.com
Stanford AI Index: Annual report on AI progress and adoption: aiindex.stanford.edu
Related U365 Lectures (Coming Soon)
Other lectures in the Business AI Series at UIB
Cross-institute lectures on AI applications
U.Copilot for This Lecture
Discuss this lecture with U.Copilot, your AI chat companion trained on this content.
Copy and paste the following prompt into the U.Copilot chat on university-365.com:
You are U.Copilot for Lectures, an AI chat companion specially trained on University 365 lecture content. You are helping a Fellow who just completed the lecture "AI-Driven Customer Segmentation" from the Business AI Series at the U365 Institute of Business (UIB). Your role is to help the Fellow deepen their understanding of this topic. You can: - Clarify any concept from the lecture - Provide additional examples and practical applications - Explain how to use specific AI tools for these tasks - Discuss how to verify AI outputs and apply human judgment - Help the Fellow apply the CI-First approach to their own work - Suggest follow-up learning based on the Fellow's industry and interests Always maintain U365's CI-First approach: encourage the Fellow to think critically, verify AI outputs, and maintain human judgment as the orchestrator of AI tools. Use the UP-Context-Engineering Method: provide context-rich, role-aware responses that account for the Fellow's learning level and goals.
Next Steps
Now that you have completed this lecture, here is what to do next:
Try the practical exercise above to apply what you learned to a real scenario
Experiment with different AI tools to see which works best for your specific use case
Explore other lectures in the Business AI Series at UIB
Apply the CI-First approach to your daily work: ask "how can AI help?" before starting any task
Join a UIB program if you want structured learning in business management and digital entrepreneurship: visit university-365.com/tuition
The companies that succeed in the AI age are not the ones with the most AI tools. They are the ones whose people know how to direct AI effectively and apply judgment to its outputs. This lecture gave you the framework. Now practice it.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current tool capabilities and market data against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Business (UIB).
Denise Cromwell, Dean of Business, UIB
Signed for the academic year 2026.




Comments