
AI for Investment Analysis
Updated: 3 days ago

UIB University 365 Institute of Business
Series Finance Series
Duration 25 minutes
Business Management, Digital Entrepreneurship, Innovation, Finance, Leadership

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture
The Hook: Your Question, Answered
You have $100,000 to invest. You could spend 40 hours reading annual reports, analyzing financial statements, and comparing valuations. Or you could use AI to do the initial analysis in 30 minutes and spend your 40 hours on strategic thinking. Which produces better investment decisions?
In this lecture, you will learn how to use AI to tackle this challenge in 15 minutes. The AI handles the data processing and pattern recognition. You handle the judgment and decisions. This is the CI-First approach: human intelligence orchestrates, AI amplifies.

What AI Investment Analysis Actually Does
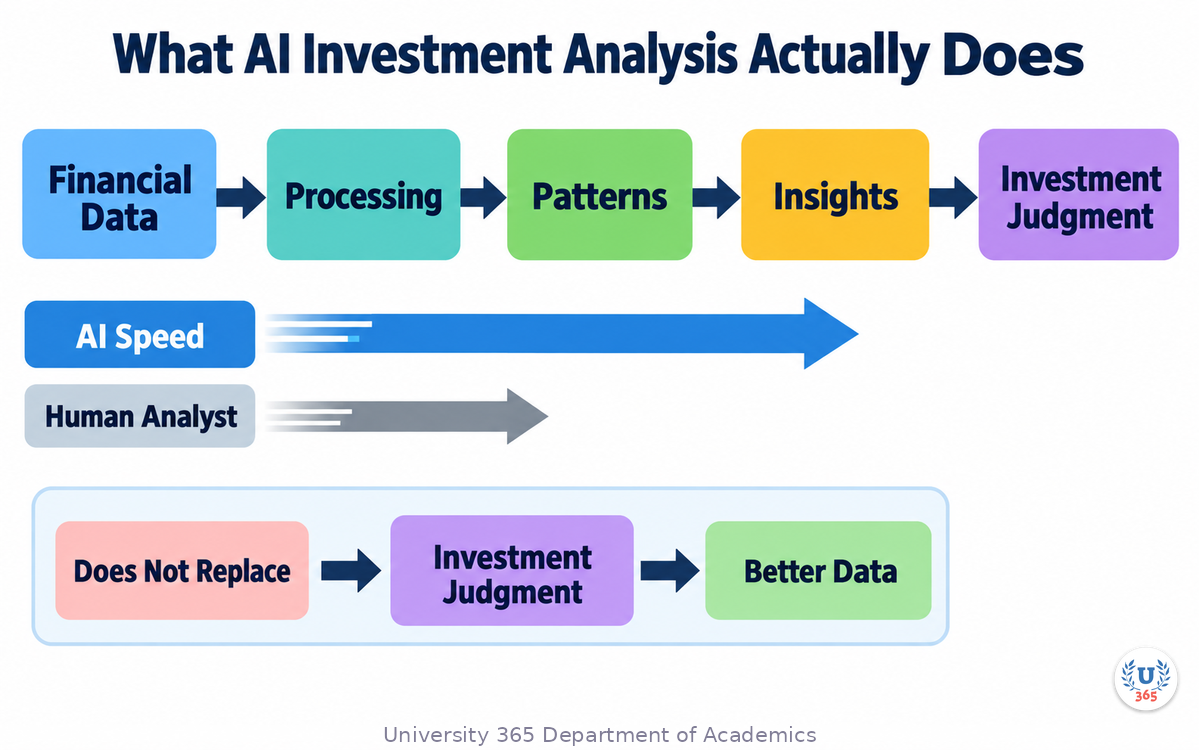
AI transforms investment research by processing vast amounts of financial data, identifying patterns, and generating insights at a speed no human analyst can match. It does not replace investment judgment. It gives you better data to base your judgment on.
Step 1: Gather and Structure Financial Data
AI can pull financial statements, market data, economic indicators, and company filings from multiple sources and structure them into comparable formats. What used to take days of manual data entry now takes minutes.
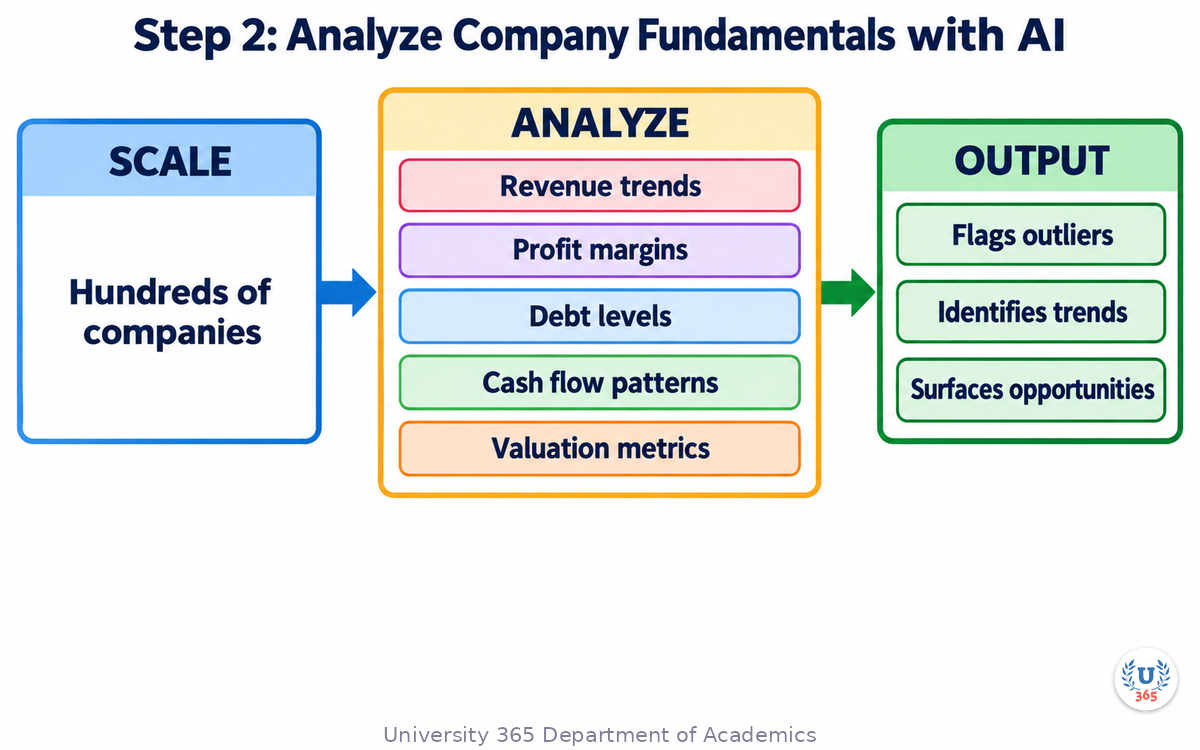
Step 2: Analyze Company Fundamentals with AI
AI can analyze revenue trends, profit margins, debt levels, cash flow patterns, and valuation metrics across hundreds of companies simultaneously. It flags outliers, identifies trends, and surfaces investment opportunities you might miss.
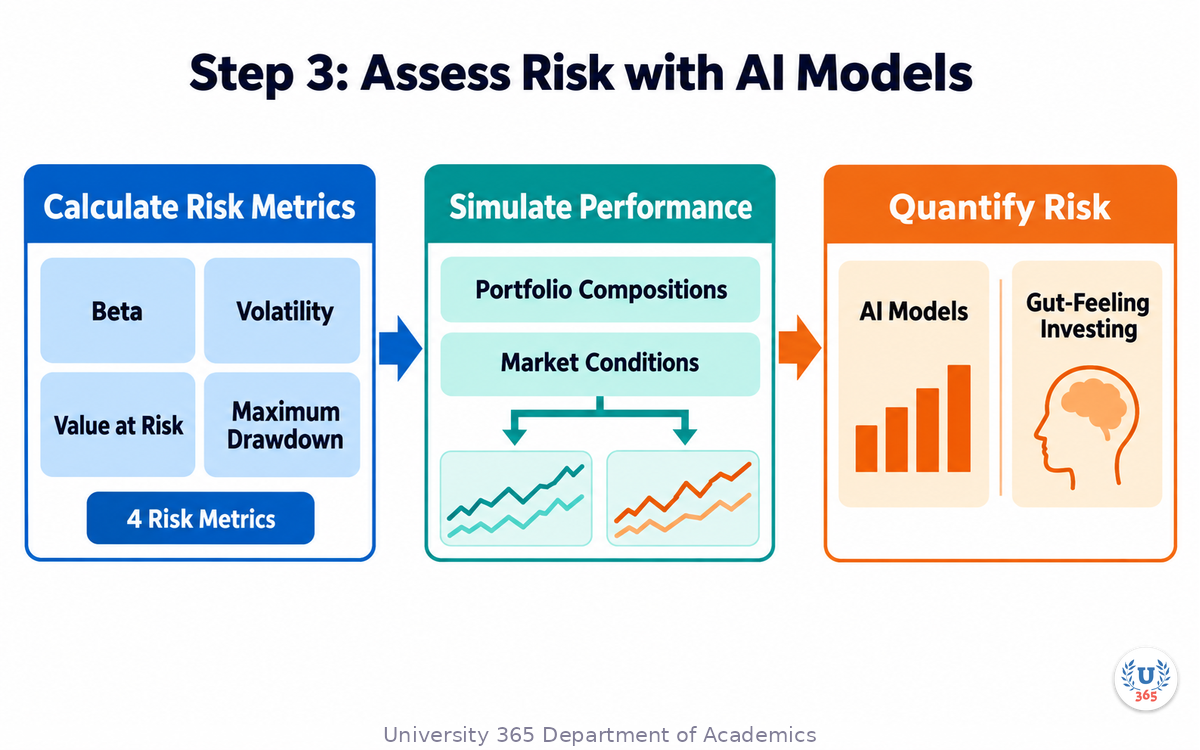
Step 3: Assess Risk with AI Models
AI can calculate risk metrics (beta, volatility, Value at Risk, maximum drawdown) and simulate how different portfolio compositions would perform under various market conditions. It quantifies risk in ways that gut-feeling investing cannot.
Step 4: Optimize Portfolio Allocation
Modern Portfolio Theory meets AI. AI can optimize asset allocation across stocks, bonds, and alternatives to maximize expected return for a given risk level. It can also suggest rebalancing triggers based on market movements.
Step 5: Monitor and Rebalance with AI Alerts
Investment analysis is not a one-time event. AI can continuously monitor your portfolio, alert you to significant changes, and suggest rebalancing actions. It watches the market so you do not have to stare at screens all day.
What AI Does Well in Investment Work, and What It Does Not
Investment analysis is the discipline where AI's failure modes cost the most money, and also where its leverage is largest. Both are true at once, and the method is knowing which is which.
Where AI genuinely wins
Reading volume. A large language model with a long context window will read a 200-page annual report and answer targeted questions about it in under a minute. An analyst doing the same read takes two to three hours, and does it for one company while the model does it for forty.
Standardising the unstandardised. Filings from different companies describe the same economics in different words. Extracting a consistent set of line items across 180 companies is dull, mechanical work, and it is exactly the work a model does without fatigue.
Building the argument against itself. Asking a model to construct the strongest bear case for a name you like is a genuine analytical use, not a gimmick. It surfaces the datapoints you had stopped looking at.
Where AI costs you money
Arithmetic you did not recompute. A model that sums a column of financial figures gets it wrong often enough to matter, and it reports the wrong total with exactly the same confidence as the right one. Every number that reaches a client must be recomputed by something deterministic.
Stale data presented as current. A model's training data has a cutoff. Ask it for a current price and you get a plausible number from a date you cannot see. For anything time-sensitive, the model must be given the data explicitly rather than asked to recall it.
The confident synthesis of a weak source. Ask for a summary of a company's competitive position and you get fluent prose. Whether that prose came from the annual report or from a blog post is invisible in the output.
The dividing line
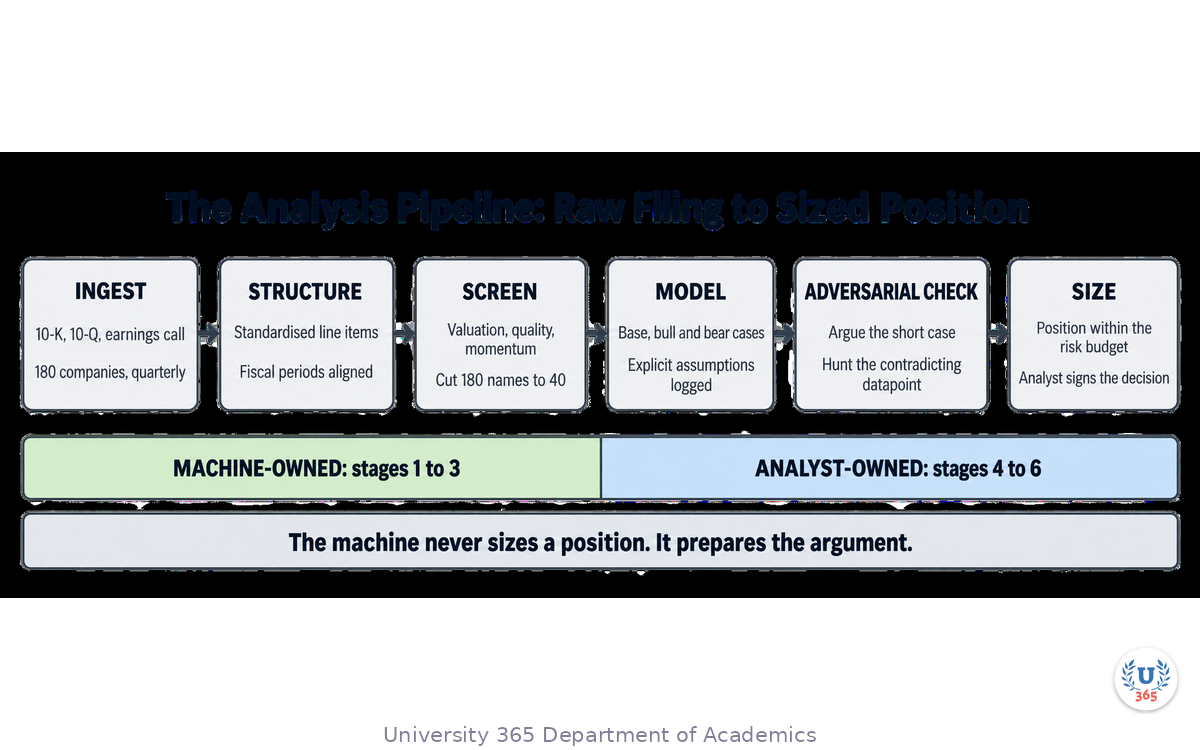
The machine owns preparation, the analyst owns judgement. Preparation is retrieving, extracting, standardising and drafting. Judgement is what the numbers mean, what could make them wrong, and how large a position to take. In the worked example below the analyst never delegates sizing, and the model never touches a total that has not been recomputed.
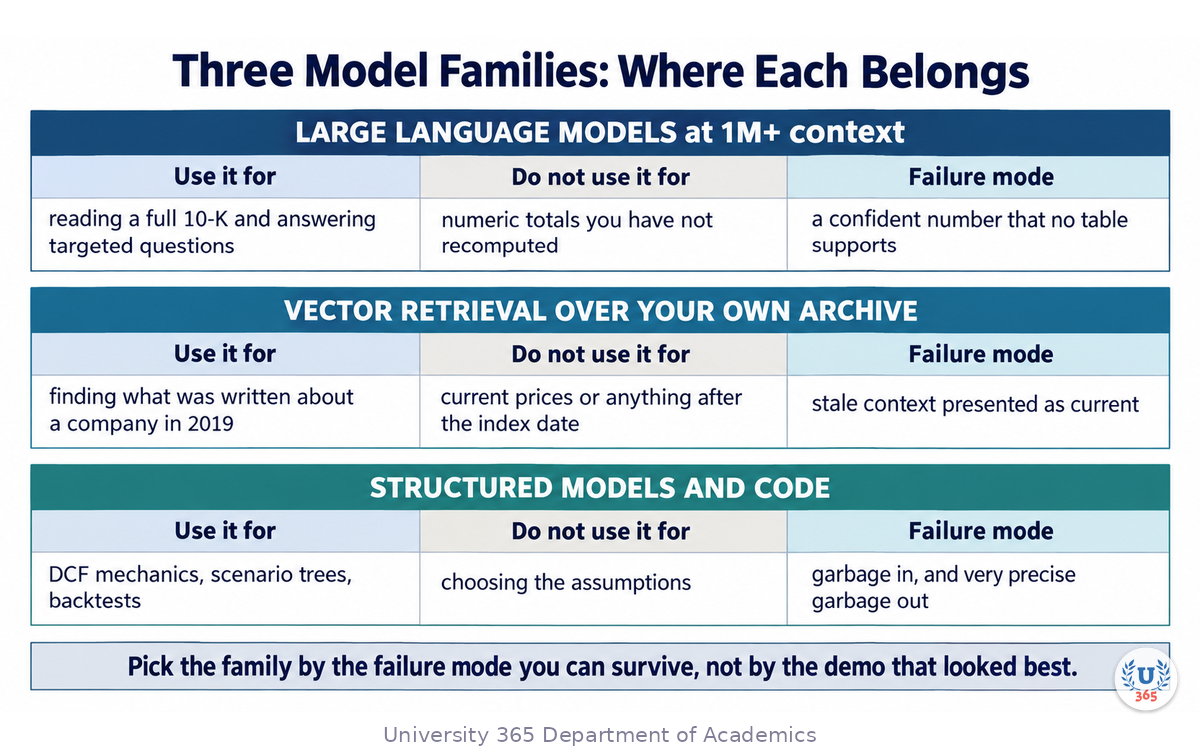
Model family | Use it for | Do not use it for |
Large language model, long context | Reading a full filing and answering targeted questions | Totals you have not recomputed |
Vector retrieval over your archive | Finding what you wrote about a company years ago | Anything after the index date |
Structured models and code | Valuation mechanics and scenario trees | Choosing the assumptions |
Step 1: Build the Data Layer Before You Ask a Question
Most disappointing AI research outputs trace back to the data layer, not the model. If the model is reading three different formats of the same metric, no amount of prompt engineering will reconcile them.
Collect the primary documents, not summaries
Pull the filings themselves. Ten-K and ten-Q equivalents, the earnings call transcript, the investor presentation. If you build your data layer from news summaries of the filings, you have inherited someone else's errors and lost the ability to check them.
Standardise the line items once
Decide the twenty or thirty metrics you care about and define each precisely: revenue, gross margin, operating cash flow, net debt, capital expenditure, share count. Then extract those fields across every company and period into one table. This is where a model earns its cost: 180 companies times four quarters is 720 mechanical extraction tasks.
Align the fiscal periods
Companies close their years on different dates. A comparison of a January year-end and a June year-end on the same row is a silent error that survives every downstream check. Align the periods explicitly and record the alignment rule.
Record the provenance of every field
Each extracted number should carry the document it came from and the page or table within it. This is what makes the seven-point verification checklist possible later. An extraction without provenance is a number you cannot defend in a client meeting.
Version the dataset
Date the dataset and freeze it for the analysis. When a conclusion is challenged three weeks later, you need to know exactly which extraction you used. A live, continuously updated dataset makes results irreproducible, which is the opposite of what a research process requires.
In the worked example, the team builds the data layer once for 180 companies and it takes the largest share of the project's time. Every later stage becomes fast because the data layer holds.
Primary filings, not news summaries
One defined schema of 20 to 30 metrics
Fiscal periods aligned, with the rule recorded
Provenance on every extracted field
Dataset versioned and frozen for the analysis
Step 2: Screening with AI Without Fooling Yourself
AI makes screening faster, and faster screening makes false positives cheaper to produce. The discipline is to decide the rule before you look at the results.
Write the screen down first
A screen is a rule: valuation below a threshold, returns on capital above another, momentum in a defined band. Write the rule and its thresholds before running anything. A screen whose criteria were chosen after seeing which names it returned is not a screen, it is a rationalisation.
Beware the survivorship problem
If your dataset contains only companies that exist today, every screen looks better than it was. AI makes this worse, because it is easy to assemble a universe quickly from current sources and never notice that the failures are missing. State your universe construction rule and its known gaps.
Test the screen on a period you did not use to design it
Split your data. Design the screen on one window and test it on another. This is elementary and it is routinely skipped when AI makes iteration fast enough that the same period gets reused twenty times.
Look for the mechanism, not just the pattern
A screen that works for reasons you can state is a strategy. A screen that works for reasons you cannot state is a data artefact waiting to fail. Ask why each surviving name is there, and if the answer is a coincidence of the metric definition, remove it.
Cut the list to something a human can hold
In the worked example, 180 names reduce to 40, which is where a four-analyst team can give each name genuine attention. A screen returning 150 names has moved the selection problem rather than solved it, and the next stage is done badly because there is too much of it.
Screen discipline | Why it matters |
Rule written before the run | Stops the criteria being chosen to fit the answer |
Universe gaps declared | Survivorship makes every screen look better than it was |
Out-of-sample test period | Fast iteration makes reuse of one window tempting |
A stated mechanism | Separates a strategy from a data artefact |
Output a human can hold | 40 names get real attention, 150 do not |
Step 3: Modelling, Valuation and the Assumption Log
AI is excellent at the mechanics of a valuation model and useless at choosing what goes into it. Keep those two jobs separate in your process and in your file.
Let the model build the machinery
Discounted cash flow mechanics, sensitivity grids, scenario trees and the arithmetic that connects them are deterministic work. Generating the spreadsheet logic with code, rather than asking a chat model to produce numbers, gives you something you can run again, audit and change.
Keep every assumption in one visible place
Growth rates, margins, discount rates and terminal values belong in one assumptions block at the top of the model, each with a source note. When an assumption moves, the whole model moves, and anyone can see exactly what changed. An assumption buried inside a formula is one nobody will challenge.
Build the bear case as seriously as the base case
The bear case is where AI earns its place in this stage. Ask for the strongest argument against your thesis and require it to cite specific evidence from the filings. A bear case that reads as a formality tells you the model was asked politely rather than adversarially.
Recompute every number that leaves the model
This is the rule from the previous lecture section, applied here: nothing reaches a client until something other than a language model has computed it. In practice that means the final figures come from the spreadsheet, and the model's role ends at drafting the narrative around them.
Write the falsification line
For each name, state the observation that would prove the thesis wrong, and make it concrete and observable: a specific metric crossing a specific level by a specific date. A thesis without a falsification line cannot be managed, only believed.
Model mechanics generated as runnable code, not prose
One assumptions block, every input source-noted
Bear case built adversarially, with citations
Every published figure recomputed outside the model
One falsification line per name: metric, level, date
Step 4: Risk, Position Sizing and the Line AI Must Not Cross
Nothing in this lecture matters as much as this rule: a language model may prepare a decision, and it must never make the sizing decision.
Why sizing is different from analysis
Analysis asks what a company is worth. Sizing asks how much you are willing to lose if that analysis is wrong. The second question depends on your risk budget, your correlation with existing positions, your liquidity constraints and your tolerance for being wrong in public. None of those live in the filings, so no model reading the filings can answer it.
Quantify the downside before the upside
For each candidate, write the loss under the bear case in portfolio terms, not company terms. A 30 percent drawdown in a position sized at 2 percent of the portfolio costs 0.6 percent. The same drawdown in a position sized at 10 percent costs 3 percent, which is the difference between a bad month and a bad year.
Set the risk budget before the ideas arrive
Decide the maximum a single name may hold and the maximum an uncorrelated cluster may hold, in advance. A risk budget set after the ideas have arrived is not a budget, it is a negotiation with yourself, and you will lose it for the idea you like most.
What AI can contribute to this stage
It can compute the portfolio-level exposure of a proposed size, run the correlation against existing positions, and show what the position does to the overall risk profile. It can prepare all the inputs. It must not choose the number.
Record the decision and the person who made it
Every sized position carries a name. That record is what makes an investment process accountable, and it is also the fastest way to discover that a model output quietly became a decision nobody owned. If a position exists with no human attached to the sizing, that is a process failure, not a model failure.
Task | Owner |
Retrieve and extract filings | Machine |
Standardise and screen | Machine |
Draft the bull and bear cases | Machine, reviewed by analyst |
Decide the position size | Analyst, recorded by name |
Set the risk budget | Investment committee, in advance |
Worked Case: Four Analysts and 180 Companies
This is a composite worked example built on the method in this lecture. The figures are illustrative, not a benchmark, and the point is the shape of the change rather than the precise numbers.
Before the pipeline
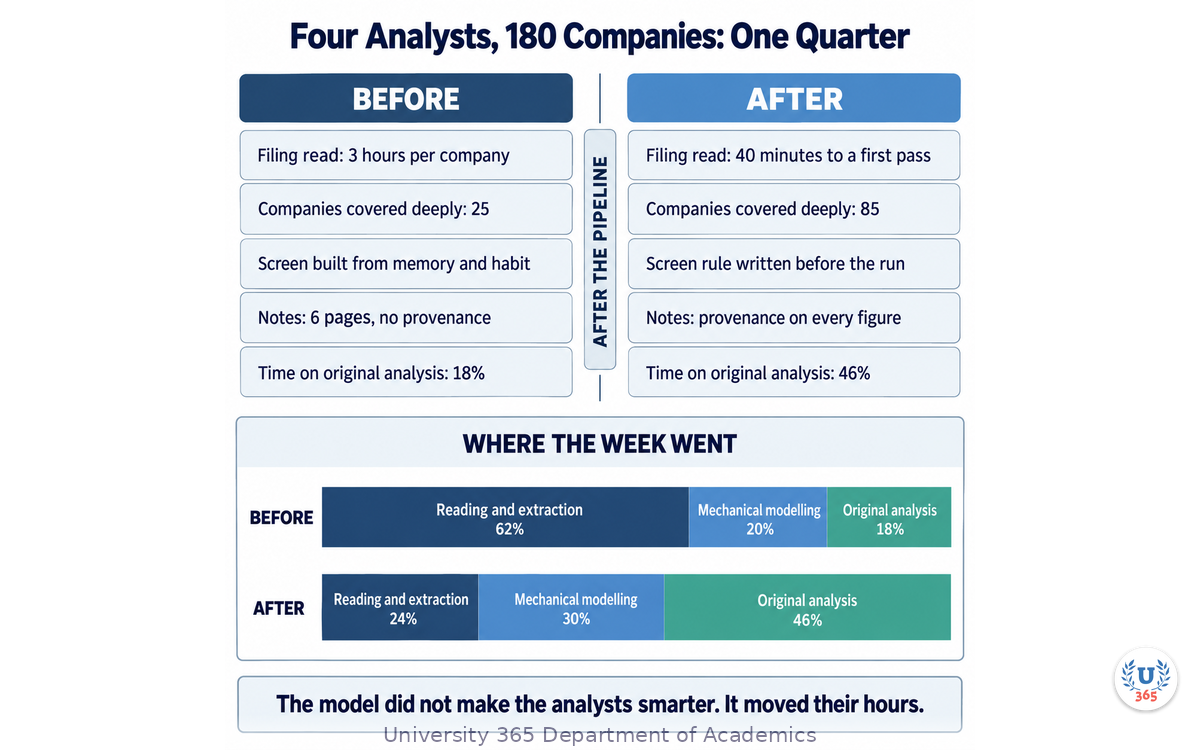
A four-analyst equity research function covers 180 companies. Each analyst reads filings by hand, about three hours per company, so deep coverage reaches roughly 25 names a quarter. Screening criteria live in the analysts' heads, notes run to six pages with no provenance, and about 18 percent of the week goes to original analysis.
The change
The data layer is built once, from a schema of metrics extracted across all 180 companies and their fiscal periods, each field carrying its source document. Reading becomes a forty-minute first pass with the model, and the analyst goes deep only where that pass raises a question. The screen rule is written down before it runs and tested on a held-out window. Valuation mechanics move into generated code with one assumptions block.
What actually changed
Deep coverage rises from about 25 names to about 85. Reading and extraction fall from 62 percent of the week to roughly 24 percent. Mechanical modelling rises slightly, because the team now runs scenarios it previously skipped. Original analysis rises from 18 percent to about 46 percent.
The important detail is the direction of the change. The model did not make the analysts produce more recommendations. It moved their hours from extraction into thinking, and the coverage increase is a consequence of that, not the goal.
What did not change
Every figure in a published note is still recomputed outside the model. The position sizing decision is still made by a named analyst. The bear case is still built and still argued. Nothing about the investment discipline relaxed; what relaxed was the reading load.
The cost
The tooling for a team of this size runs to roughly $6,000 a year on top of existing data subscriptions. The dominant cost is building the data layer once; the dominant benefit is that every later quarter is faster. That is the general shape of an AI investment in research: a one-time build against a permanent change in where the hours go.
Measure | Before | After |
First-pass read per company | 3 hours | 40 minutes |
Names covered deeply per quarter | 25 | 85 |
Screen criteria | Habit | Written before the run |
Provenance on figures | None | Every figure sourced |
Time on original analysis | 18 percent of the week | 46 percent of the week |
The Compliance Boundary: Research Is Not Advice
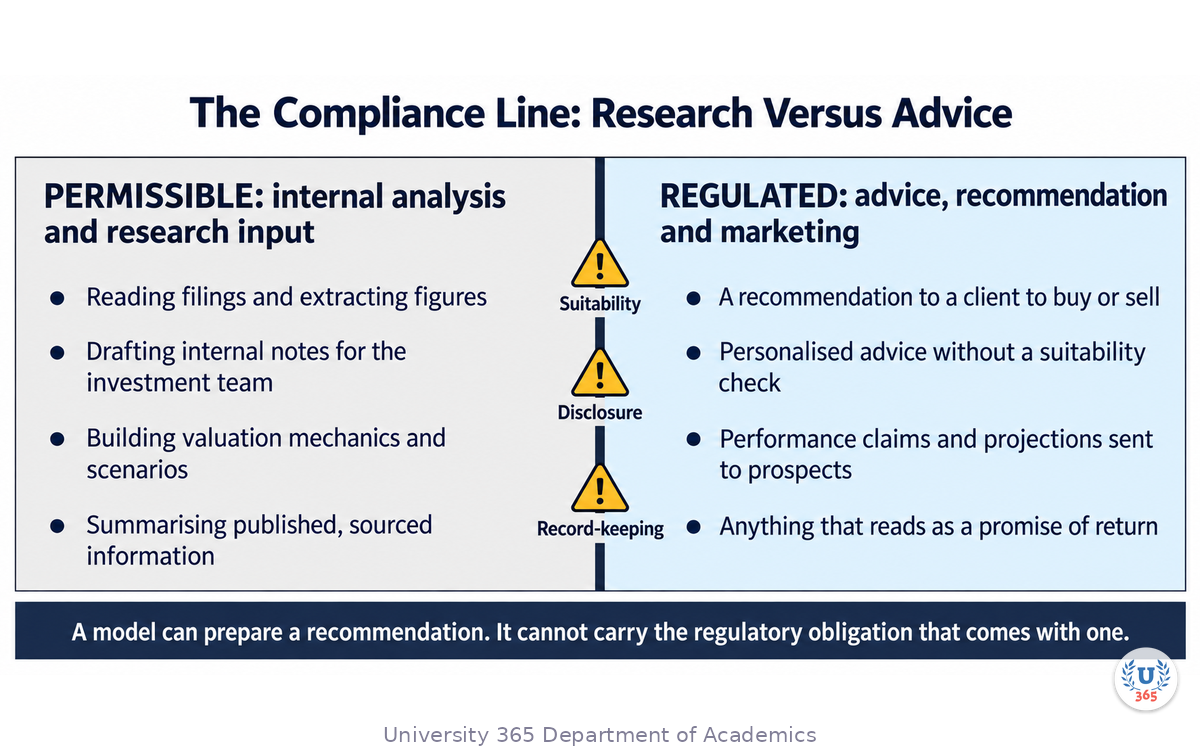
In regulated jurisdictions, the difference between research and advice is not the quality of the analysis. It is who receives it and what it tells them to do. AI does not change that boundary, and it does make it easier to cross by accident.
What stays on the permissible side
Internal analysis, extraction from public filings, drafting notes for the investment team, building valuation mechanics and summarising published, sourced information. All of this is preparation, and preparation is where AI belongs.
Where the boundary sits
The line is crossed when output becomes a recommendation to a client, personalised advice that has not passed a suitability process, a performance claim sent to a prospect, or any statement that reads as a promise of return. A model can draft the sentence. It cannot carry the regulatory obligation that attaches to it, and the obligation does not transfer because the text was generated.
Three duties that do not delegate
Suitability: knowing whether a recommendation fits the recipient. Disclosure: telling them what the analysis rests on and what the conflicts are. Record-keeping: being able to show, later, what was said and on what basis. Each of these is a human duty owed by a licensed entity, and each is a place where an AI-generated artefact can create an obligation nobody intended to take on.
Practical controls
Keep internal notes and client-facing material in visibly different templates, so a draft cannot drift into an outbound channel. Require a named reviewer before anything leaves the firm. Log which model produced which text, and on what date, so the record exists if it is ever asked for.
The disclosure line that most teams forget
If AI was used in preparing published research, the firm needs a position on whether and how that is disclosed. It should be a deliberate decision rather than a consequence of a draft that was never examined. Check the current rules for your jurisdiction: they are moving, and this lecture is not legal advice.
Research input stays internal; advice goes through suitability
Separate templates for internal notes and client material
A named human reviewer before anything leaves the firm
Log the model and the date for every generated text
Decide the AI-disclosure position deliberately, not by default
Verification: The Seven Checks Before a Note Leaves Your Desk
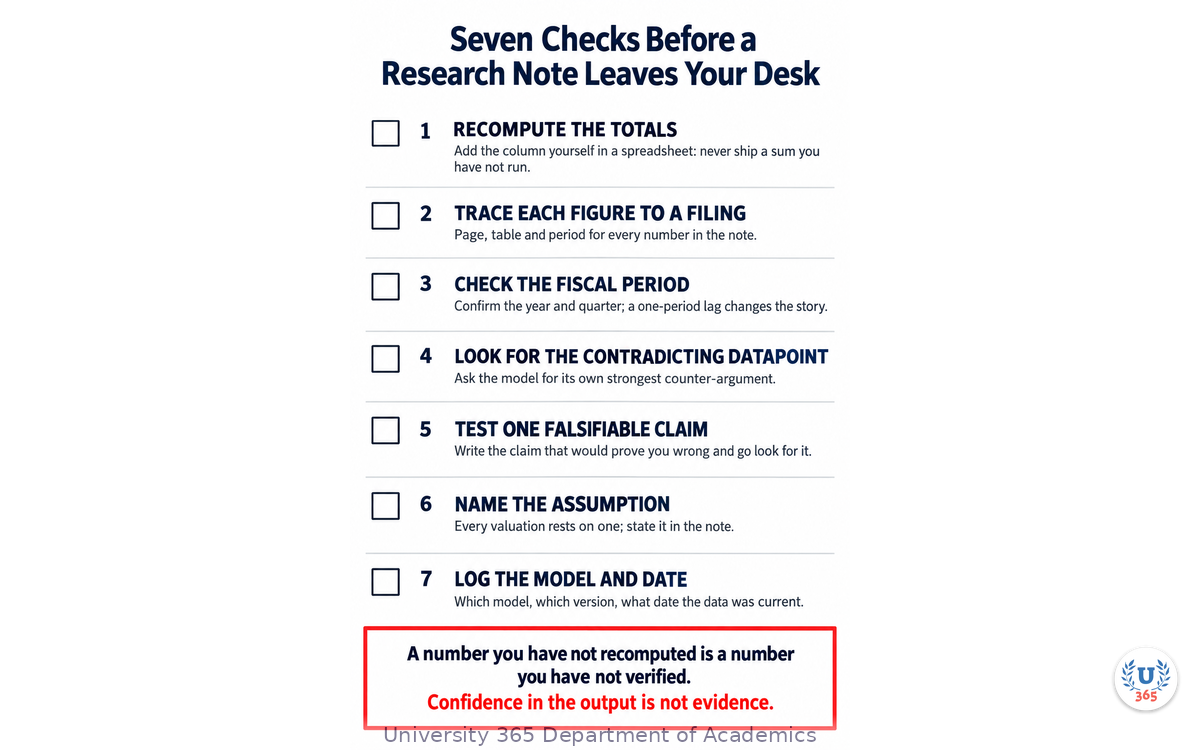
A wrong number that reaches a client costs more than the analysis ever earned. These seven checks take about twenty minutes on a typical note and they are not optional.
1. Recompute the totals
Add the column yourself. Every sum, every percentage, every growth rate. A language model's arithmetic is not reliable enough to publish, and the error rate is high enough that a note without this check will contain one eventually.
2. Trace each figure to a filing
Page, table and period for every number. If a figure cannot be traced, it does not go in the note. This check is unpleasant the first time and becomes trivial once the data layer carries provenance.
3. Check the fiscal period
Confirm the year and the quarter. A one-period lag changes the story and is invisible once the numbers are in a table.
4. Ask for the contradicting datapoint
Prompt the model for its own strongest counter-argument and require evidence. If it cannot produce one, that is a signal that you have constrained the question too tightly, not that the thesis is confirmed.
5. Test one falsifiable claim
Write down the claim that would prove you wrong and go and look for it. This is the difference between research and advocacy, and it is the check most likely to change your conclusion.
6. Name the assumption
Every valuation rests on one assumption that matters more than the others. Name it in the note, so the reader knows where the analysis is sensitive.
7. Log the model and the date
Which model, which version, and what date the underlying data was current. This is the record that lets you reproduce the work when it is questioned, and it is the first thing that goes missing when the process is informal.
Check | Failure it prevents |
Recompute the totals | A confident arithmetic error reaching a client |
Trace each figure | An unsourced number that cannot be defended |
Check the fiscal period | A comparison across mismatched periods |
Find the counter-argument | A one-sided thesis that reads as advocacy |
Test a falsifiable claim | Confirmation bias in the conclusion |
Name the assumption | An unstated sensitivity in the valuation |
Log the model and date | An irreproducible result weeks later |
Run the seven checks as a habit and they take twenty minutes. Skip them once and you will spend a week rebuilding your credibility.
Your Own Workflow: A Repeatable Weekly Rhythm
The method is worth little without a rhythm that survives a busy week. Here is a structure that fits the work into a normal five-day cycle.
Monday: refresh and screen
Update the data layer with any new filings, then run the written screen. Output is a list you can hold, not a list you have to triage. Anything that fails the screen is logged with the reason, so a name cut today can be explained in six months.
Tuesday and Wednesday: deep work on the shortlist
Model build for the names that survived, with the assumptions block filled in source-noted. This is where the model mechanics run and where the bear case gets constructed adversarially. Reserve the mornings for this: it is the work that cannot be done in fragments.
Thursday: verification and drafting
Run the seven checks on everything produced this week. Then draft the narrative, and remember that the numbers in the narrative come from the spreadsheet, not from the model's prose.
Friday: review and record
Decide what changed in the portfolio view, record which positions were sized and by whom, and log every model interaction that produced a published figure. Fifteen minutes on Friday is what makes the Thursday work defensible in three months.
The monthly addition
Once a month, review the screen itself rather than its output. Did the criteria still reflect what you actually believe, and did anything the screen rejected subsequently work out? That review is how the screen improves instead of calcifying.
Day | Work | Output |
Monday | Refresh data, run the screen | A shortlist you can hold |
Tuesday and Wednesday | Model, assumptions, bear case | A defensible valuation |
Thursday | Seven checks, draft the note | Verified figures, cited narrative |
Friday | Review, record sizing, log models | An accountable record |
Monthly | Review the screen criteria | A screen that still means something |
The rhythm matters more than the tooling. A team with a mediocre model and a disciplined weekly cycle produces better research than a team with the best model and no cycle, because the cycle is what catches the errors.
Backtests, Overfitting and Why Fast Iteration Is Dangerous
AI makes it cheap to test an idea, and cheap testing is how a research team talks itself into a strategy that has never worked and never will.
The multiple-testing problem, in plain terms
If you test twenty variations of a screen against the same five years of history, one of them will look excellent by chance alone. That is arithmetic, not luck. When a model can generate and test fifty variations before lunch, the number of chances to be fooled per day rises sharply.
The correction is to count your tests. Keep a log of every variation you ran, and treat the best result as one of that many candidates. If you ran forty, the best one is the maximum of forty draws and it needs a much larger effect to be believable.
The degrees of freedom you did not notice you used
Overfitting is not only about parameter values. The universe, the lookback window, the rebalancing date and the metric definition are all choices, and each consumes a degree of freedom. A screen whose thresholds are round because you tried the alternatives is not a conservative screen.
What AI is genuinely useful for here
It is good at generating the variations you should test and at enumerating how a simple rule can break. It is also good at writing the backtest code so the test is reproducible. What it must not do is tell you which variation is right, because the one that scores highest on your history is precisely the one most likely to be an artefact.
Three practical rules
First, hold out a period and do not look at it until the end. Second, prefer simple rules with few parameters, because there is less to fit. Third, state the mechanism before the test: if you cannot say why the effect should exist, a good backtest result should increase your suspicion rather than your position.
Trap | Why it bites | Discipline |
Many variations tested | The best of many draws looks excellent by chance | Log every test and correct for the count |
Choices counted as assumptions | Universe, window and date choices all consume freedom | State and freeze each choice |
Simple rules with round numbers | Round numbers often mean the alternatives were tried | Document the sensitivity around each threshold |
No stated mechanism | A good result with no reason is an artefact candidate | Write the mechanism before testing |
Disclosure, Conflicts and the Written Record
Two obligations sit beside the analysis whether or not AI is involved, and AI changes how easily both are met or missed.
Conflicts of interest
If your firm holds the security, advises the issuer, or stands to earn fees from a transaction connected to your recommendation, that must be disclosed. AI neither creates nor removes the conflict. What it changes is the speed at which a draft becomes something that reads like a recommendation, which is why the disclosure step belongs in the process rather than in someone's memory.
The written record
Keep the record that shows what you considered, what you concluded and on what evidence. This is straightforward when notes carry provenance on every figure and every model interaction is logged with its date. It is very difficult to reconstruct later, which is why the logging has to be automatic rather than remembered.
What the record is for
It is not only a regulatory requirement. It is what lets you disagree with your own past self. A team that can see what it believed about a company in March, and why, can learn from its errors. A team that cannot re-derives the same view from scratch every time.
Practical logging that survives a busy week
Log the model, the version, the date the underlying data was current, and the prompt or question asked. Store the output alongside the note it informed. Do this at the moment of the interaction, because the alternative is reconstructing it from memory at the end of the quarter, and the reconstruction will be wrong.
Disclose holdings, advisory relationships and fee exposure
Provenance on every figure that reaches a note
Log model, version, data date and question at the time
Store the output next to the note it informed
Treat the record as a tool for learning, not only for compliance
The Analyst Skill Set in 2026
The job has not been replaced. It has been re-weighted, and the people who thrive are the ones who noticed which half of the work moved.
Skills that gained value
Defining the question precisely. A vague question produces a fluent answer that is useless, and the ability to specify what you actually want to know is now the first productive act of the day.
Judging output quality. Knowing what a wrong number looks like, and knowing which claims in a fluent paragraph would need evidence if they were tested. This is the skill that separates an analyst using AI from an analyst being used by it.
Designing verification. Building the checks into the process so that a wrong figure is caught by structure rather than by attention. The seven checks in this lecture are a design, not a personal virtue.
Choosing the model for the failure mode. A long-context model, a retrieval index and a deterministic script fail in different ways, and picking by the failure you can survive is a professional judgement.
Skills that lost value
Re-keying figures from one format to another. Reading a filing cover to cover for a first pass. Producing the standard opening paragraphs of a research note. None of this is gone, but none of it is where your time should sit.
The skill that did not change at all
Deciding what a company is worth and how much you are willing to lose being wrong about it. That was always the job. Everything else was scaffolding around it.
How to build the new profile deliberately
Pick one analysis you do by hand and move it into the pipeline over a month. Build the data layer, write the screen, generate the model mechanics, and run the seven checks on the output. Then measure where your hours went before and after: the measurement is what tells you whether the change was real rather than merely busy.
Skill | Direction | Why |
Question specification | Rising | A vague question produces a useless fluent answer |
Output judgement | Rising | You must know what a wrong number looks like |
Verification design | Rising | Structure catches errors that attention misses |
Manual re-keying | Falling | Mechanical work the model does without fatigue |
Valuation and sizing | Unchanged | It was always the job |
The professionals who will struggle are not the ones who refused AI. They are the ones who adopted it without redesigning the verification step, and who will therefore learn about their first serious error from a client.
Reading a Filing with AI: A Practical Method
Reading a 200-page annual report is where most of an analyst's week disappears. This is the method that compresses it without losing the parts that matter.
Start with the question, not the document
Write down the three questions you want the filing to answer before you open it. What changed in the revenue mix. What management said about the next twelve months. What the cash flow statement says that the income statement does not. A model given those three questions produces a usable first pass. A model told to summarise the filing produces a press release.
Read the accounts, not the narrative
Ask for the three financial statements first, at line-item level, with changes from the prior year. The narrative is management's interpretation; the statements are the facts. Most disagreements in research are disagreements about the interpretation, and they are easier to have once you both agree on the numbers.
Force the comparison across periods
Ask specifically what changed since the same period last year and since the prior quarter. Models are naturally drawn to summarising the current document, and a summary of the current document will not tell you that receivables grew twice as fast as revenue.
Interrogate the footnotes
The footnote is where the accounting decisions live: revenue recognition, lease treatment, segment definitions, related-party transactions. Ask the model for each one and for what changed. This is the part of a filing a human reader skips under time pressure and the model does not.
Require a page reference for every claim
If the model cannot point to where in the document it found something, treat the statement as unsourced and verify it yourself. This is the single rule that makes AI-assisted reading safer than fast human reading, because a human under time pressure will not tell you what they skimmed.
Then go deep where the question was not answered
The first pass is forty minutes and produces a list of things the filing did not resolve. Those are the places where an analyst's attention earns its return. The point of the compression is not to read less; it is to spend the remaining hours on the parts that a summary cannot settle.
Step | What to ask for |
Frame | The three questions you want answered |
Statements | Line items with year-on-year and quarter-on-quarter change |
Comparisons | What changed since last year and last quarter |
Footnotes | Accounting policies and what changed in them |
Provenance | A page reference for every claim |
Escalation | The list of questions the filing did not resolve |
Used this way, AI changes the shape of an analyst's day rather than the quality of their judgement. The judgement still happens. It just happens on the parts of the filing that no summary can reach.
Feynman Summary: Explain It Like You Are 12
Imagine you have a problem to solve at work. It usually takes a long time and a lot of effort. Now imagine you have a super-smart robot friend who can do the boring parts in seconds.
That is what AI does for investment analysis. The robot reads all the information, finds the patterns, and shows you the results. You look at what the robot found and decide what to do.
The robot does not make the final decision. You do. The robot just does the hard work of gathering and organizing information so you can focus on thinking and deciding.
That is the CI-First way: you are the boss, the AI is your helper. Together, you get better results faster.
Mindmap: The Complete Picture
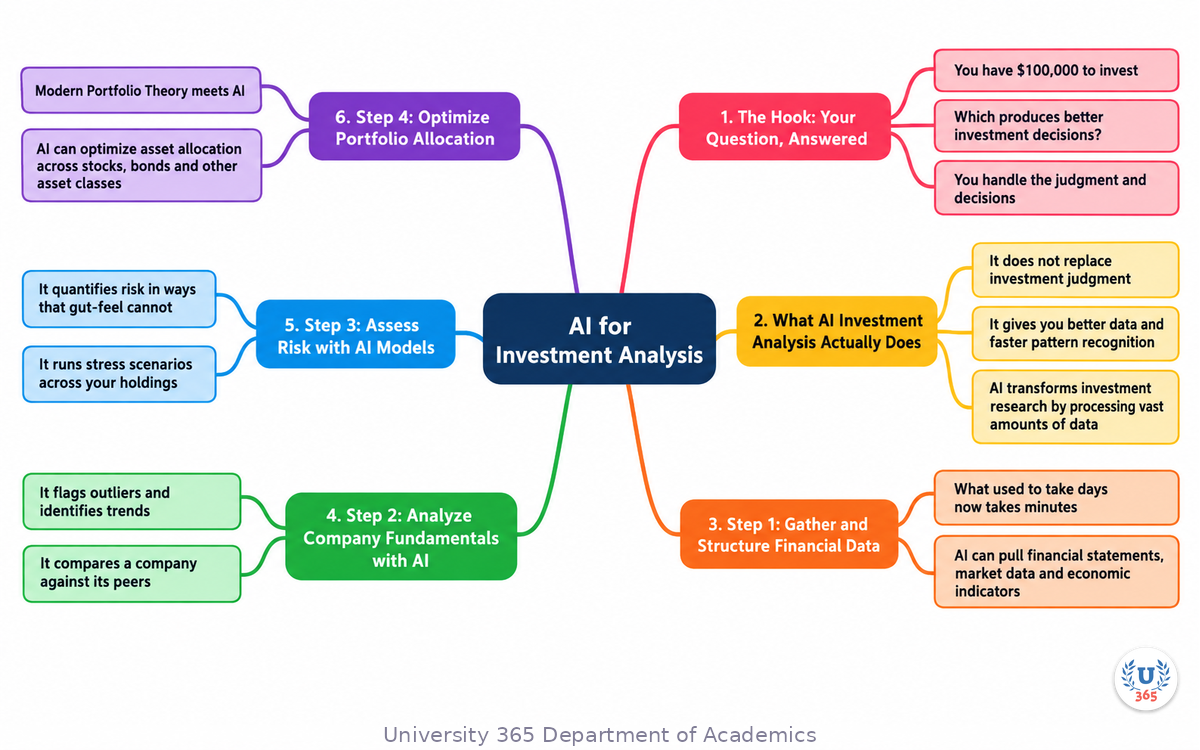
The mindmap shows the complete workflow: defining your objective leads to gathering and preparing data, which feeds into AI analysis and processing, which produces insights and recommendations, which you validate with human judgment before taking action. The CI-First principle wraps the entire process: you start with human-defined goals and end with human-validated decisions.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Apply What You Learned
Exercise: 15-Minute Application Sprint
Identify a real scenario: Think of a situation in your work or business where this topic applies.
Define your objective: What specific outcome do you want to achieve in 15 minutes?
Use an AI tool: Open ChatGPT, Claude, or Gemini and apply the framework from this lecture.
Analyze the output: Did AI produce useful results? What needs verification? What needs human judgment?
Make a decision: Based on AI output plus your judgment, what action will you take?
What to Look For
Did AI produce specific, actionable output or generic statements? Generic output means your prompt needs more context.
Did AI invent any data or make unsupported claims? Always verify critical facts against primary sources.
What would you do differently from what AI suggested? The gap between AI output and your judgment is where your value lies.
The CI-First formula is CI = HI + (AI x HI). Your intelligence is the foundation. AI multiplies it. But the final decision is yours.
Applied AI Connection
This exercise demonstrates the CI-First workflow in practice. You defined the objective (human intelligence). AI processed and analyzed (AI amplification). You validated and decided (human intelligence). The speed gain from AI lets you iterate faster and explore more options than you could manually.
Glossary
Term | Definition |
Investment Analysis | The process of evaluating investments for their potential return and risk, including fundamental, technical, and quantitative analysis. |
Portfolio Optimization | Selecting the best asset allocation to maximize expected return for a given level of risk, based on Modern Portfolio Theory. |
Value at Risk (VaR) | A risk metric that estimates the maximum potential loss over a given time period with a specified confidence level. |
Beta | A measure of a stock's volatility relative to the overall market. A beta of 1.0 moves with the market; above 1.0 is more volatile. |
Maximum Drawdown | The largest peak-to-trough decline in an investment's value, measuring downside risk. |
Fundamental Analysis | Evaluating a company's financial health, management, competitive position, and growth prospects to assess investment value. |
Modern Portfolio Theory | The framework for constructing portfolios that maximize expected return for a given level of risk through diversification. |
CI-First | Co-Intelligence First: the U365 principle that human intelligence orchestrates and AI amplifies. |
5M2S | 5 Minutes to Success: the U365 principle of using AI to compress time-intensive tasks into minutes. |
UNOP | University 365 Neuroscience-Oriented Pedagogy: the pedagogical framework behind all U365 lectures. |
Rebalancing | Adjusting portfolio allocations back to target weights when market movements cause them to drift. |
Diversification | Spreading investments across different assets to reduce risk without necessarily reducing expected return. |
Quiz: TEST YOUR UNDERSTANDING
1. What does AI investment analysis do?
A) Processes financial data, identifies patterns, and generates insights at a speed no human can match
B) Guarantees investment returns
C) Replaces the need for investment judgment
D) Predicts stock prices with 100% accuracy
2. What is portfolio optimization?
A) Selecting the best asset allocation to maximize expected return for a given risk level
B) Buying as many stocks as possible
C) Only investing in one asset class
D) Following the market index exactly
3. What does Value at Risk (VaR) measure?
A) The maximum potential loss over a given time period with a specified confidence level
B) The minimum guaranteed return
C) The tax liability of the portfolio
D) The number of trades per month
4. Why is continuous portfolio monitoring important?
A) Because market conditions change and portfolios need rebalancing when allocations drift
B) Because it is required by law
C) Because AI needs something to do
D) Because it increases trading fees
5. What is the CI-First approach to investment analysis?
A) AI provides better data and analysis, humans make the investment decisions
B) AI makes all investment decisions
C) Humans do all the analysis manually
D) AI and humans vote on each investment
Answers: 1-B, 2-B, 3-B, 4-B, 5-B
Related Resources
U365 INSIDE Publications
Book Essential: Co-Intelligence by Ethan Mollick: The Centaur model and human-AI collaboration
Lecture 1: AI for Market Research: First lecture in the Business AI Series
External Resources
Harvard Business Review: AI in Business: How AI is transforming business operations: hbr.org
McKinsey: The State of AI: Annual report on AI adoption: mckinsey.com
Stanford AI Index: Annual report on AI progress and adoption: aiindex.stanford.edu
Related U365 Lectures (Coming Soon)
Other lectures in the Finance Series at UIB
Cross-institute lectures on AI applications
U.Copilot for This Lecture
Discuss this lecture with U.Copilot, your AI chat companion trained on this content.
Copy and paste the following prompt into the U.Copilot chat on university-365.com:
You are U.Copilot for Lectures, an AI chat companion specially trained on University 365 lecture content. You are helping a Fellow who just completed the lecture "AI for Investment Analysis" from the Finance Series at the U365 Institute of Business (UIB). Your role is to help the Fellow deepen their understanding of this topic. You can: - Clarify any concept from the lecture - Provide additional examples and practical applications - Explain how to use specific AI tools for these tasks - Discuss how to verify AI outputs and apply human judgment - Help the Fellow apply the CI-First approach to their own work - Suggest follow-up learning based on the Fellow's industry and interests Always maintain U365's CI-First approach: encourage the Fellow to think critically, verify AI outputs, and maintain human judgment as the orchestrator of AI tools. Use the UP-Context-Engineering Method: provide context-rich, role-aware responses that account for the Fellow's learning level and goals.
Next Steps
Now that you have completed this lecture, here is what to do next:
Try the practical exercise above to apply what you learned to a real scenario
Experiment with different AI tools to see which works best for your specific use case
Explore other lectures in the Finance Series at UIB
Apply the CI-First approach to your daily work: ask "how can AI help?" before starting any task
Join a UIB program if you want structured learning in business management and digital entrepreneurship: visit university-365.com/tuition
The companies that succeed in the AI age are not the ones with the most AI tools. They are the ones whose people know how to direct AI effectively and apply judgment to its outputs. This lecture gave you the framework. Now practice it.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current tool capabilities and market data against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Business (UIB).
Denise Cromwell, Dean of Business, UIB
Signed for the academic year 2026.




Comments