
AI for Sales Forecasting
Updated: Oct 8

UIB University 365 Institute of Business
Series Business AI Series | Level Basic (Free)
Duration 25 minutes | Access Free
Business Management, Digital Entrepreneurship, Innovation, Finance, Leadership

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture
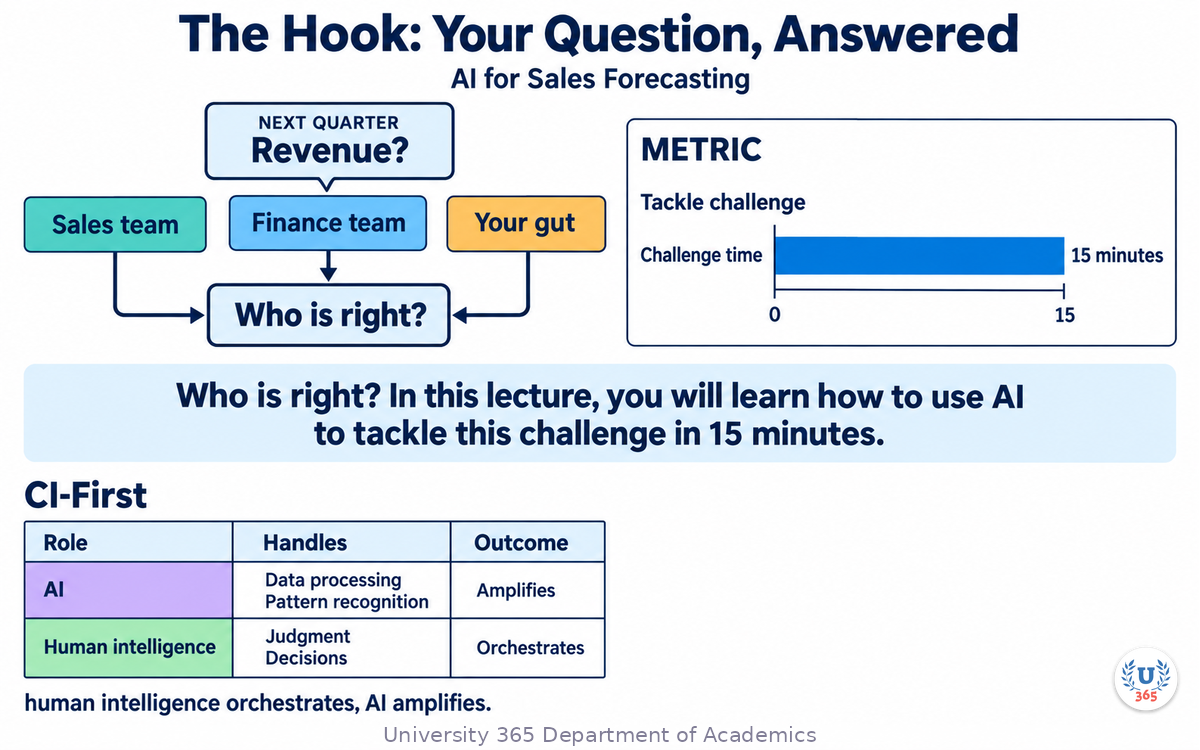
The Hook: Your Question, Answered
Your board meeting is next week. The question is simple: what will revenue be next quarter? Your sales team says one number, your finance team says another, and your gut says something different. Who is right?
In this lecture, you will learn how to use AI to tackle this challenge in 15 minutes. The AI handles the data processing and pattern recognition. You handle the judgment and decisions. This is the CI-First approach: human intelligence orchestrates, AI amplifies.

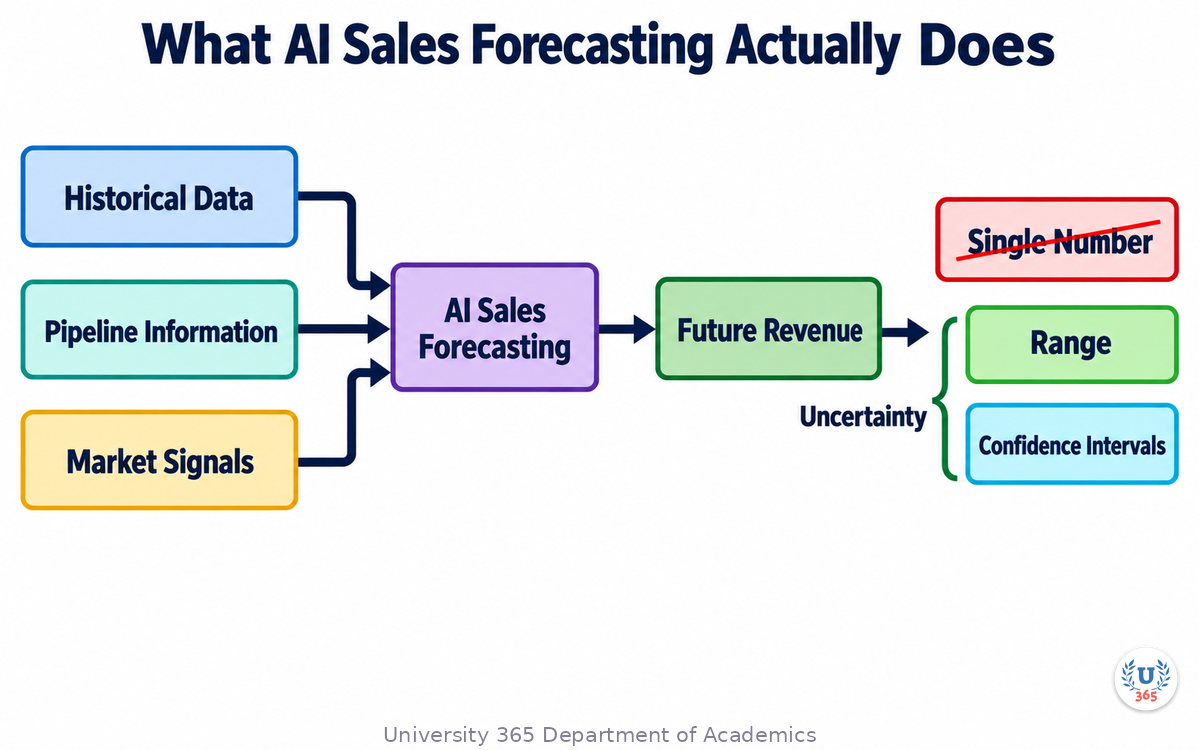
What AI Sales Forecasting Actually Does
AI sales forecasting uses historical data, pipeline information, and market signals to predict future revenue. It does not eliminate uncertainty. It quantifies it. Instead of a single number, AI produces a range with confidence intervals.
Step 1: Gather Historical Sales Data
AI needs data to learn from. The minimum is 24 months of monthly sales data. More is better. AI also needs context: what was happening in the market during each period that affected sales?
Step 2: Identify Patterns and Seasonality
AI can detect patterns that humans miss: weekly cycles, monthly patterns, seasonal trends, and annual growth rates. It separates baseline demand from seasonal fluctuations and one-time events.
Step 3: Build the Forecast Model
AI supports multiple forecasting methods: moving averages, exponential smoothing, ARIMA, and neural networks. The right method depends on your data patterns and forecast horizon.
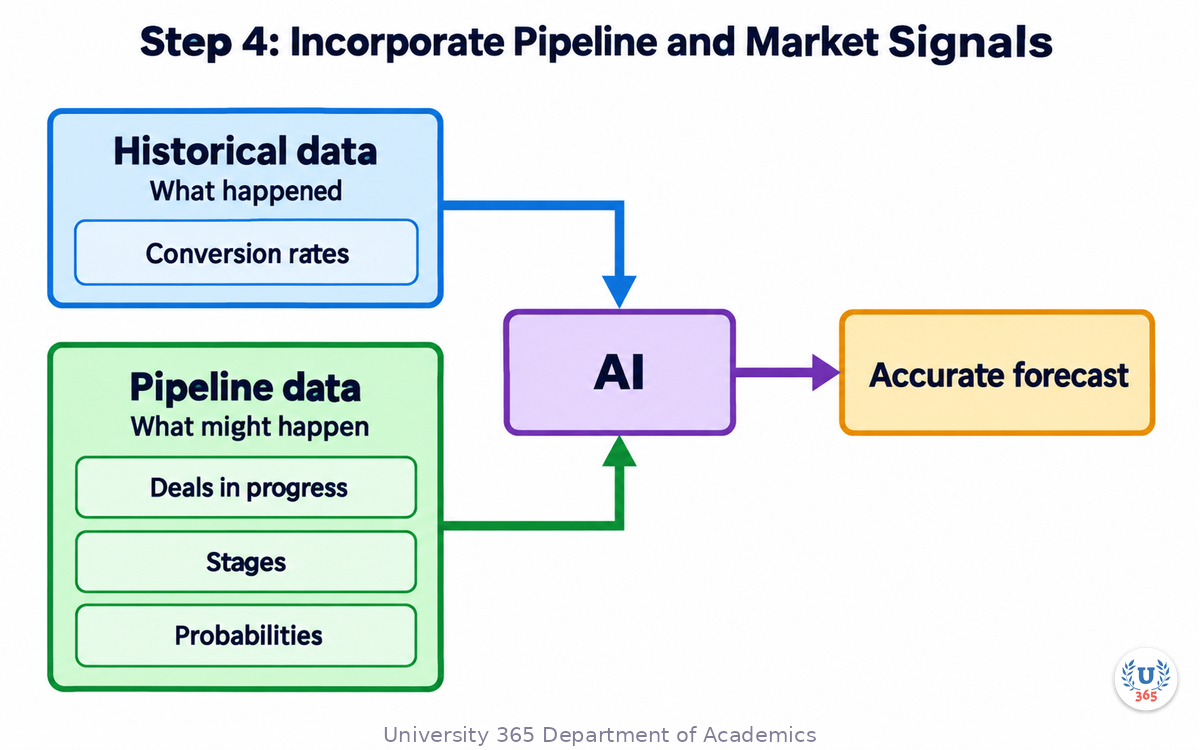
Step 4: Incorporate Pipeline and Market Signals
Historical data tells you what happened. Pipeline data tells you what might happen. AI can combine your sales pipeline (deals in progress, stages, probabilities) with historical conversion rates to produce a more accurate forecast.
Step 5: Measure and Improve Forecast Accuracy
A forecast is only valuable if it is accurate. AI can track your forecast accuracy over time, identify systematic biases (always too optimistic or too pessimistic), and auto-correct the model.
Why Forecasts Fail Before the Model Runs
Most forecast projects fail on the data rather than on the algorithm. The model is usually adequate; the inputs are not, and no amount of tuning repairs them.
Pushed deals and the end-of-quarter cliff
If the recorded close date is the date the deal was booked rather than the date the customer decided, every forecast built on it inherits the push. The symptom is a pipeline that looks strong until the last two weeks of the quarter and then moves. The repair is to record a close-date range and to treat the recorded date as an artefact of the sales process.
The surviving pipeline
Most CRM systems keep won deals and open deals and quietly lose the deals that were lost. That means the historical data you fit the model on contains only successes, and any model trained on it will be systematically optimistic. Log every closed-lost deal with its reason, and go back to reconstruct what you can.
Duplicates and the inflated pipeline
The same buyer under two account names in two regions counts twice. This is common after an acquisition, a territory change or a rep's habit of creating a new record rather than finding the old one. Enforce one account identifier and deduplicate on a schedule, because the duplicate rate drifts upward continuously.
Currency, units and product codes
Totals that silently mix currencies are the most damaging defect because they look right. Fix one reporting currency and state it. Keep a mapping table for renamed products rather than renaming, because a rename splits a product's history and the model sees a new product that never recurs.
The seasonality that three months cannot show
A model fitted on three months of data will produce a forecast with no seasonality, and the error will appear at the seasonal peak where it matters most. Twenty-four months of history is the minimum before the forecast can say anything about a seasonal pattern.
The test before you build anything
Take the last four quarters and check whether the numbers reconcile to the finance system. If they do not, the forecast will not either, and the disagreement will surface as an argument about the model when it is really an argument about the data.
Defect | Symptom | Repair |
Pushed deals | Revenue lands in the final week | Close-date ranges, not points |
Surviving pipeline | Only wins and open deals stored | Log every closed-lost with its reason |
Duplicate accounts | The same buyer counted twice | One account id, deduplicated monthly |
Mixed currency | Totals that add euros to dollars | One reporting currency, stated |
Renamed products | History split at the rename | A mapping table |
No seasonality | A forecast with a flat year | Twenty-four months minimum |
Step 1: Build the Historical Spine
Before any modelling, build the dataset that everything else will be measured against. This is unglamorous work and it determines whether the forecast is trusted.
Decide the grain first
The grain is the unit of the forecast: per rep per month, per product per region per week, per account per quarter. Choose it once and state it, because changing the grain halfway through is how a forecast ends up with numbers that cannot be reconciled to anything.
Reconcile to finance before you model
The historical spine must tie to the accounting system for the periods it covers. If the sales view and the finance view of last year differ by five percent, the forecast will be argued about in those terms forever, and the argument will not be about the forecast.
Capture the drivers, not only the outcome
Revenue alone is a weak signal. Add the things that move it: number of qualified opportunities, average deal size, win rate by stage, sales-cycle length, marketing spend, headcount, and the seasonality of the customer's own buying pattern. A forecast built only on revenue history is a forecast that cannot explain itself.
Record the losses with reasons
Closed-lost deals with a reason code are the most under-used dataset in most sales organisations. They tell you which deals never had a chance, which is the information a forecast needs to avoid counting them.
Freeze and version the dataset
Date the spine and freeze it for the modelling work. When the forecast is challenged in three months, you need to know exactly which data produced it. A live, continuously updated history makes the result irreproducible.
One grain, chosen and stated
Reconciled to finance for every historical period
Drivers recorded alongside revenue
Closed-lost deals with reasons
Dataset dated, frozen and versioned
Step 2: Three Forecasts, Not One
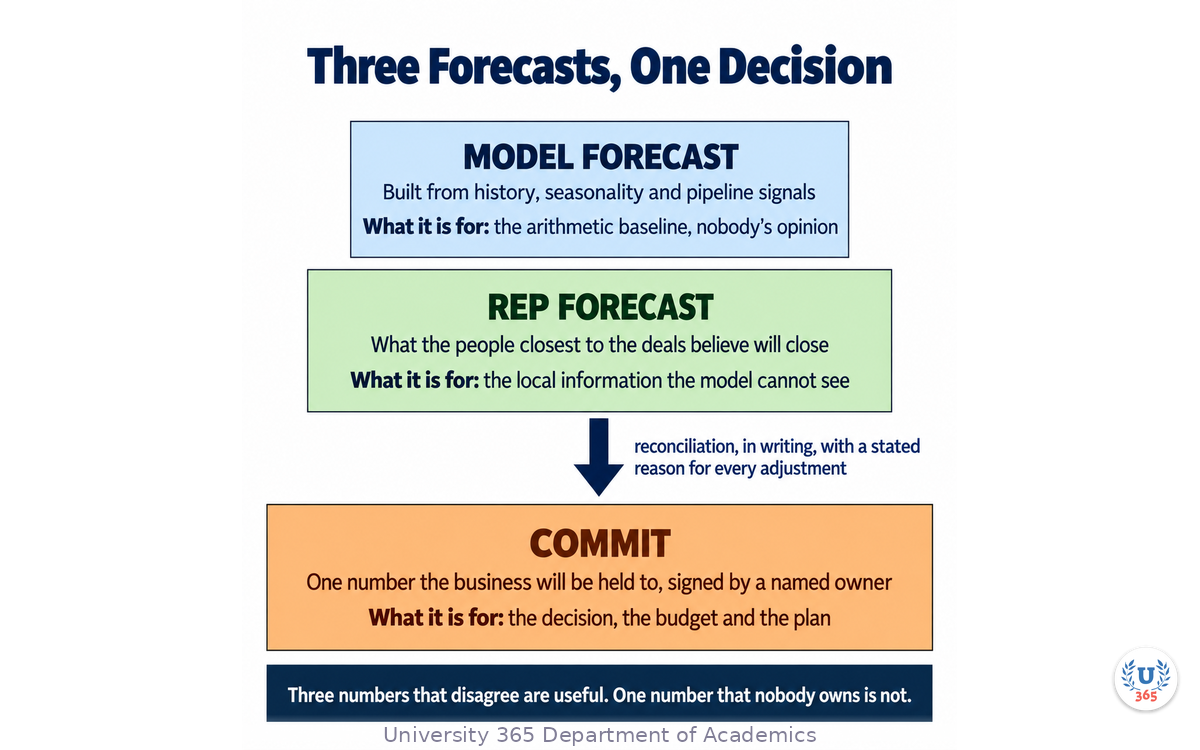
The most common structural mistake is producing a single number and arguing about it. A useful forecasting process produces three numbers and reconciles them in writing.
The model forecast
Built from history, seasonality and pipeline signals. It is the arithmetic baseline and it contains nobody's opinion. Its value is that it is the same every month if the inputs are the same, which makes it a fixed reference for the argument.
The rep forecast
What the people closest to the deals believe will close. It contains local information the model cannot see: a budget cycle, a champion leaving, a competitor's price move, a legal review that is stalling. It is also systematically biased, usually upward, and the bias is consistent enough to be corrected for.
The commit
One number the business will be held to, owned by a named person. This is the forecast that reaches the board and the budget, and it must have an owner. A commit that belongs to a committee has no owner and therefore no accountability when it is wrong.
Reconciliation is the work
The value of the process is the reconciliation: every adjustment between the model forecast and the commit carries a stated reason and a name. Over a few quarters, the pattern of adjustments becomes information in itself. A team that consistently adjusts upward and consistently misses is telling you something about its incentives, not about its forecast.
Score all three
Track the accuracy of each forecast separately. The model's error tells you about the data. The reps' error tells you about the incentives. The commit's error tells you about the process. A team that only scores the commit learns nothing about which part to fix.
Forecast | Built from | Failure mode |
Model | History, seasonality, pipeline signals | Misses local information |
Rep | Local knowledge of the deals | Systematically optimistic |
Commit | Reconciled judgement, owned | An owner who is not there when it misses |
Step 3: Choose the Simplest Method That Beats the Baseline
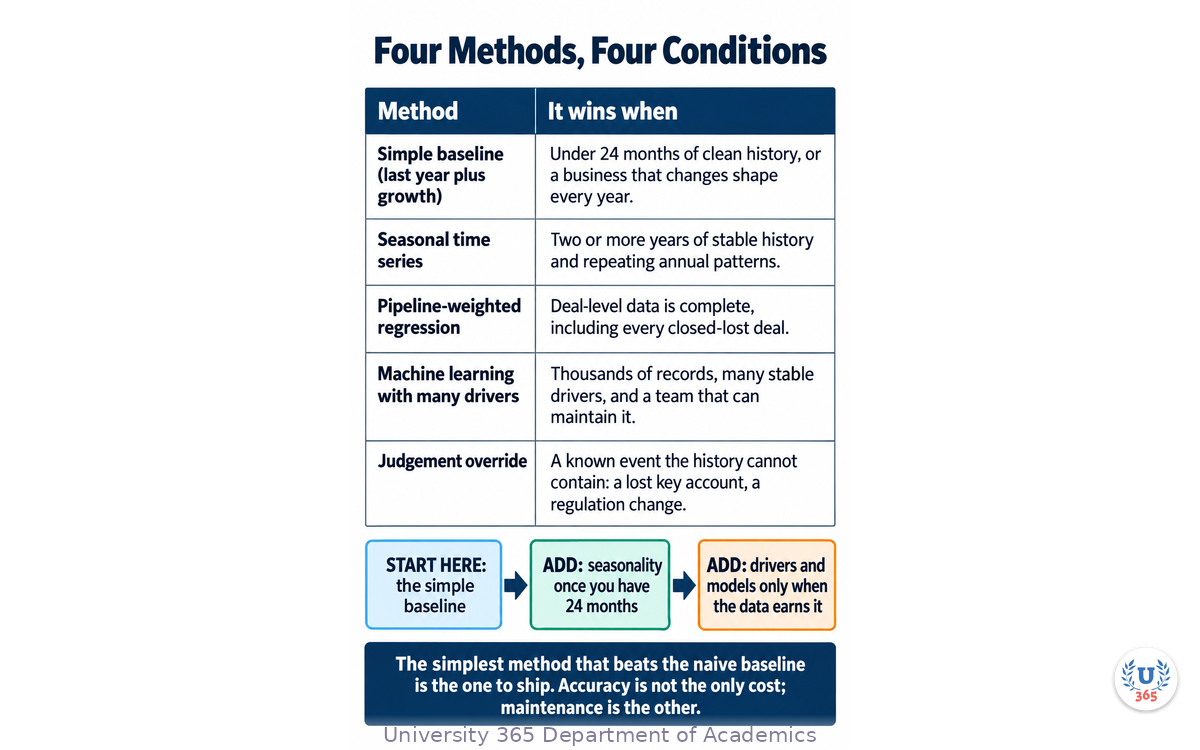
Every forecasting conversation should begin with the naive baseline, which is simply last year's same month, or last month, carried forward. If your method cannot beat it, you are paying for a number that is worse than the one you already had.
The simple baseline
Last year plus a growth factor. It wins when you have under twenty-four months of clean history or when the business changes shape every year, which describes most small and mid-sized sales organisations. It is also the honest starting point, because a more complex method can only claim a victory relative to it.
Seasonal time series
Once you have two or more years of stable history with repeating annual patterns, a seasonal method will usually beat the baseline, and it will do so with a small number of parameters that you can explain to a sceptical sales director. Explainability matters here more than in many modelling problems, because the forecast is used in arguments about targets and compensation.
Pipeline-weighted regression
This is where the deal-level data earns its cost. Weight the pipeline by stage-specific conversion rates and add the drivers identified in the historical spine. It wins when the deal data is genuinely complete, which means every closed-lost deal is present. Built on a surviving pipeline, it will be systematically over-optimistic and will look excellent in backtests.
Machine learning with many drivers
This wins when you have thousands of records rather than hundreds, many stable drivers, and a team that can maintain it. The last condition is the one usually omitted. A model that requires the original builder to maintain it becomes an abandoned asset the moment that person changes role, and the forecast silently degrades.
Judgement override, used deliberately
There will always be events the history cannot contain: an account lost, a regulation changed, a competitor exiting. These should be applied as a documented override with a named owner and a written reason, not blended into the model where they become invisible. An override that turns out to be wrong should be as visible as one that turns out to be right.
The cost of complexity
Accuracy is not the only cost of a method. Maintenance, explanation and the ability to hand it over are the others. A slightly less accurate method that a sales director can understand and that a different analyst can maintain is worth more than a marginally better one that dies when its author moves on.
Method | It wins when | Main failure mode |
Simple baseline | Under 24 months of clean history | Misses turning points |
Seasonal time series | Two or more years of stable history | Breaks when the business changes shape |
Pipeline-weighted regression | Complete deal data including losses | Optimism if losses are missing |
Machine learning | Thousands of records, a maintainer | Abandoned and degrading silently |
Judgement override | A known event history cannot contain | Undocumented overrides |
Step 4: Measure Accuracy Honestly
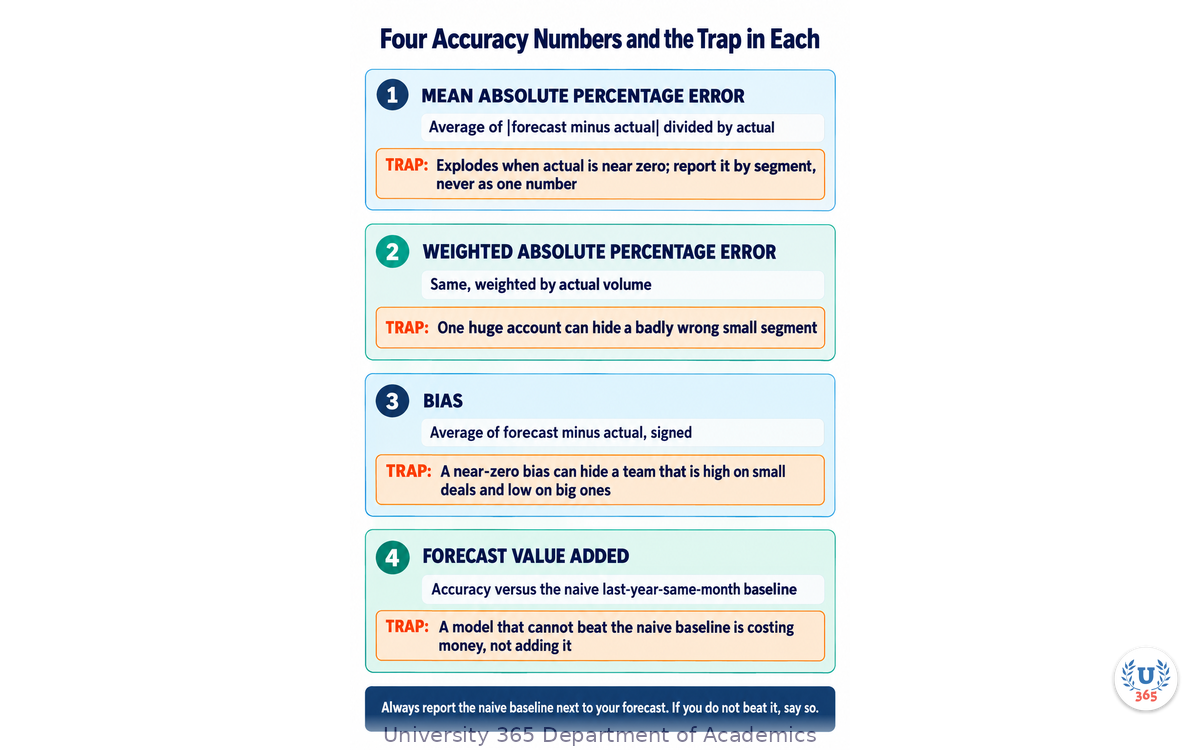
A forecast nobody scores is a forecast nobody improves. Four numbers cover the ground, and each one has a trap.
Mean absolute percentage error
The average of the absolute error divided by the actual, expressed as a percentage. It is the most used and the most misused, because it explodes when the actual is near zero. Report it by segment rather than as a single figure for the whole business, or a small segment with a tiny denominator will dominate the number without meaning anything.
Weighted absolute percentage error
The same measure weighted by the actual volume, which stops small segments dominating. Its trap is the reverse: one very large account can make a badly wrong small segment invisible, so use it alongside the unweighted version rather than instead of it.
Bias
The signed average of the error. This is the measure that tells you which direction you are systematically wrong in, and it is the one sales organisations most often ignore, because an upward bias is uncomfortable to report. Its trap is that a near-zero overall bias can hide a team that is consistently high on small deals and consistently low on large ones.
Forecast value added
The comparison of your forecast against the naive baseline. This is the measure that justifies the work. A model that cannot beat last year's same month is not adding value, whatever its percentage error looks like in isolation. Always report the baseline alongside the forecast, so the comparison is visible rather than implied.
Score at the grain you forecast at
If you forecast per rep, score per rep. National accuracy can be excellent while half the regions are badly wrong in offsetting directions, and the national number will hide it while the individual plans absorb the damage.
Keep the scorecard simple
Four numbers, by segment, published every month. A scorecard with twenty metrics will not be read, and a scorecard that is not read does not change behaviour.
Metric | What it tells you | The trap |
Mean absolute percentage error | Typical error size | Explodes near zero |
Weighted absolute percentage error | Error weighted by volume | Hides small segments |
Bias | Which direction you are wrong | Aggregates hide offsetting errors |
Forecast value added | Whether the work beats the baseline | Needs the baseline reported |
Step 5: The Human Layer
A forecast is used by people whose performance is measured against it. Ignoring that produces a technically correct model and a forecast nobody trusts.
Never let the forecast set the target
If the forecast directly determines the target, the people producing the inputs will learn to produce a number that produces a comfortable target. Separate the two, or accept that the forecast is really a negotiation instrument and stop calling it a forecast.
Reward accuracy, not optimism
If forecast accuracy is not measured and rewarded, the incentive is to be optimistic, because optimism is pleasant and its cost is deferred. Publish the accuracy of each forecast and treat it as a professional skill, not an administrative task.
Give the reps a reason to be honest
A rep who reports a deal as unlikely and is then challenged on every such report learns to keep the number and stay silent. Ask what has changed, not what will close, and record the answer without arguing with it. The forecast is only as honest as the conversation that produces it.
The override register
Every manual adjustment to the model forecast carries a name, a date and a reason. The register is how you learn whether your judgement adds or subtracts value over a year. Most teams that keep one discover their overrides cost more accuracy than they add, which is a finding worth having.
Communicate uncertainty in language people use
A single number implies a precision that does not exist. Give a range and a confidence, and say what would move the outcome: two enterprise deals landing a month early, one major renewal slipping a quarter. Uncertainty stated in the language of the business is more useful than a confidence interval in a footnote.
Forecast and target are separate processes
Accuracy is measured and rewarded, per forecast
Ask what changed, not what will close
Every override has a name, a date and a reason
State a range and what would move it
Reader Exercise: Score Your Own Last Forecast
The fastest way to learn this material is to score a forecast you have already made. You have the data and you have the history, and the exercise will take under an hour.
Step 1: Recover the forecast and the actual
Take your most recent forecast, in whatever form it existed, and the actual result for the same period. If the forecast was never written down, that is the first finding, and it is a significant one.
Step 2: Compute the naive baseline
Take the same period last year and the same period's growth. This is what you would have forecast with no model at all. Compare it to your actual forecast and to the result.
Step 3: Compute the four numbers
Absolute percentage error, the volume-weighted version, the signed bias, and the difference from the naive baseline. Four numbers, twenty minutes, and they will tell you more about your process than any modelling discussion.
Step 4: Find where the error lives
Break the error by rep, by product and by month. Almost always the error is concentrated rather than evenly spread, and the concentration points at a specific cause: one deal that did not land, one segment where the seasonality is different, one month where the process breaks.
Step 5: Write one change
One change to the process, not five. Add the closed-lost reasons, or fix the currency, or start scoring the model separately from the commit. A single sustained change to a forecasting process is worth more than a comprehensive redesign that is abandoned in a quarter.
Step | Output |
Recover forecast and actual | Whether the forecast was ever written down |
Compute the naive baseline | What you would have had with no model |
Compute the four numbers | Error, weighted error, bias, value added |
Break the error down | Where the error concentrates |
Write one change | A single sustained improvement |
Run this exercise twice and you will have a view of your forecasting process that is grounded in your own numbers rather than in a vendor's case study.
The Monthly Cycle: Running It So It Actually Happens
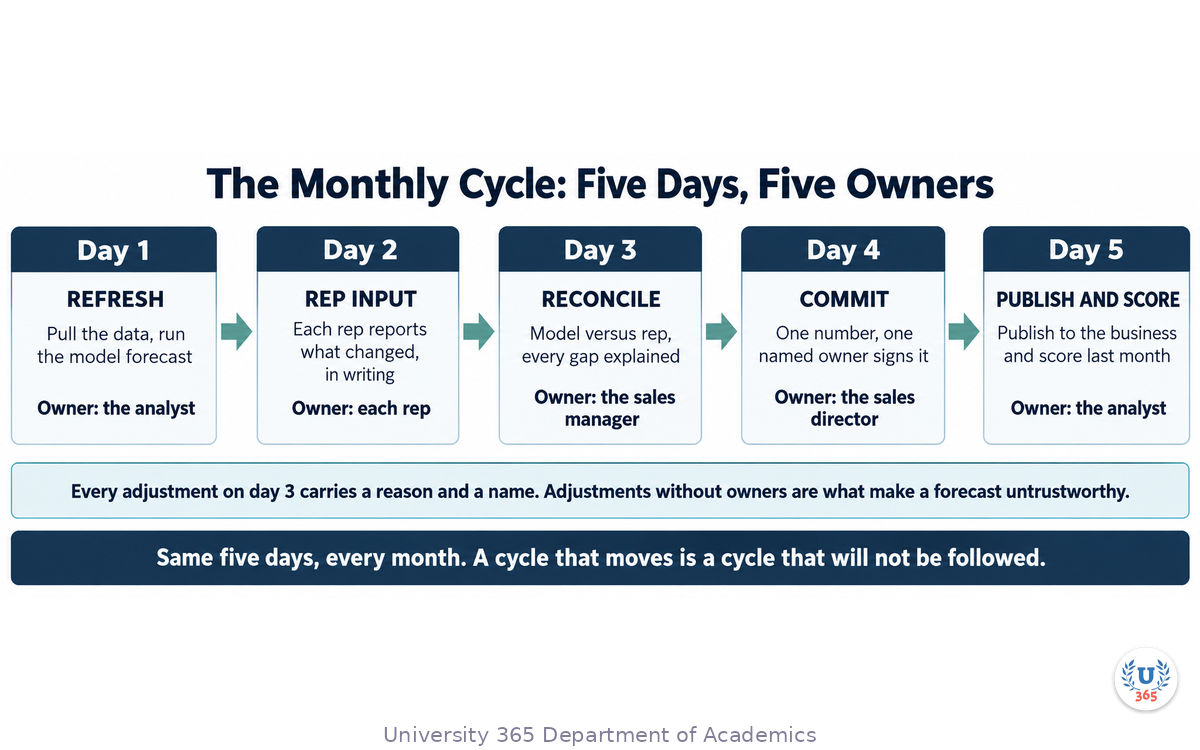
A forecasting process is a calendar before it is a model. If the cycle is not fixed, the forecast arrives when it is ready, which means it arrives after the decision it was meant to inform.
Day one: refresh and model
The analyst pulls the data and runs the model forecast. The output is the arithmetic baseline, published internally on day one so that everyone is working from the same reference before opinions are heard.
Day two: rep input, in writing
Each rep reports what changed, in writing, with the reason. Not a revised number alone: the change and the cause. Written input matters because a verbal conversation about a deal produces a different recollection in every participant a week later.
Day three: reconciliation, with every gap explained
The manager reconciles the model forecast against the reps' view and requires a stated reason for every adjustment. This is the day that makes the process worth running, and it is the day that gets skipped when the quarter is busy. Skipping it removes the only step that turns three numbers into one decision.
Day four: the commit
One number, signed by a named owner. The number goes to the business with the material assumptions attached: the two or three things that must happen for it to be right. A commit presented without its assumptions cannot be managed, only missed.
Day five: publish and score
Publish to the business and score last month's forecast against the four accuracy numbers. Scoring on the same day every month is what keeps the process honest, because a scorecard that arrives late is a scorecard that was edited.
Why the fixed calendar matters more than the model
Teams with a mediocre model and a fixed calendar forecast better than teams with an excellent model and a fluid process, because the calendar produces the data the model needs and the reconciliation that catches the model's blind spots. The calendar is the infrastructure.
Day | Activity | Owner |
1 | Refresh the data, run the model | Analyst |
2 | Rep input in writing, change and cause | Each rep |
3 | Reconcile, every gap explained | Sales manager |
4 | Commit, one number, named owner | Sales director |
5 | Publish and score last month | Analyst |
Forecasting Under Real Uncertainty
Most forecasting teaching assumes a stable business. Most real forecasting happens while something is changing underneath it, and the method has to survive that.
When the history stops being relevant
A new market, a competitor exit, a regulatory change, a large customer lost. In these conditions, the historical pattern is not evidence about the future, and a model fitted on it will be confidently wrong. The correct response is to say so, fall back to the naive baseline, and apply a documented judgement override with a named owner.
Scenario forecasting instead of point forecasting
When the uncertainty is structural, produce three scenarios with a probability attached to each rather than one number. The value is not the probabilities, which are guesses; it is that the exercise forces the assumptions into the open, where they can be argued about individually instead of as a single contested total.
Leading indicators, used carefully
In unstable conditions, indicators that move before revenue become more valuable: qualified opportunity creation, trial signups, website enquiries from target accounts, sales-cycle stage transitions. They are noisy and they must be validated against outcomes, but they are the only current information available when the history has stopped predicting.
The honest statement
It is legitimate to tell a board that the forecast confidence this quarter is low and why. It is much better than presenting a point forecast with false precision, because the false precision will be discovered and the credibility cost falls on the next forecast as well.
Building the range into the plan
Where confidence is low, plan against the lower end and manage the upside as opportunity rather than committing to the upper end. This sounds conservative and it is; the alternative is committing to a number the business does not believe and then spending the quarter explaining.
Say when the history has stopped being relevant
Three scenarios, with the assumptions exposed
Leading indicators, validated against outcomes
State the confidence level explicitly
Plan to the lower end when confidence is low
Five Forecasting Traps at Scale
The defects that matter change as the organisation grows, and the ones that were harmless at twenty reps become structural at two hundred.
1. The forecast that becomes the target
At small scale the two can be the same number without much harm. At scale the coupling teaches three hundred people to manipulate the input. Separate them, or accept that the number is a commitment device and score it as one.
2. The aggregate that hides the segment
National accuracy of two percent looks excellent. If one region is twenty percent high and another is twenty percent low, the national figure is a coincidence and both regions are being managed badly. Always score at the grain you forecast at.
3. The single owner of a distributed process
One analyst owning the forecast for two hundred reps produces a process that cannot scale, because the analyst becomes the bottleneck for every input and every reconciliation. Distribute the input, centralise the method.
4. The model nobody maintains
A machine learning forecast built by someone who then changes role will degrade silently. Either keep a maintainer named and funded, or choose a simpler method that a generalist analyst can run. Degradation is invisible from the outside until it has been wrong for two quarters.
5. The unmeasured override
Manual adjustments scale faster than anything else, because every manager has a reason and no manager has to defend it. At scale the overrides can swamp the model. The override register is the control: name, date, reason, and a score against the outcome six months later.
The pattern behind all five
Every trap is a coupling problem. The forecast is coupled to the target, the aggregate is coupled to the segments, the method is coupled to one person, the model is coupled to its author, the adjustments are coupled to nobody. Decoupling is the work of scaling a forecasting process.
Trap | Small scale | At scale |
Forecast equals target | Harmless | Three hundred people manipulating the input |
Aggregate accuracy | Coincidence passes | Offsetting regional errors hidden |
One owner | Manageable | The analyst becomes the bottleneck |
Unmaintained model | Rarely matters | Degrades silently for two quarters |
Unmeasured overrides | A few adjustments | Overrides swamp the model |
The Forecast Review Meeting: Running It Without a Fight
The monthly review is where a forecasting process either earns its credibility or loses it. Most reviews turn into an argument about the number, which is the one thing the process was built to prevent.
Review the variance, not the number
Start from the reconciliation: which adjustments were made on day three, by whom, and on what evidence. The question is not whether the commit is high or low. It is whether the gap between the model and the commit was justified, and whether the justifications last month turned out to be correct.
Score the previous month first
Open with last month's accuracy. Doing the scoring at the start of the meeting, rather than in a separate report, makes accuracy the frame for everything else. A team that never sees its own error rate in the room will not improve it.
Separate the three forecasts in the discussion
If the model is high and the reps are low, that is information about the pipeline data. If it is the reverse, that is information about the reps' incentives. Discussing the three numbers separately produces a diagnosis; discussing one number produces a negotiation.
Ask what changed, not what will close
The question that produces honest information is what changed since last month and why. The question that produces optimism is what will close. Use the first, and record the answers without arguing with them, because an argued answer stops being given.
End with one change
Every review should end with one change to the process, written down with an owner. A review that ends with a resolved disagreement ends with nothing that persists. A review that ends with one process change compounds into a materially better forecast within a year.
Keep it to an hour
A review that runs to three hours will be cancelled within a quarter. An hour, with the variance analysis prepared in advance, is enough to score, diagnose and decide.
Agenda item | Time | Purpose |
Score last month | 10 minutes | Make accuracy the frame |
Variance and adjustments | 20 minutes | Check the justification, not the number |
Three forecasts compared | 15 minutes | Diagnose which part is failing |
What changed since last month | 10 minutes | Current, honest information |
One process change | 5 minutes | Something that compounds |
The Tooling Landscape in 2026, and How to Choose
The tools changed quickly and will change again. The selection criteria are more stable than the products, so choose on the criteria and re-evaluate the products annually.
The four categories you will actually see
The spreadsheet with an add-in, which is where most organisations start and where a surprising number stay because it is maintainable and understood. The dedicated forecasting module inside a CRM or ERP, which is limited but integrated. The cloud forecasting service, which is capable and requires a data pipeline to feed it. The in-house model built on your own data, which is the most capable, the most expensive, and the one that dies when its builder leaves.
The criteria that matter
Whether it can be handed over, which is the criterion most often ignored and the one that decides whether the forecast survives a year. Whether the error is explainable, because a forecast used in target-setting must be defensible. Whether it can handle your grain and your seasonality. Whether the data pipeline it needs is one you can maintain.
The criterion that does not matter much
Absolute accuracy in a backtest. A vendor will demonstrate a lower error rate on a prepared dataset than your own approach achieves on your own data, and the comparison rarely survives contact with your pipeline. Require a trial on your data and score it against your own naive baseline, in your own environment.
When to build in-house
Build in-house when the forecast is a genuine competitive differentiator and you have a maintainer who will stay. Buy when the forecast is infrastructure, which is most of the time. The mistake in both directions is symmetrical: building something that should have been bought, and buying something that needed to be part of your product.
The re-evaluation cadence
Re-evaluate the tool annually against the same six criteria, using your own baseline as the benchmark. A tool that was adequate two years ago may now be the constraint on your accuracy, and the only way to know is to measure it the way you measure the forecast itself.
Can it be handed over to a different analyst
Is the error explainable to a sales director
Does it handle your grain and your seasonality
Can you maintain the pipeline it needs
Trial it on your data, against your own baseline
Forecasting as a Competence, Not a Report
The organisations that forecast well treat it as a skill the business develops, rather than a report that arrives on the twentieth of the month.
The three capabilities that make it a competence
A clean dataset someone owns. A method that can be explained. A cycle that runs on a calendar. None of the three is glamorous and any one missing reduces the whole to guesswork with a spreadsheet attached.
Why the scorecard is the centre of it
A monthly scorecard, by segment, with the naive baseline beside it, is the single artefact that turns forecasting into an improving practice. Without it the process produces numbers; with it the process produces learning. Teams that keep one for a year are measurably better than teams that do not, and the improvement comes from the discussions the scorecard forces rather than from any change in modelling.
Where AI fits, without overselling it
AI removes the extraction and assembly work that consumes most of a forecasting analyst's month, and it makes it feasible to maintain a cleaner dataset. It does not repair bad inputs, does not choose the method for you, and does not make a forecast true. What it does is give the analyst the time to do the parts that require judgement, which is the same effect it has in every other lecture in this series.
The realistic improvement curve
Expect the first two quarters to produce no accuracy improvement at all, because the work is building the spine and agreeing the cycle. Expect the third and fourth quarters to produce a visible improvement, and expect the source of it to be the data work rather than the model. Organisations that expect an improvement in month one abandon the programme before it can work.
What to do next in your own organisation
Recover your last forecast, score it against the naive baseline, break the error down by segment, and write one change. Then run the cycle for three months with no model change at all and see what the discipline alone produces. Most teams find that the cycle, not the algorithm, was the missing piece.
Quarter | Expect | Where the improvement comes from |
1 | No accuracy change | Building the spine, agreeing the cycle |
2 | No accuracy change | Fixing data defects, starting to score |
3 | Visible improvement | Better inputs reaching the same model |
4 | Compounding improvement | Method choices justified by measured error |
A forecast is a decision instrument. Everything in this lecture exists to make that instrument trustworthy enough that people will act on it, and the discipline that does that is ordinary, cumulative and undramatic.
Feynman Summary: Explain It Like You Are 12
Imagine you have a problem to solve at work. It usually takes a long time and a lot of effort. Now imagine you have a super-smart robot friend who can do the boring parts in seconds.
That is what AI does for sales forecasting. The robot reads all the information, finds the patterns, and shows you the results. You look at what the robot found and decide what to do.
The robot does not make the final decision. You do. The robot just does the hard work of gathering and organizing information so you can focus on thinking and deciding.
That is the CI-First way: you are the boss, the AI is your helper. Together, you get better results faster.
Mindmap: The Complete Picture
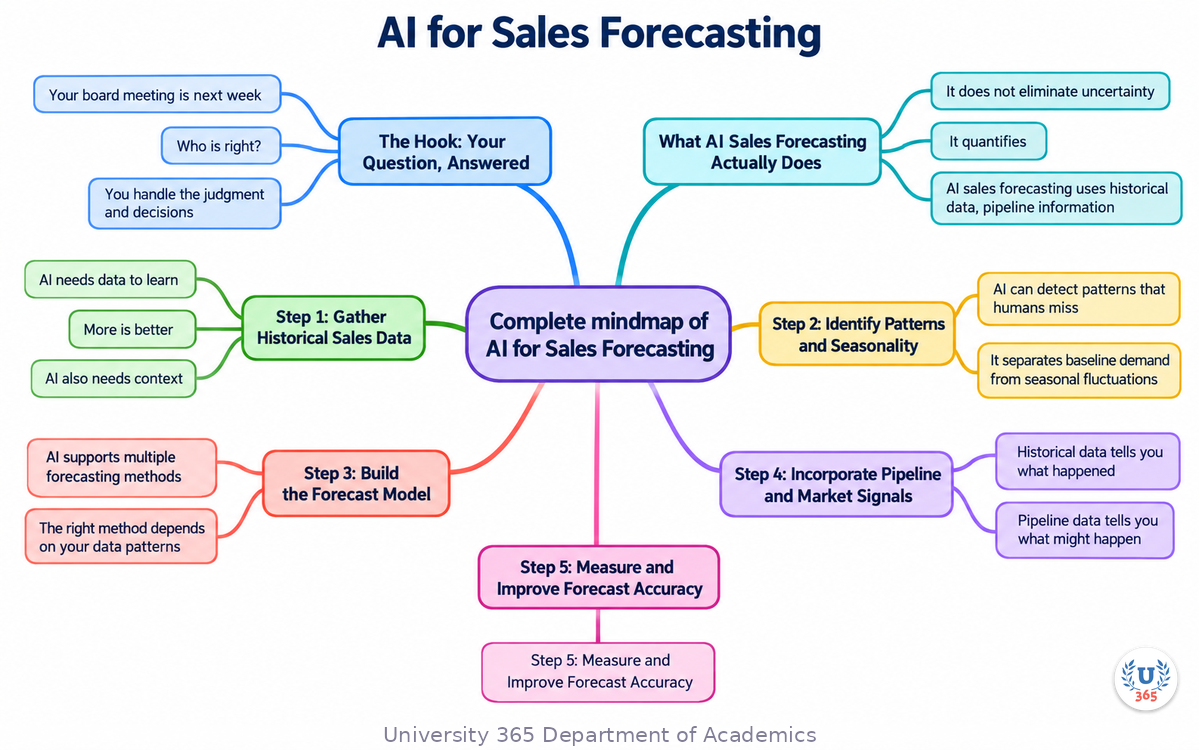
The mindmap shows the complete workflow: defining your objective leads to gathering and preparing data, which feeds into AI analysis and processing, which produces insights and recommendations, which you validate with human judgment before taking action. The CI-First principle wraps the entire process: you start with human-defined goals and end with human-validated decisions.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Apply What You Learned
Exercise: 15-Minute Application Sprint
Identify a real scenario: Think of a situation in your work or business where this topic applies.
Define your objective: What specific outcome do you want to achieve in 15 minutes?
Use an AI tool: Open ChatGPT, Claude, or Gemini and apply the framework from this lecture.
Analyze the output: Did AI produce useful results? What needs verification? What needs human judgment?
Make a decision: Based on AI output plus your judgment, what action will you take?
What to Look For
Did AI produce specific, actionable output or generic statements? Generic output means your prompt needs more context.
Did AI invent any data or make unsupported claims? Always verify critical facts against primary sources.
What would you do differently from what AI suggested? The gap between AI output and your judgment is where your value lies.
The CI-First formula is CI = HI + (AI x HI). Your intelligence is the foundation. AI multiplies it. But the final decision is yours.
Applied AI Connection
This exercise demonstrates the CI-First workflow in practice. You defined the objective (human intelligence). AI processed and analyzed (AI amplification). You validated and decided (human intelligence). The speed gain from AI lets you iterate faster and explore more options than you could manually.
Glossary
Term | Definition |
Sales Forecasting | The process of predicting future revenue based on historical data, pipeline analysis, and market signals. |
Time Series Analysis | Statistical methods for analyzing data points collected over time to identify trends, cycles, and seasonality. |
Seasonality | Regular, predictable patterns in sales data that repeat at fixed intervals (weekly, monthly, quarterly, annually). |
ARIMA | AutoRegressive Integrated Moving Average: a time series forecasting method that models autocorrelation in data. |
Pipeline Conversion Rate | The percentage of deals at each stage of the sales pipeline that progress to the next stage. |
Confidence Interval | A range of values that likely contains the true value, with a stated probability (e.g., 95% confidence). |
Forecast Accuracy | How close a forecast prediction is to the actual result, typically measured as MAPE or MAE. |
MAPE | Mean Absolute Percentage Error: the average percentage difference between forecasted and actual values. |
CI-First | Co-Intelligence First: the U365 principle that human intelligence orchestrates and AI amplifies. |
5M2S | 5 Minutes to Success: the U365 principle of using AI to compress time-intensive tasks into minutes. |
UNOP | University 365 Neuroscience-Oriented Pedagogy: the pedagogical framework behind all U365 lectures. |
Exponential Smoothing | A forecasting method that gives more weight to recent data points and less to older ones. |
Quiz: TEST YOUR UNDERSTANDING
1. What is the minimum historical data recommended for AI sales forecasting?
A) 24 months of monthly sales data
B) 1 month
C) 5 years
D) No historical data needed
2. What does AI detect in sales data that humans might miss?
A) Weekly cycles, monthly patterns, seasonal trends, and annual growth rates
B) Employee names
C) Office locations
D) Product colors
3. What does a confidence interval tell you?
A) A range of values that likely contains the true value with a stated probability
B) How confident the sales team feels
C) The maximum possible revenue
D) The minimum acceptable revenue
4. Why should you incorporate pipeline data into your forecast?
A) It shows what might happen based on deals in progress and their conversion probabilities
B) It replaces historical data entirely
C) It is required by accounting standards
D) It makes the forecast 100% accurate
5. What should you do if your forecast consistently overestimates revenue?
A) Track the bias and auto-correct the AI model to adjust for systematic optimism
B) Fire the sales team
C) Ignore the forecast entirely
D) Only forecast pessimistic scenarios
Answers: 1-B, 2-B, 3-B, 4-B, 5-B
Related Resources
U365 INSIDE Publications
Book Essential: Co-Intelligence by Ethan Mollick: The Centaur model and human-AI collaboration
Lecture 1: AI for Market Research: First lecture in the Business AI Series
External Resources
Harvard Business Review: AI in Business: How AI is transforming business operations: hbr.org
McKinsey: The State of AI: Annual report on AI adoption: mckinsey.com
Stanford AI Index: Annual report on AI progress and adoption: aiindex.stanford.edu
Related U365 Lectures (Coming Soon)
Other lectures in the Business AI Series at UIB
Cross-institute lectures on AI applications
U.Copilot for This Lecture
Discuss this lecture with U.Copilot, your AI chat companion trained on this content.
Copy and paste the following prompt into the U.Copilot chat on university-365.com:
You are U.Copilot for Lectures, an AI chat companion specially trained on University 365 lecture content. You are helping a Fellow who just completed the lecture "AI for Sales Forecasting" from the Business AI Series at the U365 Institute of Business (UIB). Your role is to help the Fellow deepen their understanding of this topic. You can: - Clarify any concept from the lecture - Provide additional examples and practical applications - Explain how to use specific AI tools for these tasks - Discuss how to verify AI outputs and apply human judgment - Help the Fellow apply the CI-First approach to their own work - Suggest follow-up learning based on the Fellow's industry and interests Always maintain U365's CI-First approach: encourage the Fellow to think critically, verify AI outputs, and maintain human judgment as the orchestrator of AI tools. Use the UP-Context-Engineering Method: provide context-rich, role-aware responses that account for the Fellow's learning level and goals.
Next Steps
Now that you have completed this lecture, here is what to do next:
Try the practical exercise above to apply what you learned to a real scenario
Experiment with different AI tools to see which works best for your specific use case
Explore other lectures in the Business AI Series at UIB
Apply the CI-First approach to your daily work: ask "how can AI help?" before starting any task
Join a UIB program if you want structured learning in business management and digital entrepreneurship: visit university-365.com/tuition
The companies that succeed in the AI age are not the ones with the most AI tools. They are the ones whose people know how to direct AI effectively and apply judgment to its outputs. This lecture gave you the framework. Now practice it.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current tool capabilities and market data against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Business (UIB).
Denise Cromwell, Dean of Business, UIB
Signed for the academic year 2026.




Comments