
Nova Premier: Amazon's retired million-token teacher, and what to move to

Status: Retired | Last tested: 2026-11-20 (Nova Premier, amazon.nova-premier-v1:0, released 2025-04-30) | Re-check: trigger-based, end of life 2026-09-14
Retired: the tool still works but is no longer recommended. See the Migration Path section.
For detailed explanations of the CI-First evaluation terms used in this review, including the Humics Protection Badge and the AI Imposture Risk levels, see the Glossary at the end of this post.

In this Tool Review

Nova Premier
The id, the name, and the four models this review is not
Five strings circulate for this product and its neighbours, and they do not do the same job.
Name | What it is | Where it appears |
Nova Premier | The product name. Amazon's most capable first-generation Nova understanding model, and its teacher model for Bedrock Model Distillation | The launch note of 2025-04-30, the Nova 1 user guide, the technical report addendum |
amazon.nova-premier-v1:0 | The callable model id on bedrock-runtime | The Bedrock model card and every Bedrock sample |
us.amazon.nova-premier-v1:0 | The Geo cross-Region inference id. There is no global. id and no separate in-region route | The model card's programmatic access table and the regional availability page |
Nova Premier, as a model attribute | The billing name on 14 SKUs of the Bedrock us-east-1 offer file | The price list, published 2026-11-11 |
Nova 2.0 Lite, Nova 2.0 Pro, Nova 2.0 Omni | The next generation, announced 2025-12-02. Different models, different evidence, different reviews | The Nova 2 launch note and their own posts |
This is a new review, not a re-score. No U365 Tools record carries an Amazon Nova Premier row, no live Tools post covers it, and no local review document exists for this model. The three Nova 2 reviews published in November 2026 cover Nova 2 Lite, Nova 2 Pro and Nova 2 Omni, each a different generation and a different tier.
Nova Premier and Nova Pro are first-generation models, not Nova 2 variants. They were announced at re:Invent 2024 and shipped in 2024 and 2025. A reader who meets the name "Nova Pro" beside "Nova Premier" is looking at two tiers of the same generation: Premier at 1M tokens of context and a flagship price, Pro at 300K tokens and a mid-tier price. Nova Pro has its own card in this campaign and its own review. Its price, its context window and its lifecycle are not carried here.
The lifecycle record disagrees with itself, and the disagreement is the first finding. The Bedrock model card for Nova Premier, read on 2026-11-20, states a launch date of 2025-10-31 and an EOL floor of 2026-10-31, then states an EOL date of 2026-09-14 and a lifecycle of Legacy. The AWS What's New announcement for the model is dated 2025-04-30, the technical report addendum is dated 2025-04-30, and Artificial Analysis publishes 2025-04-30 as the release date. The announcement and the independent record agree on 2025-04-30; the card's date field is the outlier, and it is the field that matters least, because the card's own EOL date has already passed.
What this review is not. It is not a review of Amazon Bedrock as a platform, of Nova 2 Lite, Nova 2 Pro, Nova 2 Omni or Nova Pro, or of Bedrock Model Distillation as a service. It is not a buying guide for a model that cannot be adopted. It is a scored snapshot of a retired flagship, with the migration written out, because a reader who still runs it needs both.

Nova Premier
Tool Snapshot
Nova Premier, Amazon's retired first-generation flagship: a 1M-token multimodal reader that led the Nova family on document, chart and long-video work, came with no reasoning switch and no structured outputs, and now carries a published end of life that has passed.
Category: Applied AI / Hosted large language model, built for complex tasks: long documents, long videos, large codebases, multi-step agentic workflows, and use as the teacher model in Bedrock Model Distillation. It is the top tier of the first Nova generation, not of the second.
Primary use cases:
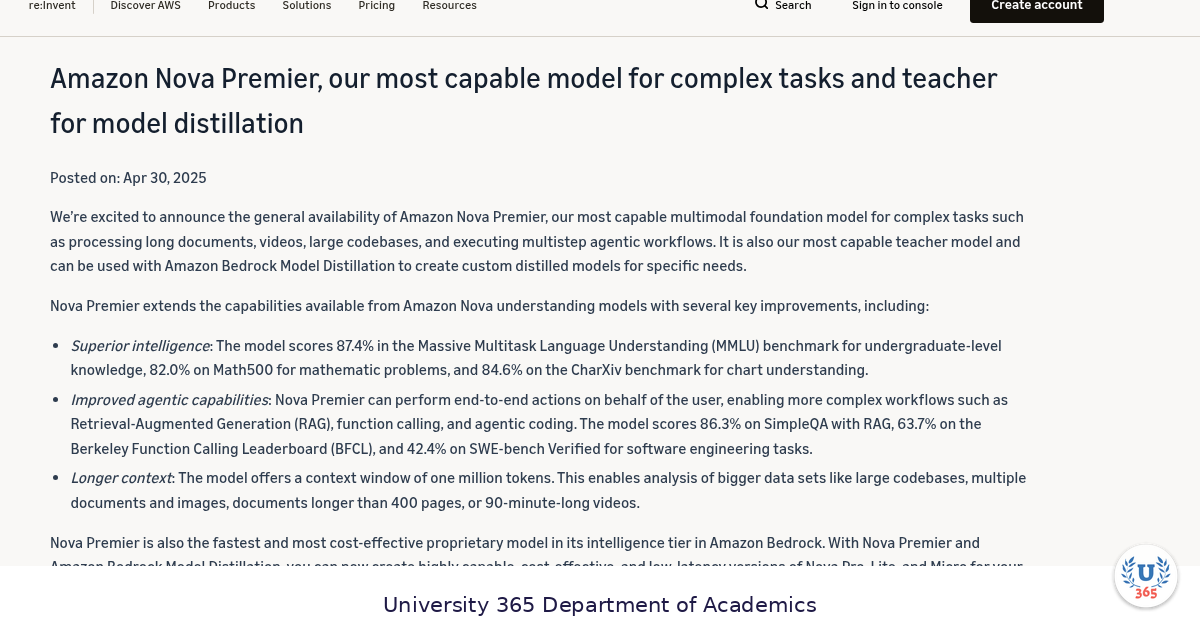
Reading a document set that does not fit an ordinary window. The 1M-token context window is the model's defining specification, and AWS describes it as enough for documents over 400 pages, several documents and images, or a 90-minute video. The vendor's chart evidence is 84.6 percent on CharXiv.
Chart and figure interpretation. CharXiv at 84.6 percent is the vendor's strongest differentiated row, and it is the one a board pack or a research report exercises.
Distillation. Nova Premier is the teacher model for Amazon Bedrock Model Distillation. AWS reports that a Nova Pro distilled from Premier for tool selection and API calling scored 20 percent higher on API invocations than the base Pro.
Agentic workflows with client-side tools. Berkeley Function Calling Leaderboard at 63.7 percent is the vendor's tool-use figure, and client-side tool calling is a supported Bedrock feature on this id.
Vision and video triage. Text, image and video input in one request, with text as the only output.
What it is not. It is not a reasoning model in the sense the 2026 market uses the term: no effort level, no thinking budget and no reasoningConfig is documented for this id, and Artificial Analysis lists it as non-reasoning. It is not a structured-output model: the Bedrock model card marks structured outputs as not supported. It is not open weights, not self-hostable and not inspectable from outside Bedrock. It publishes no parameter count and no architecture. It does not accept audio, and it does not produce images, video or speech. And it is not adoptable: the lifecycle is Legacy, the published EOL date has passed, and AWS no longer lists the model among its supported models.
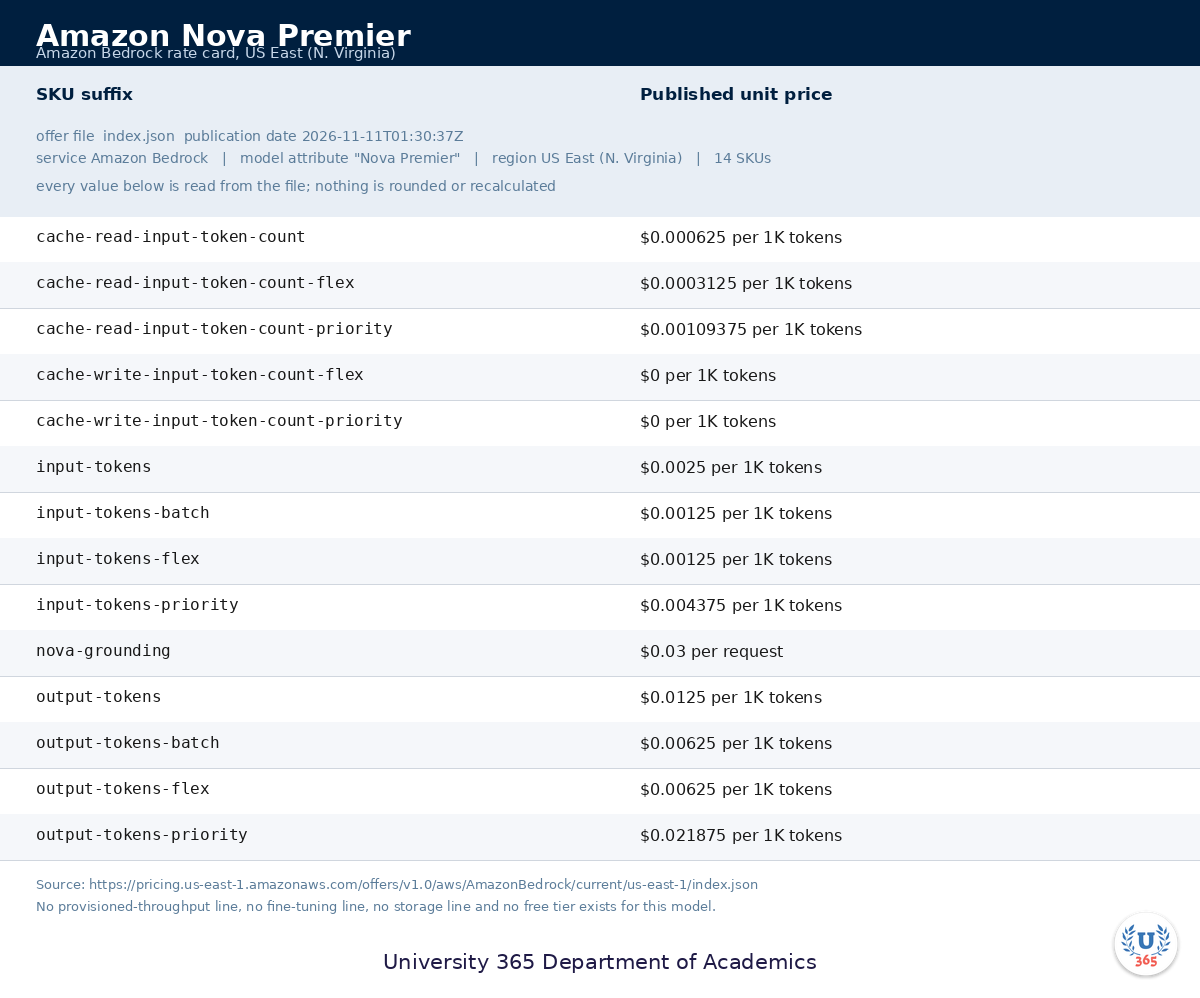
Pricing, as published in the Bedrock us-east-1 offer file of 2026-11-11:
Line | Standard | Priority | Flex | Batch |
Input, per million tokens | $2.50 | $4.375 | $1.25 | $1.25 |
Output, per million tokens | $12.50 | $21.875 | $6.25 | $6.25 |
Cached input, read, per million tokens | $0.625 | $1.09375 | $0.3125 | Not listed separately |
Cached input, write | $0.00 | $0.00 | $0.00 | Not listed separately |
Web grounding | $0.03 per request | $0.03 per request | $0.03 per request | Not listed separately |
Two sentences of arithmetic, because the tiers are the price. Priority is 1.75 times Standard and Flex and Batch are half of it, so the same job costs 3.5 times more on Priority than on Batch. The cache read is 25 percent of the input rate on every tier and the cache write is free, inside the 20,000-token ceiling AWS publishes for Nova prompt caching.
Official links:
Launch note, 2025-04-30: https://aws.amazon.com/about-aws/whats-new/2025/04/amazon-nova-premier-complex-tasks-model-distillation/
Bedrock model card, Nova Premier: https://docs.aws.amazon.com/bedrock/latest/userguide/model-card-amazon-nova-premier.html
Amazon Nova 1 user guide, what is Nova: https://docs.aws.amazon.com/nova/latest/userguide/what-is-nova.html
Nova 1 complete request schema: https://docs.aws.amazon.com/nova/latest/userguide/complete-request-schema.html
Amazon Nova product page: https://aws.amazon.com/nova/models/
Amazon Nova pricing: https://aws.amazon.com/nova/pricing/
Amazon Bedrock pricing: https://aws.amazon.com/bedrock/pricing/
Bedrock price list, us-east-1 offer file: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonBedrock/current/us-east-1/index.json
Nova Premier technical report and model card: https://www.amazon.science/publications/amazon-nova-premier-technical-report-and-model-card
Bedrock models at a glance: https://docs.aws.amazon.com/bedrock/latest/userguide/model-cards.html
Bedrock regional availability: https://docs.aws.amazon.com/bedrock/latest/userguide/models-region-compatibility.html
Bedrock model lifecycle, legacy policy: https://docs.aws.amazon.com/bedrock/latest/userguide/model-lifecycle-legacy.html
Bedrock batch inference, supported models: https://docs.aws.amazon.com/bedrock/latest/userguide/batch-inference-supported.html
AWS service terms: https://aws.amazon.com/service-terms/
LLM-specific fields:
API model identifier: amazon.nova-premier-v1:0, with the Geo id us.amazon.nova-premier-v1:0. No global. id and no eu. or apac. Geo id.
Release date: 2025-04-30, stated in the AWS What's New announcement and in the technical report addendum. The Bedrock model card prints 2025-10-31 in the same record that prints a 2026-09-14 EOL date.
Context window: 1,000,000 input tokens, stated on the model card, in the user guide and by Artificial Analysis.
Maximum output: 25,000 tokens on the Bedrock model card. The Nova 1 user guide's family table states 10,000 tokens for the same model.
Reasoning controls: none documented for this id. The card records Reasoning as Supported, while the Nova 1 request schema restricts reasoningConfig to Nova Pro and Nova Lite, and publishes no effort levels or default for Premier.
Knowledge cutoff: October 2024, stated on the model card.
Modalities: text, image and video input; text output. Documents are supported in PDF, CSV, DOC, DOCX, XLS, XLSX, HTML, TXT and MD. Audio input is not documented for this model.
Built-in tools: web grounding at $0.03 per request. Client-side tool calling is supported. No code interpreter is documented for this id.
Structured outputs: not supported, stated on the model card.
Prompt caching: explicit caching supported, minimum 1,000 tokens per checkpoint, at most 4 checkpoints per request, 5-minute time to live, on the system and messages fields, with a maximum of 20,000 tokens for Nova models.
APIs and endpoints: Invoke and Converse on bedrock-runtime. Responses, Chat Completions and bedrock-mantle are not supported.
Deployment: Amazon Bedrock, Geo cross-Region inference only, sourced from us-east-1, us-east-2 or us-west-2. In-region and global routes are both marked as not supported on the model card.
Service tiers: Standard, Priority and Flex. Reserved is not supported. Batch inference is supported and priced.
Licence: proprietary hosted service under AWS terms. No open weights, no self-hosting.
Parameters and architecture: not disclosed.
Lifecycle: Legacy on 2026-11-20, with a published EOL date of 2026-09-14 and a legacy period of at least six months.
Customization of this model: no fine-tuning, provisioned-throughput or storage line exists for Nova Premier in the offer file. Its documented customization role is as the teacher for distilled Nova Pro, Lite and Micro models.
At a Glance Dashboard
Field | Value |
Category | Applied AI / Hosted large language model (text, image, video and document input, text output, Amazon Bedrock) |
CI-First Benefit Score | 4.3 / 10 (CI-First Positive) |
Sub-scores | Time 5 / Quantity 5 / Quality 4 / Skill 3 |
CI-First Profile | Primary: Co-Worker and Assistant (level 2). Secondary: Co-Researcher, Analyst and Tester (level 4) |
Humics Protection | Humics-Neutral (-1 / +3) |
AI Imposture Risk | Medium overall, with Skill Illusion High |
Status | Retired |
Last tested | 2026-11-20 |
Pricing | $2.50 and $12.50 per million tokens Standard; $4.375 and $21.875 Priority; $1.25 and $6.25 Flex and Batch; cache read $0.625 Standard and write free; grounding $0.03 per request; no free tier |
Platforms | Amazon Bedrock, Geo cross-Region inference from three US regions |
User sentiment | No review platform and no independent user corpus exists for this model; the public record is vendor-authored, with one independent benchmark page carrying no composite index |

Nova Premier
The Problem
A long document is the work that most organisations cannot delegate and cannot afford to read. A 400-page tender, a board pack with sixty charts, a two-hour recorded walkthrough, a codebase nobody has opened in a year. A person can read one of those in a week, carefully, and can read none of them twice. The promise of a million-token window is that the whole set goes in at once and comes back as something a person can use.
The models sold for that work have carried a specific compromise, and Nova Premier is a clean example of it. The first generation of long-context flagships bought the window by giving up control. Nova Premier publishes a 1M-token window and no reasoning switch, no structured output and no effort level: a caller can send the whole set, but cannot tell the model how hard to think about it, and cannot require the answer to arrive in a schema. The result is a capable reader with an uncontrolled output shape, which is the hardest combination to put behind a workflow.
The second half of the problem is measurement. A vendor benchmark table is a vendor's choice of tasks, comparators and test settings, and the reader has no way to tell a real capability from a well-chosen demonstration. Nova Premier is the case where the independent record and the vendor record diverge far enough that the difference is the finding. Amazon's launch note reports 87.4 on MMLU and 84.6 on CharXiv. Artificial Analysis reports 56.9 on GPQA Diamond, 36.2 on IFBench, 38.3 on tau2-bench and 4.2 on Humanity's Last Exam. Those are different tests, and they are not reconcilable into one story of a leading model.
The third problem is the one U365 cares about most. A model that reads 400 pages for a person produces an answer that person cannot check. The whole point of the delegation is that nobody was going to read the set. A summary, a table or a chart reading arrives looking complete, and the only defence is a citation the reader can open: a page, a figure number, a clause. Nova Premier's output shape makes that defence harder, because structured outputs are not supported and every citation has to be requested in prose and parsed by the caller.
The fourth problem arrived in 2026 and settles the review. The model was moved to Legacy, given a published EOL date of 2026-09-14, and dropped from AWS's supported-models list, its regional availability page and its Nova product page. A reader who solves the reading problem with Nova Premier today has solved it on a service that has already passed its own end date.

Nova Premier
The Outcome
Nova Premier delivered the first-generation version of the long-document promise: a real 1M-token window, the strongest chart-reading result in the Nova 1 family, and a distillation role no other Nova model had. It delivered them without a reasoning switch, without structured outputs and without a second independent opinion until after the model had been retired.
The strongest part of the release is the window, and it is real rather than nominal. One million tokens covers documents over 400 pages or a 90-minute video by AWS's own description, and it arrives with image and video input in the same request. For a team whose alternative was chunking a set across forty calls and stitching the answers, that is the capability the model was bought for, and it is the part of the release that holds up.
The chart result is the second real gain, and it is the most differentiated number in the vendor's set. CharXiv at 84.6 percent measures chart understanding, which is the part of a board pack or a research report that text-only extraction loses. Nova Pro, the next tier down, publishes 300K of context and no CharXiv result in the same announcement.
The independent record is where the release changes character. Artificial Analysis carries a page for Nova Premier with a 1M-token context, no Intelligence Index and no publicly available API, and its table carries nine benchmark values for the model: GPQA Diamond 56.9, IFBench 36.2, tau2-bench 38.3, LiveCodeBench 31.8, AIME 2025 17.3, Humanity's Last Exam 4.2, Terminal-Bench Hard 6.8, AA long-context reasoning 34.3 and CritPt 0. Read together with the vendor's 87.4 MMLU and 84.6 CharXiv, the picture is a model that reads documents and charts well and reasons, follows instructions and completes agentic tasks at a level well below the 2026 field.
The lifecycle is the fact that decides the review. The model card carries a Legacy state and an EOL date of 2026-09-14. AWS's supported-models list, regional availability page and Nova product page no longer carry the model at all. The 2026-11-11 offer file still prices 14 SKUs, which is the only live trace of it in the commercial record. A reader who needs a 1M-token Nova today is buying Nova 2 Lite, not this model.
For U365 Fellows, the outcome is a study object as much as a tool. Nova Premier is the clearest available case of three things a Fellow should learn to see: a vendor benchmark table that leads with its own best rows, an independent table that tells a different story, and a lifecycle record whose own date fields contradict each other. The reading skill transfers to every model that follows it.
What the release does not change. It does not produce a reasoning control, a structured output, an audio input or an open weight. It does not make a 20,000-token prompt cache into a way to cache a 600-page set. It does not make the model adoptable after its published end of life. And it does not remove the verification step on any output a person will act on.

Nova Premier
Who Should Use Nova Premier
Nova Premier is retired, so this section answers a narrower question than usual: who still has a legitimate use for it, and who should read the Migration Path instead.
Learner type | Difficulty | Typical ROI | Career path |
Students (Bachelor, Master) | Intermediate | A study object rather than a working tool. The exercise is to take one vendor launch table and one independent table for the same model, put them side by side, and explain why 87.4 on MMLU and 56.9 on GPQA Diamond are both true of the same system. That comparison teaches benchmark literacy faster than any lecture. Running the model itself is possible only on a legacy-enabled account. | |
Professionals (career upskilling) | Intermediate | The realistic case is an existing deployment that has to move. A team that built a 400-page extraction or a chart-reading step on Premier in 2025 or 2026 now owns a migration with a published end date behind it. The transferable skill is not the model: it is the labelled sample, the citation rule and the validator that catch a model change. | |
Everyone (lifelong learners) | Beginner to Intermediate | A low-cost way to see what a million-token window changes, if an account already has the model enabled. The durable gain is a habit: require a page, a figure number or a clause for every claim, and open three of them. | LIPS Collect and Review phases for the reading work, and the UP-Context-Engineering Method order for prompting. No assessment home is asserted. |
For teams and organisations. A team deciding what to do with Nova Premier starts with four questions.
Team deployment. The route is Amazon Bedrock with Geo cross-Region inference from us-east-1, us-east-2 or us-west-2. There is no in-region route and no global route, so a request cannot be pinned to a single Region. New customers cannot adopt a Legacy model, and an existing customer may lose access after 15 days of inactivity.
Cost at team scale. Four lines decide the bill: the tier (Priority at 1.75 times Standard, Flex and Batch at half), the cache (free to write, a quarter of the input rate to read, capped at 20,000 tokens for Nova models), the output length (25K on the card, 10K in the user guide), and grounding at $0.03 per request. There is no provisioned-throughput line and no fine-tuning line for this model, so volume is metered only.
Data and compliance. AWS states in the Bedrock FAQ that customer inputs and outputs are not used to train Amazon Nova models and are not shared with model providers, and that content is encrypted in transit and at rest. That is the ordinary Bedrock position. It does not make the output a compliance artefact: an extraction row or a chart reading is a draft that a qualified person reviews.
U365 for companies. Professional learners reach University 365's academic services individually or through their organisation, and the company route runs through a customized training agreement for employee groups. Corporate education programmes are built on demand, and their tuition follows content and duration.
Skill level required: Intermediate. Stating a finish line, designing a citation rule, parsing an unstructured answer and checking a table against its sources are prerequisite skills. The model is easy to call and easy to over-trust, because a long fluent summary of a document nobody read looks like diligence.
Prerequisites. An AWS account with Bedrock enabled, the model still enabled in your Region, and a confirmed lifecycle state from ListFoundationModels. A route decision, because the Geo id is the only option. A parser and a validator, because structured outputs are not supported. A citation rule. And a named replacement, because the end date has passed.
Typical time to first result: Under fifteen minutes on an account where the model is still enabled. Send a one-paragraph prompt with amazon.nova-premier-v1:0, confirm the response, then send a 100,000-token input that carries a question you can answer yourself.
Typical time to competence: Ten to twenty hours of active use, most of it spent on the check rather than the prompt. Two habits carry the value: requiring a page or figure reference for every row, and treating every unsourced sentence as unverified.
Who should wait. Anyone who has not yet started: the model cannot be adopted, and Nova 2 Lite carries the same window with a published output ceiling, a reasoning control, structured workflow support and a current lifecycle. Anyone whose work depends on instruction following or agentic tool use, where the independent record is weakest. Anyone planning to cache a long document set, because the Nova cache ceiling is 20,000 tokens. And anyone who needs a vendor-named successor: AWS does not publish one, so the choice in Migration Path is University 365 research's determination.

Nova Premier
U365 Institutes Alignment
The alignment below rates what a U365 institute could take from this model as a working instrument and as an object of study. The primary home is UIT (Technology, AI, Data Science), because the model's usable strengths are long-context reading, chart interpretation and the evaluation discipline its two benchmark tables demand. The other three readings are real and each is bounded.
UIT (Technology, AI, Data Science)
Rating. High (primary)
Why. Four engineering competencies, each of which survives the removal of the tool. Long-context design: a 1M-token window turns a document set into a decision about what goes in, what carries a reference and what is left out, and the vendor's CharXiv result at 84.6 only partly measures it. Output shaping without structured outputs: a model that cannot emit a schema forces the caller to write the parser and the validator, which is exactly the discipline a cohort should practise. Evaluation reconciliation: the vendor's 87.4 MMLU and the independent 56.9 GPQA Diamond are the same model, and explaining the gap is a competence. Lifecycle engineering: a model with a published EOL date and a self-contradicting card is a live exercise in reading a dependency's contract before it stops.
The limit that holds the row. The model is a service a practitioner operates, not an artefact a practitioner inspects. There are no weights, no architecture and no parameter count, and the service is retired, so the competencies are engineering-with rather than engineering-of. No published programme assesses long-context extraction or benchmark reconciliation as a named component. Adjacent anchors, not assessment homes.
UIB (Business Management, Entrepreneurship)
Rating. Medium
Why. Two decisions the release forces that are commercial before they are technical. Tier and route selection: a Standard rate of $2.50 and $12.50, a Priority premium of 1.75 times, a Flex and Batch discount of 50 percent and a Geo-only route are a procurement decision with a measurable answer. And the migration itself: a flagship that costs 3.1 times the mid tier on input and reaches end of life within a procurement cycle is a vendor-risk lesson with a real contract behind it.
The limit that holds the row. The model supplies no management method and does not measure its own return. It publishes no completion rate, no time-per-task figure and no cost-per-task figure, so a business case has to be built by the unit. No published programme assesses the economics of a model portfolio as a named component. Adjacent anchors, not assessment homes.
UIC (Digital Communication, Marketing)
Rating. Low to Medium
Why. One competency that matters and is easy to miss: reading a vendor claim against the table that supports it. This release is a worked example, because "most capable" is true of the Nova 1 family and false against the 2026 field, and a communication practitioner who can find the base is doing the job the profession claims. The media surface is real as well: video input with text output makes a recorded demo a usable source, provided the quoted moment is checked against the recording.
The limit that holds the row. The model teaches no register, no audience analysis and no publication standard. It returns no sourced evidence of its own by default, so fact-checking stays with the writer, and no campaign or content-strategy competency appears in it. Rated as evaluation contact with a media-analysis surface. No credential is mapped.
UID (Digital Design, UX/UI)
Rating. Low
Why. The design contact is narrow but real: image input means a designer can put a UI screenshot in front of the model and get a structured description of what is on screen and where the elements sit, and the CharXiv result at 84.6 supports reading a chart or a dashboard capture. That is a research input rather than a design output.
The limit that holds the row. The model produces no image, no layout and no visual artefact: image output is a capability of Nova Canvas and Nova 2 Omni, not of this model. It evaluates no design against a brief and holds no design method. No layout, interaction or motion competency is assessed by it. No credential is mapped.
U365 methods, not an institute (UNOP, ULM, LIPS, CARE and the UP-Context-Engineering Method)
Rating. Applicable
Why. The methods layer is relevant in the way a long-context model is: the FULL-CONTEXT layer is the product's input, and the EXPECTED-FORMAT-AND-CONSTRAINTS layer is what keeps a long answer inside the job, which matters more here because no schema can enforce it. The record of what a run was asked to do, which documents went in and what came back belongs in the Fellow's own LIPS system, because the model holds no state between calls. CARE's Review phase is where an extraction row is checked against its page. UNOP has no direct fit: the model is not built to teach, and its gains come from context and multimodal input rather than from any pedagogical mechanism.
The limit that holds the row. The model carries no method of its own and no coaching surface. A Fellow who does not keep the reasoning about route, tier, source citation and lifecycle in their own system has no account of it, and nothing in the product writes that account for them.

Nova Premier
How Nova Premier Works
A first-generation natively multimodal understanding model, sold only through Amazon Bedrock, with a 1M-token input window, a 25K output ceiling on the model card, text, image and video input, built-in web grounding, client-side tool calling and no reasoning control.
Inputs: Text, images, video and documents. Documents are accepted in PDF, CSV, DOC, DOCX, XLS, XLSX, HTML, TXT and MD. A video arrives either as an S3 URI or as bytes. Audio input is not documented for this model, and there is no image, audio or video output.
What happens inside: Amazon publishes no architecture, no parameter count and no training description for Nova Premier beyond the family-level statement that it is a multimodal understanding model. What the vendor does document is the control surface, and it is thin: a system prompt, messages, inferenceConfig with maxTokens, temperature, topP, topK and stop sequences, and a toolConfig for client-side tools. There is no reasoning field for this id.
Outputs: Text. Markdown and tool calls are supported, through the Invoke and Converse APIs. Structured outputs are not supported, which is the single most consequential omission for the workflows below: the caller, not the model, owns the schema and the validation.
Built-in tools: web grounding at $0.03 per request, and client-side tool calling. No code interpreter is documented for this model, so arithmetic inside a workflow has to be checked outside the call or handed to a tool the caller defines.
Prompt caching: Explicit caching is supported on the system and messages fields, with a minimum of 1,000 tokens per checkpoint, at most four checkpoints per request, a five-minute time to live, and a maximum of 20,000 tokens for Nova models. The cache write is free and the cache read is billed at a quarter of the input rate. The ceiling is the constraint: a repeated instruction set fits, a 600-page document set does not.
Deployment: Amazon Bedrock only, with Geo cross-Region inference as the only route. The model card marks in-region and global as not supported for us-east-1, us-east-2 and us-west-2, and publishes us.amazon.nova-premier-v1:0 as the Geo id with no global equivalent. Service tiers are Standard, Priority and Flex, with Batch inference supported and Reserved not supported.
Guardrails and safety: Guardrails are a supported Bedrock feature on this id, and the model card links the Amazon Nova 1 AI Service Card for its responsible-AI documentation. That is the vendor's own framework applied to its own model. It is the right kind of document to publish and it is not independent measurement.
Customization: No fine-tuning, provisioned-throughput or storage line exists for Nova Premier in the offer file, and a Legacy model cannot start a new customization job. Its documented customization role runs the other way: Premier is the teacher model in Bedrock Model Distillation, generating training data for custom Nova Pro, Lite and Micro models. AWS reports that a Nova Pro distilled from Premier for tool selection and API calling scored 20 percent higher on API invocations than the base Pro.
What is not documented. No parameter count, no architecture, no training-data description, no reasoning control, no structured output, and no published successor. Three of those are normal for a proprietary hosted model. The fourth and fifth are limits a builder plans around, and the sixth is why the Migration Path is a University 365 research determination rather than a vendor instruction.

Nova Premier
Getting Started with Nova Premier
A fifteen-minute checklist for a first call on an account that still has the model enabled, and for the decision that follows it.
Confirm the lifecycle in your Region before anything else. Call ListFoundationModels and read the modelLifecycle field for amazon.nova-premier-v1:0. A Legacy state means the model may still answer for an existing customer, and a missing entry means it does not. The model card is not a substitute, because its own date fields disagree.
Confirm the route. The only inference id is the Geo id us.amazon.nova-premier-v1:0. A request that names a Region without the us. prefix is asking for a route the model card marks as not supported.
Write the rate base into the project notes. Standard is $2.50 and $12.50 per million tokens; Priority is $4.375 and $21.875; Flex and Batch are $1.25 and $6.25. Every cost comparison you read will quote one of these and name none of them.
Set a token budget against the lower output figure. The model card says 25K and the Nova 1 user guide says 10K. Plan against 10K, and treat anything above it as unverified until you see it in a response.
Do not look for a reasoning switch. There is none documented for this id. If a workflow needs more compute per answer, that workflow belongs on a reasoning model, not on a larger prompt to this one.
Build the parser and the validator first. Structured outputs are not supported, so the schema lives in your code. Run one call with a deliberately malformed answer and confirm the validator rejects it before you trust ten thousand good ones.
Test the cache before you rely on it. Put a repeated instruction set of about 5,000 tokens in the system field, call twice, and compare the billed input on the second call. The cache read is a quarter of the input rate and the write is free, and the 20,000-token ceiling is the limit to confirm.
Name the check and the replacement in the same note. A page you can open, a figure number you can read, a clause you can quote, and a model you will move to. The check is the deliverable's acceptance criterion, and the replacement is the project's.

Nova Premier
Real Workflows
Three workflows, each chosen because the model's measured strength and a check the reader already owns sit in the same place. Each sample prompt uses the UP-Context-Engineering Method's eight layers in method order, with the constraints and the data limits inside EXPECTED-FORMAT-AND-CONSTRAINTS. Each is written for a reader who still runs the model, and each transfers to its replacement with the model id changed.
Workflow 1: Turn a 400-page document set into a cited extraction table
When to use it: a tender, a contract set or a filing batch has to become a table a person can act on, and the set does not fit an ordinary window. This is the workflow the 1M-token context exists for, and the check is the page reference on every row.
This sample prompt uses the UP-Context-Engineering Method and the CI-First doctrine. Read the method at https://www.university-365.com/post/the-up-method-university-365-prompting-the-new-gold-standard-for-prompt-engineering, the doctrine at https://www.university-365.com/post/discover-the-ci-first-approach, learn both in a U365 online program at https://university-365.com/programs, and request a U.Coach for orientation at https://university-365.com/ucoach.
USER-PERSONA: My UP-Context-Engineering USER-PERSONA file is the file for this layer, attached. The parts that matter here: I sign off the table before it is used, I am audited on it, and I do not accept a row I cannot trace to a page. If the file is not attached, ask for it before you start.
FULL-CONTEXT: The FULL-CONTEXT set for this task, added and not merged: BUSINESS-PERSONA for [the organisation], PROJECT-DESCRIPTION for [the review], the document set at [location, count, page counts], the column definitions and their formats [columns], the validation rules [rules], and the decision the table feeds [decision]. The documents are the only authority for a value. If a column definition or a validation rule is missing, name it and stop.
AI-PROFILE-ROLE-EXPERTISE: Act as a Co-Researcher, Analyst and Tester, in the role of a document analyst preparing an evidence table, with expertise in contract structure, cross-references between annexes and exception handling.
USER-FINAL-GOAL: A table I can rely on, with a page reference in every row, and an exceptions list I can work through before anything is signed.
AI-EXACT-TASK: Produce the extraction table, one row per document item, with a page reference per row, then the exceptions list, then the passages you could not read or could not resolve.
AUDIENCE: Me, the reviewer who signs, and an auditor who will re-open three rows.
EXPECTED-FORMAT-AND-CONSTRAINTS: Format: (1) the table in the column order I supplied, as a markdown table, (2) the exceptions list, (3) the unresolved passages. Constraints: one row per item and no merged rows; every row carries a page reference in the form file:page; preserve the document's own units and formats and state the unit in the column header; write "not stated" rather than inferring a missing value; never carry a value from one document to another; if the set exceeds the window, say which files you left out before you answer; your knowledge cutoff is October 2024, so a document dated after that is read only from the set I supplied. Data limits: the set is cleared for this model at the level I state in the FULL-CONTEXT set; no document outside the set leaves my control.
EXAMPLES: The last signed-off table is the format example, attached, and one exceptions list is the exception example.
Before you use the output, run the check yourself: re-open three rows at random, compare the value and the page, and work the exceptions list before anything is signed. The decision is yours, per CI-First.
What the model does well here: holding a set in one window, with the images and the pages in the same request. The 1M-token context is the whole point, and the vendor's CharXiv result at 84.6 supports reading the charts inside the same documents. The caveat: there is no structured output, so the table arrives as prose or markdown and your parser is the only thing standing between a plausible row and a wrong one. The independent IFBench result of 36.2 is the reminder that a constraint stated in the prompt is not a constraint enforced by the model.
VERIFICATION CHECKLIST for the extraction table:
Multi-Model Check: run the same set through a second model and compare the rows that disagree, not the totals.
External Source: re-open three rows at random and compare the value and the page.
Human Review: the person who signs the review reads the exceptions list and confirms it is complete.
CI-First Test: can you defend any row by opening the page without the transcript? If not, the table is not yours yet.
Workflow 2: Read a board pack's charts at figure level
When to use it: a board pack, a research report or a dashboard export arrives as images alongside text, and the reading has to name the figure and the number it shows. This is the workflow the image input and the CharXiv result exist for, and the check is the figure number.
This sample prompt uses the UP-Context-Engineering Method and the CI-First doctrine. Read the method at https://www.university-365.com/post/the-up-method-university-365-prompting-the-new-gold-standard-for-prompt-engineering, the doctrine at https://www.university-365.com/post/discover-the-ci-first-approach, learn both in a U365 online program at https://university-365.com/programs, and request a U.Coach for orientation at https://university-365.com/ucoach.
USER-PERSONA: My UP-Context-Engineering USER-PERSONA file is the file for this layer, attached. The parts that matter here: I present this reading to a board, I answer for every number, and I do not accept a trend I cannot point to on a page. If the file is not attached, ask for it before you start.
FULL-CONTEXT: The FULL-CONTEXT set for this task, added and not merged: BUSINESS-PERSONA for [the organisation], PROJECT-DESCRIPTION for [the meeting], the pack at [location, page count], the questions the board will ask [questions], the definitions the pack uses [definitions], and the decisions the reading must support [decisions]. The pack is the only authority for a number. If a definition or a question is missing, name it and stop.
AI-PROFILE-ROLE-EXPERTISE: Act as a Co-Researcher, Analyst and Tester, in the role of an analyst briefing a board, with expertise in chart reading, axis and unit checks, and separating a trend from a formatting choice.
USER-FINAL-GOAL: A figure-level reading in which every number carries a page and figure reference, and every claim about a trend names the series it comes from.
AI-EXACT-TASK: Produce the reading as a list of findings, each with the figure reference, the number read from the chart, the unit and the direction of the trend, then a list of figures you could not read reliably and why.
AUDIENCE: Me, the presenter, and a board member who will turn to the page while I speak.
EXPECTED-FORMAT-AND-CONSTRAINTS: Format: (1) the findings list, (2) the unreadable figures, (3) the places where the text and the chart disagree. Constraints: quote the number as printed, with its unit; state the axis and the series for every trend; do not interpolate a value the chart does not label, say "unlabelled"; do not average two series; if a figure is a screenshot of a table rather than a chart, say so; your knowledge cutoff is October 2024, so any period after that comes only from the pack. Data limits: the pack is cleared for this model at the level I state; no page outside the pack leaves my control.
EXAMPLES: The last board reading is the format example, attached, and one figure note is the citation example.
Before you use the output, run the check yourself: open three cited figures and read the number yourself, confirm one axis and one unit, and check one "disagreement" between text and chart. The decision is yours, per CI-First.
What the model does well here: reading a chart and a page of prose in the same request, which is what a board pack is. The vendor's 84.6 on CharXiv is the evidence, and it is the strongest differentiated row in the release. The caveat: CharXiv is the vendor's own measurement of its own model, and a chart reading is exactly the output a reader cannot check without opening the page. The independent record carries no chart benchmark at all, so the one number that supports this workflow is single-source.
VERIFICATION CHECKLIST for the board reading:
Multi-Model Check: run two pages through a second model and compare the numbers, not the prose.
External Source: open three cited figures and read the number and the axis yourself.
Human Review: the presenter reads the findings against the pack before the meeting, not during it.
CI-First Test: can you point to the figure for every sentence you will say aloud? If not, the reading is not ready.
Workflow 3: Build a distillation set from a teacher model
When to use it: a team wants a smaller, cheaper model to do one narrow job well, and needs labelled examples that a strong model can generate at volume. This is the workflow Nova Premier was uniquely built for, and the check is a human-labelled holdout the teacher never saw.
This sample prompt uses the UP-Context-Engineering Method and the CI-First doctrine. Read the method at https://www.university-365.com/post/the-up-method-university-365-prompting-the-new-gold-standard-for-prompt-engineering, the doctrine at https://www.university-365.com/post/discover-the-ci-first-approach, learn both in a U365 online program at https://university-365.com/programs, and request a U.Coach for orientation at https://university-365.com/ucoach.
USER-PERSONA: My UP-Context-Engineering USER-PERSONA file is the file for this layer, attached. The parts that matter here: I own the evaluation set, I will not ship a student model I cannot measure, and I do not accept a training set I cannot audit. If the file is not attached, ask for it before you start.
FULL-CONTEXT: The FULL-CONTEXT set for this task, added and not merged: BUSINESS-PERSONA for [the organisation], PROJECT-DESCRIPTION for [the distillation], the task definition and its input distribution [task], the output schema [schema], the policy constraints [constraints], the seed examples [seeds], and the holdout set that must never enter the prompt [holdout]. The schema and the policy are the only authority for an output. If the schema or the task definition is missing, name it and stop.
AI-PROFILE-ROLE-EXPERTISE: Act as a Co-Worker and Assistant, in the role of a data generator for model distillation, with expertise in the task's edge cases and in producing outputs that match a fixed schema.
USER-FINAL-GOAL: A labelled set in the schema, with the edge cases represented and every generated row auditable, plus the rows you refused to generate and why.
AI-EXACT-TASK: Produce one row per input in the schema, then the refused rows with their reasons, then a count of rows by category so I can check the distribution against the task definition.
AUDIENCE: Me, the owner of the evaluation set, and a reviewer who will audit twenty rows.
EXPECTED-FORMAT-AND-CONSTRAINTS: Format: (1) the rows in the schema, one per line as JSON, (2) the refusals, (3) the category counts. Constraints: every row validates against the schema I supplied or is dropped, not repaired; do not invent an input that is not in the list; mark an ambiguous input as ambiguous rather than choosing for me; keep the output in the language of the input; never copy a holdout example into an output; your knowledge cutoff is October 2024, so a policy change after that date must come from the constraints I supplied. Data limits: the inputs are cleared for this model at the level I state; the holdout set is not sent to you at all.
EXAMPLES: Twenty seed rows in the schema are attached, and one refusal is the refusal example.
Before you use the output, run the check yourself: validate every row against the schema, audit twenty rows against their inputs, and run the student model against the holdout the teacher never saw. The decision is yours, per CI-First.
What the model does well here: generating a large, consistent labelled set for a narrow task, which is the job AWS built it for and priced it for. The vendor's own example, a Nova Pro distilled for tool selection and API calling at 20 percent higher accuracy than the base model, is the intended shape. The caveat: a teacher's errors are inherited by the student, and the independent instruction-following result is the part to worry about. If the teacher drops a constraint in one row in three, the student learns the drop as part of the task.
VERIFICATION CHECKLIST for the distillation set:
Multi-Model Check: generate the same inputs with a second teacher and compare the rows where the two disagree.
External Source: audit twenty rows against their inputs and the schema, not against the seeds.
Human Review: the evaluation owner confirms the holdout was never in a prompt and the category counts match the task definition.
CI-First Test: can you explain, for any row, why it is correct without asking the teacher? If not, the set is not audited.

Nova Premier
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | A real saving on a set that would otherwise be chunked, stitched and re-read. | A 1M-token input window in a single call, image and video input in the same request, a 25K output ceiling on the card, built-in web grounding and a free cache write with a read at a quarter of the input rate. Held at 5 rather than 7 by the absence of structured outputs, which moves parsing and repair into the caller, by the 20,000-token cache ceiling and by a single Geo-only route. |
Quantity | A genuine multiplier for document and media volume at the top of the first-generation range. | One window holds a set of more than 400 pages; Flex and Batch run at half the Standard rate; the cache read is 25 percent of input and the write is free; grounding is priced per request. Held at 5 because there is no provisioned-throughput line, no fine-tuning line and no code interpreter, so volume is metered only and the reading is still the bottleneck. |
Quality | Strong document and chart reading for its generation, and a much weaker position on instruction following, agentic work and reasoning once the independent record is read. | Vendor: MMLU 87.4, Math500 82.0, CharXiv 84.6, SimpleQA with RAG 86.3, BFCL 63.7, SWE-bench Verified 42.4. Independent: GPQA Diamond 56.9, IFBench 36.2, tau2-bench 38.3, LiveCodeBench 31.8, AIME 2025 17.3, Humanity's Last Exam 4.2, Terminal-Bench Hard 6.8, AA long-context reasoning 34.3, CritPt 0. Held at 4 because the two records point the same way on reading and opposite ways on control, and the model cannot be re-measured on a live route. |
Skill | Marginal, and honestly marginal. | No reasoning trace to learn from, no teaching mode, no structured output to study, no open weights, and a service that is retired. A Fellow can learn from the two benchmark tables, which is why the score is not lower, but the model itself transfers nothing. |
Limits
The model is retired and its published end date has passed. The card carries Model lifecycle: Legacy and an EOL date of 2026-09-14. AWS's supported-models list, regional availability page and Nova product page no longer carry the model. New customers cannot adopt it.
No successor is named by AWS. The Migration Path in Migration Path is a University 365 research determination, not a vendor instruction, because no AWS page names a replacement for this id.
Structured outputs are not supported. The model card marks them as not supported, so every schema, parser and validator belongs to the caller.
There is no reasoning control. The card records Reasoning as Supported, while the Nova 1 request schema restricts reasoningConfig to Nova Pro and Nova Lite and publishes no effort level for Premier. Artificial Analysis lists the model as non-reasoning.
The independent record is weak on control. IFBench 36.2, tau2-bench 38.3, LiveCodeBench 31.8, AIME 2025 17.3 and Humanity's Last Exam 4.2 describe a model that drops instructions and fails multi-step tasks far more often than the vendor table suggests.
There is no independent composite index. Artificial Analysis carries a model page with no Intelligence Index, no price and no publicly available API, so the nine values are not a live-remeasured row and no ranking exists.
The output ceiling is published twice and differently. 25K on the model card, 10K in the Nova 1 user guide. A workflow planned on the higher figure can silently truncate.
The route is Geo-only. No in-region route and no global route: a request cannot be pinned to one Region, which is a real constraint for a data-residency requirement.
The prompt-cache ceiling is 20,000 tokens for Nova models. A repeated instruction set fits; a repeated document set does not.
No parameter count, architecture or training-data description is published. Nothing about the model can be inspected from outside Bedrock.
The lifecycle record contradicts itself. Launch 2025-10-31 on the card against 2025-04-30 in the announcement and in Artificial Analysis; an EOL floor of 2026-10-31 against an EOL date of 2026-09-14; a Legacy state against a model that AWS no longer lists.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The saving is real: one call instead of forty, image and video in the same request, a 25K ceiling that returns a table rather than a summary, and a free cache write. The overhead is real as well: no structured output means the caller writes the parser and repairs the failures, no reasoning control means a hard task cannot be escalated, the Geo-only route and the retirement add migration work, and the 25K against 10K disagreement means a workflow planned on the higher ceiling can truncate. |
Quantity Illusion | Medium | The product invites volume at $1.25 per million input tokens on Batch and Flex: a million-token window, a filled row in every position, and a price that makes producing more rational. The independent record is the counterweight, with IFBench at 36.2 and tau2-bench at 38.3, and a table of ten thousand plausible rows is exactly where those failures stop being visible. |
Skill Illusion | High | A model that reads a 400-page set, a board pack and a recorded walkthrough returns an answer the reader could not have produced and cannot check, which is the definition of expert-looking output for a person without the underlying skill. The absence of structured outputs makes it worse rather than better: there is no schema to force the model to declare what it does not know. Mitigations exist and are cited: a page reference on every row, a figure reference on every claim, a labelled holdout, a parser and a validator. Those mitigations lower the frequency of failure; they do not move the capability to the reader. |
Overall Imposture Risk: Medium. One trap is High with identifiable mitigations, and two are Medium. Under the framework's arithmetic, one High with clear mitigations stated is Medium rather than High. The band-precedence sentence does not change the outcome, because the Medium band names this exact trap set and no second rating competes with it.
Framework v1.2 clause note
Clause 5.2.3-a, agent-authored procedural memory: NULL, recorded with its boundary. The model holds no state between calls, writes no skills, no memory store and no standing instruction, and the Bedrock surface offers no documented mechanism by which it authors procedural memory on the user's behalf. The boundary is the agentic surface: a deployment that lets an agent built on this model write and revise the user's instruction files, memory or skills would meet the clause, and client-side tool calling makes that arrangement easy to build. The clause is a property of the deployment in that case, not of the model.
Clause 4.2-a, agent-mediated conversation: NULL for the model as a generator. Neither erosion condition is met. No agent-authored text is presented as the person's own voice in a human-facing channel by default, and nothing substitutes agent interaction for human contact. The live condition to watch on any deployment: a support or advisory workflow that sends a Premier answer in the company's or a person's voice through a connected account without a person reading it first would meet condition (a). That is a property of a deployment built around this model rather than a property of the model.
Recorded together: the two clause questions return nulls with boundaries and live conditions rather than mechanisms, and the boundary is the part that matters. The reason Skill Illusion still rates High is not a clause mechanism; it is the plain fact that the model reads a set nobody will read and returns a summary that looks complete, on a service that is retired and cannot be re-measured.

Nova Premier
Section 7c: A lifecycle record that contradicts itself, a flagship rate cut four ways, and the independent row that was said not to exist
A Section 7c finding is recorded where a supplier's governance, safety record or commercial terms have a real result for the reader. The items below were checked against primary sources, and they produce findings a buyer should carry. All findings are stated as facts of record, and the difference between a company statement, a published evaluation and a policy term is kept intact.
The lifecycle record contradicts itself in three places, and the contradiction is the finding. The Bedrock model card for Nova Premier states a launch date of 2025-10-31, an EOL floor of 2026-10-31, an EOL date of 2026-09-14, a legacy period of at least six months, and a lifecycle of Legacy. The AWS What's New announcement and the technical report addendum both date the general availability to 2025-04-30, and Artificial Analysis publishes 2025-04-30 as the release date. The EOL floor cannot hold simultaneously with an EOL date seven weeks earlier. The finding is not that a date is wrong. It is that the record a buyer is told to read for the lifecycle is internally inconsistent, that the model disappears from the supported-models and regional pages while its card still says Legacy, and that the only remaining commercial trace is the price list.
The independent row exists, and it was reported as absent. Artificial Analysis carries a model page for Nova Premier with a 1M-token context, a non-reasoning label, no Artificial Analysis Intelligence Index, no price and no publicly available API. Its table carries nine measured values for the model: GPQA Diamond 56.9, IFBench 36.2, tau2-bench 38.3, LiveCodeBench 31.8, AIME 2025 17.3, Humanity's Last Exam 4.2, Terminal-Bench Hard 6.8, AA long-context reasoning 34.3, and CritPt 0. The distinction that matters is between an index and a measurement: there is no composite index and no rank, and there is a set of independent benchmark values that contradicts the impression the vendor table gives. A review that says no independent row exists has not read the page.
The rate card is complete for four tiers and empty for everything else. The us-east-1 offer file published 2026-11-11 carries 14 Nova Premier SKUs: Standard, Priority, Flex and Batch input and output lines, three cache-read lines, two cache-write lines at $0.00, and a grounding line at $0.03 per request. There is no provisioned-throughput line, no fine-tuning line, no storage line and no free tier. The four tiers are the price: Priority is 1.75 times Standard, Flex and Batch are half of it, and the same job costs 3.5 times more on Priority than on Batch.
Two figures that circulate for this model are one Priority rate and one Standard rate. Standard is $2.50 input and $12.50 output per million tokens. Priority is $4.375 and $21.875. A page that quotes $4.375 input and $12.50 output has quoted the Priority input rate beside the Standard output rate, which is a real pair of published numbers and not a price for any single job. The flagship premium over Nova Pro, at $0.80 and $3.20, is 3.1 times on input and 3.9 times on output.
The route is Geo-only, which is a data-residency term and not a routing detail. The model card marks in-region and global as not supported for us-east-1, us-east-2 and us-west-2, publishes us.amazon.nova-premier-v1:0 as the only cross-Region id, and publishes no global. equivalent. A request therefore cannot be pinned to one Region, and a buyer with a single-Region requirement cannot meet it with this model. That is a property of the service, stated on the card, and it survives any migration only if the replacement offers the route the requirement needs.
Structured outputs are not supported, and that is a contract term for a builder. The model card marks structured outputs as not supported while response streaming, guardrails and client-side tool calling are supported. For an extraction or classification workflow, the schema, the parser and the validator are therefore the caller's engineering, and the model can return a syntactically plausible row that violates the schema. No benchmark row measures that cost, and it is the largest single overhead in the Time score.
The maximum output is published twice and differently. The model card states 25K tokens; the Nova 1 user guide's family table states 10K for the same model. Both are AWS pages. A workflow planned on 25K and run against a 10K ceiling truncates silently, and the lower figure is the one to plan against until a response proves otherwise.
The reasoning field says one thing and the schema says another. The model card records Reasoning as Supported. The Nova 1 request schema documents reasoningConfig for Amazon Nova Pro and Amazon Nova Lite only, with no effort level and no default for Premier, and Artificial Analysis lists the model as non-reasoning. The practical statement is that the model reasons in the ordinary sense and offers no switch, which is the reading a builder should take.
No sub-score moved for these findings beyond the ones already stated, and the reason is explicit. The Time score already carries the absent structured outputs and the Geo-only route. The Quantity score already carries the missing provisioned-throughput and fine-tuning lines. The Quality score already carries the independent record and the retired lifecycle. The Imposture table already carries the fluency risk that a long summary hands to a reader who will not open the set. Section 7c closes with what it does not do: it does not allege misconduct, it does not treat a published end of life as a scandal, and it does not convert a supplier's own documentation inconsistency into a finding against the supplier's honesty. It records what a reader adopting this model was also adopting: a lifecycle record that cannot be reconciled, a rate card with four tiers and no commitments, a single geo route, no schema, and an independent measurement that was available before the model retired.

Nova Premier
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (level 2). Secondary profile: Co-Researcher, Analyst and Tester (level 4).
Why this profile and not Co-Creator. The vendor's positioning does the reasoning. Nova Premier is sold for complex tasks, long documents, long videos and agentic workflows, which is a delegation framing: state the job, hand over the set, check what returns. Co-Worker and Assistant is the role the model actually plays. Analyst and Tester is recorded as secondary because a document set, a chart pack and a recording are the inputs where the model measures best and where the reader interprets rather than authors. Professor, Coach and Tutor is not assigned: the model returns no reasoning trace, explains nothing by design, and offers no teaching surface, so assigning the profile would claim a capability the product does not publish.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 5 | Moderate net savings on the work it is sold for: a 1M-token window removes the chunk-and-stitch step, image and video arrive in the same request, and a 25K ceiling returns a table rather than a summary. Held at 5 by the absent structured outputs, which move parsing and repair to the caller, by the 20,000-token cache ceiling, by the single Geo-only route and by the retirement, which adds migration to every current use. |
Quantity | 5 | A genuine multiplier for document and media volume: one window for a set of more than 400 pages, Batch and Flex at half the Standard rate, a free cache write with a read at a quarter of the input rate, and priced grounding. Held at 5 because there is no provisioned-throughput line, no fine-tuning line and no code interpreter, and because the reading is the bottleneck on a long table. |
Quality | 4 | Strong document and chart reading for its generation, and a weak position on control. CharXiv 84.6 and MMLU 87.4 are real, and so are the independent IFBench 36.2, tau2-bench 38.3, AIME 2025 17.3 and Humanity's Last Exam 4.2. Marginal rather than moderate because the verified gain concentrates in one task type and the model cannot be re-measured on a live route. |
Skill | 3 | Marginal skill benefit: the reader picks up benchmark literacy and a citation discipline, and the model itself teaches nothing. No reasoning trace, no teaching mode, no structured output to study, no open weights, and a retired service. Scored conservatively per the framework's guidance. |
CI-First Benefit Score: 4.3 / 10 (CI-First Positive)
Why the score sits where it sits
4.3 with sub-scores 5 / 5 / 4 / 3 is a marginal Positive position, and the marginality is the point. It is a scored snapshot of a retired model, not an adoption recommendation, and the band describes what the model offered per unit of cost while it served.
Why not higher. Three reasons, each measured. There is no structured output, so a workflow pays an engineering cost that no benchmark row reflects. The independent record is weak on the two dimensions that decide whether a delegated run survives contact with a real constraint: IFBench at 36.2 and tau2-bench at 38.3. And the model cannot be adopted or re-measured, so Quality cannot rise on evidence that no longer accumulates.
Why not lower. The reading capability is real and it is in the right place for the work. A 1M-token window with image and video input, a 25K output ceiling and a CharXiv result at 84.6 is a specification no other Nova 1 model publishes, and the distillation role is a genuine capability with a vendor-reported result: a Nova Pro distilled from Premier at 20 percent higher accuracy on API invocations. At $2.50 and $12.50 Standard, with Batch at half, the arithmetic for a document-heavy job is defensible while the service lasts.
Why 4.3 and not a higher band, stated as arithmetic. Time 5, Quantity 5, Quality 4 and Skill 3 average to 4.25, which rounds to 4.3. Two dimensions at 5, one at 4 and one at 3 is the shape of a model that reads well, controls poorly and teaches nothing: it holds a set nobody else in its generation could hold, it hands back an unvalidated answer, and it leaves the reader no better at the task than before.
What the score does not carry. The four dimensions measure what the reader's work gained. They do not carry the lifecycle, the self-contradicting card, the Geo-only route or the missing successor, which sit in Section 7c and Migration Path with an explicit statement of which sub-score each finding already touches. They do not carry the clause questions either, which return nulls with boundaries. A reader who wants the score to encode procurement risk would need a different instrument, and the framework's instrument is the clause note and the 7c finding.
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | It produces tables, readings and labelled sets on request and originates no direction. It neither trains nor replaces the user's ideation: an extraction table leaves the judgement about what the set means with the reader. |
Critical Thinking | Erodes (-1) | A model built to summarise a set nobody will read, at a price that makes volume rational, with no schema to force it to declare uncertainty and an independent instruction-following result at 36.2. The failure mode is not an obvious error; it is a complete-looking reading of 400 pages with one inverted trend and a table whose tenth constraint was dropped. The mitigations lower the frequency and do not reverse the direction: a page reference catches a wrong row only if someone opens the page. |
Social Authenticity | Neutral (0) | The model produces text and tables rather than speaking in a person's name, and clause 4.2-a returns a null for it as a generator. The live condition stays in the record: a deployment that lets an agent send Premier's answers under the company's name without a person reading them first moves this dimension. |
Humics Protection Score: -1 / +3 Badge: Humics-Neutral
Superhuman Usage Guidance
When to invite this tool:
Only inside an existing deployment that has not yet migrated, and only with a named reviewer and a named replacement.
Document sets that exceed an ordinary window and end in a table a person can audit, with a page reference on every row.
Chart and figure reading where a figure number is the proof, and where the reader will open the page.
Distillation work where the holdout set is human-labelled and the student is measured against it.
When to keep this tool out:
Any new build. The model cannot be adopted, and a new dependency on a service past its published end date is a decision that has to be defended later.
Any workflow that requires a schema, a guaranteed JSON shape or a machine-checkable field, because structured outputs are not supported.
Any workflow that requires a reasoning budget, an effort level or a visible chain of reasoning, because none is documented for this id.
Any single-Region or data-residency requirement, because the only route is Geo cross-Region.
Any output that will be acted on without a qualified person reading it. The longer the input, the more the output looks like diligence.
The final judgement calls: what to publish, what to sign, what to tell a person. Those are the Humics this model does not supply.
U365 method integration:
LIPS + CARE: route the model's extraction and reading output into the Collect phase, and keep the Action Plan and Review phases as your own work. A reading of 400 pages is a collected artefact, not a decision, and the Review phase is where the page reference is checked.
ULM + EVA: the decision about whether a retired dependency stays in a workflow belongs in the Career and Quality of Life domains, because it is a risk decision about the person's own work, not a routing decision. ULM is the six-domain frame that holds it.
UP-Context-Engineering: the method's eight layers are the control surface this model needs, because FULL-CONTEXT is literally the input and EXPECTED-FORMAT-AND-CONSTRAINTS is the only schema the model will respect. The USER-PERSONA and AUDIENCE layers are what a high-volume run usually skips, and skipping them is how a fluent summary becomes a generic one. The three workflow samples above use the eight layers.
UNOP: no direct fit. The model is not built to teach and returns no reasoning trace.
Over-delegation warning: the failure mode with a long-context model is that the window justifies delegating the whole set. A person who would have read forty pages carefully now sends four hundred and reads a summary, and the summary is the only artefact that survives. The framework's arithmetic is the point: if your Human Intelligence input drops while the Artificial Intelligence term rises, the product falls. A reader who hands a 1M-token set to Nova Premier, changes nothing about how many pages a qualified person opens, and keeps the dependency after the end date has taken the release's worst offer.

Nova Premier
What Users Say
Aggregate Rating Table
Source | Reading | What it is | Link |
Artificial Analysis | Model page exists, no Intelligence Index, no price, no publicly available API; nine benchmark values published | Independent benchmark house | |
Amazon Bedrock model card | Launch date, lifecycle, EOL date, context, output ceiling, knowledge cutoff, prompt-cache limits, feature matrix | Vendor specification, not a rating | |
Bedrock us-east-1 offer file, 2026-11-11 | 14 SKUs under the model attribute "Nova Premier" | Vendor price list, not a rating | |
AWS What's New, 2025-04-30 | General availability, benchmark table, region list, distillation role | Vendor statement, not a rating | |
Amazon Nova product page, 2026-11-20 | The current Nova line lists Nova 2 Lite, Nova 2.5 Sonic and Nova Multimodal Embeddings; Nova Premier is absent | Vendor catalogue, not a rating |
Note on method, stated plainly because it affects how much this section is worth. There is no user-review corpus for this model. A model sold through a cloud console to developers has no consumer review body, and this review does not manufacture one. What exists is the vendor's own evaluation, the model card, the price list, the product page, and one independent benchmark page that publishes no composite index. That is what this section reports, and no quotation and no count is attributed to a platform whose threads were not read.
What Users Praise
There is no independent user praise to report for this model. The praise that exists is vendor-authored, and three themes in it are specific enough to be useful.
The window is the thing a document team would notice first. Documents over 400 pages, several documents and images, or a 90-minute video in one request is a capability that changes the shape of a back-office job. A team that had built a chunking pipeline to read a tender set would notice this before it noticed any benchmark.
The chart result is the differentiated row. CharXiv at 84.6 percent is the number a board-pack or research workflow depends on, and it is the row the vendor leads with after MMLU.
The distillation role is the capability no other Nova 1 model had. A teacher that produces training data for cheaper students, with a vendor-reported 20 percent improvement on API invocations in the distilled Pro, is a real answer to a cost problem, and it is the use AWS built the model for.
What Users Complain About
There are no user complaints to report either, and the two complaints a reader will actually meet are about the record rather than the behaviour.
The price figures circulating do not agree. Pages quoting $2.50 and $12.50, $4.375 and $12.50, and $1.25 and $6.25 describe the Standard, a Priority-input with Standard-output mix, and the Flex and Batch rates. Most of them do not say which, and a reader comparing three pages concludes that three sources disagree about one model.
The lifecycle record cannot be reconciled. A card that states a launch date of 2025-10-31, an EOL floor of 2026-10-31 and an EOL date of 2026-09-14, beside an announcement dated 2025-04-30 and a product page that no longer lists the model, leaves a reader unable to answer the only question that matters: does it still answer today. The answer has to come from ListFoundationModels in the account, not from the documentation.
Sentiment Summary
Overall sentiment: Unformed. No independent user corpus exists for this model on 2026-11-20, and the model is retired.
Key themes: a 1M-token multimodal window, a strong chart result, a unique distillation role, no reasoning control, no structured outputs, a Geo-only route, a rate card with four tiers, and a lifecycle record that contradicts itself.
U365 Editorial Note
The public record for this model is a vendor record with one independent page beside it, and a reader should treat it as exactly that. On the positive side, a 1M-token window with image and video input, CharXiv at 84.6, a distillation role with a reported 20 percent gain in a distilled student, and a complete four-tier rate card are the facts that made Nova Premier the top of its generation. On the negative side, the independent record puts IFBench at 36.2, tau2-bench at 38.3 and Humanity's Last Exam at 4.2, the model publishes no reasoning control and no structured output, its only route is Geo cross-Region, and its published end of life has passed. The Framework rates AI Imposture Risk Medium overall with Skill Illusion High, and that rating is the editorial position: Nova Premier is a reading instrument whose output a qualified person must open the page to check, and it is a dependency to migrate rather than a model to adopt. A reader who wants a lower rating is asking for a live independent measurement that no longer exists, not for a different review.

Nova Premier
Comparison and Alternatives
Model | Position | Evidence | Price, input and output per million | Choose it if |
Nova Premier | The retired first-generation flagship: the 1M-token reader and the distillation teacher | Vendor MMLU 87.4, Math500 82.0, CharXiv 84.6, SimpleQA with RAG 86.3, BFCL 63.7, SWE-bench Verified 42.4; independent GPQA Diamond 56.9, IFBench 36.2, tau2-bench 38.3, LiveCodeBench 31.8, AIME 2025 17.3, Humanity's Last Exam 4.2, Terminal-Bench Hard 6.8; U365 rates it 4.3 / 10 | $2.50 and $12.50 Standard; $4.375 and $21.875 Priority; $1.25 and $6.25 Flex and Batch; cache read $0.625 and write $0.00; grounding $0.03 per request; no free tier | You already run it, you have a named reviewer, and you have a migration date |
Nova 2 Lite | The current 1M-token Nova understanding model, generally available, and the replacement this review names | Vendor IF-Bench 70.8, MultiChallenge 76.6, tau2-bench Verified telecom 76.0 and retail 76.5, MMLU-Pro 80.9, SWE-bench Verified 53.6 or 64.5 with scaling; vendor-reported, no independent row; U365 rates it 5.8 / 10 | $0.33 and $2.75 in-region Standard, $0.30 and $2.50 global; cache read $0.0825 and write $0.00; Priority 1.75 times; Flex and Batch half; grounding $0.03 per request | You need a 1M window and multimodal input on a current lifecycle, at about an eighth of the Premier input rate |
Nova 2 Pro | The current flagship, sold as a preview to Nova Forge customers | Vendor MMLU-Pro 81.6, GPQA Diamond 81.4, IF-Bench 80.2, tau2-bench Verified telecom 92.7, SWE-bench Verified 70.0 with scaffolding; vendor-reported; U365 rates it 5.3 / 10 | $1.25 and $10.00 global Standard, $1.375 and $11.00 in-region; no published cache rate; no published output ceiling | You have the Nova Forge route, the task is genuinely complex, and the preview status is acceptable |
Nova Pro | The mid tier of the same first generation, still listed as Active on its own card | Vendor: 300K context, 10K output, no CharXiv result in the Premier announcement; no independent page read in this review | $0.80 and $3.20 Standard | The task fits 300K tokens and a mid-tier price, and the vendor's own lifecycle is acceptable |
Nova Lite | The cheapest first-generation multimodal model | Vendor: 300K context, 10K output; no independent page read in this review | $0.06 and $0.24 Standard | The task is trivial, the volume is enormous, and instruction following does not matter |
The comparison in one paragraph. Nova Premier is priced at 3.1 times Nova Pro on input and 3.9 times on output, and roughly 7.6 times Nova 2 Lite on input, and what it buys over both is the 1M-token window and the chart result. Against Nova 2 Lite it loses on everything that decides a 2026 deployment: instruction following (vendor IF-Bench 70.8 against nothing comparable for Premier, independent IFBench 36.2 against no independent Lite row), a published 64K output ceiling against 25K or 10K, a reasoning control against none, a global route against a Geo-only route, and a current lifecycle against a published end date that has passed. A buyer choosing between them in 2026 is not choosing between a flagship and a cheaper model; they are choosing between a retired service and its successor.

Nova Premier
Verdict and Next Steps
Verdict: Nova Premier is a capable long-document reader on a service that has already passed its published end of life, and the useful decision it forces is not whether to adopt it but what to move to.
At 4.3 / 10, CI-First Positive, with sub-scores 5 / 5 / 4 / 3, it is a marginal Positive snapshot. The strengths are in the right place for the work it was built for: a 1M-token window with image and video input, a CharXiv result at 84.6, a unique distillation role, and a rate card that prices four tiers cleanly. The weaknesses are equally specific: no structured output, no reasoning control, a Geo-only route, an independent record that puts instruction following at 36.2 and tau2-bench at 38.3, and a lifecycle record whose own dates cannot be reconciled.
Adopt it if you already run it, you have a named reviewer who opens the page, and you have a migration date. Do not adopt it as a new dependency, as a structured-output engine, as a reasoning model, as a single-Region deployment, or as a reason to stop reading the rows.
The three things to do in the first week:
Read the lifecycle in your own account, not in the documentation. Call ListFoundationModels and read the modelLifecycle field for amazon.nova-premier-v1:0. The card says Legacy, the card's EOL date says 2026-09-14, the product page no longer lists the model, and the price list still prices 14 SKUs. Only the account answers the question that matters.
Write the rate base and the tier into the project notes. Standard is $2.50 and $12.50; Priority is $4.375 and $21.875; Flex and Batch are $1.25 and $6.25. If your notes carry $4.375 beside $12.50, they carry a Priority input rate beside a Standard output rate.
Name the replacement and re-run the labelled sample before the end date bites. Nova 2 Lite carries the same 1M window, a published 64K output ceiling, a reasoning control, a global route and a current lifecycle. The sample is the only thing that tells you whether the move is a model change or a workflow change.
UP-Context prompt packs: the three samples are in Real Workflows, one per workflow, each in the UP-Context-Engineering Method's eight layers and each followed by the check the reader runs before using the output.
What would change this verdict. A confirmed live serving state with a current lifecycle, a published successor from AWS, a structured-output mode, a documented reasoning control, or an independent composite index. The re-check triggers at the top of this review name each one, and the first is a date that has already passed.

Nova Premier
Status and Last Tested
Status: Retired Last tested: 2026-11-20 Version tested: Nova Premier (amazon.nova-premier-v1:0, released 2025-04-30) Re-check: trigger-based, with the published end of life of 2026-09-14 as the first trigger
Retired: the tool still works but is no longer recommended. See the Migration Path section.
The badge records a published lifecycle fact rather than a judgement of the model. The Bedrock model card carries Model lifecycle: Legacy and Model EOL date: September 14, 2026; AWS's supported-models list, regional availability page and Nova product page no longer carry the model; the us-east-1 offer file published 2026-11-11 still prices 14 SKUs. The badge is Retired rather than Deprecated because the card's own state field still reads Legacy and the commercial record still prices the model. A reader who confirms that requests fail should treat it as Deprecated and read the Migration Path for what to use instead.
The date in Last tested is the date the vendor's own surfaces were read: the model card, the Nova 1 user guide, the request schema, the launch announcement, the product page, the lifecycle pages, the batch-inference list and the us-east-1 offer file, together with the independent benchmark page. No claim in this review rests on a figure that was not on one of those surfaces on that date. The re-check triggers are listed at the top of the post, and the first one is a date rather than an event.

Nova Premier
Migration Path
The replacement this review names is Nova 2 Lite (amazon.nova-2-lite-v1:0), and the naming is a University 365 research determination rather than a vendor instruction. AWS publishes no successor line for Nova Premier: the lifecycle page no longer carries the model, the product page has removed it, and no announcement names a replacement. Nova 2 Lite is the replacement on four published facts: it is the only current Nova understanding model with a 1M-token context window, it accepts text, images, video and documents, it is generally available rather than preview, and it carries its own review at 5.8 / 10. A reader who wants the family's strongest model instead should look at Nova 2 Pro, which is a preview sold to Nova Forge customers and is not a drop-in replacement for a generally available service.
What transfers unchanged.
The prompt pack: the eight UP-Context-Engineering layers are model-independent, and a pack written for Premier is a pack for the next model.
The documents and the images: multimodal input is a capability of the family rather than of this snapshot, and the same set can be sent to the replacement.
The citation rule: a page, a figure number or a clause on every row is a property of the reader's standard, not of the model.
The labelled sample and the validator: these are the transferable assets, and they are worth more than the prompt.
The tier and caching habits: Flex and Batch at half, a free cache write and a cache read at a quarter of input are family-level economics.
What does not transfer.
The model id. amazon.nova-premier-v1:0 is not an alias for any successor, and a call that keeps the old id reaches a service whose published end date has passed.
The price basis. $2.50 and $12.50 Standard becomes $0.33 and $2.75 in-region Standard, or $0.30 and $2.50 on the global route, which is about an eighth of the Premier input rate and a fifth of its output rate.
The route. Premier offers Geo cross-Region only; Nova 2 Lite offers global, Geo and in-region routes. A data-residency decision has to be re-made rather than carried.
The output ceiling. Premier publishes 25K on the card and 10K in the user guide; Nova 2 Lite publishes 64K. A request written to the old ceiling is under-budgeted, not over-budgeted.
The reasoning control. Premier has none; Nova 2 Lite ships reasoning off by default with low, medium and high effort. A caller who relied on the default behaviour of Premier has to set the new default explicitly.
The distillation role. Premier was a teacher model; the replacement is a student-tier model, and a team that used Premier to generate training data needs a different teacher. That is a separate decision and this section does not make it.
The behaviour. A different model answers differently on the same pack, and the labelled sample has to be re-run rather than trusted.
Migration steps.
Inventory the calls by model id, route, tier and input type. The inventory is the input to both the cost model and the test plan.
Read the replacement's card and rates from primary sources. Do not carry this model's 25K, 10K or Geo-only route across.
Change the model id explicitly and remove the old one from the code. No alias exists, and a fallback that keeps the old id is an incident waiting for a date.
Run the same document set on the replacement and compare against your labelled sample. Record the answer length, the token counts and the failures, and compare the rows that disagree rather than the totals.
Re-baseline the cost and the check. The rate falls by roughly an order of magnitude and the output ceiling rises, and both change how much a person is expected to read.
Record the lifecycle of the replacement before you depend on it. A published EOL date is a feature of this family, not a surprise, and it belongs in the same note as the rate.
What this section does not do. It does not score the replacement, which has its own review and its own evidence. It does not promise that the replacement behaves like this model on any particular workload. And it does not present a University 365 research determination as a vendor statement: no AWS page names a successor for Nova Premier, and a reader who needs a vendor instruction will not find one.

Nova Premier
U365's Recommendations to Learn More
Start with the model card and the lifecycle page, in that order
The Bedrock model card for Nova Premier is the single most useful page in the record, and it is also the page that contradicts itself. It states the launch date, the EOL floor, the EOL date, the lifecycle, the 1M-token context, the output ceiling, the knowledge cutoff, the feature matrix and the prompt-cache limits in one place. Read it beside the lifecycle page, which explains what Legacy and EOL mean in practice, and beside ListFoundationModels in your own account, which is the only surface that answers whether the model still serves you.
Then read the two benchmark tables side by side
The launch announcement carries the vendor's table: MMLU 87.4, Math500 82.0, CharXiv 84.6, SimpleQA with RAG 86.3, BFCL 63.7, SWE-bench Verified 42.4. The Artificial Analysis model page carries the independent values: GPQA Diamond 56.9, IFBench 36.2, tau2-bench 38.3, LiveCodeBench 31.8, AIME 2025 17.3, Humanity's Last Exam 4.2. They are different tests, they are not reconcilable into one story, and the exercise of explaining why is the most useful thing this model teaches.
The price list is the contract, and it is readable
The us-east-1 offer file is a plain CSV inside a JSON wrapper, published with a date, and it carries every line: Standard, Priority, Flex, Batch, three cache-read rates, two cache-write rates at zero, and grounding at $0.03 per request. It also shows what is absent: no provisioned throughput, no fine-tuning, no storage, no free tier. A reader who can read a rate card can answer most procurement questions without a sales call.
Resources on X
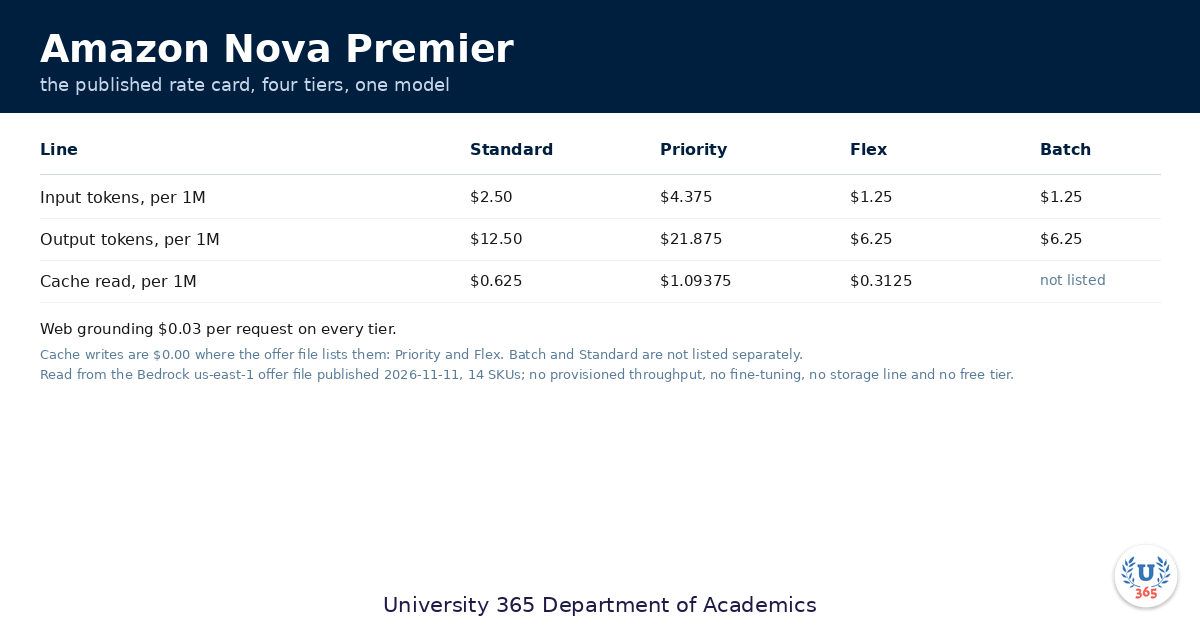
Dedicated X channels: the AWS account and the Amazon Science account carry launch material and research framing for the Nova family. No dedicated channel for this model was found.
U365 courses and programmes that build the surrounding skill
UIT (Technology, AI, Data Science): the engineering track where long-context design, evaluation reconciliation and cost-per-finished-task arithmetic belong.
UIB (Business Management, Entrepreneurship): the commercial track where a four-tier rate card and a vendor-retirement decision are analysed.
UIC (Digital Communication, Marketing): the media track where a recorded source is turned into a published brief with timestamps.
The one habit to carry
Require a location for every claim before you read the claim. A page, a figure, a clause, a timestamp. A long-context model is cheap enough that the volume of claims rises with the size of the set, and a model that processed 400 pages can sound as though it verified 400 pages. The location is the difference between a summary and evidence.

Nova Premier
CI-First Evaluation Summary Card
Field | Value |
Tool | Nova Premier (amazon.nova-premier-v1:0), Amazon Web Services |
Category | Applied AI / Hosted large language model (text, image, video and document input, text output, Amazon Bedrock) |
CI-First Benefit Score | 4.3 / 10, CI-First Positive |
Sub-scores | Time 5 / Quantity 5 / Quality 4 / Skill 3 |
CI-First Profile | Primary: Co-Worker and Assistant (level 2). Secondary: Co-Researcher, Analyst and Tester (level 4) |
Humics Protection | Humics-Neutral (-1 / +3). Creativity 0, Critical Thinking -1, Social Authenticity 0 |
AI Imposture Risk | Medium overall. Time Medium, Quantity Medium, Skill Illusion High |
Framework v1.2 clauses | 5.2.3-a null with boundary, 4.2-a null with live condition |
Status | Retired |
Last tested | 2026-11-20 |
Version tested | Nova Premier (amazon.nova-premier-v1:0, released 2025-04-30) |
Pricing | $2.50 per million input tokens and $12.50 per million output tokens Standard; $4.375 and $21.875 Priority; $1.25 and $6.25 Flex and Batch; cache read $0.625 and write $0.00; grounding $0.03 per request; no free tier |
Primary institute | UIT (Technology, AI, Data Science) |
Review status | Retired: the tool still works but is no longer recommended. See the Migration Path section |

Nova Premier
Glossary
CI-First Benefit Score
The arithmetic mean of the four benefit dimensions, each scored 0 to 10, rounded to one decimal place. 0 to 2.0 is CI-First Negative, 2.1 to 4.0 is CI-First Neutral, 4.1 to 6.0 is CI-First Positive, 6.1 to 8.0 is CI-First Strong, and 8.1 to 10 is CI-First Transformative. Nova Premier scores 4.3, which is Positive.
Time Benefit
Whether the tool returns more time than it costs, after the overhead of using it is subtracted. Nova Premier is 5: a 1M-token window removes the chunk-and-stitch step, image and video arrive in the same request, and a 25K ceiling returns a table rather than a summary, against the absent structured outputs, the 20,000-token cache ceiling, a single Geo-only route and the migration a retired service imposes.
Quantity Benefit
Whether the tool increases the volume of usable work a person can produce in a given time. Nova Premier is 5: one window for a set of more than 400 pages, Batch and Flex at half the Standard rate, a free cache write with a read at a quarter of the input rate and priced grounding, against no provisioned throughput, no fine-tuning and a reading bottleneck on a long table.
Quality Benefit
Whether the tool helps the user produce better work than they could alone, judged after verification rather than on surface polish. Nova Premier is 4: CharXiv at 84.6 and MMLU at 87.4 are real, and the independent IFBench at 36.2, tau2-bench at 38.3, AIME 2025 at 17.3 and Humanity's Last Exam at 4.2 are the counterweight. The verified gain concentrates in document and chart reading.
Knowledge and Skill Benefit
Whether the tool helps the user learn what they did not know and do what they did not know how to do. Nova Premier is 3, scored conservatively: the reader picks up benchmark literacy and a citation discipline from the two tables and the workflows, and the model itself returns no reasoning trace, offers no teaching mode and cannot be inspected.
Humics Protection Badge
The sum of three ratings, each +1, 0 or -1, across Creativity, Critical Thinking and Social Authenticity. +2 to +3 is Humics-Friendly, -1 to +1 is Humics-Neutral and -2 to -3 is Humics-Risky. Nova Premier scores -1, which is Humics-Neutral: it neither strengthens nor systematically destroys the three capabilities, and it requires the reader to keep the critical habit that a 400-page summary discourages.
AI Imposture Risk
The likelihood that the tool traps its user in one of three illusions: the Time Illusion, where the overhead exceeds the saving; the Quantity Illusion, where volume passes for quality; and the Skill Illusion, where the user believes they can do what the tool did. Each trap is rated Low, Medium or High. Nova Premier is Medium overall, with Skill Illusion High and the other two Medium.
CI-First Profile
The role the AI plays in the working relationship: Co-Creator and Thought Partner (1), Co-Worker and Assistant (2), Professor, Coach and Tutor (3), Co-Researcher, Analyst and Tester (4), or Challenger, Critic, and Devil's Advocate (5). Nova Premier is primarily Co-Worker and Assistant, with Co-Researcher, Analyst and Tester as the secondary role.
User Sentiment
The direction of independent and practitioner reaction to a tool, read from reports rather than assumed from a rating average. Nova Premier has no independent user-review corpus. Its record consists of vendor material and one independent benchmark page, so this review reports that evidence rather than inventing sentiment.
Review Status
The badge on this review states how much confidence to place in it. The vocabulary: Active means the tool is current and recommended. Active (updated) means it is current and recommended and was recently re-checked and refreshed. Changed means a re-check trigger fired and an update is pending, so read it with that in mind. Risky means the tool has significant unresolved issues or has been clearly surpassed by newer alternatives, so use it with caution and read the Limits section. Stale means the review has not been re-checked in over six months, so treat pricing and features as unverified. Retired means the tool still works but is no longer recommended. Deprecated means it has been shut down or fundamentally changed. This review is Retired, and it carries a Migration Path.
Last tested and Re-check
The date on which the review's evidence was last read against the vendor's own surfaces, and the condition under which it will be read again. This review was last tested on 2026-11-20 and is re-checked on a trigger list whose first entry is the published end of life of 2026-09-14, because a model past its own end date can change state without any other event.

Nova Premier
Sources
Vendor primary sources:
AWS, "Amazon Nova Premier, our most capable model for complex tasks and teacher for model distillation", What's New, 2025-04-30: https://aws.amazon.com/about-aws/whats-new/2025/04/amazon-nova-premier-complex-tasks-model-distillation/
Amazon Web Services, Bedrock model card, Nova Premier: https://docs.aws.amazon.com/bedrock/latest/userguide/model-card-amazon-nova-premier.html
Amazon Web Services, "What is Amazon Nova?", Nova 1 user guide: https://docs.aws.amazon.com/nova/latest/userguide/what-is-nova.html
Amazon Web Services, "Complete request schema", Nova 1 user guide: https://docs.aws.amazon.com/nova/latest/userguide/complete-request-schema.html
Amazon Web Services, Amazon Nova foundation models: https://aws.amazon.com/nova/models/
Amazon Web Services, Amazon Nova pricing: https://aws.amazon.com/nova/pricing/
Amazon Web Services, Amazon Bedrock pricing: https://aws.amazon.com/bedrock/pricing/
Amazon Web Services, Amazon Bedrock price list, us-east-1 offer file, publication date 2026-11-11: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonBedrock/current/us-east-1/index.json
Amazon Artificial General Intelligence, "Amazon Nova Premier: Technical report and model card", 2025: https://www.amazon.science/publications/amazon-nova-premier-technical-report-and-model-card
Amazon Web Services, "Models at a glance", Bedrock user guide: https://docs.aws.amazon.com/bedrock/latest/userguide/model-cards.html
Amazon Web Services, "Regional availability by models": https://docs.aws.amazon.com/bedrock/latest/userguide/models-region-compatibility.html
Amazon Web Services, "Model lifecycle (Legacy)": https://docs.aws.amazon.com/bedrock/latest/userguide/model-lifecycle-legacy.html
Amazon Web Services, "Batch inference, supported models": https://docs.aws.amazon.com/bedrock/latest/userguide/batch-inference-supported.html
Amazon Web Services, Amazon Bedrock FAQs: https://aws.amazon.com/bedrock/faqs/
Amazon Web Services, AWS service terms: https://aws.amazon.com/service-terms/
Independent measurement:
Artificial Analysis, Nova Premier model page, read 2026-11-20: https://artificialanalysis.ai/models/nova-premier
Artificial Analysis, model comparison leaderboard, read 2026-11-20: https://artificialanalysis.ai/leaderboards/models
U365 reference:
U365 CI-First Evaluation Framework v1.4.1: https://www.university-365.com/post/discover-the-ci-first-approach

Nova Premier
Faculty Note on Evidence Quality
What this review rests on, in order of weight. First, the vendor's own primary documents: the launch note, the Bedrock model card, the Nova 1 user guide, the request schema, the product page, the lifecycle pages, the batch-inference list and the us-east-1 offer file. Second, one independent benchmark page with nine measured values and no composite index. Third, the lifecycle pages, which are the strongest evidence in the document because they are policy rather than performance and a third party can verify them without running the model.
What is measured and what is inferred. The performance figures are reported as their sources state them, with the vendor's own test settings kept intact and the independent values kept separate rather than averaged into a single claim. The price figures are published rates read from the offer file, and they are the most verifiable claims in the document. The claim that the model is a good fit for long-document extraction is an interpretation of the 1M window and the CharXiv row against the work the model was sold for, and it is the interpretation this review defends. The claim that a reader will over-delegate at a large window is an inference from the framework's model of human behaviour, supported by the economics of volume rather than by a controlled study, and it is labelled as an inference.
The two-record problem is the honest headline. A review of a retired model that no party can re-measure cannot tell a reader how the model behaves today, and this one does not pretend otherwise. The vendor table and the independent table are not reconcilable, because they measure different things on different tasks, and the difference between them is itself the most useful evidence in the document: a model can lead its own table on chart reading and sit far down an independent table on instruction following, and both statements can be true.
Three findings cut in the vendor's favour and should be said as plainly as the rest. The 1M-token window was real, not nominal, and it arrived with image and video input in the same request. The rate card is complete for four tiers, with cache read and cache write priced, grounding priced, and no hidden free tier to mislead a buyer. And the lifecycle was published before it bit: a dated Legacy state, a dated EOL, and a written legacy period are more notice than many hosted models give, even when the card's own date fields disagree with each other.
What this review does not do. It does not score Nova 2 Lite, Nova 2 Pro, Nova 2 Omni or Nova Pro, each of which has its own review and its own evidence. It does not score Amazon Bedrock as a platform or Bedrock Model Distillation as a service. It does not treat a published end of life as a scandal, a documentation inconsistency as bad faith, or a rate card as a capability claim. And it does not convert a vendor benchmark row into a promise: a model that scores 84.6 on CharXiv will still misread a figure, and a model that scores 87.4 on MMLU will still drop the tenth instruction. The reader who plans for that is the reader the framework is written for.

Nova Premier
Status and Re-check
Status: Retired | Last tested: 2026-11-20 (Nova Premier, amazon.nova-premier-v1:0, released 2025-04-30) | Re-check: trigger-based, end of life 2026-09-14
Retired: the tool still works but is no longer recommended. See the Migration Path section.
The badge records a published lifecycle fact, not a judgement of the model. The Bedrock model card carries Model lifecycle: Legacy and Model EOL date: September 14, 2026, a date that has passed. AWS's supported-models list, its regional availability page and its Nova product page no longer carry the model. The Bedrock us-east-1 offer file published 2026-11-11 still prices 14 Nova Premier SKUs, and the model card's own state field still reads Legacy, which is why the badge is Retired rather than Deprecated. A reader arriving today should expect requests to fail, and existing deployments should read the Migration Path before anything else. The CI-First Benefit Score of 4.3 describes what the model offers per unit of cost while it serves, not an adoption recommendation.
For detailed explanations of the CI-First evaluation terms used in this review, including the Humics Protection Badge and the AI Imposture Risk levels, see the Glossary at the end of this post.
Re-check triggers:
A correction to the lifecycle record. The card states a launch date of 2025-10-31, an EOL floor of 2026-10-31, and an EOL date of 2026-09-14. Any correction to those three fields changes the badge and the Migration Path.
The first live confirmation that the model still answers. The offer file of 2026-11-11 still prices the model, and the model card still reads Legacy. A confirmed serving state, or a confirmed failure, settles the Retired or Deprecated question.
A published replacement line from AWS. No AWS page names a successor for this id. A vendor page that names one replaces the University 365 research determination in Migration Path.
A change to the Standard, Priority, Flex or Batch rate. Four rate lines carry every cost figure here, and the flagship premium over Nova Pro is 3.1 times on input.
A change to the maximum output figure. The model card publishes 25K and the Nova 1 user guide publishes 10K for the same model. A reconciliation, in either direction, changes what a long extraction can return.
A change to the reasoning control. The card records Reasoning as Supported, the request schema restricts reasoningConfig to Nova Pro and Nova Lite, and Artificial Analysis lists the model as non-reasoning. A documented reasoning switch for this id would reopen How Nova Premier Works and the Skill score.
A change to structured-output support. The model card marks structured outputs as not supported. That absence is the reason every extraction workflow below carries its own parser and validator.
A new independent measurement. Artificial Analysis now carries a model page for Nova Premier, with nine benchmark values and no Intelligence Index. A composite index, or a second independent house, is the event that would move Quality.




Comments