
Understanding AI Agents
Updated: Oct 8

UIT University 365 Institute of Technology
Series AI Agents Series | Level Basic (Free)
Duration 25 minutes | Access Free
IT Engineering, AI and Applied AI, Data Science, Software Development, Digital Transformation

UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to prepare your brain. Play the isochronous tone track (40Hz gamma frequency) with your eyes closed. Gamma-frequency tones before a learning session raise attention and make the material easier to absorb.
[Audio player: UNOP Pre-Lecture Isochrone (40Hz, 5 minutes)]
In this Lecture

The Word Everyone Uses Differently
Ask five people what an AI agent is and you will get five answers. One means an autocomplete feature in an editor. One means a chatbot with a memory. One means a script that runs on a schedule. One means a system that books appointments. One means a research assistant that reads twenty pages and writes a report.
The confusion is not new, and it is not trivial. It matters because the word carries an implication about autonomy, and autonomy is what determines how much damage a mistake can do. A feature you must trigger and approve is a different risk from a process that runs unattended and can send email.
This lecture settles the vocabulary first, then explains what an agent actually does between your instruction and its result, where the human gates belong, why the current generation works where earlier ones did not, and how to decide whether a particular task is worth delegating at all.
By the end you should be able to look at any product described as an agent and place it, without vendor language, into one of three categories, and you should know which questions to ask about its controls.
Automation, Generative AI, and an Agent
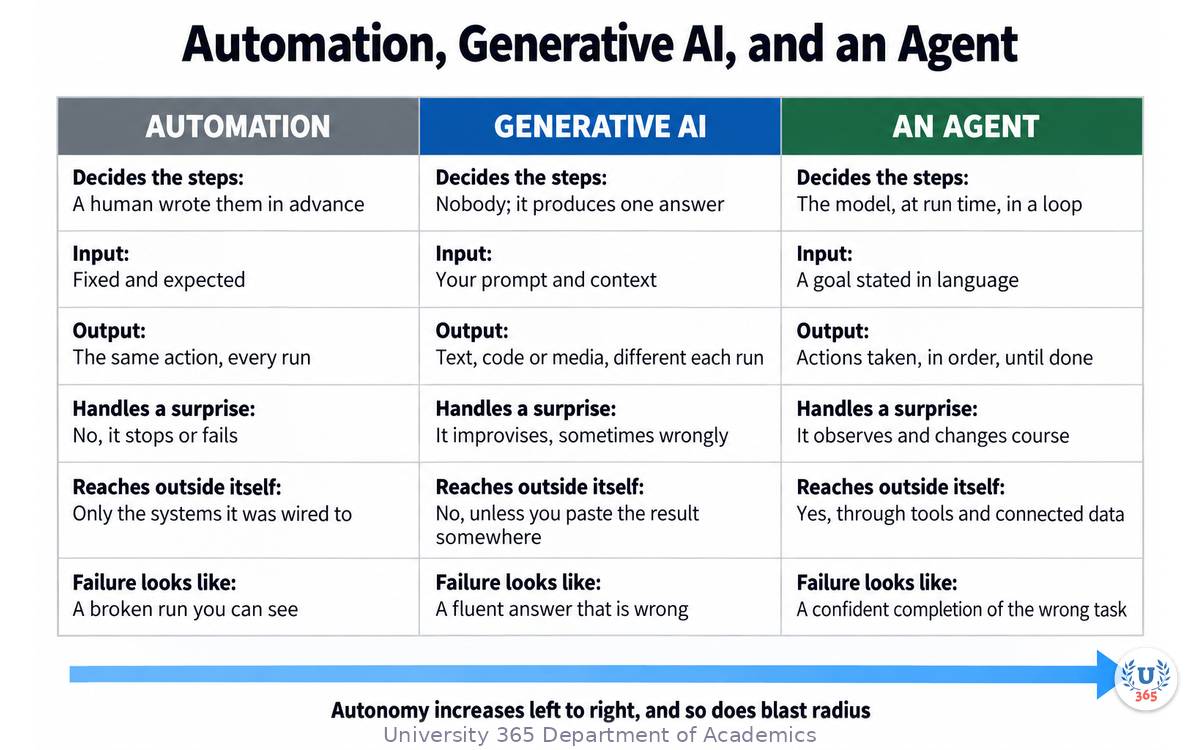
Three different things get called agents, and the difference is who decides the steps.
Automation
Automation is a fixed sequence a human designed in advance. A script that renames files, a scheduled job that syncs a database, a workflow that routes a form submission to the right queue. The input is expected, the output is the same action every run, and it reaches only the systems it was wired to.
Its failure is visible: something breaks and the run fails or produces an obvious error. When a surprise arrives, automation stops. That is a property, not a defect. It means the blast radius is bounded by the design.
Generative AI
A generative model produces an answer. You give it a prompt and context, and it returns text, code or media. The output differs each run, because it is generated rather than retrieved.
Its failure is different in kind. It produces a fluent, confident answer that may be wrong, and the fluency makes the error hard to see. It also does nothing outside itself. If it answers a question about your calendar, it does not read the calendar. You do.
An agent
An agent decides its own steps at run time, in a loop, in service of a goal you stated in language. It observes the result of each action and chooses the next one. It reaches outside itself through tools and connected data.
That is the definition that matters, and its consequence is that the failure mode changes again. An agent does not usually fail by producing a visibly wrong answer. It fails by confidently completing the wrong task, or by continuing to work after it should have stopped.
The infographic below lays the three side by side.
The one-line test
If you can write down every step in advance, you want automation. If you want one answer, you want a generative model. If you want a goal pursued across steps you cannot enumerate in advance, you want an agent, and you should be prepared to pay for its autonomy with controls.
The Loop That Makes Something an Agent
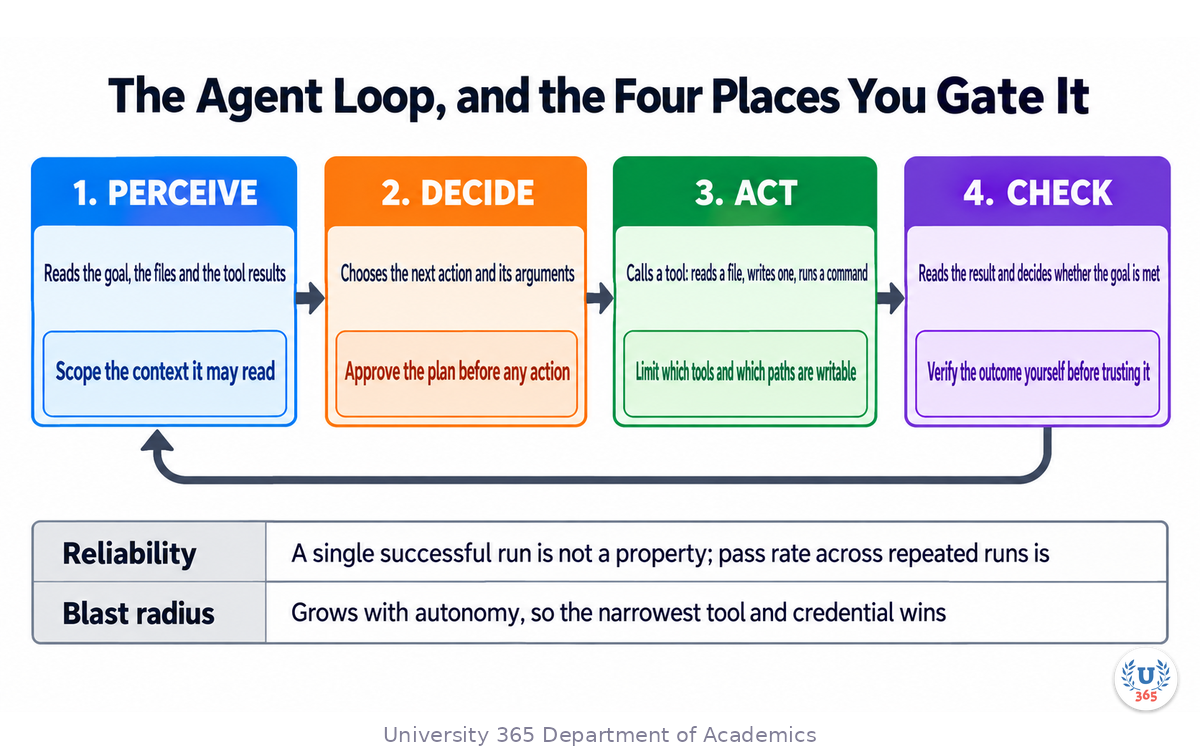
The defining structure is a cycle of four stages. Everything an agent does fits inside it.
Stage one: perceive
The agent reads the goal, the context it has been given, and the results of whatever it did last. In practice this means reading files, querying an index, or receiving the output of a tool call.
The information available at this stage is the agent's entire world. Anything outside it does not exist for the agent, which is why scoping the context is the first control rather than an afterthought.
Stage two: decide
The model chooses the next action and its arguments. It may reason before choosing, which is where the reasoning models changed things: a model that works through a problem before committing makes better choices about which action comes next.
This is the stage that distinguishes an agent from a pipeline. No human wrote the branch that selected this action; the model selected it from the goal and the current state.
Stage three: act
The agent calls a tool. It reads a file, writes a file, runs a command, queries a database, or sends a request. This is the first stage with an effect outside the agent's own process, and it is where irreversibility enters.
A file edit in a version-controlled repository can be undone. A database write, a sent message, or a deployed change cannot, at least not without cost.
Stage four: check
The agent reads the result and decides whether the goal is met. If not, it returns to stage one with new information. If it believes the goal is met, it stops and reports.
The critical detail is the word believes. The agent's completion condition comes from your instruction. If your instruction did not state what finished looks like, the agent invents a definition, and its definition may be weaker than yours.
Why this matters even if you never build one
The loop is the reason agent outputs need a different review than model outputs. A generative model's answer can be checked against a question. An agent's result has to be checked against a goal, and its intermediate actions have to be checked against your boundaries.
How an Agent Reaches the Outside World
An agent without tools is a reasoning system that cannot affect anything. The reach is what makes it useful and what makes it risky, so the mechanism is worth understanding.
Tools
A tool is a function the model can call, with a typed description of its inputs. The description is part of the prompt: the model reads what each tool does and decides when to use it. This means the tool description is a security surface, not just documentation. Instructions hidden in a tool's description are readable by the model and may not be visible to the person who approved the tool.
Connected data
Retrieval gives the agent access to documents, a knowledge base, or a code index. In the current generation, the common route is a standard protocol rather than a bespoke adapter.
The Model Context Protocol, published by Anthropic in November 2024 and moved to the Agentic AI Foundation under the Linux Foundation in December 2025, standardises how an AI application connects to external tools and data. A server exposes capabilities; a client inside the application connects, lists what is offered, and passes the model's requests through. Build one server and every compatible client can use it.
Credentials and permissions
Everything an agent can do, it can do with the authority of whatever credential it holds. This is the sentence that determines your risk.
If the agent connects to a database with an administrative account, then any action within that account is available to it, including ones you would never authorise. If it connects with a read-only account, then even a badly chosen action cannot write.
The narrowest credential that still lets the task succeed is always the right choice, and it is the control most often skipped, because a narrow credential is more work to set up than reusing the one you already have.
Memory and state
Some agents keep state between runs: a log of what they did, a memory of preferences, or a record of which files they already examined. Persisted state is useful and it is also a place where a mistake can accumulate, because a wrong assumption written to memory returns on the next run.
The Four Gates You Control
Every point in the loop has a corresponding control. The infographic shows the loop with its gates.
Gate one: scope the context
Decide what the agent may read. A repository, a document set, a database view. Narrow scope reduces both the chance of a wrong conclusion and the chance that untrusted content reaches the model.
Gate two: review the plan
If your tool supports it, require the agent to state its approach before it touches anything. Reading a five-line plan takes seconds. Discovering that the agent misunderstood the task takes an afternoon. Any difference between the plan and your intent is an instruction you did not write, and those are exactly the things to catch.
Gate three: limit the actions
Constrain which tools the agent may call and which paths it may write. A read-only sandbox lets it investigate without changing anything. A workspace-write sandbox lets it edit inside a project. Full access removes the boundary and is appropriate only in an environment you can discard.
Keep destructive operations behind an approval that a person actually reads, and make sure the person knows what they are approving.
Gate four: verify the outcome
Check the result against your own goal, with your own command, in your own environment. An agent that verified its own work has reported what it believed. Belief is evidence of a sort, and it is not the kind you need.
The two properties that belong beside the gates
Reliability is not a single success. It is the rate of success across repeated runs. An agent that works once and fails a third of the time is not a reliable process, whatever its demonstration showed.
Blast radius is the scope of damage one run can cause. It grows with autonomy and with access, which is why the narrowest tool and the narrowest credential are the default answer rather than a compromise.
Reasoning Models and Why Agents Got Better
Agents existed before the current generation. They were fragile, and the reason is worth understanding.
The earlier problem
An agent's quality depends on the quality of each decision it makes, because errors compound across a loop. Early models made locally plausible choices that were globally wrong: they picked the wrong file, took a shortcut that violated a constraint, or declared success too early. Over ten steps, a five percent per-step error rate becomes a large chance of a bad outcome.
The problem was not the loop design. It was the decision quality inside it.
What changed
Reasoning models spend additional computation at answer time. Instead of emitting the first plausible next step, the model works through the problem, considers alternatives, and then commits. On multi-step tasks this measurably improves the decisions, which is why agent reliability improved without anyone redesigning the loop.
Tool use also became a first-class capability rather than a prompt-engineering trick. A model that was trained to call functions picks the right tool and the right arguments more often, and it recovers better when a call fails.
The third change is the standard protocol described above. Integration work was previously the largest cost in building an agent. Reducing it to a configuration file moved the effort from plumbing to design.
What did not change
The failure modes. A better model still completes the wrong task confidently, because that failure comes from the instruction rather than the model. Better decisions reduce the frequency of a runaway loop; they do not remove the need for a stopping condition.
That is the useful summary of the current generation: the loop got more reliable, and the controls are still yours to set.
Agents in 2026: What Actually Changed in the Tools
The loop, the gates and the failure modes are stable. What has moved quickly is the tooling, and a reader in 2026 needs to know which parts are current rather than remembering a description from a year earlier.
One standard replaced a pile of adapters
The Model Context Protocol moved from an Anthropic project to the Agentic AI Foundation under the Linux Foundation in December 2025, and the 2026 revision made the protocol stateless: each request carries its own version, identity and capabilities, and the session identifier and the initialise handshake are gone. In practice this means an agent's connection to a tool is described by a configuration entry rather than by integration code, and the same server can be reached by any compatible client.
For anyone building or buying, the consequence is that the integration question has changed shape. It used to be "does this product support my system", and it is now "does my system expose a server", which is a question you can answer yourself in an afternoon.
Reasoning became a separate dimension
Current models ship with an effort setting rather than a fixed behaviour. The same model asked to work at high effort will spend more computation before answering, and score better on hard multi-step tasks, at a higher cost and a longer latency. For an agent this matters directly: effort determines how well each decision in the loop is made, and therefore how many steps a run takes before it converges.
The practical reading is that effort is a tuning parameter for cost and reliability together. A routine agent task does not need maximum effort, and paying for it simply lengthens every run.
The model tiers stabilised
Each major vendor now ships three tiers rather than one model: a frontier tier for hard reasoning, a workhorse tier at roughly a fifth to a tenth of the price, and a fast cheap tier for classification, extraction and routing. The capability gap between the workhorse and the frontier tier is usually smaller than the price gap, which makes per-task routing a normal engineering decision rather than a compromise.
For an agent specifically, routing is often the single largest cost lever. Classification and extraction steps do not need the frontier tier, and the decision-making steps do.
Permissions became a first-class product feature
Tool makers converged on the same control vocabulary: a sandbox that constrains what the agent can reach, an approval policy that decides when it stops to ask, and a plan step that lets a person review the intended approach before any change. These are the four gates described in this lecture, exposed as settings.
Treat the specific names as perishable. Vendors change approval policy values and sandbox modes between releases, and a lecture's list will age faster than your project. The durable part is the shape of the control: scope the reach, review the plan, limit the actions, verify the outcome.
Observability arrived last and matters most
The newest addition is tracing. A production agent now emits a record of each step: which tool was called, with what arguments, what came back, how many tokens it cost, and how long it took. Without this, an agent failure is a mystery, because the model's reasoning is not inspectable and the intermediate actions were never recorded.
With it, three questions become answerable that were previously guesswork: where a run spent its budget, which step produced the wrong decision, and how the same task behaves across repeated runs. If you are evaluating an agent platform, the trace is the feature that determines whether you can operate it, and it is worth more than a marginal difference in benchmark score.
How to use this section
When you read any product description of an agent, map it onto the four gates and the trace. Which sandbox modes does it offer? When does it stop and ask? Can a plan be reviewed before the first change? What does the trace record? A product that answers all five questions well is operable. A product that answers none of them is a demonstration.
Where Agents Earn Their Place in Real Work
Agents are not uniformly useful. They pay off where a task has three properties together.
Property one: many steps, uncertain order
If the steps are known and fixed, automation is cheaper, faster and safer. An agent's value appears when the sequence depends on what is found: search a codebase for the caller of a function, then decide whether to update the call site or the function.
Property two: a checkable outcome
If you can state what success looks like, the agent can be given a stopping condition and you can verify the result. If you cannot state it, you cannot verify it either, and an unattended run becomes an unverifiable one.
Property three: tolerance for the occasional miss, or a cheap human gate
Either the task can fail sometimes without harm and be retried, or the outcome passes through a person before it matters. Tasks where a single silent error is expensive and there is no review step are the wrong first choice.
Worked examples
A code migration across many files scores well: many mechanical steps, a test suite as the check, and a diff a person reviews before merge.
Document triage scores well: classify and route incoming material, with a person handling the exceptions.
A customer-facing reply with no review scores badly: the steps are few, the outcome matters, and the error is not detectable until it has been sent.
A financial transaction scores badly: the failure is expensive, irreversible, and the check often happens after the fact.
Two questions that settle most cases
Ask what a wrong action would cost, and ask whether you can tell that it was wrong. If the cost is high and the detection is late, keep a person in the loop regardless of how reliable the agent appears in a demonstration.
Where They Fail, and How Often
Four failure modes account for most agent incidents. Knowing them is what lets you design around them.
Wrong goal, executed well
The agent understood you correctly and acted on the wrong instruction. It reports success in language that matches what you meant. Everything it says is true and the outcome is wrong.
The countermeasure is a written intent with an explicit completion condition, reviewed against the plan before the work begins.
The runaway loop
An agent with a hard task, no verification command and no stopping condition can consume a large budget without converging. Each iteration looks like progress and the run never terminates.
The countermeasure is a stated verification command, a stated behaviour on failure, and supervision of long runs. Cost per task is part of the design, not an operational surprise.
Injection through retrieved content
Anything the agent reads can contain instructions: a web page, a document, an issue comment, a tool result. The model may treat that text as a directive from its operator.
The countermeasure is a posture rather than a setting. Treat retrieved content as data, not as orders. Do not give one agent broad access to everything at once. Keep irreversible actions behind a human approval.
Thin verification
The agent ran the tests and they passed. The tests did not cover the case the change broke. The green result was accurate and meaningless.
The countermeasure is that your test suite becomes part of your agent configuration. Its quality determines how much autonomy is safe.
Measuring failure properly
The right measurement is not whether a demonstration worked. It is the pass rate across repeated runs on your own tasks, at your own cost, with your own review in place. A published benchmark will not give you that number, because your task is not on it.
Reliability: Pass Rate, Not a Single Success
The single most common mistake in evaluating an agent is to judge it from one impressive run.
An agent is a stochastic process. Two runs on the same task can produce different sequences of actions and different outcomes. A demonstration shows that a successful trajectory exists, which is a much weaker claim than that the agent finds one reliably.
Why repetition changes the picture
Suppose an agent succeeds on a given task seventy percent of the time. That sounds acceptable until you ask what seventy percent means in practice: roughly one failure in three. If the failure is detectable and retryable, the process is fine. If it is silent, one third of the outputs are wrong and nothing tells you which.
Agentic benchmarks capture this with a metric called pass^k, the probability of succeeding on k independent attempts in a row. It falls fast. An agent that succeeds seventy percent per attempt succeeds about seventeen percent of the time on five consecutive attempts, which is why pass^k is the number to ask about for any process that must run without supervision.
The four numbers to measure
Pass rate on your tasks. Not on a benchmark. Build a small set of representative tasks, as the Benchmarks lecture describes, and run it repeatedly.
Cost per completed task. Include the failed runs. An agent that costs twice as much and succeeds once more is often the better deal, and you cannot tell without dividing by successes.
Time to completion. Including the human review time. An agent that saves ten minutes of work and costs you fifteen minutes of review has not saved anything.
Rate of silent error. The proportion of runs that report success and are wrong. This is the number that decides whether a task can run unattended.
The practical rule
Grant autonomy in proportion to your measurement, not in proportion to the agent's demonstration. A task with a strong automated check and a cheap retry can run unattended. A task with a late-detection failure needs a person in the loop, whatever the pass rate.
What You Must Decide Before You Delegate
Five decisions, and all five belong to you rather than to the tool.
One: what the task is
State it in one sentence, in terms of the outcome rather than the steps. If you cannot write the sentence, the task is not ready to delegate.
Two: what a wrong action would cost
Time, money, a customer relationship, a compliance obligation. Name the cost, because it determines how much autonomy is appropriate.
Three: how you will detect a wrong outcome
Name the check. If the answer is "someone would notice eventually", the detection is too late for an unattended run.
Four: what the agent may reach
The credential and the tools. State them explicitly. The narrowest option that still works is the answer.
Five: who reviews, and when
Approve before the action, review after the run, or both. Write it down. In practice, most agent incidents are the result of a review step that everyone assumed someone else was doing.
The delegation test
A task is ready to delegate when you can answer all five questions without inventing anything. If any answer is "we would figure it out", that is the part to fix first, and it is a better use of an hour than another trial run.
Feynman Summary: Explain It Like You Are 12
Imagine you have a very fast helper who is excellent at following instructions and does not get tired.
Some jobs are good for this helper. If you say "go through all these boxes and put every blue folder in the cupboard", the helper can do it, you can check the cupboard afterwards, and if one folder is in the wrong place you can fix it in a second.
Some jobs are not good. If you say "handle my messages while I am away", the helper does not know which messages are urgent, which people are joking, or which one you would want to answer yourself. It will do something reasonable, it will sound confident, and you may only find out it went wrong days later.
The difference is not how clever the helper is. It is whether you can tell, quickly and cheaply, whether the job was done right.
So the trick is: give the helper jobs where being wrong is easy to spot and cheap to fix, keep the important decisions for yourself, and always look at what it actually did rather than at its note saying it went well.
Mindmap: The Complete Picture
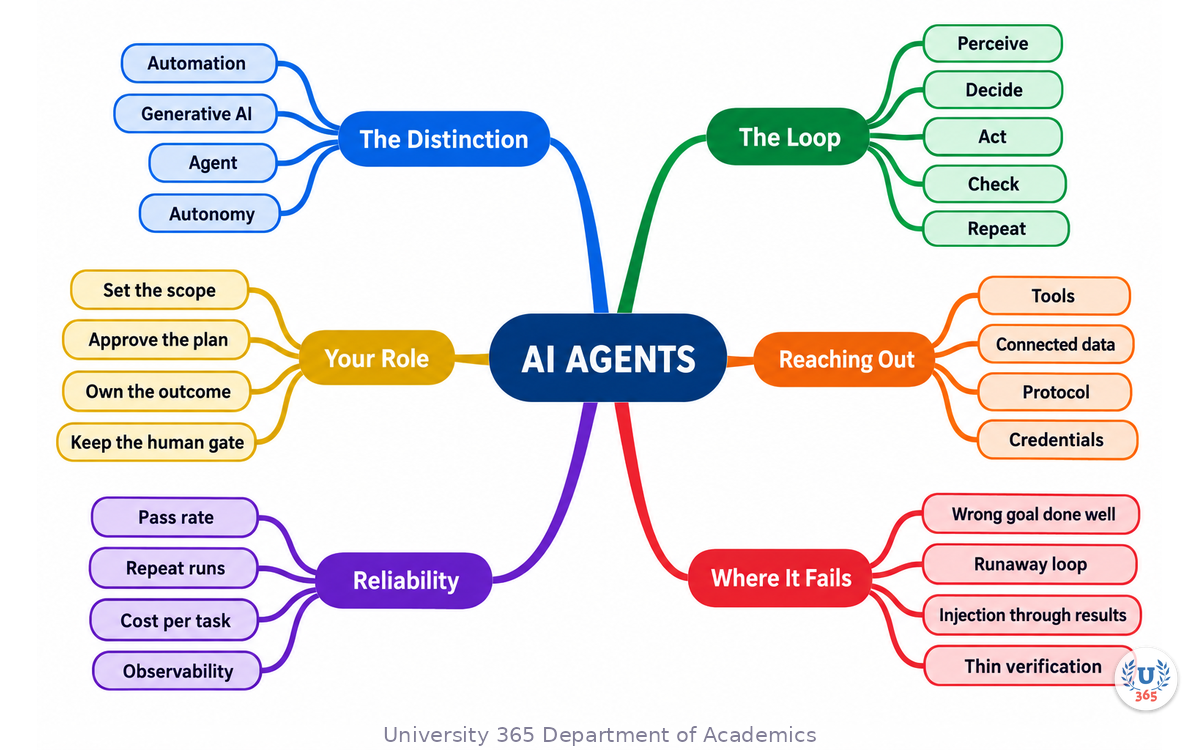
The mindmap puts AI agents at the centre and branches to the distinction from the two neighbouring ideas, the four-stage loop, the reach into tools and data, the failure modes, the measurement of reliability, and the part a person keeps.
UNOP Sound (University 365 Neuroscience Oriented Pedagogy)
Take five minutes to consolidate your memory. Play the isochronous tone track (10Hz alpha frequency) with your eyes closed. Alpha-frequency tones after a learning session support consolidation, helping move what you just learned from short-term to long-term memory.
[Audio player: UNOP Post-Lecture Isochrone (10Hz, 5 minutes)]
Practical Exercise: Scope One Agent Task and Gate It
This exercise takes about one hour, and it produces a decision document rather than a running system.
Step 1: Name one task you would genuinely delegate
Choose something you actually do, not a hypothetical. Write it in one sentence as an outcome, not as a sequence of steps.
Step 2: Answer the five delegation questions
Write down the task, the cost of a wrong action, how you would detect a wrong outcome, what the agent may reach, and who reviews. Do not move on until all five have a written answer.
Step 3: Place the task against the three properties
Many steps with uncertain order? A checkable outcome? Tolerance for a miss, or a cheap human gate? If it fails two of the three, write down why you still want to delegate it, or drop it.
Step 4: Set the four gates
Write the specific setting for each: the scope of what it may read, whether a plan is reviewed first, which tools and paths it may write, and the exact command you will run to verify the result.
Step 5: Design the check before you run anything
Write the test that will prove a good run had the effect you intended, and the test that will prove a bad action is refused. A task without both is not ready.
Step 6: Run it three times, not once
Run the same task three times and record: the outcome, the cost, the review time, and whether the agent's report matched what it actually did. Three runs will tell you more than thirty minutes of reading about reliability.
What to look for
If Step 2 produced "we would figure it out" anywhere, that is your finding. If Step 6 produced one good run and two that differed, you have measured a pass rate rather than a demonstration, which is the whole point of the exercise.
Applied AI connection
This is the CI-First position applied to delegation. You remain the orchestrator; the agent's reach and its stopping conditions are things you decide and document rather than things you discover. The value of the discipline is that it lets you delegate more, not less, because you know where the boundaries are.
Glossary
Term | Definition |
Automation | A fixed sequence of steps a human designed in advance, with expected input and the same action every run. |
Generative AI | A model that produces text, code or media from a prompt and context, without acting outside itself. |
AI agent | A system that decides its own steps at run time, in a loop, in service of a goal stated in language. |
Agentic loop | The four stages an agent cycles through: perceive, decide, act, check. |
Tool | A function an agent can call, described in a typed schema the model reads; the description is part of its prompt and therefore a security surface. |
Model Context Protocol (MCP) | The open standard published by Anthropic in November 2024 and hosted by the Agentic AI Foundation under the Linux Foundation from December 2025, standardising how AI applications connect to tools and data. |
Credential scope | The authority an agent holds when it acts; the narrowest credential that still completes the task is the correct default. |
Sandbox | The boundary limiting where an agent may write and what it may reach, such as read-only, workspace-write, or full access. |
Approval policy | The rule deciding when an agent must stop and ask, such as on-request or never. |
Plan gate | Requiring the agent to state its approach for review before it modifies anything. |
Blast radius | The scope of damage a single autonomous run can cause; it grows with autonomy and with access. |
Runaway loop | A run that continues without converging, consuming budget without producing a correct outcome. |
Prompt injection | Instructions embedded in content an agent reads, which the model may treat as directives from its operator. |
Pass rate | The proportion of runs that succeed on a task; a single successful demonstration is not a pass rate. |
pass^k | The probability of succeeding on k independent attempts in a row; it falls quickly even at a high per-attempt success rate. |
Cost per completed task | Total spend divided by successes, including failed runs. |
Silent error rate | The proportion of runs that report success and are wrong; the number that decides whether a task may run unattended. |
Reasoning model | A model that spends additional computation at answer time working through a problem before committing to an output. |
Human gate | A required human decision at a defined point in a run, either before an action or before its outcome is used. |
Quiz: TEST YOUR UNDERSTANDING
1. What distinguishes an agent from automation?
A) It runs faster
B) The model decides its own steps at run time, rather than following a sequence a human wrote in advance
C) It uses a larger model
D) It runs on a schedule
2. What distinguishes an agent from a generative model?
A) An agent produces longer answers
B) An agent acts outside itself through tools and repeats until a goal is met, rather than producing one answer
C) An agent is more accurate
D) An agent has no prompt
3. Which stage of the loop introduces irreversibility?
A) Perceive
B) Act, because a tool call can write to a database, send a message, or deploy a change
C) Decide
D) Check
4. Why is a tool's description a security surface?
A) Because it slows the model
B) Because the model reads it as part of its prompt, so instructions hidden there are readable by the model and may not be visible to the person who approved the tool
C) Because it must be written in JSON
D) Because it costs tokens
5. What is the correct default for an agent's credential?
A) An administrative account, so it never fails for permission reasons
B) The narrowest credential that still lets the task succeed
C) The same credential a developer uses
D) No credential
6. Why did agents get more reliable in the current generation?
A) Because the loop was redesigned
B) Because reasoning models make better decisions at each step, so errors compound less across the loop
C) Because tools became cheaper
D) Because prompts became shorter
7. What does pass^k measure?
A) The number of steps in a run
B) The probability of succeeding on k independent attempts in a row
C) The cost per task
D) The number of tools available
8. Which task is the worst first choice for an agent?
A) A code migration across many files with a test suite
B) A customer-facing reply sent with no human review, where the error is only discovered after it matters
C) Document triage with a person handling exceptions
D) A repository search followed by a decision
9. What is a runaway loop?
A) An agent that reads too many files
B) A run that continues without converging, consuming budget without producing a correct outcome
C) An agent that repeats a successful action
D) A tool that returns an error
10. When is a task ready to delegate?
A) When an agent demonstrates it once
B) When you can answer all five delegation questions without inventing anything: the task, the cost of being wrong, the detection method, the access granted, and who reviews
C) When the tool supports it
D) When the model has a large context window
Answers: 1-B, 2-B, 3-B, 4-B, 5-B, 6-B, 7-B, 8-B, 9-B, 10-B
Related Resources
U365 INSIDE Publications
Lecture: Understanding AI Benchmarks: how agentic capability is measured, including pass^k and why agent scores are the least comparable
Lecture: The Model Context Protocol (MCP): Connecting AI to Everything: how an agent reaches tools and data in a standardised way, and the controls that govern that reach
Lecture: Building Your First AI Agent with Function Calling: the first loop, built step by step
External Resources
Model Context Protocol specification: the current version of the protocol used for connected tooling, including its security guidance.
tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains: the agentic benchmark and the pass^k metric described in the reliability section.
OWASP Top 10 for Large Language Model Applications: the application-security framing that covers prompt injection and excessive agency.
The National Security Agency information sheet "Model Context Protocol (MCP): Security Design Considerations for AI-Driven Automation" (May 2026, reference U/OO/6030316-26): an official treatment of access control gaps, insecure serialization, weak approval workflows and token or session security in agent tooling.
Agentic AI Foundation (aaif.io): the body that hosts the Model Context Protocol under the Linux Foundation, with the member roster and the project governance.
Related U365 Lectures (Coming Soon)
Evaluating Tool-Using Agents: Test Sets That Catch Regressions, in the AI Engineering series
Agent Handoffs and the A2A Protocol, in the AI Engineering series
U.Copilot for This Lecture
Use this prompt with your own AI assistant to decide whether a task should be given to an agent, and to write the controls first. It follows the UP-Context-Engineering method: context first, then the task, then the constraints, then the output shape.
CONTEXT I am deciding whether to delegate a task to an AI agent, and I want the boundaries written down before anything runs. The task: [one sentence, stated as an outcome] How I do it today: [one or two sentences] What a wrong action would cost me: [time, money, relationship, compliance] How I would notice a wrong outcome: [the check, and how soon it runs] What the agent would need to reach: [files, databases, APIs, email] The credential available to it: [describe the exact scope] Whether a person can review before or after: [before, after, both, or no] How often I need this done: [frequency] TASK 1. Classify this task: is it a fit for automation, a generative model, or an agent? Justify the classification from the three properties: many steps with uncertain order, a checkable outcome, and tolerance for a miss or a cheap human gate. 2. Test the task against the worst-first-choice pattern: is there a single silent error that would be expensive, with late detection? If so, say what must change. 3. Write the four gates for this task: the scope of what it may read, whether a plan is reviewed first, which tools and paths it may write, and the exact verification command. 4. Write the two tests I need before enabling it: one proving a bad action is refused, one read-back proving a good run had the intended effect. 5. Design the reliability measurement: how many runs, what to record, and what pass rate would justify running it unattended. 6. Name the three conditions under which I should take the agent off this task. CONSTRAINTS Use only the information I gave you and what is in this conversation. Do not invent tool names, credential scopes, cost figures or pass rates. Where a control depends on a feature of a specific product, name the feature so I can verify it rather than assuming it exists. Separate what is measured from what is assumed. OUTPUT First a one-line verdict: automate, delegate with a gate, delegate unattended, or do not delegate. Then the four gates as a table. Then the two required tests. Then the measurement plan. Then the three off-switch conditions. End with the single control I am most likely to skip.
Next Steps
Run the exercise on one real task this week, and run it three times rather than once. Three runs turn a demonstration into a pass rate
Inventory the agents already running in your tools and write down, for each, what credential it holds and which gates are set. You cannot govern reach you have not listed
Write a verification command for every delegated task before it runs. A task without one cannot be checked, and cannot safely run unattended
Narrow one credential this month. Replacing a broad account with a read-only or scoped one is the single highest-value control available
Measure cost per completed task, including failures, for anything you run regularly. It is the number that decides whether the delegation is worth keeping
The loop got better, and the reach did not get safer on its own. The controls are still yours to set, and the difference between a useful agent and an expensive incident is usually one written boundary that somebody decided to add before the run rather than after it.
IMPORTANT NOTICE
This lecture is published by University 365 as part of its INSIDE Publications Hub. The content is free to read for all visitors. Lectures in this series may be part of a structured academic program leading to a Micro-Credential for your Career (MCC). To enroll in an academic program, visit university-365.com/tuition.
This content is for educational purposes. While we strive for accuracy, AI is a fast-moving field. Verify current technical details against primary sources for professional applications.
Copyright University 365, Inc. All rights reserved. This content is protected under University 365's copyright policies. For permissions or inquiries, contact uda@university-365.com.
Published by the Department of Academics, University 365.
Lecture delivered by the University 365 Institute of Technology (UIT).
Sam Utteker, Dean of Technology, UIT
Signed for the academic year 2026.



Comments