
Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud

Status: Retired | Last tested: 2026-11-14 (Gemini 3.5 Flash, `gemini-3.5-flash`, released 2026-05-19) | Re-check: trigger-based (max 6 months)
Retired: the tool still works but is no longer recommended. See the Migration Path section.
For detailed explanations of the CI-First evaluation terms used in this review, including the Humics Protection Badge and the AI Imposture Risk levels, see the Glossary at the end of this post.

In this Tool Review

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
The Gemini 3.5 Flash name, the thinking levels and two vendor surfaces that disagree about the model this review scores
Three facts have to be settled before anything is scored: which model this review is about, what the family naming does and does not cover, and what "available" means for a model that one Google surface still sells and another has already replaced.
Name | What it is | Where it appears |
Gemini 3.5 Flash | The model this review scores. Model id gemini-3.5-flash, released 2026-05-19 | The launch post, the model card, the Google Cloud model page, the deprecation table |
Gemini 3.5 | The family name used in the launch post, which opened with 3.5 Flash and promised 3.5 Pro for the following month | The launch post of 2026-05-19 |
Gemini 3.5 Flash-Lite | A separate, cheaper model in the same family, released 2026-07-21, at $0.30 and $2.50 per million tokens | The pricing page, the model list, the U365 review of Flash-Lite |
Gemini 3 Flash (Preview) | The base this model was built on, released 2025-12-17, at $0.50 and $3.00 per million tokens | The model card's dependency statement, the deprecation table, the pricing page |
Gemini 3.6 Flash | The recommended replacement, released 2026-07-21, and the model an unmodified request to this ID now reaches on the Developer API | The deprecation table, the pricing page, the Google Cloud model page |
Gemini 3.8 Flash | The current model in this line, released 2026-09-02, at $0.75 and $3.75 through 2026-12-31 | The model list, the pricing page, the U365 review of 3.8 Flash |
This is a new review rather than a re-score, and the distinction is not administrative. No U365 review of Gemini 3.5 Flash has ever been published. The library carries Gemini 3.1 Pro, 3.6 Flash, 3.7 Flash, 3.8 Flash, 3.5 Flash-Lite, 3.8 Live, Gemini 4 Argon, Gemini 4 Carbon and Gemini 4 Hydrogen, and the nearest neighbours to this model are the 3.5 Flash-Lite review at 5.5 and the 3.6 Flash review at 5.3. Neither is a substitute: Flash-Lite is a different and cheaper model, and 3.6 Flash is the successor that replaced this one two months after launch.
The family skipped a number, and the vendor's own record shows it. The launch post of 2026-05-19 says Google is "kicking off the series by releasing 3.5 Flash" and that 3.5 Pro is "already being used internally" with a rollout "next month". No gemini-3.5-pro appears on the current model list or on the deprecation page, and the U365 library carries no 3.5 Pro review. The successor line then ran 3.6 Flash on 2026-07-21, 3.7 Flash on 2026-08-13 and 3.8 Flash on 2026-09-02, three generations in six weeks.
"Available" has two answers, and this review reports both rather than picking one. On the Gemini Developer API, gemini-3.5-flash is no longer available in Google AI Studio, and the deprecation table states that the endpoint is not shutting down and that API requests automatically route to gemini-3.6-flash. On Google Cloud, the same ID is generally available, with a release date of May 19, 2026 and a retirement date of May 19, 2027 or later. A reader on the Developer API is not running this model at all. A reader on Google Cloud is, and has the longest published support window in the 3.x Flash line.
What this review is. It is the URC scoring of Gemini 3.5 Flash under the CI-First Evaluation Framework, version 1.4.1, on evidence read on 2026-11-14: the launch post of 2026-05-19, the model card, the Google Cloud model page and its thinking-level table, the Gemini API model list, pricing page and deprecation table, the Artificial Analysis model page, the Hacker News launch thread with its two follow-up threads, and the published U365 scores of the models this one is compared against.
What this review is not. It is not a review of the Gemini app, of AI Mode in Search, of Google Antigravity, of Gemini Enterprise, of the Gemini Enterprise Agent Platform as a product, or of Gemini 3.5 Flash-Lite. Those surfaces appear where a scored fact depends on them. It is not a re-score of Gemini 3 Flash, Gemini 3.6 Flash, Gemini 3.7 Flash or Gemini 3.8 Flash, each of which has its own document. And it is not an assessment of Google's safety programme beyond the facts a buyer of this model has to carry, which are stated in Section 7c with their sources named.
The score is 5.3, and the badge is Retired, and the two are not in conflict. The framework measures the benefit a tool delivers when it is used, not whether the reader should buy it today. A model that was fast, capable for its class and cheap enough to run at volume in May 2026 still delivers a positive net benefit to the person who is already running it on Google Cloud. It is retired because the same money now buys a faster route, a lower price and a current support line, and because the ID on the Developer API no longer selects this model. The Verdict and the Migration Path carry that distinction; the score does not try to.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Tool Snapshot
Gemini 3.5 Flash, the model Google launched as frontier intelligence at Flash speed and priced at three times its predecessor: a genuine speed and agentic-capability step in May 2026, replaced on the Developer API two months later and still sold on Google Cloud as a GA model with a support window to May 2027.
Category: Applied AI / Large Language Model. Agentic coding, tool use, multimodal document triage, computer-use agents and high-volume execution. It sat below the Pro line on depth and above the Flash-Lite line on price when it shipped.
Primary use cases:
Agentic coding with a checkable end state. The vendor reports 76.2 percent on Terminal-Bench 2.1 against 58.0 for Gemini 3 Flash and 70.3 for Gemini 3.1 Pro, and 55.1 percent on SWE-Bench Pro against 49.6 and 54.2. The launch materials show it transforming a legacy codebase to Next.js and running builder and player agents in a loop.
Multi-step tool use behind an agent loop. MCP Atlas at 83.6 percent against 62.0 for its predecessor, Toolathlon at 56.5, and function calling, structured output, URL context, code execution and Google Search grounding all supported on the Cloud surface.
Multimodal document and chart work inside a million-token window. Text, image, audio and video input with 84.2 percent on CharXiv Reasoning and 83.6 on MMMU-Pro, both without tools.
Computer-use agents. Added on 2026-06-24 as a built-in tool, with 78.4 percent on OSWorld-Verified at launch, against 65.1 for its predecessor.
High-volume execution where the answer is checked by a schema or a second model. Batch inference, Flex and Priority pay-as-you-go, provisioned throughput and context caching at a 90 percent discount.
What it is not. It is not the frontier model of its generation: on the vendor's own table it trails Claude Opus 4.7 and GPT-5.5 on Terminal-Bench, SWE-Bench Pro, GDPval-AA, ARC-AGI-2 and Humanity's Last Exam, and it leads them only on some multimodal and agentic-tool rows. It is not a cheap model by the standards of the line it replaced: at $1.50 and $9.00 it is three times the price of Gemini 3 Flash Preview and six times the price of Gemini 3.1 Flash-Lite, which is why the launch thread is dominated by price rather than capability. It is not a long-context model at the top of its window: 77.3 percent on MRCR v2 at 128k falls to 26.6 percent at 1M. It is not a knowledge model: the cutoff is January 2025, fourteen months before release. It is not a teacher, it is not open weights, and it is not inspectable from outside Google's service. And it is no longer the model that answers to its own ID on the Gemini Developer API.
Pricing, as published on 2026-11-14:
Line | Rate per million tokens | Note |
Input (text, image, video, audio) | $1.50 | Global endpoint; $1.65 on non-global endpoints |
Output (response and reasoning) | $9.00 | Global endpoint; $9.90 on non-global endpoints |
Context caching | $0.15 | 90 percent discount on the input rate |
Batch input and output | $0.75 and $4.50 | 50 percent discount on both lines |
Provisioned throughput | $2.70 and $16.20 | 1.8 times the pay-as-you-go rate |
The rate card is the finding, not the footnote. Gemini 3 Flash Preview, the model this one is built on, was $0.50 and $3.00. Gemini 3.1 Flash-Lite was $0.25 and $1.50. This model arrived at $1.50 and $9.00, which is close to the $2.00 and $12.00 of Gemini 3.1 Pro Preview and three times the Flash tier it replaced. The successor is now $0.75 and $3.75 through 2026-12-31, which is half the input price and less than half the output price of the model it replaced. A reader who bought the Flash tier for cheap iteration in May 2026 was buying a different product by July.
Official links:
Launch post, "Gemini 3.5: frontier intelligence with action": https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-5/
Model card, published 19 May 2026: https://deepmind.google/models/model-cards/gemini-3-5-flash/
Model card PDF: https://storage.googleapis.com/deepmind-media/Model-Cards/Gemini-3-5-Flash-Model-Card.pdf
Google Cloud model page, gemini-3.5-flash: https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-5-flash
Thinking levels, model by model: https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/thinking
Gemini API model list: https://ai.google.dev/gemini-api/docs/models
Gemini API pricing: https://ai.google.dev/gemini-api/docs/pricing
Gemini API deprecations, including the routing note: https://ai.google.dev/gemini-api/docs/deprecations
Computer use in Gemini 3.5 Flash, added 2026-06-24: https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-computer-use-gemini-3-5-flash/
Google Cloud generative AI pricing: https://cloud.google.com/vertex-ai/generative-ai/pricing
LLM-specific fields:
API model identifier: gemini-3.5-flash. No dated snapshot name is published for this model; the identifier is the model.
Context window: 1,048,576 tokens. Maximum output: 65,536 tokens, stated as 64K on the model card.
Modalities: text, image, audio and video input; text output only. Agentic video understanding is not supported on the Cloud surface for this model.
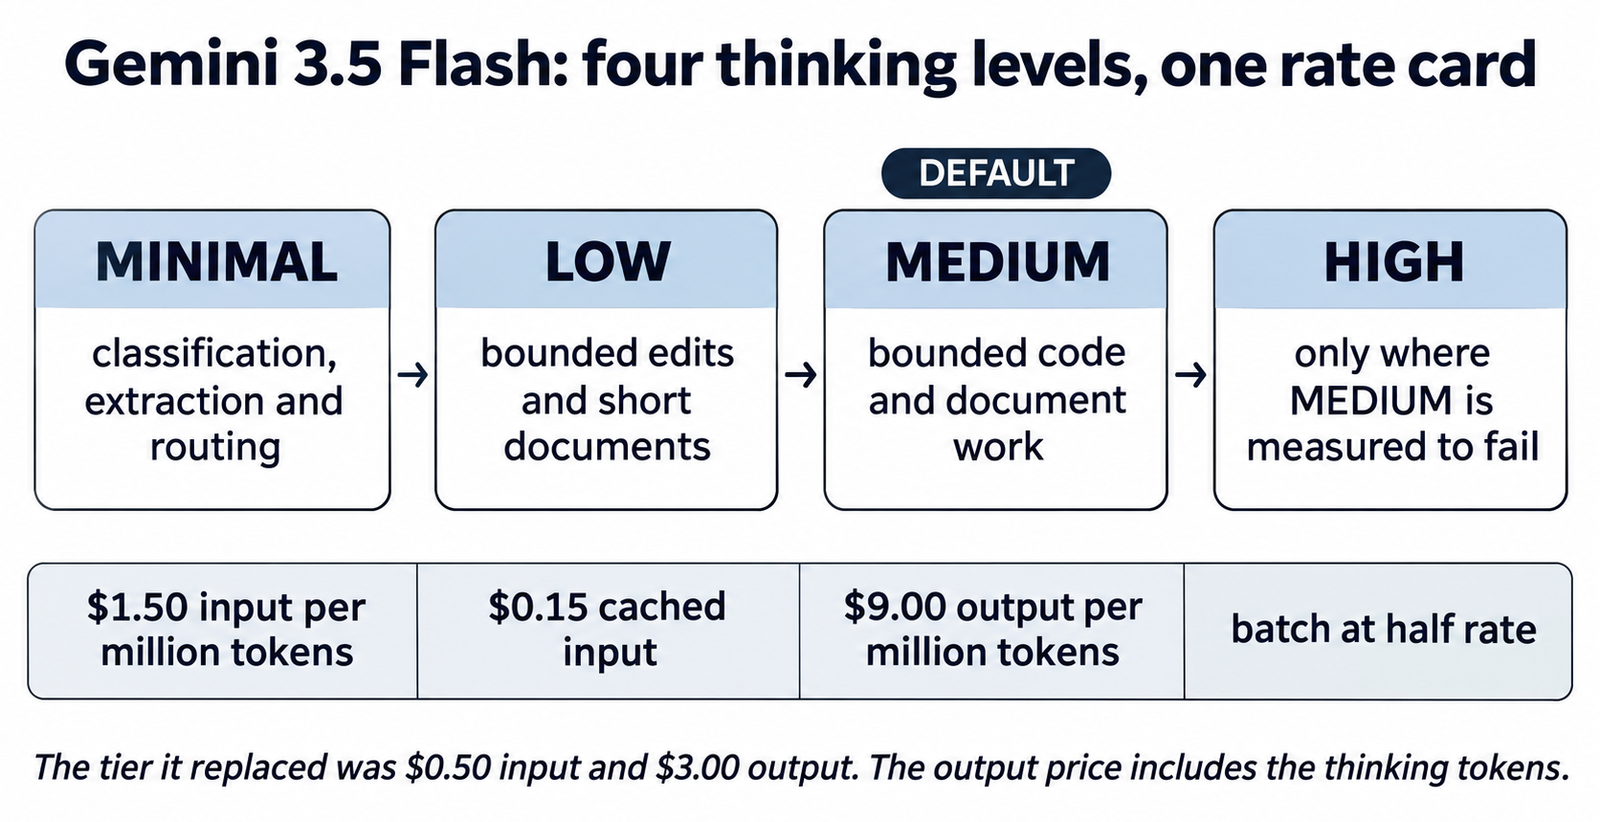
Thinking levels: MINIMAL, LOW, MEDIUM and HIGH, with MEDIUM as the default. The level is a request setting, and the output price includes reasoning tokens.
Supported capabilities on Google Cloud: system instructions, structured output, implicit and explicit context caching, RAG Engine, supervised and reinforcement-learning fine-tuning, Google Search and Parallel Web Search grounding, code execution, function calling, URL context, computer use.
APIs: GenerateContent, Interactions, Count Tokens and Chat Completions supported; the Gemini Live API is not.
Consumption options: Batch inference, Provisioned Throughput, Standard PayGo with usage tiers, Flex PayGo and Priority PayGo.
Knowledge cutoff: January 2025, as reported from the vendor's "What's new in Gemini 3.5 Flash" documentation at launch.
Model relationship: built on the Gemini 3 Flash reasoning foundation, per the model card, with thinking levels added to control the mix of quality, cost and latency.
Parameters and architecture: not disclosed. No parameter count, no weights, no architecture description beyond the reference to Gemini 3 Flash.
License: proprietary hosted service. Not open weights and not self-hostable.
Lifecycle: GA on Google Cloud with a retirement date of May 19, 2027 or later; no longer available in Google AI Studio on the Developer API, where requests route to gemini-3.6-flash.
At a Glance Dashboard
Field | Value |
Category | Applied AI / Large Language Model (agentic coding, tool use, multimodal document work and high-volume execution) |
CI-First Benefit Score | 5.3 / 10 (CI-First Positive) |
Sub-scores | Time 6 / Quantity 6 / Quality 6 / Skill 3 |
CI-First Profile | Primary: Co-Worker and Assistant (level 2). Secondary: Co-Researcher, Analyst and Tester (level 4) |
Humics Protection | Humics-Neutral (-1 / +3) |
AI Imposture Risk | Medium overall, with Skill Illusion High |
Status | Retired |
Last tested | 2026-11-14 |
Released | 2026-05-19 |
Access | Google Cloud (Gemini Enterprise Agent Platform), generally available; Gemini Developer API, where the ID routes to Gemini 3.6 Flash |
Price | $1.50 per million input tokens, $9.00 per million output tokens, cache at $0.15, batch at $0.75 and $4.50 |
Context window | 1,048,576 tokens in, 65,536 tokens out |
Thinking levels | MINIMAL, LOW, MEDIUM (default), HIGH |
Framework comparison with siblings and peers | Gemini 3.6 Flash 5.3 (CI-First Positive); Gemini 3.5 Flash-Lite 5.5 (CI-First Positive); Gemini 3.8 Flash 7.0 (CI-First Strong); Gemini 4 Hydrogen 6.3 (CI-First Strong) |
Benchmarks, one line each | Vendor, May 2026: 76.2 percent on Terminal-Bench 2.1, 55.1 on SWE-Bench Pro, 83.6 on MCP Atlas, 78.4 on OSWorld-Verified, 1656 Elo on GDPval-AA, 84.2 on CharXiv, 83.6 on MMMU-Pro, 77.3 on MRCR v2 at 128k and 26.6 at 1M, 40.2 on Humanity's Last Exam, 72.1 on ARC-AGI-2. Independent: 11.65 seconds to first answer token and 167 output tokens per second, with no Intelligence Index published at review time |

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
The Problem
The model is faster and more capable than the Flash tier it replaced, and the buyer's problem is that the price and the product moved in opposite directions: a 3x rate rise for a model that was replaced on the Developer API two months later.
Five problems sat in front of a reader deciding about Gemini 3.5 Flash in May 2026, and four of them still apply to the reader who finds it on Google Cloud today.
The first is that the tier stopped being cheap, and the launch thread noticed before it noticed anything else. The first substantive comments on Hacker News were the price. f311a wrote the rate card as a single line: "$9/1M output". swe_dima put it as "Flash family but costs like a Pro. $9 vs $12 for output." bakugo called it "Triple the price of the last Flash model ($3 -> $9 per 1M output)" and added that it feels "like the AI pricing noose is tightening". asar counted the multiplier against the cheapest model in the line and got six. The launch post's own framing supports the reading rather than answering it: it sells the model on doing frontier work "often at less than half the cost of other frontier models", which is a comparison against Pro and frontier models, not against the Flash tier it replaced.
The second is that the speed advantage is real at the bottom of the thinking ladder and can disappear at the top. Google's headline is four times the output tokens per second of other frontier models, and one independent latency benchmark, run at the low setting, put the average answer at 2.84 seconds against 33 seconds for GPT-5.5. But this is a reasoning model whose thinking tokens are billed as output, and two practitioners measured the consequence. pqdbr reported that "in real production use cases" it was "10-15% slower and also more expensive than Gemini 3.1 Pro, because it thinks more than 2.5x". nl measured an agentic SQL benchmark at 19 of 25 against 22 of 25 for 3.1 Flash-Lite, at 367 seconds against 142 seconds. The same model, on the same class of task, can be the fastest thing available or slower than the model it was supposed to beat, and the setting decides which.
The third is that cost per task is not cost per token, and on the vendor's own benchmark selection the new Flash cost more to run than the old Pro. The independent evaluation house Artificial Analysis publishes the cost of running its whole benchmark suite against each model. Simon Willison read those figures on launch day: Gemini 3.5 Flash at high cost $1,551.60 to run the suite, against $892.28 for Gemini 3.1 Pro Preview, $278.26 for Gemini 3 Flash Preview and $93.60 for Gemini 3.1 Flash-Lite Preview. A model sold as the fast, cheap tier cost 74 percent more than the previous Pro to evaluate, because it spent more tokens. That single comparison is the clearest statement of what went wrong with the tier's economics.
The fourth is that the model was the default for billions of people within a day, and the defaults are where the imposture risk lives. The launch post states that 3.5 Flash became the default model for the Gemini app and for AI Mode in Search globally, and that the Gemini Spark personal agent runs on it. That is a distribution fact, not a defect, and it changes what a review has to say: a model that answers for a search box is a model whose fluency is consumed by people who did not choose it and cannot check it. The thinking-level dial makes this worse rather than better, because a dial labelled HIGH reads as a quality setting to exactly the user who cannot tell whether more thinking produced a better answer.
The fifth is that the product was replaced faster than any buyer could plan around. 3.5 Flash shipped on 2026-05-19. Gemini 3.6 Flash shipped on 2026-07-21, and the Developer API now routes this model's ID to it. Gemini 3.7 Flash followed on 2026-08-13 and 3.8 Flash on 2026-09-02. The Google Cloud retirement dates make the same point from the other direction: 3.6 Flash is listed for retirement on 2026-11-19, while this older model carries a date of May 19, 2027 or later. The older model has the longer support window, which is the only reason this review still has a Cloud-side argument to make.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
The Outcome
What changes for a reader who adopts this model, and what does not.
Agentic coding became usable at the Flash price, briefly. Terminal-Bench 2.1 rose from 58.0 percent on Gemini 3 Flash to 76.2, and SWE-Bench Pro from 49.6 to 55.1. The launch materials show the model converting a legacy codebase to Next.js and running two agents, a builder and a player, in a self-improvement loop. That is a change in what the tier could be asked to do, and it is the strongest part of the record.
Tool use at scale arrived with a caveat the vendor's own table hides. MCP Atlas at 83.6 percent is a large gain over 62.0, and the agent orchestration story is coherent. But practitioners who ran it in production reported the opposite direction on instruction following: data-ottawa found it "very bad at instruction following vs 3.1", calling tools it had been told not to call, and noted that the release notes suggest reducing thinking to reduce unnecessary tool calls. The capability is real; the control of it is not uniform.
Multimodal reading is the quiet strength. 84.2 percent on CharXiv without tools, 83.6 on MMMU-Pro, and text, image, audio and video input in one window. A reader whose work is a set of dense PDFs, charts and screenshots gets a genuinely better first pass than the previous Flash tier offered.
The long-context promise does not hold at the top of the window. MRCR v2 scores 77.3 percent at 128k and 26.6 percent at 1M. The window is a million tokens; the usable retrieval range is far smaller, and a workflow that fills the window will degrade quietly rather than fail loudly.
The price went up, and the successor's went down. $1.50 and $9.00 at launch against $0.50 and $3.00 for the model it replaced. Today the successor is $0.75 and $3.75 through 2026-12-31, then $1.50 and $7.50. Whatever the capability gain was worth, the buyer is now paying more for the older model than for the newer one.
The knowledge cutoff is January 2025. Fourteen months before release, and nineteen months before this review. Anything time-sensitive needs grounding, retrieval or documents, and the search tool is the only route the model has to the present.
What does not change is the shape of your work. You still state the task and the finish line, choose a thinking level, read the output and verify it against something outside the conversation. The framework's Skill sub-score of 3 says that plainly: this model executes, it does not teach, and a model that is retired makes learning its particular behaviour a depreciating investment.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Who Should Use Gemini 3.5 Flash
Learner type | Difficulty | Typical ROI | Career path |
Students (Bachelor, Master) | Intermediate | A student meets this model mostly through the Gemini app and AI Mode in Search, where it was the default at launch, and through Google AI Studio while it was still selectable there. Its value in study is multimodal reading: a set of lecture slides, a scanned chapter, a chart and a photo in one prompt, at a quality that beats the previous Flash tier on CharXiv and MMMU-Pro. The risk is the one the whole review is about: an answer that reads as finished, from a model whose thinking level the student did not choose and cannot evaluate. | UIT (Technology, AI, Data Science) tracks through agentic coding practice and evaluation design. UIC (Digital Communication, Marketing) for source reading and drafting. No published U365 credential assesses model lifecycle or thinking-level policy as a named component, and none is asserted. |
Professionals (career upskilling) | Intermediate | The strongest case in the release, and a narrowing one. Engineers running bounded agentic tasks on a real repository, analysts reducing a document set to a table, and teams that need a fast multimodal model behind an internal tool. On Google Cloud it is still a supported GA model with a longer published runway than its own successor. On the Developer API it is not the model that answers, which turns an engineering choice into a procurement question. | UIT (Technology, AI, Data Science) engineering tracks for agent supervision and tool-use design, and UIB (Business Management, Entrepreneurship) for the cost-per-task arithmetic that decides whether a workflow survives its second month. |
Everyone (lifelong learners) | Beginner in the app, Intermediate for agentic work | In the Gemini app and Search this was, for a period, the model behind the answer box: fast, fluent and multimodal. That is a good default for reading a long page, summarising a video or drafting a message, and a poor one for any decision the reader cannot check. The January 2025 cutoff matters here more than anywhere else, because the everyday questions people ask a search box are the ones most likely to need current facts. | LIPS Collect and Review phases for reading and drafting, and the UP-Context-Engineering Method order for prompting. UNOP fit is weak, because the model produces rather than teaches. No assessment home is asserted. |
For teams and organisations. The model is sold to companies as well as to individuals, and a team deciding on it starts with four questions.
Team deployment. Reachable across a team through Google Cloud's Gemini Enterprise Agent Platform, Gemini Enterprise, Google Antigravity, the Gemini API and, while it lasted, Google AI Studio. The deployment question is no longer "can we get it" but "which surface are we on": a team that builds against the Developer API is calling Gemini 3.6 Flash under a 3.5 Flash ID, and a team that builds against Google Cloud is calling this model with a retirement date of May 19, 2027 or later.
Cost at team scale. Three lines move independently: the token rate, the thinking level and the volume of retries. The rate is $1.50 and $9.00, with cache at $0.15 and batch at half rate. The thinking level decides how many output tokens a task spends, and output includes reasoning. The retry line is the one teams forget: a model that over-calls tools produces failed runs that are billed, and two practitioners on the launch thread reported exactly that. A team with no thinking-level policy and no retry budget has left its largest line to individual habit.
Data and compliance. Google's Gemini API separates unpaid from paid service: content sent to the unpaid services is used to improve its products, and the paid services are not. On Google Cloud the model carries the platform's data residency, CMEK, VPC Service Controls and access transparency controls, which is a materially easier position for a regulated buyer than the consumer surfaces. A team that standardises on this model should pin the surface as well as the model id, because the two surfaces now behave differently.
U365 for companies. Professional learners reach University 365's academic services individually or through their organisation, and the company route runs through a customized training agreement for employee groups. Corporate education programmes are built on demand, and their tuition follows content and duration.
Skill level required: Intermediate. Driving this model well means choosing a thinking level deliberately, bounding the task so the answer can be checked, and knowing which surface you are on. The model will run without any of that, and the result will look finished either way.
Prerequisites. For the app and Search: a Google account, with the model reached through automatic routing rather than a model picker. For the API: a Google Cloud project with the Agent Platform API enabled, or a Gemini API key while the ID still routes. Working knowledge of prompt structure, tool schemas and verification practice, because output at this level reads as complete whether or not it is.
Typical time to first result: Under two minutes in the Gemini app or Search. Under fifteen minutes on Google Cloud for a first call against gemini-3.5-flash at the default MEDIUM thinking level.
Typical time to competence: Ten to twenty hours of active use. Three habits carry most of the value: thinking-level selection, because HIGH can turn a fast model into a slow one; context discipline, because retrieval degrades long before the million-token window is full; and verification design, because the model's fluency is the risk.
Who should wait. Anyone starting a new integration today. The successor is cheaper, current, and the model an unmodified Developer API call already reaches. A team that has not yet built on this ID has no reason to start. A team already running it on Google Cloud has a reason to plan the move rather than to rush it, and the Migration Path sets out the order.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
U365 Institutes Alignment
The alignment below rates what a U365 institute could take from this model as a working instrument and as an object of study. The primary home is UIT (Technology, AI, Data Science), because agentic coding, tool-use design, thinking-level policy and evaluation reading are the competencies this model exercises, and because a model that was replaced in two months is itself a teaching object about model lifecycle. The other three readings are real and each is bounded.
UIT (Technology, AI, Data Science)
Rating. High (primary)
Why. Four competencies, each of which survives the removal of the tool. Agentic coding on a bounded task: state the finish line, name the tests, bound the paths, read the report before the diff, with the vendor's own rows at 76.2 percent on Terminal-Bench 2.1 and 55.1 on SWE-Bench Pro as the reason the exercise is real rather than a toy. Tool-use design: MCP Atlas at 83.6 percent is a multi-step workflow measurement, and the independent reports of over-calling tools make "write the tool policy, then measure the call rate" a live exercise. Thinking-level policy: the same model at MINIMAL and at HIGH is a different purchase, and the practitioners who measured 2.84 seconds and 367 seconds were measuring two different settings as much as two different models. Evaluation reading: holding a vendor table against an independent evaluator that publishes no composite for this model is a lesson in what an absent measurement means.
The limit that holds the row. The model is a service a practitioner operates, not an artefact a practitioner inspects. There are no weights, no parameter count and no architecture description beyond "based on Gemini 3 Flash". The lifecycle lesson is real but comes at the cost of the investment: the competencies transfer, the specific behaviour does not. The catalogue's AI-agent instruction is concentrated in the n8n certificate series and the Superhuman certifications rather than spread across the degree paths: 0 of the 20 degree programmes carry agent, agentic or prompt in title or description. No published programme assesses thinking-level policy or model lifecycle as a named component either: thinking level returns 0 of the 81 published programmes, deprecat returns 0, and lifecycle returns 1, Product Management Consultant, where the phrase is a product's lifecycle rather than a model's. Adjacent anchors, not assessment homes.
UIB (Business Management, Entrepreneurship)
Rating. Medium
Why. Three decisions the release forces that are commercial before they are technical. Pricing a capability step: the tier moved from $0.50 and $3.00 to $1.50 and $9.00, and a business case that reads only the rate card misses that the benchmark-run cost rose from $278.26 to $1,551.60 against the predecessor on the independent suite. That gap is a live exercise a cohort can run on published figures. Procurement risk: a model replaced on the developer surface in two months and retired on the cloud surface in twelve is a supplier-concentration question, and the answer is a migration budget rather than a cheaper seat. And routing: the same ID buys different things on different surfaces, which is an asset-register problem before it is an engineering one. A workflow that models the token line and not the re-qualification line will approve a process that loses money in its second year.
The limit that holds the row. The model supplies no management method and does not measure its own return. It publishes no completion rate and no time-per-task figure outside the vendor's benchmark selection. No published U365 programme assesses model lifecycle, supplier concentration or the cost of a completed task as a named component: across the 81 published programmes lifecycle returns 1, Product Management Consultant, a product's lifecycle; procurement, supplier, portfolio, cost, price, benchmark, token and model selection each return 0. Adjacent anchors, not assessment homes.
UIC (Digital Communication, Marketing)
Rating. Low to Medium
Why. The multimodal reading surface is the strongest non-technical case. A million-token window holds a campaign archive, a brand guide, a set of screenshots and a folder of video, and 84.2 percent on CharXiv and 83.6 on MMMU-Pro describe a model that can read a chart and a layout rather than only a paragraph. The launch materials lean on presentation work: interactive animations for a research paper, a full branding concept for a school fundraiser, four checkout-flow UX approaches in sixty seconds. Those are vendor demonstrations rather than measurements, and they are the clearest statement of what the vendor believes the model is for. The second competency is reading a launch claim against the record: this launch led with a cost comparison against frontier models while tripling the price of the tier it replaced, and the thread that followed is the correction.
The limit that holds the row. The model teaches no register, no audience analysis and no publication standard. It returns no sourced evidence of its own, so fact-checking stays with the writer, and nothing in it assesses a layout or a campaign. Its knowledge stops in January 2025. Rated as a drafting and source-reading surface. No credential is mapped.
UID (Digital Design, UX/UI)
Rating. Low to Medium
Why. The production use is design-to-code: the vendor demonstrates a checkout flow rendered as several UX approaches in a minute, interactive hardware from a text description, and animations for a paper, all as HTML and code rather than as images, so a design student can produce variants fast enough that comparison becomes the work. The judgement stays with the student, because the model will produce something that looks like a design and cannot tell you whether it is a good one. One reading contact sits beside the production use: visual understanding, measured at 84.2 on CharXiv without tools, which is a real competence for reading a chart or a screenshot and turning it into a specification.
The limit that holds the row. The model generates no images and evaluates no design against a brief. It reads images and produces text and code, so the visual surface is input plus code output, and a student who wants a critique of a layout is asking for a judgement the model cannot ground. Rated as presentation and code-generation support. No credential is mapped.
U365 methods, not an institute (UNOP, ULM, LIPS, CARE and the UP-Context-Engineering Method)
Rating. Applicable
Why. The methods layer is relevant in the way a fast, disposable model is. Thinking level is a planning decision before it is a settings decision, and the UP-Context-Engineering Method's context-role-task-constraints-output order is what makes a run reproducible when the same prompt can be run at four settings. The constraints part matters more here than usual, because a documented early stop and a hard output ceiling decide whether a run spends its budget usefully. For LIPS and CARE, the record of what was asked, at which thinking level, and what was verified belongs in the Collect and Review phases, because the model holds no state on your behalf beyond the session and the model itself has a shelf life. UNOP has no direct fit: the model is not built to teach, it claims no teaching mode, and its Skill sub-score of 3 records that a user learns less by working with it.
The limit that holds the row. The model carries no method of its own and no coaching surface. A Fellow who does not write the thinking decision and the verification result into their own system has no account of them, and nothing in the product writes that account.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
How Gemini 3.5 Flash Works
A reasoning model built on the Gemini 3 Flash foundation, with four thinking levels that decide how much it thinks, a million-token input window with a 64K output ceiling, multimodal input, and a price high enough that the thinking level rather than the seat count is the budget decision.
Inputs: Text prompts, documents, images, audio and video, up to 1,048,576 tokens in total; through the API, a conversation history, tool definitions, and on Google Cloud the grounding sources a request names. Through the app and Search, whatever the surface chooses to pass. The model reads text, images, audio and video and produces text.
Outputs: Text, code, structured tool calls and, through agent surfaces, edits to files and actions in a browser or on a desktop. Up to 65,536 tokens in a single response, inside a context window of 1,048,576 tokens, with reasoning tokens billed as output. Independent measurement records 167 output tokens per second and 11.65 seconds to first answer token.
Underlying technology, as the vendor publishes it:
Model: Gemini 3.5 Flash, model id gemini-3.5-flash, released 2026-05-19. Built on the Gemini 3 Flash reasoning foundation, per the model card.
Thinking levels: MINIMAL, LOW, MEDIUM and HIGH, with MEDIUM as the default. The vendor describes the levels as controlling the mix of quality, cost and latency.
Context and output: 1,048,576 tokens in, 65,536 out, stated as 64K on the model card. Knowledge cutoff January 2025.
Multimodal input: text, image, audio and video. Text output only.
Price: $1.50 and $9.00 per million tokens, cache at $0.15, batch at half rate, provisioned throughput at 1.8 times the standard rate.
Safety: frontier safety assessment states no critical capability levels, and additional cyber testing found the model below the cyber CCL. Internal safety evaluations against Gemini 3 Flash show a 3.9 percent regression on text-to-text safety, a 2.6 percent regression on multilingual safety, no change on image-to-text safety, an 8.9 percent improvement on tone and a 0.8 percent increase in unjustified refusals.
Tools: function calling, structured output, code execution, URL context, Google Search and Parallel Web Search grounding, and computer use from 2026-06-24.
Fine-tuning: supervised, continuous, reinforcement-learning fine-tuning and tuning checkpoints, on the Cloud surface.
Consumption: batch, flex, priority, standard pay-as-you-go with usage tiers, and provisioned throughput.
What is not disclosed. No parameter count. No weights. No architecture description beyond the reference to Gemini 3 Flash. No per-level token budget, because the level is a named position rather than a number. No statement that would let a buyer audit what the model does internally. One reader on the launch thread, easygenes, published an estimate of roughly 250 to 300 billion total parameters and 10 to 16 billion active, inferred from TPU 8i serving constraints; it is an informed estimate and not a disclosure, and this review does not score it.
The thinking ladder is the product, and the levels are not interchangeable. At MINIMAL the model answers fast and spends almost nothing on reasoning. At HIGH it can spend more on thinking than the answer is worth, and two practitioners measured exactly that against the previous Pro model. One practitioner reported that the release notes advise reducing unnecessary tool calls by reducing thinking (data-ottawa), which is consistent with thinking and tool use being coupled rather than independent dials.
The long-context behaviour is a cliff, not a slope. MRCR v2, the vendor's own needle-in-a-haystack measure, reads 77.3 percent at 128k and 26.6 percent at 1M. The window is real, the retrieval is not uniform, and a workflow that fills it will get confident answers from the wrong part of the document. The design rule that follows is to keep the needle inside the first 128k tokens or to retrieve before prompting.
What the model is bad at natively. Instruction following under a long system prompt, where two practitioners reported tool calls it had been told not to make. Sycophancy and enthusiasm, where one reader described output full of exclamation marks and "Everything is in perfect order!" while the code did not work. And grading, where a reproducible failure makes the model compress a rubric toward the middle of the scale and return 7 out of 10 for a correct answer, which Section 7c records as a finding rather than an anecdote.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Getting Started with Gemini 3.5 Flash
Required accounts: A Google Cloud project with billing and the Agent Platform API enabled for the Cloud surface. A Google account for the consumer surfaces, where the model is reached by automatic routing rather than by a model picker. A Gemini API key only if the ID still routes on the Developer API, which is the first thing to test.
Installation: Nothing to install for the app or Search. For Google Cloud, the Google Gen AI SDK or an HTTP client against the regional or global endpoint, with the model selected by the id gemini-3.5-flash. For the API, nothing beyond an HTTP client or an official SDK.
First-time configuration:
Test which model your call actually reaches before you build anything. On the Developer API, requests to gemini-3.5-flash route to gemini-3.6-flash. Ask the endpoint to identify itself, or compare a known output against both models, and write the answer down. A pipeline that logs only the status code will attribute the successor's output to this model indefinitely.
Choose the thinking level by task, before the first prompt. Four positions, with MEDIUM as the default. MINIMAL for classification, extraction and routing; LOW or MEDIUM for bounded code and document work; HIGH only where a measured failure at MEDIUM justifies it, because the output price includes the thinking tokens.
Keep the material inside the first 128k tokens, or retrieve before you prompt. The vendor's own long-context row falls from 77.3 percent at 128k to 26.6 percent at 1M. A million-token prompt is a supported request, not a supported workflow.
Set a maximum output length and a stop condition. The ceiling is 65,536 tokens, reasoning included. A run that is allowed to think to the ceiling spends the budget before it writes the answer.
Write the tool policy before the agent run. A short instruction file that names the tools in scope, the tools that are out of scope, the files the agent may touch and the finish line. Two practitioners reported tool calls outside the instruction, and a policy that is written down is the only way to measure the call rate afterwards.
Decide the data boundary at the account level. Paid Google Cloud service for anything confidential, with residency, CMEK and VPC Service Controls configured; the free consumer surfaces for public or disposable material.
Put the first task on a surface where you already own the check. A test suite, a schema validator, a quote table, a chart you can re-read by hand.
First 15 minutes checklist:
☐ Confirm which model your endpoint returns, and write the answer into the run log.
☐ Run one real task at MEDIUM with a stated finish line and a stated stopping rule.
☐ Run the same task at MINIMAL and at HIGH, and compare the answer, the wait and the token count. Write the three costs down.
☐ Take one factual claim from the answer and check it against a source outside the conversation, knowing the cutoff is January 2025.
☐ Count the tool calls the run made and compare them with the tool policy you wrote.
☐ State, in one sentence you could repeat to a colleague, which task you would keep on this model and which you would move to its successor.
Result: One real task completed end to end, a thinking level chosen with its cost known, a routing fact recorded, and a tool-call count you can defend. That is a working setup rather than an impression.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Real Workflows
Three workflows, each chosen because the model's measured strength and a check the reader already owns sit in the same place. The first is the work the vendor sold it on. The second is the work its window makes possible and its retrieval makes risky. The third is the work it fails at quietly, which is why it is in the review at all.
Workflow 1: Repair a failing test suite without rewriting the file
Learner type: Professional (career upskilling). Developer, technical lead or platform engineer. CI-First benefit tags: Time, Quantity, Quality. Connects to: UIT (Technology, AI, Data Science) engineering tracks. Time estimate: Twenty to sixty minutes for a bounded fix plus the review time you would have spent anyway.
What you do vs what the tool does:
Step | You do | The tool does |
1 | Write or name the failing test, and state what done means. | (Nothing yet) |
2 | Put the rulebook, the test and the scope in the working directory the agent reads. | Reads the repository, plans the change and runs the test it has been given. |
3 | Choose the thinking level before the run starts, and decide what the agent may not touch. | Works through the fix at that level, batching tool calls where it can. |
4 | Read the report before the diff. | Returns what it changed, what it found and what it needs from you. |
5 | Run the full suite and the linter yourself. | (Nothing. You verify.) |
6 | Read the diff. If it is too large to read, the task was too large. | (Nothing. You decide.) |
Sample prompt (UP-Context-Engineering method: context, task, constraints, output format):
Context: this repository is [project]. The defect is [the behaviour]. The failing test is
[test name or command]. Done means that test passes and no other test changes state.
I am running this at thinking level [MEDIUM or HIGH] and I chose it because [reason].
Role: AI as a Co-Worker and Assistant for the fix. I hold the decision to merge.
Profile: Act as a Co-Worker and Assistant, keeping the change bounded and evidenced.
Task: make the failing test pass without changing behaviour outside the defect.
Constraints: one module at a time. Do not edit [protected paths]. Do not add dependencies.
Do not refactor code the defect does not touch. Use only these tools: [list]. Do not call
[tools out of scope]. If you cannot finish, say what remains rather than reporting the change
as complete.
Output format: a short table with file, change, and the evidence you used. Then three headings:
Blocked on me, Changed, Found. State plainly anything you did not verify, and list anything in
the request you skipped.
Memory: the change table and the evidence I accepted belong in my repository record. If the
surface writes its own notes, treat them as the tool's working state and not as the record.
UP-Context-Engineering verification: I read the report before the diff, I run the suite myself,
and I can defend every change without the tool.
Data safety: this pack carries no personal data. I do not paste credentials, customer data or an
unreleased repository into it, and I keep the change record in version control.
Cost note: A bounded fix at MEDIUM is the setting this model is priced for, and the price is the problem. At $1.50 per million input tokens and $9.00 per million output, with cache reads at $0.15, a repository context that is re-read across turns is affordable but not cheap, and reasoning tokens are billed at the output rate. The independent comparison that matters is not per token: running the full Artificial Analysis suite cost $1,551.60 for this model at high against $892.28 for Gemini 3.1 Pro Preview, because it spent more tokens. Budget on tokens per finished task, not on the rate card, and set HIGH only where MEDIUM has demonstrably failed.
Verification checklist:
☐ Multi-Model Check: run the same defect on Gemini 3.6 Flash or Claude Sonnet 5.5 at their default settings and compare what each found. A difference in what the models noticed is more informative than a difference in prose.
☐ External Source: run the project's own test suite, linter and static analysis. Do not accept the model's statement that the test passes.
☐ Human Review: read the diff. If it is too large to read, the task was too large.
☐ Report-to-Specification Check: compare the report against the request line by line, because a run can complete half the specification and describe the half it did.
☐ CI-First Test: can you explain and defend the change without the model? If not, it is not ready.
Workflow 2: Reduce a document set to a table you can defend
Learner type: Professional. Analyst, operations lead or research assistant. CI-First benefit tags: Time, Quality. Connects to: UIC (Digital Communication, Marketing), UIB (Business Management, Entrepreneurship) and UIT for the extraction design. Time estimate: One to three hours for a first table over twenty to forty documents, plus the check time you would have spent anyway.
What you do vs what the tool does:
Step | You do | The tool does |
1 | Name the decision the table informs, the columns, and the unit each column is in. | (Nothing yet) |
2 | Select the documents and put the most decision-relevant ones first in the prompt. | Reads the set in one window, images and charts included. |
3 | Keep the set inside the first 128k tokens, or retrieve and prompt in batches. | Answers from the material it was given, with a citation when asked. |
4 | Spot-check two rows per document against the page. | (Nothing. You verify.) |
5 | Ask it to name what the set does not contain, and treat silence as a finding to test. | Returns an explicit gap list on request. |
6 | Rewrite the conclusion in your own words. | (Nothing. This step is yours.) |
Sample prompt (UP-Context-Engineering method):
Context: the attached set is [description, number of documents, period]. The table informs
[decision]. Done means every cell can be traced to a document and a page, and any cell that
cannot be filled is empty rather than plausible.
Role: AI as a Co-Researcher and Analyst on a first pass. I hold the conclusion.
Profile: Act as a Co-Researcher, separating what the documents say from what you infer.
Task: fill the table from the attached documents only.
Constraints: cite document and page for every cell. Do not reconcile figures that disagree;
report the disagreement in a separate column. Do not use knowledge from before or after the
documents. Do not summarise a document you were not given. Keep the set inside the first part
of the context where you can, and say which documents you read last.
Output format: a table with the named columns, a citation column, and a confidence column of
high, medium or low. Then a section headed What the set does not contain, and a section headed
Where the sources disagree.
Memory disclosure: keep the document set and the column list for this session only. Do not retain the documents, and do not write a summary of them outside this conversation.
UP-Context-Engineering verification: I open the cited page for every cell I will act on, I
rewrite the conclusion myself, and I can defend each row without reopening the session.
Data safety: this pack is [classification]. Personal data is minimised, and the table stays in
the matter file rather than in the conversation.
Cost note: The window is the reason to use this model and the reason to be careful. A million tokens of input at $1.50 is $1.50, which is cheap; the cost arrives in the output, at $9.00 per million with reasoning included, and in the retries a bad extraction causes. Cache reads at $0.15 make a repeated document set affordable across a day of work, which is the one place this model's economics still look like a Flash model's. Keep the set inside 128k where the vendor's own retrieval row reads 77.3 percent, and treat a prompt that fills the window as a request you have not yet designed.
Verification checklist:
☐ Multi-Model Check: re-extract two rows with a second model and compare. A disagreement is a cell to check by hand.
☐ External Source: open the cited page for every cell you will act on and confirm the number is there. A citation that resolves to the wrong page is worse than no citation.
☐ Human Review: have the person who owns the decision read the table and the uncertainty list together, not the table alone.
☐ Position Check: confirm which documents sat beyond the first 128k tokens, and re-check those rows first, because the vendor's own long-context row falls from 77.3 percent to 26.6 between 128k and 1M.
☐ CI-First Test: can you defend each row without reopening the model session? If a row depends on the transcript, it is not a finding yet.
Workflow 3: Build a rubric grader, and test the grader before you trust it
Learner type: Professional. Educator, evaluation lead or operations manager scoring free-text answers at volume. CI-First benefit tags: Time, Quantity. Connects to: UIT (Technology, AI, Data Science) for evaluation design, and UIB for the cost case. Time estimate: Two hours to build the rubric and the control set, then minutes per batch.
What you do vs what the tool does:
Step | You do | The tool does |
1 | Write the rubric, the scale and the anchors for each point on the scale. | (Nothing yet) |
2 | Build a control set of twenty answers with scores you already know, including three perfect answers. | (Nothing yet) |
3 | Run the control set at MINIMAL and at MEDIUM and compare against your scores. | Applies the rubric and returns a score with a rationale. |
4 | Check whether a perfect answer receives the top of the scale. | (Nothing. This is the test the model fails.) |
5 | If the scale compresses, remove the rubric text from the prompt and score against named criteria instead, then re-run the control set. | Applies the named criteria without a scale to compress. |
6 | Route every score at the top and bottom of the scale to a person. | (Nothing. You decide.) |
Sample prompt (UP-Context-Engineering method):
Context: I am scoring [number] answers to [task]. The criteria are [three to five named
criteria]. The scale is 0 to 10 with anchors at 0, 5 and 10. I have already scored a control
set of twenty answers and I will compare your scores with mine before I use any of them.
Role: AI as a Co-Worker applying a stated rubric, with no authority to reinterpret it.
Profile: Act as a careful grader, not as a coach and not as an editor.
Task: score each answer against each criterion, then give one total.
Constraints: quote the sentence that satisfies or misses each criterion. Do not reward length,
confidence or politeness. If an answer satisfies every criterion, give the top of the scale;
do not compress the scale toward the middle. If the rubric is ambiguous for an answer, say so
and mark the score as provisional rather than choosing a middle value.
Output format: a table with answer id, score per criterion, total, and the quoted evidence.
Then a list of provisional scores with the ambiguity named.
Memory disclosure: keep the rubric, the anchors and the control scores for this session only. Do not retain the answer texts and do not write a standing note about how I grade.
UP-Context-Engineering verification: I run the control set first, I compare your scores with
mine, and I read every answer that scores at either end of the scale.
Data safety: this pack carries [classification]. Answers are anonymised before they are pasted,
and the score record stays in the assessment file.
Cost note: Grading is an output-token business, and this model bills reasoning as output. At MINIMAL a score costs almost nothing; at HIGH the rationale can cost more than the answer being graded. Run the control set at MINIMAL first, because the failure this workflow guards against is not a shortage of thinking, and a cheaper setting that produces the same score on twenty known answers is the correct production setting.
Verification checklist:
☐ Multi-Model Check: score the control set with a second model and compare the disagreements, not the averages.
☐ External Source: your own hand-scored control set, including at least three answers that should receive the top of the scale and three that should receive the bottom.
☐ Human Review: a person reads every score at either end of the scale and a sample from the middle.
☐ Scale Check: confirm that a perfect answer receives the top of the scale. If it receives 7 out of 10, the rubric is being compressed and the scores are not usable.
☐ CI-First Test: could you explain to the person being graded how their score was produced, without the transcript? If not, the grader is not ready.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | Fast at the settings most work uses, with a genuine agentic step over its predecessor. | Vendor: Terminal-Bench 2.1 at 76.2 percent against 58.0 for Gemini 3 Flash, SWE-Bench Pro at 55.1 against 49.6, and output at four times the tokens per second of other frontier models. Independent: 11.65 seconds to first answer token and 167 output tokens per second, faster than the current 3.8 Flash on both measures, and one latency benchmark at 2.84 seconds average at its low setting. Held at 6 by the two production reports of 10 to 15 percent slower and 367 seconds against 142 on an agentic SQL benchmark, both caused by thinking volume. |
Quantity | More finished units of work per day through window, modalities and consumption options. | A 1,048,576-token window, a 65,536-token output ceiling, text, image, audio and video input, batch and flex and priority consumption, provisioned throughput, and context caching at a 90 percent discount. Held at 6 by the $9.00 output rate, which prices volume twice: once per token and again in the tokens a high thinking level spends. |
Quality | A strong multimodal reader and a capable agentic coder for its generation. | Vendor: CharXiv 84.2 without tools, MMMU-Pro 83.6, MCP Atlas 83.6, OSWorld-Verified 78.4, GDPval-AA 1656 Elo, ARC-AGI-2 72.1, Humanity's Last Exam 40.2. Independent: quality reported as a wash with Gemini 3 Flash Preview across 144 runs, below Gemini 3.1 Pro in two production workloads, and no Intelligence Index published for the model at review time. Held at 6 by that mixed record and by the absence of a current composite. |
Skill | Marginal, and scored conservatively at 3. | No teaching mode is claimed. The thinking ladder is a real skill surface, because choosing it is a judgement the user has to make, but nothing in the product teaches that judgement. The model is retired, so the behaviour a user learns is behaviour they will have to relearn on the successor. |
Limits
The tier's price tripled and the value did not. $1.50 and $9.00 against $0.50 and $3.00 for the model it replaced, and within two months of Gemini 3.1 Pro's $2.00 and $12.00. The launch thread's dominant complaint was the price, not the capability.
Cost per task rose above the previous Pro. The full Artificial Analysis suite cost $1,551.60 at high, against $892.28 for Gemini 3.1 Pro Preview, $278.26 for Gemini 3 Flash Preview and $93.60 for Gemini 3.1 Flash-Lite Preview, because the model spent far more tokens.
The speed advantage is a setting, not a property. Two practitioners reported it slower than Gemini 3.1 Pro in production because it thinks 2.5 times as much, and one measured an agentic SQL benchmark at 367 seconds against 142 for the cheaper model.
Retrieval collapses long before the window fills. MRCR v2 at 77.3 percent on 128k and 26.6 percent at 1M, on the vendor's own table.
The knowledge cutoff is January 2025, fourteen months before release, which makes grounding mandatory for anything time-sensitive.
Instruction following under a long system prompt is unreliable. Two practitioners reported tool calls the model had been told not to make, and one noted the release notes' own advice to reduce thinking to reduce tool calls.
Grading collapses on a rubric. A reproducible case returns 7 out of 10 for an answer that meets every stated criterion, with the rationale "compressed toward the center of the scale per the evaluation constraints". Section 7c records it.
Sycophancy and enthusiasm are in the record. One reader reported exclamation marks everywhere and "Everything is in perfect order!" while the generated code did not work.
The model was replaced on the Developer API two months after launch, and the ID now routes to Gemini 3.6 Flash. Its own successor's Cloud retirement date, 2026-11-19, falls five days after this review.
No open weights, no self-hosting and no external auditability. Nothing about this model can be inspected from outside Google's service.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The speed is real at MINIMAL and MEDIUM, and one independent benchmark measured 2.84 seconds average at the low setting against 33 seconds for GPT-5.5. The overhead is real as well: a thinking decision on every job, four settings whose cost and latency differ by an order of magnitude, a long-context cliff that turns a big prompt into a slow wrong answer, and a migration the buyer did not plan for. The saving is real where the setting is low and the task is bounded, and it disappears where the setting is high. |
Quantity Illusion | Medium | The volume is the offer: a million-token window, batch and flex consumption, and agent stacks that run subagents in parallel. Nothing separates a complete table from a plausible one for a reader who does not know the source set, and the vendor's own long-context row shows the model reading far less of a large prompt than the window implies. |
Skill Illusion | High | Expert-form code, tables and scores produced for users who cannot evaluate them, by the default model behind the Gemini app and AI Mode in Search for billions of people, with a dial labelled HIGH that reads as a quality setting. The grading failure is the clearest case: a rubric grader that returns 7 out of 10 for a perfect answer looks like a considered judgement, and a reader who never tests it will use it. Mitigations are stated below and none of them moves the capability to the reader. |
Overall Imposture Risk: Medium. One trap is High with clear mitigations stated, and two are Medium. Under the framework's arithmetic, one High with clear mitigations stated is Medium rather than High, and the band-precedence sentence does not change that outcome because the other two traps are Medium rather than High. The rating holds for a specific reason: the speed and multimodal quality argue downward, while the default-model distribution, the thinking dial and the grading collapse argue upward at the same time.
The mitigations, stated clearly, because the band condition requires them. First, the thinking level can be fixed by policy rather than left to habit: MINIMAL for extraction and grading, MEDIUM for bounded code, HIGH only after a measured failure. Second, every workflow in this review carries a check that does not depend on the model's account of itself, and two of the three are mechanical: a test suite and a hand-scored control set. Third, the routing can be verified once and logged, so a caller knows which model answered. Fourth, the long-context cliff is documented by the vendor and can be designed around. Fifth, the model's retirement is published, which makes the migration a scheduled task rather than a surprise. These lower the frequency and the cost of failure. They do not transfer capability, which is why the Skill sub-score is 3.
Framework v1.2 clause note
Clause 5.2.3-a, agent-authored procedural memory: NULL, recorded with its boundary. The clause sets a Skill Illusion floor of no lower than Medium where a tool writes procedural memory, skills or standing instructions on the user's behalf, during use, by default. Gemini 3.5 Flash does not document a mechanism of that kind. It is a stateless model endpoint: no skills are written, no memory store is maintained by the model, and the surfaces that keep context on a user's behalf, such as the app's saved information, are product features that a person chooses to use rather than a model writing its own procedure. The live condition is the Gemini Spark agent announced at launch, which runs continuously and acts on the user's behalf under their direction. If that agent begins writing standing instructions or reusable procedures that the user did not author, this clause re-opens.
Clause 4.2-a, agent-mediated conversation: NULL as a generator, with the live condition recorded. Neither erosion condition is met by the model itself. No agent-authored text is presented as the person's own voice in a human-facing channel by default, and nothing substitutes agent interaction for human contact. The live condition is a deployment property rather than a model property: an application built on this model that sends text in a person's own name, or an agent that acts in their accounts without them reading each action, would move this dimension. The computer-use addition of 2026-06-24 makes that arrangement easier to build, which is why the condition is recorded rather than dismissed.
Clause 7.5: removed by framework v1.4, not assessed. The subsection was removed on 2026-10-13 and no part of this review reaches its case. It is recorded here so that a reader comparing this review with an older one knows why the clause is absent rather than unanswered.
Why the clause note does not carry the whole Skill finding. The Skill Illusion is High for a reason that no clause mechanism supplies: the model produces expert-form output on tasks whose correctness the reader often cannot check, and it was the default behind a search box used by billions of people who did not choose it. The clause questions return nulls. A reader who confirmed both nulls would still face the distribution and the fluency.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Section 7c: What the model ID buys today, the computer-use surface and the routing that moved, stated plainly
A Section 7c finding is recorded where a supplier's governance, lifecycle or conduct has a real result for the reader. The items below were checked against primary sources, and they produce findings a buyer should carry. All findings are stated as facts of record, and the difference between a company statement, a published date and a product behaviour is kept intact.
The same model id now means two different things on two Google surfaces. The Gemini API deprecation table lists gemini-3.5-flash with a release date of May 19, 2026, a shutdown date of N/A, and a note that reads: the model "is no longer available in Google AI Studio; the endpoint is not shutting down and automatically routes API requests to gemini-3.6-flash". The Google Cloud model page, read on the same day, lists the same id as generally available, with a launch stage of GA, a release date of May 19, 2026 and a retirement date of "May 19, 2027 or later". Neither page is wrong. A developer calling the Developer API is calling the successor and being billed for something, and a developer calling Google Cloud is calling this model. A pipeline that logs only the HTTP status will record the first case as a success of the model it named.
The deprecation note states the route and not the rate, and the difference from an older note is worth recording. For gemini-2.5-flash, the same page states that requests "will automatically route to gemini-3.5-flash-lite and be billed at Gemini 3.5 Flash-Lite rates". For gemini-3.5-flash the note ends at the route. This review does not assert which rate applies, because the vendor does not state it, and a reader costing a workload should confirm it against a bill rather than a documentation page.
Inside the same vendor, the older model has the longer support window. The Cloud model pages, read on 2026-11-14, give these dates: gemini-3.5-flash retires on May 19, 2027 or later; gemini-3.6-flash, released 2026-07-21, retires on 2026-11-19; gemini-3.7-flash, released 2026-08-13, retires on 2027-01-28; gemini-3.8-flash, released 2026-09-02, retires on 2027-09-02 or later. The successor that the Developer API routes to is five days from its own Cloud retirement date at the time of this review. That is not a reason to stay on the older model, and it is the one fact that makes the older model's Cloud deployment defensible for another year: a team that has qualified this model has a published runway, where a team that moves to the successor will re-qualify again inside six months.
Computer use was not in the launch, and arrived a month later with a safeguard story. At launch the model had no computer-use tool, and a reader on the launch thread flagged the omission as the thing his team used the previous Flash for. Google added computer use to Gemini 3.5 Flash on 2026-06-24 as a built-in tool, describing it as the first time the capability was integrated into the main Flash model rather than shipped as a standalone model, with targeted adversarial training to mitigate prompt injection for agents operating in live environments, and two optional enterprise safeguard systems. The Cloud model page now lists computer use as supported. A reader adopting the model for browser or desktop agents is adopting that surface and its threat model, and the vendor's own framing is that prompt injection is the risk being mitigated.
The safety record improved on tone and regressed on content safety, and the vendor published both. The model card reports the internal evaluations against Gemini 3 Flash as an absolute percentage change: 3.9 percent lower on text-to-text safety, 2.6 percent lower on multilingual safety, unchanged on image-to-text safety, 8.9 percent better on tone, and a 0.8 percent increase in unjustified refusals that the card calls non-egregious. On frontier safety, the card states that Gemini 3.1 Pro was assessed as the most capable model at publication and reached no critical capability levels, that 3.5 Flash shows no meaningful new capabilities against it, and that additional cyber testing found the model below the cyber CCL. A reader who wants the safety position of this model should take both halves: no new critical capability, and a measured regression on content safety that the vendor chose to publish.
The model became the default answer for billions of people on the day it shipped. The launch post states that 3.5 Flash was the default model for the Gemini app and for AI Mode in Search globally, and that Gemini Spark, a personal agent that runs continuously and acts on the user's behalf, runs on it. That is a distribution fact and it is the fact that matters most for the Skill Illusion: the population consuming this model's fluency is not the population that chose it, and the dial that would change its behaviour is not in front of them.
The grading collapse is a finding, not an anecdote, because it reproduced on the first attempt. A reader published a case in which the model scored answers against a rubric and returned 7 out of 10 for an answer that met every stated criterion, with the rationale that the rating had been "compressed toward the center of the scale per the evaluation constraints". Another reader reproduced it in the Gemini app on the first try. The behaviour is not documented by the vendor, it is not measurable from the published benchmarks, and it lands directly on the workflow a large share of professional users would build first, which is automated grading at volume. This review treats it as a named limit and carries it into Workflow 3.
No sub-score changed for these findings, and the reason is explicit. The Time sub-score already carries the routing and the thinking-level overhead, because a route check and a level decision are steps before the work rather than part of it. The Quality sub-score already carries the model's measured position, including the absence of a current independent composite. The Skill sub-score already carries the distribution and the fluency, which is where the Skill Illusion lands. The items above concern lifecycle, access structure and a published safety record rather than a defect in the artefact a buyer receives, and none of them is a resolved safety failure. Section 7c closes with what it does not do: it does not allege misconduct, it does not treat a published regression or a retirement date as a scandal, and it does not convert a company's own caveats into findings against it. It records what a reader adopting this model is also adopting: a routing rule that decides which model answers, a support window that is longer than its successor's, and a computer-use surface that did not exist at launch.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (level 2). Secondary profiles: Co-Researcher, Analyst and Tester (level 4).
Why this profile. Google's positioning does the reasoning. The launch sells 3.5 Flash for "agentic workflows, coding tasks, and multi-week enterprise processes", with demonstrations of subagents transforming a codebase and running builder and player loops, and the surfaces that made it matter most were the Gemini app and AI Mode in Search, where it answered as an assistant. That is an execution framing: name the task, hand it over, review what returns. Co-Worker and Assistant (level 2) is the role the model plays for the person using it. Co-Researcher, Analyst and Tester (level 4) is recorded as secondary because the million-token multimodal window and the 84.2 on CharXiv make first-pass document and chart work genuine, and because a cheap model with a long window is a natural checker beside a stronger one. The primary stays at level 2 because the price, the agent orchestration and the app distribution all point the same way.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 6 | A real speed case at the bottom of the thinking ladder: 11.65 seconds to first answer token and 167 output tokens per second on independent measurement, faster than the current 3.8 Flash on both, and 2.84 seconds average on one latency benchmark at the low setting. Held at 6 by two production reports of 10 to 15 percent slower than Gemini 3.1 Pro because it thinks about 2.5 times as much, and by a 367-second agentic SQL run against 142 seconds for a cheaper model. |
Quantity | 6 | A genuine multiplier on breadth: a 1,048,576-token window, 65,536 tokens of output, text, image, audio and video input, batch and flex consumption, provisioned throughput and caching at 90 percent off the input rate. Held at 6 because the output rate is $9.00 per million with reasoning included, which prices volume twice, and because the vendor's own long-context row shows the window delivering far less than it promises at the top. |
Quality | 6 | Strong for its generation on the vendor's table: 76.2 percent on Terminal-Bench 2.1, 83.6 on MCP Atlas, 84.2 on CharXiv, 83.6 on MMMU-Pro, 78.4 on OSWorld-Verified. Held at 6 rather than 7 by the independent record, which reports quality as a wash with the cheaper predecessor across 144 runs and below Gemini 3.1 Pro in two production workloads, and by the absence of any published Intelligence Index for the model at review time. |
Skill | 3 | Execution rather than learning, scored conservatively. Nothing in the product teaches thinking-level judgement or verification, and the thinking ladder is a decision the user must make without help. The retirement compounds it: the behaviour a user learns here is behaviour they will relearn on a successor, so the learning is worth less than it would be on a model with a live future. |
CI-First Benefit Score: 5.3 / 10 (CI-First Positive)
Why the score sits where it sits
5.3 with sub-scores 6 / 6 / 6 / 3 puts this model level with its own successor, Gemini 3.6 Flash at 5.3, above Gemini 3.1 Pro at 5.0, below Gemini 3.5 Flash-Lite at 5.5 in the same family, and well below Gemini 3.8 Flash at 7.0 and Gemini 4 Hydrogen at 6.3. That ordering needs explaining, because a reader will ask why a retired model scores level with the model that replaced it.
Why not higher. Four reasons, each measured. The quality record is mixed and no current independent composite exists, so the Quality dimension cannot claim more than 6 on evidence a reader can check today. The long-context row falls from 77.3 percent at 128k to 26.6 percent at 1M, which caps what the window is worth. The economics failed the launch: at $1,551.60 to run the independent suite against $892.28 for the previous Pro, the model cost more per task than the model it was supposed to undercut. And the Skill sub-score is 3 because the model executes rather than teaches and is already retired.
Why not lower. The instrument is genuinely good for its generation. On the vendor's own table it beats Gemini 3.1 Pro on Terminal-Bench 2.1, MCP Atlas, OSWorld-Verified, Finance Agent v2, GDPval-AA and CharXiv, and it beats Gemini 3 Flash on every row reported. It is faster than the current 3.8 Flash at the same measured settings, at 167 tokens per second against 114. It reads charts, screenshots, audio and video in one window. And it is still a supported GA model on Google Cloud with the longest published runway in the 3.x Flash line, which is a real deployment fact rather than a marketing one.
Why 5.3 and not a higher band, stated as arithmetic. Time 6, Quantity 6, Quality 6 and Skill 3 average to 5.25, which rounds to 5.3 and sits mid-way through the CI-First Positive band (4.1 to 6.0). A single point on any one dimension would not change the band; two would, and neither is supportable on the evidence. The score is Positive rather than Neutral because the tool does deliver net benefit to a reader already using it, and it is not Strong because the benefit is capped by the price, the retrieval cliff and the retirement.
What the score does not carry. The four dimensions measure what your work gains. They do not carry the routing between two Google surfaces, the retirement dates, the safety regressions or the default-model distribution, which is why those sit in Section 7c with an explicit statement that no sub-score changed. They do not carry the thinking-level defaults beyond the overhead already counted in Time. A reader who wants the score to encode lifecycle policy would need a different instrument, and the framework's instrument for that is the status badge and the Migration Path.
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | It drafts, designs and executes against a direction you set, and the launch materials show interactive UI, animation and branding concepts generated at speed. It does not originate the direction and it neither trains nor replaces your ideation. A model that produces four checkout-flow approaches in a minute gives you more to choose between and does not tell you which one is right, and the choice stays yours. |
Critical Thinking | Erodes (-1) | Fluent, near-frontier output for people who cannot evaluate it, delivered as the default answer in the Gemini app and AI Mode in Search for billions of users, with a thinking dial that reads as a quality setting. The grading collapse is the mechanism in miniature: a rubric score that looks considered, is internally consistent, and is wrong in a way only a control set reveals. The launch thread's reports of sycophancy and of code that did not work while the model declared everything in perfect order describe the same direction from the other side. The mitigations lower the frequency and do not reverse it. |
Social Authenticity | Neutral (0) | The model produces text rather than speaking in a person's name, and clause 4.2-a returns a null for it as a generator. The live condition stays in the record: Gemini Spark acts on a user's behalf across their digital life under their direction, and the computer-use tool lets an application act in their accounts. An agent that acts without the person reading each action would move this dimension, and this release made that arrangement easier to build. |
Humics Protection Score: -1 / +3 Badge: Humics-Neutral
Superhuman Usage Guidance
When to invite this tool:
Bounded engineering work with a checkable end state: a bug fix, a test repair, a small refactor, where a test suite decides whether the answer is right.
Multimodal reading of a set larger than you would read: charts, screenshots, scanned pages and short video, with a citation required in every cell.
A first pass over a document set that fits inside the first 128k tokens, where the retrieval is measured at 77.3 percent rather than 26.6.
High-volume attempts where the comparison is the deliverable: several drafts, several layouts, several extraction passes, at MINIMAL or LOW.
A cheap worker behind a stronger model in an orchestration, if the orchestration layer lets you pin the model and log which model answered.
A deployment already qualified on Google Cloud, where the published support window runs to May 2027 or later and the cost of re-qualification is higher than the price difference.
When to keep this tool out:
Any new integration. The successor is cheaper today, current on both surfaces, and the model an unmodified Developer API call already reaches.
Work whose correctness you cannot check yourself. The whole proposition is that the output looks finished, and it was the default behind a search box.
Automated grading, unless you have run a hand-scored control set and confirmed that a perfect answer receives the top of the scale.
Anything that depends on knowledge after January 2025, unless you supply the documents or a retrieval path.
Prompts that fill the million-token window, where the model reads far less of it than the window implies.
Agent work in a browser or on a desktop without a prompt-injection plan, because computer use is a month-old surface on this model.
The final judgement calls: what to publish, what to send to a client, what to tell a person. Those are the Humics this model does not supply.
U365 method integration:
LIPS + CARE: route the model's reading and drafting output into the Collect phase, and keep the Action Plan and Review phases as your own work. The thinking decision and the verification result belong in the record, because the model holds no state beyond the session and the model itself has a retirement date.
ULM + EVA: relevant through the cost-per-completed-task framing and the lifecycle decision, which is a planning judgement about what a task and a dependency deserve. Career and Finance are the domains where that judgement shows up first. Weak fit elsewhere.
UP-Context-Engineering: it responds to explicit context, a stated role, a task, constraints and a named output format, and the constraints part matters here because a hard output ceiling and a named tool policy decide whether a run spends its budget usefully.
UNOP: no direct fit. The model is not built to teach, and its reliability comes from speed and multimodal breadth rather than from any pedagogical mechanism.
Over-delegation warning: the failure mode with this model is quiet because the model is quiet. It answers in seconds, it reads the chart, it writes the table, and it was the default behind a search box that billions of people already trust. Nothing about a fast answer feels like over-delegation. The arithmetic is the framework's own: if your Human Intelligence input drops while the Artificial Intelligence term rises, the product falls. A reader who lets this model grade the answers, summarise the sources and draft the reply, and stops reading the output as closely as they read a colleague's, has taken the release's worst offer. The Skill sub-score of 3, the High Skill Illusion and the grading collapse in Section 7c are the framework's way of recording that the offer is real.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
What Users Say
Aggregate Rating Table
Platform | Rating | Number of reviews | Link |
Hacker News, launch thread | 962 points, positive on speed and multimodal quality, sharply negative on the price | 658 comments | |
Hacker News, computer-use follow-up | 242 points, positive on the capability and focused on latency in long GUI workflows | 167 comments | |
Hacker News, "Tell HN: Gemini 3.5 Flash breaks in stupid ways" | 9 points, a reproducible grading failure | 4 comments | |
G2 | No reviews found on G2 | Not applicable | Not applicable |
Capterra | No reviews found on Capterra | Not applicable | Not applicable |
Trustpilot | No reviews found on Trustpilot | Not applicable | Not applicable |
Product Hunt | No reviews found on Product Hunt | Not applicable | Not applicable |
Note on method, stated plainly because it affects how much this section is worth. No review platform rates an individual model endpoint, and no G2, Capterra, Trustpilot or Product Hunt listing for this model was found on 2026-11-14. The meaningful signals are the launch thread, where practitioners posted measured comparisons within hours, its computer-use follow-up a month later, and one reproduction thread. This section reports those and attributes every quotation to the handle that posted it.
What Users Praise
The speed is the thing practitioners noticed first, and one measured it. XCSme wrote that "the biggest gain is the speed", with an average of 2.84 seconds for this model against 33 seconds for GPT-5.5 on the same benchmark, and the slowest test answered in under seven seconds against more than five minutes for an older competitor. That is a specific, checkable claim about the fast setting.
The quality against its own predecessor was a wash, and the reviewer said so rather than dressing it up. time0ut ran 144 evaluations on a personalisation task: "results came out at basically a wash on my rubric. The output quality was good, well grounded, and reliable across 144 runs. But not noticeably better." He kept the model anyway, for the speed: "consistently about 2x faster than 3 Flash Preview and slightly faster than 3.1 Flash Lite Preview".
For its class, several practitioners called it a strong release. gertlabs put it plainly: "Taking into account that this is a flash model, it's a strong release. It's very fast and frontier-ish for the price. Raw intelligence is high for a flash model." uean came to the thread to say the writing had improved: the model was "doing a much better job of removing the LLM'ness of what it produces", close to his own style.
The token efficiency of thinking was visible in side-by-side tests. SXX ran the same animated-SVG prompt at three settings and published the token counts: 7,516 tokens at medium thinking, 7,280 at high, against 28,258 for Gemini 3.1 Pro on the same task. The cheaper model spent a quarter of the tokens, though the reviewer noted that only the Pro model produced animated movement.
The computer-use follow-up drew a positive reception on capability and a practical complaint on latency. The thread reached 242 points, and the discussion concentrated on what multi-step GUI work costs in time rather than on whether the model could do it.
What Users Complain About
The price is the dominant complaint, and it is the first thing in the thread. f311a opened with "$9/1M output". swe_dima: "Flash family but costs like a Pro. $9 vs $12 for output." asar: "$1.5/m input tokens $9/m output tokens 6x the price of 3.1 flash lite". bakugo: "Triple the price of the last Flash model ($3 -> $9 per 1M output). Quickly approaching Sonnet prices." mirzap: "The Flash model costs more than the Frontier models. Didn't see that coming." jonnyasmar described the operational consequence for a multi-model workflow: "At 3x the Flash pricing that split stops making sense".
The cost per task, not per token, is the second and sharper complaint. eis did the arithmetic that this review leads with: "3.5 Flash was more expensive than 3.1 Pro to run the Artifical Analysis test suite. $1551 for 3.5 Flash vs $892 for 3.1 Pro. That's 74% more cost while ranking lower." noelsusman compared it with an open-weight model: "Roughly the same intelligence as MiMo-V2.5-Pro for over 3x the cost."
In production, the speed gain reversed. pqdbr: "In my tests, in real production use cases, it's a hard pass. It's actually 10-15% slower and also more expensive than Gemini 3.1 Pro, because it thinks more than 2.5x Gemini 3.1 Pro." nl published a benchmark table: 19 of 25 on an agentic SQL set against 22 of 25 for 3.1 Flash-Lite, at 367 seconds against 142, and 75 cents against 2 cents.
Instruction following and tool use are the technical complaints that recur. data-ottawa: "I'm finding it very bad at instruction following vs 3.1. It calls tools it is told shouldn't, and it loves calling tools." He added that the release notes advise reducing unnecessary tool calls by reducing thinking. gertlabs, otherwise positive, noted that the tool-use delta "has actually regressed from some previous models".
The knowledge cutoff surprised people. musebox35: "The cutoff date is early 2025 so make sure to enable web search when experimenting. I was expecting something more recent, took a while to notice this."
The missing computer-use tool was noticed on day one. pimeys: "No computer use yet. I wonder when they enable it for this model, CUA was one of the main selling points for us with the previous version of Flash." Google added the tool on 2026-06-24.
The tone is a recurring irritation, separate from capability. vikramkr: "this model is whack. Exclamation marks everywhere, sycophantic - not producing working code on prompts the other models handle fine", with the model declaring "Everything is in perfect order!" while the thing it built did not work.
And one reproducibility thread named the grading failure. XCSme: "trying to use Gemini 3.5 Flash to rate some answers, but it kept giving 7 instead of 10 for correct answers. Apparently once you add a 'Grading criteria' text, the model collapses into a 'compressed toward the center of the scale' hallucination", reproduced on the first try in the Gemini app.
Sentiment Summary
Overall sentiment: Positive on speed, multimodal reading and the agentic step over its predecessor; negative on the price and on cost per task; and specifically negative among practitioners who ran it in production at high thinking levels or used it to grade.
Key themes: the model is fast and reads charts and screenshots well; it is three times the price of the Flash tier it replaced and cost more per benchmark run than the previous Pro; at higher thinking levels it can be slower than the model it was supposed to beat; tool use and instruction following are less reliable than the improvements suggest; the cutoff is January 2025; and the launch lacked computer use until June.
U365 Editorial Note
User sentiment and the CI-First score agree on the capability and disagree on the price, and the disagreement is the useful part.
They agree that the model is good for its class: the first substantive comments on the thread are the price, but the measured reports that follow describe a fast, well-grounded model that reads charts and writes usable code, and the 144-run evaluation that found it "basically a wash" against the cheaper predecessor still kept it for speed. They agree on the price as well, and more sharply than the review does: the framework scores the net benefit of a tool that is already in use, and the thread is full of people deciding not to put it into use.
Where the framework goes further is on what the distribution does to the person using it. This model was the default answer in the Gemini app and AI Mode in Search for billions of people, and the dial that changes its behaviour is a thinking level those users never see. The Skill sub-score of 3 and the Skill Illusion of High are the framework's answer: the answers improve, the habit of checking them does not, and the grading failure in Section 7c is what that looks like when it lands on a task a professional would automate first.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Comparison and Alternatives
This section carries the comparison a reader came for: Gemini 3.5 Flash against the model that replaced it, against the current model in its own line, and against the Gemini 4 model that took over the Flash tier entirely.
The four-model comparison, on U365's own published readings
Field | Gemini 3.5 Flash | Gemini 3.6 Flash | Gemini 3.8 Flash | Gemini 4 Hydrogen |
U365 CI-First Benefit Score | 5.3 / 10 (CI-First Positive) | 5.3 / 10 (CI-First Positive) | 7.0 / 10 (CI-First Strong) | 6.3 / 10 (CI-First Strong) |
Sub-scores (Time / Quantity / Quality / Skill) | 6 / 6 / 6 / 3 | 6 / 5 / 6 / 4 | 8 / 7 / 7 / 6 | 8 / 7 / 7 / 3 |
Band | Positive | Positive | Strong | Strong |
Humics Protection | Humics-Neutral (-1 / +3) | Humics-Neutral (0 / +3) | Humics-Neutral (+1 / +3) | Humics-Neutral (-1 / +3) |
AI Imposture Risk | Medium (Skill Illusion High) | Medium | Medium | Medium (Skill Illusion High) |
Primary CI-First Profile | Co-Worker and Assistant (level 2) | Co-Worker and Assistant (level 2) | Co-Creator and Thought Partner (level 1) | Co-Worker and Assistant (level 2) |
Released | 2026-05-19 | 2026-07-21 | 2026-09-02 | 2026-11-12 |
API price per million tokens | $1.50 in / $0.15 cached / $9.00 out | $0.75 in / $0.075 cached / $3.75 out through 2026-12-31, then $1.50 / $0.15 / $7.50 | $0.75 in / $0.075 cached / $3.75 out through 2026-12-31, then $1.50 / $0.15 / $7.50 | $1.50 in / $7.50 out, implicit caching only |
Context and output | 1,048,576 in / 65,536 out | 1,048,576 in / 65,536 out | 1,048,576 in / 65,536 out | 1,048,576 in / 65,536 out |
U365 status | Retired | Active at its last review (2026-08-25) | Active | Active |
Independent position | 167 output tokens per second, 11.65 seconds to first token, no Intelligence Index published | 162 tokens per second, 11.81 seconds, no Intelligence Index published | 114 tokens per second, 17.34 seconds, Intelligence Index 31, $7.77 per task | 13.7 minutes per task at xhigh, 54 percent on Terminal-Bench 4.0 |
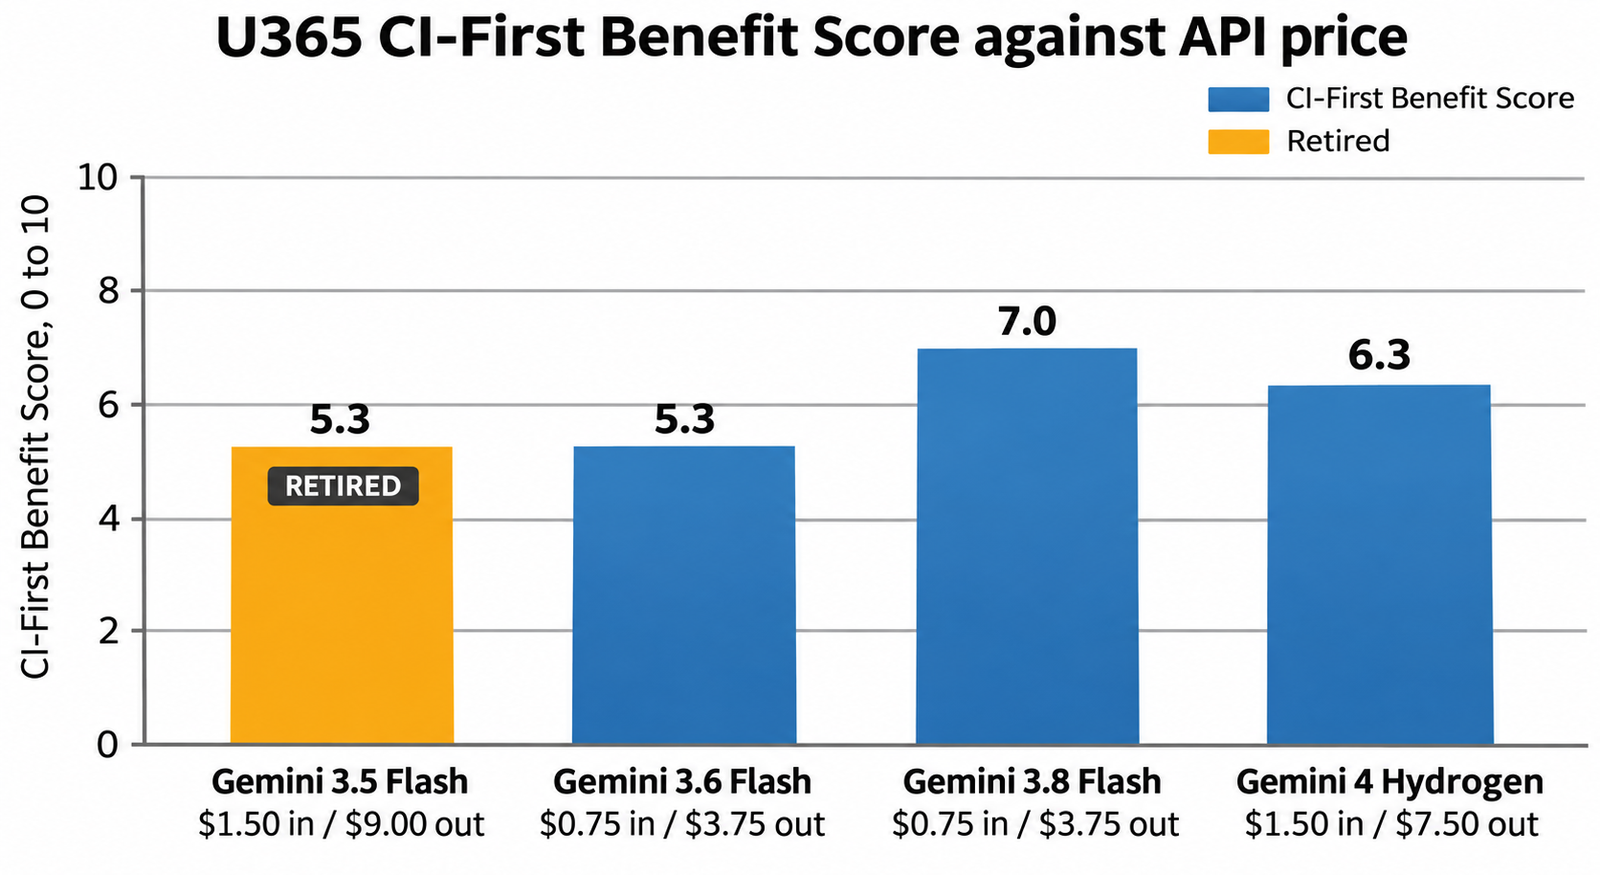
Where this model sits among the four, stated plainly. It is the oldest and the only retired one, and it is not the weakest. Its independent speed figures, 167 tokens per second and 11.65 seconds to first token, beat both the successor and the current 3.8 Flash, and its multimodal rows are close to the best in the line. What it does not have is a price: at $1.50 and $9.00 it is twice the input price and more than twice the output price of a successor that is also faster to be reached, because the successor is what answers. The two models score 5.3 because the framework measures benefit delivered, and a cheap, current, equally fast model and an expensive, retired, equally fast model differ on the dimensions that decide adoption rather than on the dimensions that decide whether the work gets done.
What moved, and what did not. Capability moved in small steps: 3.6 Flash kept the same window and output ceiling, 3.7 and 3.8 trimmed the thinking ladder by removing MINIMAL, and Gemini 4 Hydrogen replaced the tier entirely with a different model built from Gemini 4 Carbon. Price moved down and then sideways: the successor launched at half the input and 42 percent of the output price, and the standard rate from 2027-01-01 restores input parity and keeps a $1.50 output advantage. What did not move is the shape of the reader's work: state the task, choose a thinking level, read the output, verify it. The Skill sub-scores differ by one or three points across the four, and none of them makes the model a teacher.
One comparison caveat, stated because the record requires it. The vendor's benchmark table for this model is dated May 2026 and compares it with models of that moment: Gemini 3 Flash, Gemini 3.1 Pro, Claude Sonnet 4.6, Claude Opus 4.7 and GPT-5.5. It is not comparable with the tables published for Gemini 4 Carbon or Hydrogen, which use current peers and current evaluation setups. A reader should read each review against its own table rather than across them.
The field, with "Choose X if" guidance
Alternative | Choose the alternative if... | Choose Gemini 3.5 Flash if... |
Gemini 3.6 Flash | You are building now on the Developer API, where a request to this ID already reaches it, and you want the lower price and the current documentation. It is the same window and ceiling, at half the input price through 2026-12-31. | You need the longer Cloud support window: this model retires in May 2027 or later, and 3.6 Flash retires on 2026-11-19. |
Gemini 3.8 Flash | You want the current model in the line and the highest U365 score of the four, at 7.0, with the same introductory price as 3.6 Flash. Its independent position is measured and published. | Almost never on capability or price. The one case is a deployment already qualified on this model and not yet due for re-qualification. |
Gemini 4 Hydrogen | You want the tier's replacement rather than its descendant, with implicit caching, four thinking levels back including the default at high, and a review that treats the Flash tier as redefined. It scores 6.3 and is the newest model in the family. | Never on merit. A team comparing them is comparing a model that is sold with one that is retired. |
Gemini 3.5 Flash-Lite | Your work is classification, extraction or routing at volume, cost matters more than judgement, and $0.30 in and $2.50 out fits the budget. It scores 5.5 and is still in the line. | Your task needs the larger model's multimodal reading or its agentic coding, which Flash-Lite is not positioned for. |
Claude Sonnet 5.5 | The work is agentic coding or document production where you can check the answer, and you want the 7.0 score, a 128,000-token output ceiling and a $2 and $10 rate. | Your stack is on Google Cloud, your workflow already depends on Gemini's tool surface, or you need the multimodal input breadth in one window. |
Where Gemini 3.5 Flash is clearly better: on measured output speed against every model in its own line, at 167 tokens per second against 162 for 3.6 Flash and 114 for 3.8 Flash; on multimodal reading at 84.2 percent on CharXiv without tools; on the published Cloud support window, which runs to May 2027 or later; and on the price it is actually billed at if your workload is already qualified and running.
Where Gemini 3.5 Flash is clearly worse: on price against its successor, at three times the input rate and more than twice the output rate of the model that replaced it; on price per task against the previous Pro; on knowledge recency, with a January 2025 cutoff; on long-context retrieval at 1M; on current documentation and support, because the Developer API no longer selects it; and on independent verifiability, because no current Intelligence Index is published for it.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Verdict and Next Steps
Who should adopt it: nobody starting today. The verdict for a new integration is to use Gemini 3.8 Flash, Gemini 3.6 Flash or Gemini 4 Hydrogen, all of which are current, cheaper or better measured, and none of which carries a retirement badge.
Who should keep it, for now: a team already running this model on Google Cloud with a qualified workload, where the published support window to May 2027 or later is worth more than the price difference, and where the migration is a scheduled project rather than an emergency. That is a real case and it is the only one.
When: the migration is not urgent on Google Cloud and it is already done on the Developer API, whether the team knows it or not. The next step is to confirm which surface each workload calls and which model answers, then to plan the move against the successor's own dates.
For what: bounded agentic coding with a checkable end state, multimodal reading of a document set that fits inside the first 128k tokens, high-volume extraction and drafting at MINIMAL or LOW, and computer-use agents with a prompt-injection plan. Nothing in this review justifies moving new work onto it.
The honest caveat, stated once: this is a genuinely capable model for its generation, and it is the wrong purchase. It was fast, it read charts and screenshots better than its predecessor, and it could carry a bounded agentic task; it also tripled the price of its tier, cost more per benchmark run than the previous Pro, was replaced on the Developer API two months later, and fails a rubric-grading test in a way that looks like judgement. Keep it if it is already qualified and the support window is the thing you need. Move everything else.
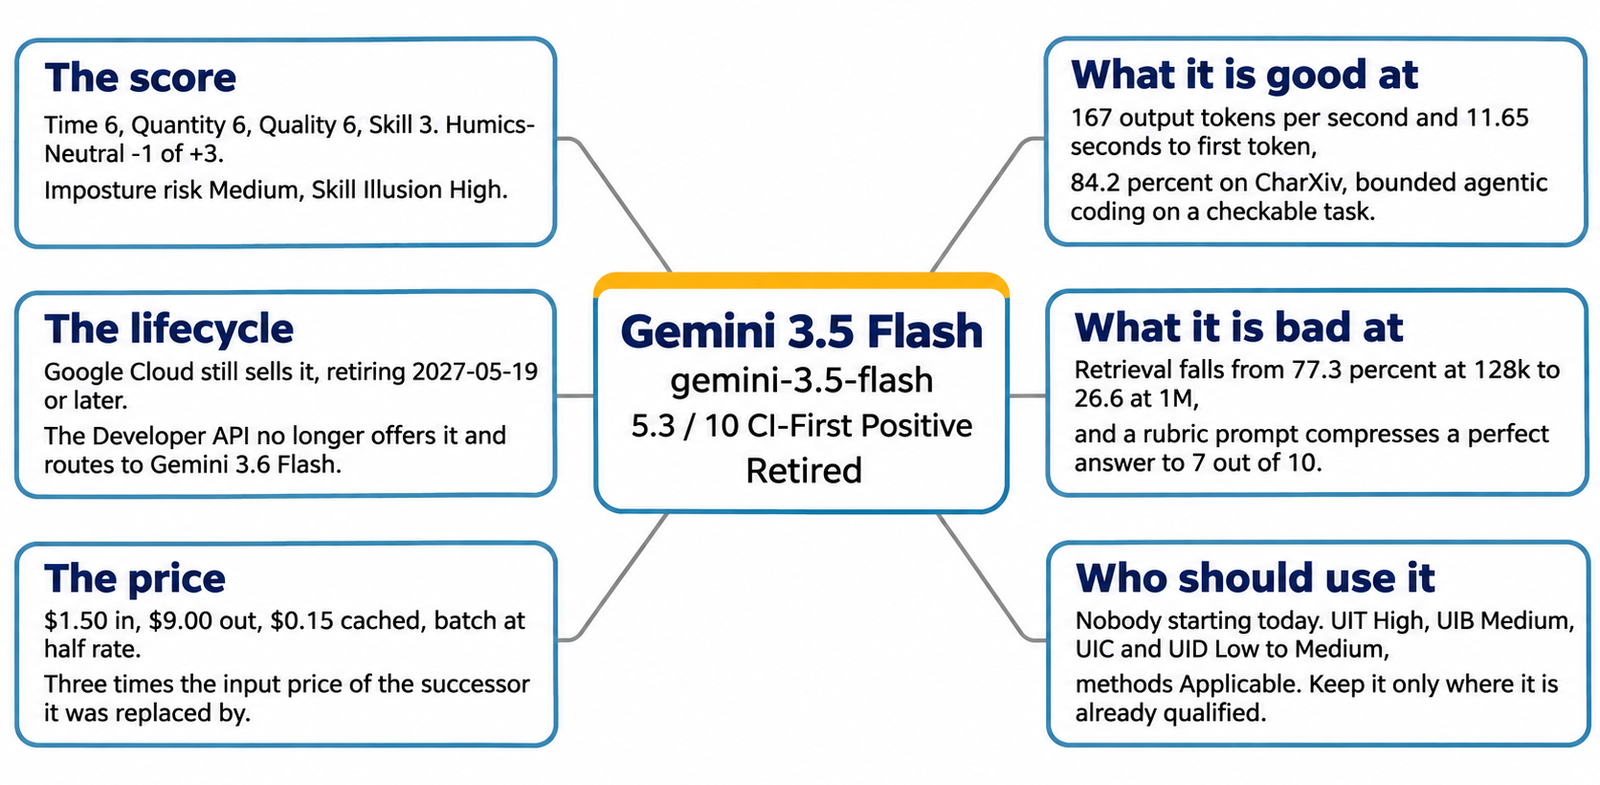
UP-Context-Engineering prompt pack
Prompt 1: Find out which model your endpoint is actually running.
Context: I have [number] services that call the model id gemini-3.5-flash. Some run on
Google Cloud and some on the Gemini Developer API. I need to know which model answers on each,
before I plan a migration.
Role: AI as an Analyst. You are not changing anything; you are producing a fact table.
Profile: Act as an Analyst and Tester, applying a stated test rather than an impression.
Task: give me a procedure that makes each endpoint identify the model behind the response,
a way to record it, and a way to detect a change later.
Constraints: no more than eight steps. Every step must be runnable without the model. Name
what the vendor documents and what has to be observed from a response. Do not assume the two
surfaces behave the same.
Output format: a table with surface, endpoint, test, expected result, and how to record it.
Then one line naming the service most likely to be misattributed.
Memory disclosure: keep the service list and the test results for this session only. Do not retain endpoint names or keys, and do not write a standing note about my estate.
UP-Context-Engineering verification: I run the test on every endpoint myself, I record the model that answers in my own log, and I can say which service was reaching the wrong model before I changed anything.
Data safety: do not paste API keys, service account files or endpoint URLs that carry a project id. Describe the surface and the region, not the credential.
Prompt 2: Decide the migration target and the order.
Context: I run [number] workloads on gemini-3.5-flash. They are [list, one line each, with
volume and whether the output is checked by a test, a schema or a person]. My constraints are
[budget, deadline, review capacity]. The candidates are gemini-3.6-flash, gemini-3.8-flash
and gemini-4-hydrogen, with the dates and prices in this review.
Role: AI as an Analyst, not as an engineer. You are sequencing the work, not doing it.
Profile: Act as a Co-Researcher, separating what the vendor publishes from what I must test.
Task: order the workloads for migration, assign a target model and a verification step to each.
Constraints: one recommendation per workload. Put the cheapest-to-check workload first. Do not
recommend a target whose published retirement date falls inside my planning horizon without
saying so. Do not recommend the top thinking level for any workload.
Output format: a table with workload, target model, thinking level, reason, verification step,
and the date the old model must be off. Then one line naming the workload I should retire
rather than migrate.
Memory disclosure: keep the workload list and my constraints for this session only. Do not retain the volumes, the dates or my team's plan.
UP-Context-Engineering verification: I can defend each target from the date and the checkability of the workload, and I can name the workload I chose to retire rather than move.
Data safety: do not paste client names, unannounced workloads, contract terms or anyone's performance record. Describe a workload by its type and its volume.
Prompt 3: Turn the grading failure into a control you keep.
Context: I want to use a model to score [task] at volume. My rubric has [criteria] and a 0 to 10
scale with anchors. A known failure of this model family is that a rubric prompt compresses
scores toward the middle, so a perfect answer can receive 7 rather than 10.
Role: AI as a Coach. You are helping me build the test, not the grader.
Profile: Act as a Coach and Tutor. Do not score anything for me now.
Task: write the control set I must build before I use any model as a grader.
Constraints: no more than 10 steps. Include at least three answers that must receive the top
of the scale and three that must receive the bottom, and a rule for what to do when a control
answer is scored wrong. Every step must be something I do, not something the model does.
Output format: When to use this. The control set. The pass condition. The failure procedure.
Memory disclosure: keep the rubric and the control answers for this session only. Do not retain the answer texts and do not write a standing note about my assessment practice.
UP-Context-Engineering verification: I can run this control set without the model, and I can
teach it to a colleague in ten minutes.
Data safety: do not paste student records, examination content or answers that identify a person. Replace names with candidate ids.
Related U365 content
Gemini 3.6 Flash Tool Review. Read the review. The recommended replacement, at 5.3 with sub-scores 6 / 5 / 6 / 4. Read it beside this review to see that the successor reached the same score at half the price.
Gemini 3.8 Flash Tool Review. Read the review. The current model in this line, at 7.0 with sub-scores 8 / 7 / 7 / 6 and a measured independent position. Read it for what the tier became.
Gemini 4 Hydrogen Tool Review. Read the review. The model that replaced the Flash tier entirely, at 6.3, with the fullest treatment of implicit caching and the four-level thinking ladder in the library.
Gemini 3.5 Flash-Lite Tool Review. Read the review. The cheaper sibling at 5.5, and the model that inherited the gemini-2.5-flash routing on 2026-12-01.
The CI-First Evaluation Framework, version 1.4.1. The method behind the score, including the clause set applied in Strengths, Limits, and AI Imposture Risk.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Status and Last Tested
Status: Retired. Last tested: 2026-11-14. Version reviewed: Gemini 3.5 Flash, `gemini-3.5-flash`, released 2026-05-19. Next scheduled re-check: on any of the seven triggers in the Status and Re-check section of this document, and in any case within six months while the Cloud endpoint remains available.
Retired is the badge for a tool that still works and is no longer recommended. It is not a claim that the model stopped functioning: on Google Cloud it is generally available with a retirement date of May 19, 2027 or later, and a workload running there continues to run. It is a claim about the purchase. The Developer API no longer selects this model, the successor is cheaper on both lines, and the current model in the line scores 1.7 points higher on the framework. A reader who arrives more than six months after 2026-11-14 should treat the price lines, the two surfaces' lifecycle dates and the thinking-level behaviour as unverified until a re-check is published, because the 3.x Flash line has changed every few weeks.
The evidence was read on the date above: the vendor's launch post and model card of May 2026, the Google Cloud model page and thinking-level table as they stood on 2026-11-14, the Gemini API model list, pricing page and deprecation table, the Artificial Analysis page, and the community record from the launch and its follow-ups.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Migration Path
This section is required, because the tool is Retired. It sets out how to leave Gemini 3.5 Flash, what transfers, what does not and what to expect on the other side.
Where to go. Three targets, and the choice is about horizon rather than capability. gemini-3.6-flash is the vendor's recommended replacement and the model the Developer API already routes to, at $0.75 and $3.75 through 2026-12-31, with the same 1,048,576-token window and 65,536-token output ceiling; its Cloud retirement date is 2026-11-19, so it is an interim target rather than a destination. gemini-3.8-flash is the current model in the line, at the same introductory price, with a Cloud retirement date of 2027-09-02 or later and an independent position measured at Intelligence Index 31 and $7.77 per task. gemini-4-hydrogen is the model that replaced the Flash tier, at $1.50 and $7.50, with implicit caching only. A team planning beyond 2027 should choose 3.8 Flash or Hydrogen; a team that only needs the ID to stop routing to an undocumented model should move to 3.6 Flash and plan the second hop.
What transfers. The model id is the only thing that changes in a simple call: the request shape, the thinking-level names, the tool definitions, the structured-output schema and the grounding configuration are the same family across 3.5 and 3.6, and 3.7 and 3.8 drop MINIMAL rather than adding a new level. Context and output limits are identical across 3.5, 3.6 and 3.8. Prompt suites and evaluation sets transfer, with one change of setting: the thinking level now means something slightly different on each model, so a suite should be re-run at the level you intend to use rather than at the level it was written for.
What does not transfer, and why. The knowledge cutoff moves with the model, and no target inherits January 2025; anything that depended on the old cutoff has to be re-grounded. The price changes direction twice, down at the introductory rate and up again on 2027-01-01, so a budget written against today's number is wrong in seven weeks. The thinking ladder loses MINIMAL on 3.7 and 3.8, so a MINIMAL policy must become LOW or be re-designed. Computer use exists on all four models but was added to 3.5 Flash after launch, so an agent built on its June 2026 behaviour should be re-tested rather than assumed. And the routing fact does not transfer: on the Developer API the old id already reaches 3.6 Flash, which means some workloads have been running the successor for months without a code change, and their measured behaviour is not the behaviour of the model this review scores.
Migration steps, in order. First, inventory every call site and record which surface each one uses, because the Developer API and Google Cloud now behave differently under the same id. Second, make each endpoint identify the model it returns, and log it, so that a later change is detected rather than discovered. Third, freeze a control set of twenty to fifty representative tasks with expected outcomes, and record the current model's results on it. Fourth, move the cheapest-to-check workload to the chosen target and compare against the control set at the thinking level you intend to use. Fifth, re-run the rubric-grading workflow specifically, because the scale-compression failure is the one most likely to survive a model change unnoticed. Sixth, update the budget from the introductory rate to the 2027-01-01 rate, and write the date into the cost model. Seventh, remove the old id from code rather than leaving it as a fallback, because on the Developer API it is an alias and on Google Cloud it is a model that retires in May 2027.
What to expect on the other side. A model that is cheaper, current and, on the independent speed figures, no faster than the one being left. The capability gain from 3.5 Flash to 3.6 Flash is small and the price gain is large; the gain from either to 3.8 Flash is the one worth planning for, at 7.0 on the framework against 5.3. What does not change is the work: the thinking level still decides the cost, the first 128k tokens still decide the retrieval, and the verification step is still yours.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
U365's Recommendations to Learn More
These resources were curated to help you go deeper on Gemini 3.5 Flash. We prioritise material that teaches something this review does not cover.
Official learning resources
The launch post, "Gemini 3.5: frontier intelligence with action": the positioning, the benchmark table, the partner list and the sentence that made it the default in the Gemini app and Search. Read it beside the price page. https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-5/
The model card, published 19 May 2026: inputs and outputs, the 1M context and 64K output, the full benchmark table against Gemini 3 Flash and its peers, and the safety deltas this review quotes. https://deepmind.google/models/model-cards/gemini-3-5-flash/
The Google Cloud model page for gemini-3.5-flash: the token limits, capabilities, tools, consumption options, supported regions and the retirement date. The single most useful page for a buyer, and the one that still describes the model as sold. https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-5-flash
The thinking-level table, model by model: which levels each model accepts and what the default is, including the MINIMAL level that 3.7 and 3.8 dropped. https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/thinking
The Gemini API model list: the current models and their ids, and the absence of this one. https://ai.google.dev/gemini-api/docs/models
The Gemini API pricing page: what each model costs now, including the successor's introductory rate and the 2027-01-01 standard rate. https://ai.google.dev/gemini-api/docs/pricing
The deprecation table: the routing note for this model, and the older 2.5 Flash note that states billing as well as routing. Read the two notes against each other. https://ai.google.dev/gemini-api/docs/deprecations
The computer-use post of 2026-06-24: what was added, the adversarial training against prompt injection, and the two optional enterprise safeguard systems. https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-computer-use-gemini-3-5-flash/
Google Cloud generative AI pricing, for the standard, batch, non-global and provisioned lines on the same page. https://cloud.google.com/vertex-ai/generative-ai/pricing
Video tutorials and channels
Artificial Analysis, "We tested Gemini 3.5 Flash, here's 3 things you should know": the independent evaluator walking through its own measurements, which is the closest thing to the composite this review could not cite. https://www.youtube.com/watch?v=bW0iLoXoH78
Better Stack, "Gemini 3.5 Flash is just... fine": a hands-on assessment whose verdict is in the title, useful as a counterweight to a launch-week thread. https://www.youtube.com/watch?v=JegffwBtXJ0
MattVidPro, "I Field Tested Gemini 3.5 Flash: Fast Boi, Smol Brain": a field test organised around the speed-and-depth trade this review scores in Time and Quality. https://www.youtube.com/watch?v=U1VMhxccPYU
Written tutorials and deep-dive articles
Simon Willison, "Gemini 3.5 Flash: more expensive, but Google plan to use it for everything": the price comparison against the previous Flash models, the benchmark-run costs from Artificial Analysis, and the knowledge cutoff, all published on launch day. https://simonwillison.net/2026/May/19/gemini-35-flash/
Artificial Analysis, the model page: the speed figures this review cites, the cost per token, and the deprecation notice that replaced the composite. https://artificialanalysis.ai/models/gemini-3-5-flash
Artificial Analysis, the intelligence index methodology: the nine evaluations behind the composite, so a reader can see which of them resemble their own work. https://artificialanalysis.ai/evaluations/artificial-analysis-intelligence-index
The Hacker News launch thread: 962 points and 658 comments of practitioner reports, including the price arithmetic, the production slowdowns and the tool-use complaints quoted in this review. https://news.ycombinator.com/item?id=48196570
The "Tell HN" reproduction of the grading failure, with a shared chat link: the clearest single piece of evidence in the record about what this model does when asked to apply a rubric. https://news.ycombinator.com/item?id=48230368
The computer-use follow-up thread: 242 points on what the added tool made possible and what it cost in latency. https://news.ycombinator.com/item?id=48662999
Community and social
Hacker News, the launch thread: the most useful single page in the record, because practitioners posted measured comparisons and cost arithmetic on the first day rather than impressions. https://news.ycombinator.com/item?id=48196570
Artificial Analysis, the release comparison page: the independent measurements as they are updated, which is where a reader should check whether any figure in this review still holds. https://artificialanalysis.ai/models/releases
Resources on X
Dedicated X channels. Three accounts carry this release: Google DeepMind, which posted the launch; the Google AI account, which carries the developer material; and Artificial Analysis, which carries the independent measurements this review cites.
@GoogleDeepMind, the research account: https://x.com/GoogleDeepMind
@GoogleAI, the developer account: https://x.com/GoogleAI
@ArtificialAnlys, the independent evaluation account: https://x.com/ArtificialAnlys
Read any post against the measurement rather than against its own caption, and treat a launch-day thread as a pointer to a source rather than as a source.


Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
CI-First Evaluation Summary Card
Field | Value |
Tool | Gemini 3.5 Flash, operated by Google |
Category | Applied AI / Large Language Model (agentic coding, tool use, multimodal document work and high-volume execution) |
Version reviewed | Gemini 3.5 Flash (gemini-3.5-flash, released 2026-05-19), as documented by the vendor on 2026-11-14 |
Status | Retired |
Last tested | 2026-11-14 |
CI-First Profile | Primary: Co-Worker and Assistant (level 2). Secondary: Co-Researcher, Analyst and Tester (level 4) for multimodal document and chart work |
CI-First Benefit Score | 5.3 / 10 (CI-First Positive) |
Time | 6, a real speed case at the bottom of the thinking ladder (167 output tokens per second, 11.65 seconds to first token, 2.84 seconds average on one latency benchmark at the low setting) against a real overhead: two production reports of 10 to 15 percent slower than Gemini 3.1 Pro because it thinks about 2.5 times as much, and 367 seconds against 142 on an agentic SQL run |
Quantity | 6, a large window and a broad modality set (1,048,576 tokens in, 65,536 out, text, image, audio and video input, batch and flex consumption, cache at 90 percent off) held back by a $9.00 output rate that bills reasoning as output and by a long-context row that falls to 26.6 percent at 1M |
Quality | 6, strong for its generation on the vendor's table (76.2 on Terminal-Bench 2.1, 83.6 on MCP Atlas, 84.2 on CharXiv, 78.4 on OSWorld-Verified) and held at 6 by an independent record that reports a wash against the cheaper predecessor, below Gemini 3.1 Pro in two production workloads, and no published Intelligence Index |
Skill | 3, execution rather than learning, with no teaching mechanism and a retirement that makes the specific behaviour a depreciating investment; scored conservatively per the framework's guidance |
Humics Protection Badge | Humics-Neutral (-1 / +3) |
Creativity | 0 Neutral: it drafts, designs and iterates against a direction you set, with strong vendor demonstrations of UI, animation and branding output; it neither trains nor replaces your ideation |
Critical Thinking | -1 Erodes: fluent, near-frontier output for people who cannot evaluate it, delivered as the default in the Gemini app and AI Mode in Search for billions of users, with a rubric-grading failure that looks like considered judgement |
Social Authenticity | 0 Neutral: clause 4.2-a returns a null for the model as a generator; the live condition is an agent such as Gemini Spark acting on a person's behalf, which this release made easier to build |
AI Imposture Risk | Medium overall, with Skill Illusion High |
Time Illusion | Medium: real savings at MINIMAL and MEDIUM against a real overhead, including a thinking decision on every job, four settings whose cost and latency differ by an order of magnitude, a long-context cliff and an unplanned migration |
Quantity Illusion | Medium: a million-token window and batch consumption that produce volume a reader cannot check, with the vendor's own retrieval row showing the model reading far less of a large prompt than the window implies |
Skill Illusion | High: expert-form code, tables and scores for users who cannot evaluate them, from the default model behind a search box used by billions, with a dial labelled HIGH that reads as a quality setting; mitigations are stated in Strengths, Limits, and AI Imposture Risk |
Clause 5.2.3-a | NULL, recorded with its boundary: a stateless model endpoint documents no mechanism that writes procedural memory or standing instructions on the user's behalf. Live condition: the Gemini Spark agent, if it begins writing procedures the user did not author |
Clause 4.2-a | NULL as a generator, with a live condition: an application that sends text in a person's own name, or an agent that acts in their accounts without them reading each action, would meet erosion condition (a) |
Clause 7.5 | Removed by framework v1.4 on 2026-10-13, not assessed; recorded so that a reader comparing reviews knows why it is absent |
Section 7c finding | Two Google surfaces disagree about the same id: the Developer API no longer offers it in AI Studio and routes requests to gemini-3.6-flash, while Google Cloud sells it as GA with a retirement date of May 19, 2027 or later, later than its own successor's 2026-11-19. Computer use arrived on 2026-06-24, not at launch; the model card publishes a 3.9 percent content-safety regression against its predecessor alongside a tone improvement. No sub-score changed, for reasons stated in the section |
Superhuman usage | Invite for bounded agentic coding, multimodal document triage inside 128k, high-volume extraction at MINIMAL, and a qualified Cloud deployment with a planned migration; keep out of new integrations, uncheckable work, automated grading without a control set, post-2025 knowledge work without retrieval, full-window prompts and unplanned agent work |
Over-delegation warning | The failure mode is a person who lets a fast model grade the answers, summarise the sources and draft the reply because it answers in seconds and was the default behind a search box, and who stops reading the output as closely as they read a colleague's. If you cannot say which model answered, at which thinking level, and what you verified this week, the price is being paid in attention rather than in dollars |
Verification checklists | Per workflow, in Real Workflows: multi-model check, external source, human review, report-to-specification or scale check, CI-First test |
U365 methods | LIPS holds the task, the thinking decision and the verification record, because the model holds no state beyond the session and has a retirement date. ULM and EVA: Career and Finance through cost per completed task and the lifecycle judgement. UP-Context-Engineering writes the context, role, task, constraints and output order the workflows use. UNOP: weak, because the model produces rather than teaches |
Re-check triggers | Any change to the Developer API routing; any change to the Cloud retirement dates; a price change on either line; any change to the thinking levels or the default; a new independent measurement; any change to the computer-use surface or its safeguards; and a successor that removes the support-window case |

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Glossary
CI-First
Co-Intelligence First: the U365 principle that the human is the ruler and the orchestrator and AI is the amplifier. The question this review answers with a score is whether the tool makes co-intelligence more profitable than human intelligence alone. Gemini 3.5 Flash is a CI-First Positive model: it amplifies a reader who already runs it, at a price and a lifecycle that make it a poor choice for anyone starting now.
CI-First Benefit Score
The arithmetic mean of the four benefit dimensions, each scored 0 to 10, rounded to one decimal place. 0 to 2.0 is CI-First Negative, 2.1 to 4.0 is CI-First Neutral, 4.1 to 6.0 is CI-First Positive, 6.1 to 8.0 is CI-First Strong, and 8.1 to 10 is CI-First Transformative. Gemini 3.5 Flash scores 5.3, which is Positive.
Time Benefit
Whether the tool returns more time than it costs, after the overhead of using it is subtracted. Gemini 3.5 Flash is 6: 167 output tokens per second and 11.65 seconds to first answer token on independent measurement, and 2.84 seconds average on one latency benchmark at the low setting, against a thinking decision on every job and two production reports of it being slower than the previous Pro model because it thinks more.
Quantity Benefit
Whether the same time produces more usable output. Gemini 3.5 Flash is 6: a 1,048,576-token window, 65,536 tokens of output, four input modalities, batch and flex consumption and caching at 90 percent off, held back by a $9.00 output rate with reasoning included and by retrieval that falls to 26.6 percent at the top of the window.
Quality Benefit
Whether the output is better, verified and durable. Gemini 3.5 Flash is 6: strong vendor rows for its generation, 76.2 on Terminal-Bench 2.1 and 84.2 on CharXiv among them, against an independent record that reports a wash with its cheaper predecessor, below Gemini 3.1 Pro in two production workloads, and no current composite.
Knowledge and Skill Benefit
Whether the user gains lasting capability. Gemini 3.5 Flash is 3: execution rather than learning, a thinking ladder the user must learn to operate without help, and a retirement that makes the specific behaviour a depreciating investment.
CI-First Profile
The role the AI plays in your working relationship. (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Professor, Coach and Tutor, (level 4) Co-Researcher, Analyst and Tester, (level 5) Challenger, Critic and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration. Gemini 3.5 Flash is primarily a Co-Worker and Assistant (level 2).
Humics
The set of capabilities that are uniquely human, as defined by Pascal Bornet: creativity, critical thinking and social authenticity. The framework asks whether a tool strengthens, leaves neutral or erodes each one.
Humics Protection Badge
A rating of whether a tool protects, leaves neutral or erodes the three human capabilities: Creativity, Critical Thinking and Social Authenticity. Each is scored +1, 0 or -1 and the sum gives the badge. +2 to +3 is Humics-Friendly, -1 to +1 is Humics-Neutral, -2 to -3 is Humics-Risky. Gemini 3.5 Flash is Humics-Neutral at -1 / +3.
AI Imposture Risk
The likelihood that a tool traps you in one of three illusions. The Time Illusion is the appearance of saving time when net time is lost. The Quantity Illusion is high volume that does not survive inspection. The Skill Illusion is the appearance of competence while the underlying skill is absent or eroding. Each trap is rated Low, Medium or High with cited evidence. The overall level is Low when all three are Low, Medium when one, two or three traps are Medium or when one trap is High with clear mitigations stated, and High when two or more traps are High or when the tool's core value proposition is built on an illusion. Gemini 3.5 Flash is Medium overall, with Skill Illusion High.
User Sentiment
The aggregate of what users report about a tool, kept separate from the framework's own findings. No review platform carries model-level data for Gemini 3.5 Flash; the signal is the Hacker News launch thread, its computer-use follow-up and one reproduction thread, all directional and all from the model's first weeks.
Review Status
The badge at the top of this review. The vocabulary is: Active, the tool is current and recommended; Active (updated), recently re-checked and refreshed; Changed, a re-check trigger has fired and an update is pending; Risky, the tool has significant unresolved issues or has been clearly surpassed, so use it with caution; Stale, not re-checked in over six months, so pricing and features are unverified; Retired, the tool still works but is no longer recommended; Deprecated, the tool has been shut down or fundamentally changed.
Last tested and Re-check
The date this review's evidence was gathered and the condition that forces a new pass. Gemini 3.5 Flash was tested on 2026-11-14 and re-checks on the seven triggers listed in the Status and Re-check section, and in any case within six months while the Cloud endpoint remains available.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Sources
Vendor primary sources
The launch post, "Gemini 3.5: frontier intelligence with action", 2026-05-19, for the positioning, the benchmark headlines, the partner list, the default-model statement for the Gemini app and AI Mode in Search, and the Gemini Spark announcement: https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-5/
The model card, published 19 May 2026, for the description, the 1M input and 64K output, the modalities, the dependency on Gemini 3 Flash, the full benchmark table and the safety deltas: https://deepmind.google/models/model-cards/gemini-3-5-flash/
The Google Cloud model page for gemini-3.5-flash, for the token limits, capabilities, tools, consumption options, supported regions, launch stage, release date and retirement date: https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/gemini/3-5-flash
The thinking-level table, for the four levels and the MEDIUM default on this model and the changes on later models: https://docs.cloud.google.com/gemini-enterprise-agent-platform/models/thinking
The Gemini API model list, for the current model set and the absence of this id: https://ai.google.dev/gemini-api/docs/models
The Gemini API pricing page, for the current rates, including the successor's introductory and 2027 rates: https://ai.google.dev/gemini-api/docs/pricing
The deprecation table, for the routing note on this model, the 2.5 Flash note that states billing as well as routing, and the release dates of the preview models: https://ai.google.dev/gemini-api/docs/deprecations
The computer-use announcement of 2026-06-24, for the added tool, the adversarial training and the optional enterprise safeguards: https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-computer-use-gemini-3-5-flash/
Google Cloud generative AI pricing, for the standard, non-global, batch and provisioned rates on one page: https://cloud.google.com/vertex-ai/generative-ai/pricing
Independent sources
Artificial Analysis, the Gemini 3.5 Flash model page, for the time to first answer token, the output speed, the token prices, the context window and the deprecation notice: https://artificialanalysis.ai/models/gemini-3-5-flash
Artificial Analysis, the Gemini 3.8 Flash model page, for the current tier's Intelligence Index, cost per task, time per task, output speed and verbosity: https://artificialanalysis.ai/models/gemini-3-8-flash
Artificial Analysis, the intelligence index methodology, for the nine evaluations behind the composite: https://artificialanalysis.ai/evaluations/artificial-analysis-intelligence-index
Simon Willison, "Gemini 3.5 Flash: more expensive, but Google plan to use it for everything", 2026-05-19, for the price comparison against the previous Flash models, the benchmark-run costs, the knowledge cutoff and the token count of a single generated SVG: https://simonwillison.net/2026/May/19/gemini-35-flash/
Community and community-reported evidence
Hacker News, the launch thread, 962 points and 658 comments, read on 2026-11-14, for every quoted commenter in the launch section of this review: https://news.ycombinator.com/item?id=48196570
Hacker News, "Computer use in Gemini 3.5 Flash", 242 points and 167 comments, read on 2026-11-14 and summarised rather than quoted: https://news.ycombinator.com/item?id=48662999
Hacker News, "Tell HN: Gemini 3.5 Flash breaks in stupid ways", 9 points, for the grading-collapse reproduction and its shared chat link: https://news.ycombinator.com/item?id=48230368
Review platform sources
No reviews found on G2, Capterra, Trustpilot or Product Hunt for this model endpoint. Those platforms rate AI products and companies rather than individual model endpoints, and none publishes a model-level figure for Gemini 3.5 Flash. This review states that rather than inventing a rating.
Framework and method
The U365 CI-First Evaluation Framework, version 1.4.1, which is the scoring method used here: CI-First Evaluation Framework
The U365 INSIDE Tools review template, which sets the structure of this post and the tool-type variants applied in it: INSIDE Tools Review template
Published U365 INSIDE Tools reviews, read as comparisons and named in this post, including the Gemini 3.6 Flash, Gemini 3.8 Flash, Gemini 3.5 Flash-Lite and Gemini 4 Hydrogen reviews: INSIDE Tools reviews
The U365 methods house pages, for the UP-Context-Engineering Method, ULM, LIPS and UNOP as they are published: U365 methods

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Faculty Note on Evidence Quality
Six things should be said plainly about the evidence behind this review, because they change how much weight a reader should put on each part of it.
First, there is no current independent composite for this model, and that absence is a finding. Artificial Analysis keeps the page, the token prices and the speed figures, but it publishes no Intelligence Index for Gemini 3.5 Flash at review time, marks the model deprecated, and points readers to a newer release. The strongest capability record in this review is therefore the vendor's own benchmark table of May 2026, read against the independent speed and cost figures that do exist. That is why Quality is 6 and not 7: a vendor table is evidence of what the vendor measured, and a review that scored it as independent evidence would be claiming more than the record supports.
Second, the cost figures in circulation use two different units, and this review names the unit every time. Artificial Analysis publishes a cost per Intelligence Index task for current models, and it published a full-suite cost at launch: $1,551.60 for this model at high, against $892.28 for Gemini 3.1 Pro Preview, as Simon Willison reported. Those are not the same denominator, and a reader who compares $1,551.60 with a per-task figure will conclude something the numbers do not say. The comparison that matters, and the one the review makes, is within one unit: at launch this model cost 74 percent more than the previous Pro to run the same independent suite.
Third, the price was misreported on launch day by at least one reader, and the cause is worth knowing. One commenter quoted $0.75 and $4.50 as the list price. Those are the batch rates, which are half the standard rates on this model. The standard rate is $1.50 and $9.00, and every other launch-day comment used it. A review that averaged the two would understate the price rise by half, which is why this review states the standard, batch, non-global and provisioned lines separately.
Fourth, the vendor's benchmark table is dated and its peer set is historical. The rows compare this model with Gemini 3 Flash, Gemini 3.1 Pro, Claude Sonnet 4.6, Claude Opus 4.7 and GPT-5.5, which were the peers in May 2026. They are not the peers of November 2026, and the evaluation setups have moved. The table is used in this review for what it says about this model against its own predecessor and the Pro model of its moment, not as a current competitive ranking.
Fifth, the community record is a launch-week signal, and it is used as one. The launch thread carries measured comparisons, including a five-setting token count, a 144-run evaluation, a production slowdown report and an agentic SQL benchmark, and it also carries single-participant impressions about price and tone. This review attributes every quotation to its handle, does not aggregate the thread into a rating, and does not treat a repeated impression as a measurement. The grading collapse is the exception: it is a single case that reproduced on the first attempt, and it is reported as a reproducible failure rather than as a measured rate.
Sixth, the lifecycle evidence comes from two vendor surfaces that disagree, and the review reports both rather than choosing. The deprecation table says the Developer API routes this id to Gemini 3.6 Flash; the Cloud model page sells the same id as GA until May 2027 or later. A reader can resolve the disagreement only by testing their own endpoint and reading their own bill. The most arguable judgement in this review is the Retired badge on a model that one Google surface still sells as generally available: the badge describes the purchase rather than the availability, and a reader who disagrees should read the Migration Path as the operative part.

Gemini 3.5 Flash: Google's Retired Flash Tier That Still Runs on Cloud
Status and Re-check
Status: Retired | Last tested: 2026-11-14 (Gemini 3.5 Flash, `gemini-3.5-flash`, released 2026-05-19) | Re-check: trigger-based (max 6 months)
Retired: the tool still works but is no longer recommended. See the Migration Path section.
For detailed explanations of the CI-First evaluation terms used in this review, including the Humics Protection Badge and the AI Imposture Risk levels, see the Glossary above.
Re-check triggers:
Any change to the routing agreement on the Developer API. The Gemini API documentation states that gemini-3.5-flash is no longer available in Google AI Studio and that API requests automatically route to gemini-3.6-flash. If the ID stops accepting requests, or starts accepting them under a different route, the Migration Path changes.
Any change to the Google Cloud retirement date. The model page states a retirement date of May 19, 2027 or later, and that date is the one remaining reason a pinned deployment can stay on this ID. Its successor's November 19, 2026 date is the other half of the same calculation.
A price change on either line. $1.50 per million input tokens and $9.00 per million output tokens, with context caching at $0.15 and batch at half rate. The successor is at $0.75 and $3.75 through 2026-12-31 and $1.50 and $7.50 from 2027-01-01, so a change to either card moves the comparison.
Any change to the thinking levels or the default. Four levels, MINIMAL, LOW, MEDIUM and HIGH, with MEDIUM as the default. The successor kept all four; the 3.7 and 3.8 models dropped MINIMAL. A change to the ladder moves every cost and latency statement in this review.
A new independent measurement. Artificial Analysis keeps this model's page but publishes no Intelligence Index for it at review time, so the independent position is a speed figure and a deprecation notice rather than a composite. A published index would change the Quality rationale.
Any change to the computer-use surface or its safeguards. Computer use was added to this model on 2026-06-24, after launch, with adversarial training against prompt injection and two optional enterprise safeguard systems.
A successor that removes the support-window case entirely. If 3.6 Flash, 3.7 Flash or 3.8 Flash extends its own retirement date past May 2027, the last argument for this ID disappears.
Re-check on any of the seven triggers listed above: a change to the Developer API routing, a change to the Cloud retirement dates, a price change on either line, a change to the thinking levels or the default, a new independent measurement, a change to the computer-use surface or its safeguards, and a successor that removes the support-window case. In any case, re-check within six months while the Cloud endpoint remains available, because the 3.x Flash line has changed every few weeks.



Comments