
GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30

Status: Risky | Last tested: 2026-11-14 (GPT-5.5, gpt-5.5, released 2026-04-23) | Re-check: trigger-based (max 6 months)
Risky: the tool has significant unresolved issues, or it has been clearly surpassed by newer alternatives. Use it with caution and read the Limits section.
For detailed explanations of the CI-First evaluation terms used in this review, including the CI-First Benefit Score, the CI-First Profile, the Humics Protection Badge and the AI Imposture Risk levels, see the Glossary at the end of this post.

In this Tool Review

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
The name, the four GPT-5.5 products and the model this review does not replace
Five names carry the number 5.5 in OpenAI's catalogue, and only one of them is the subject of this review. The distinction matters because a buyer searching for "GPT-5.5" will meet a pro model at six times the price, a pinned snapshot, a cyber-permissive variant that is being retired in February 2027, and a successor family that already costs less.
Name | What it is | Where it appears |
GPT-5.5 | The model this review scores. Model id `gpt-5.5`, released 2026-04-23, available through the Responses and Chat Completions APIs, Batch, and Amazon Bedrock as `openai.gpt-5.5`. | The model page, the pricing page, the launch post of 2026-04-23, the full model catalogue and the deprecations page |
`gpt-5.5-2026-04-23` | The only published snapshot, and the default for the `gpt-5.5` alias. A team that needs fixed behaviour should pin this string rather than the alias. | The model page's snapshots list |
GPT-5.5 Pro | A separate model, id `gpt-5.5-pro`, priced at $30 per million input tokens and $180 per million output tokens. It is not a setting on `gpt-5.5` and this review does not score it. | The model catalogue and the launch post |
`gpt-5.5-cyber-preview` | A separate cyber-permissive model distributed under OpenAI Daybreak. It is marked Deprecated with a shutdown date of 2027-02-01 and a notice date of 2026-11-05. It is not `gpt-5.5` with a flag. | The deprecations page |
GPT-5.6 Sol | The successor, id `gpt-5.6-sol`, released 2026-07-09. It adds a `max` effort level, moves the knowledge cutoff to 2026-02-16, and is priced at $4 and $20 per million tokens on promotional rates that the vendor says run until 2026-11-30. | The GPT-5.6 Sol model page, the pricing page, Artificial Analysis |
The model id is confirmed, not adapted. OpenAI documents the identifier as `gpt-5.5`, with the dated snapshot `gpt-5.5-2026-04-23` and the Bedrock identifier `openai.gpt-5.5`. The hypothesis this review began with was correct, and no spelling was changed to fit it. The identifier is a dotted decimal, unlike Anthropic's hyphenated ids, and a search that substitutes a hyphen for the second dot will land on nothing.
The vendor still lists this model as available, and U365 does not recommend it for new work. Both statements are true and they answer different questions. OpenAI's deprecations page, read in full on 2026-11-14, carries no retirement notice for `gpt-5.5` or `gpt-5.5-pro`; the model page publishes current prices, current endpoints and a current snapshot; and the model sits in the full catalogue that also lists GPT-6.1 Sol. That is the vendor's lifecycle, and it is Active. U365's status badge asks a different question, whether a reader should build on it now, and the answer is no: its own successor is cheaper and more capable, a newer sibling costs a fifth of it per output token, and the model has been overtaken twice in seven months. The badge is Risky for that reason, and the review states the vendor's position beside it rather than instead of it.
A secondary report in September said the model would be retired on 2026-10-14, and the vendor's own page does not carry that notice. The report was a trade publication, not OpenAI, and the deprecations page read on 2026-11-14 lists neither a shutdown date nor a notice for `gpt-5.5`, while the model page still serves prices and endpoints. This review treats the vendor's documentation as the authority and records the discrepancy rather than resolving it in the vendor's favour or against it. A team with a production dependency should read the `shutdown_date` field on the model record returned by the API before it plans beyond the next quarter.
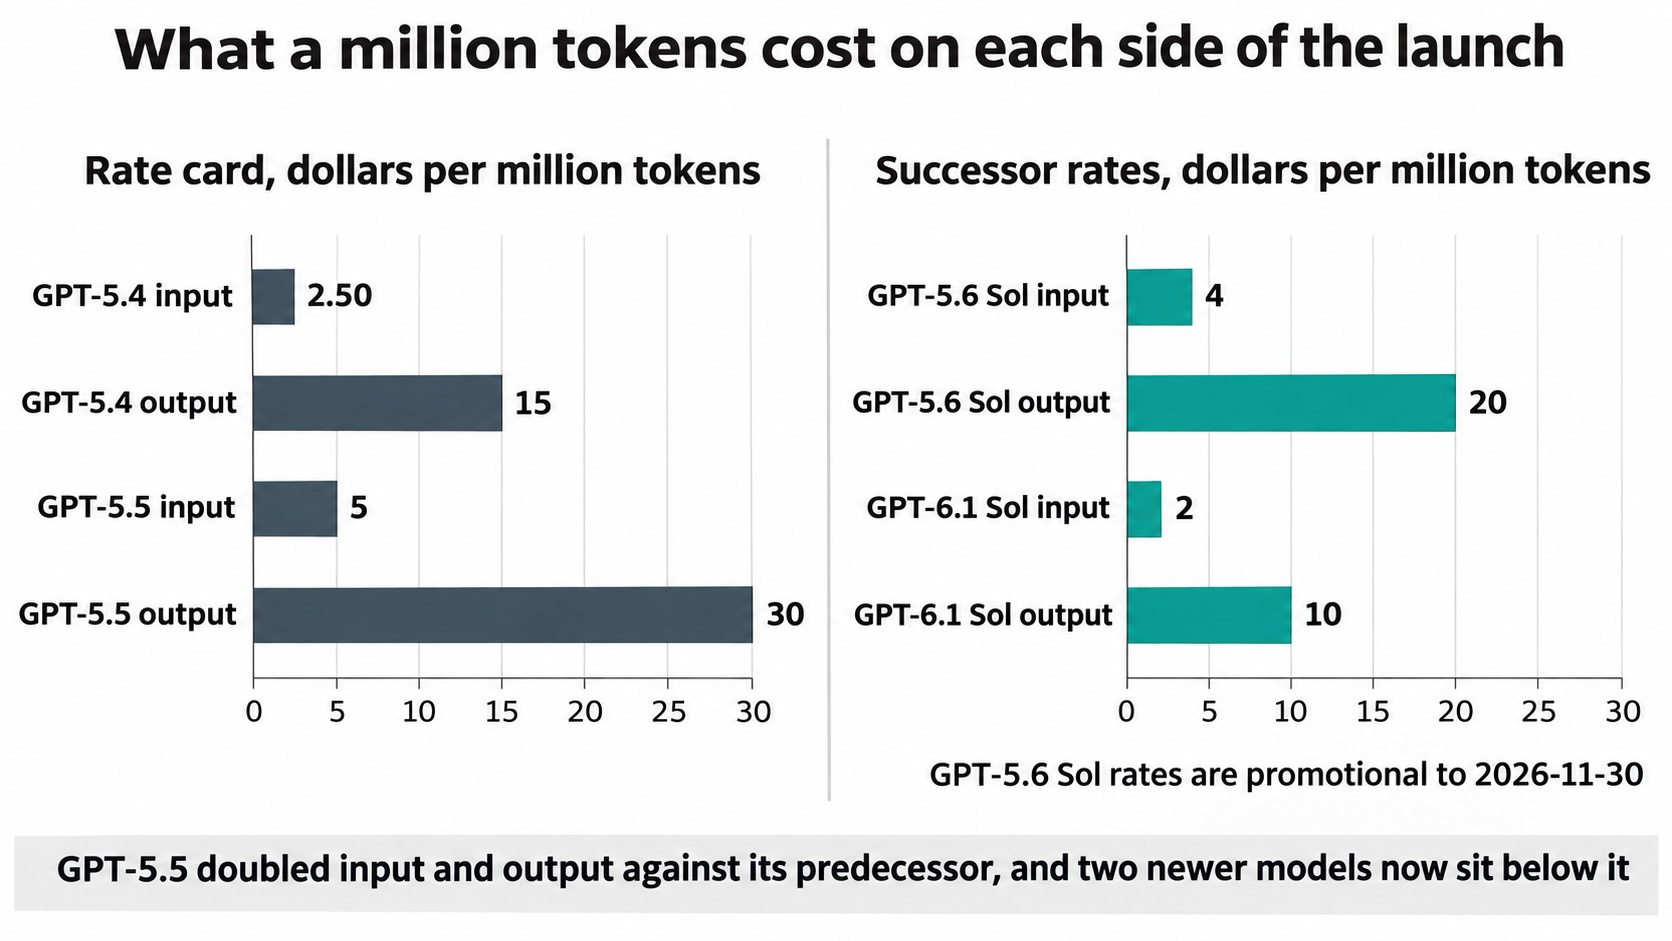
The price did not fall, and that is the whole commercial story. GPT-5.5 launched at $5 per million input tokens, $0.50 cached and $30 output, against GPT-5.4 at $2.50, $0.25 and $15. Seven months later the GPT-5.5 rate card is unchanged, the successor's promotional rate is $4 and $20, and the newer GPT-6.1 Sol is $2 and $10. A model that was priced at twice its predecessor to pay for a capability jump now sits above two models that are newer and, on the vendor's own rows, stronger. The rate card is the reason this review exists in the form it does.
What this review is. It is the U365 scoring of GPT-5.5 under the CI-First Evaluation Framework, version 1.4.1, on evidence read on 2026-11-14: the vendor's launch post, model page, pricing page, deprecations page, model guidance and system card; the independent measurements published by Artificial Analysis across five effort settings; the Hacker News launch thread of 2026-04-23 and four later threads that carry the production record; and the published U365 scores of the models this one is compared against.
What this review is not. It is not a review of ChatGPT, of Codex, of GPT-5.5 Pro, of `gpt-5.5-cyber-preview`, of Amazon Bedrock or of Microsoft Azure. Those surfaces appear where a scored fact depends on them. It is not a re-score of GPT-5.4, although it records the movement against that review. It is not a review of GPT-5.6 Sol or GPT-6.1 Sol, each of which has its own document in the U365 library. And it is not an assessment of OpenAI's safety programme beyond the facts a buyer of this model has to carry, which are stated in Section 7c with their sources named.
The score moved up by 0.2 against the predecessor, and the movement is one dimension. GPT-5.4 published at 5.8 with sub-scores 7 / 6 / 6 / 4. GPT-5.5 scores 6.0 with 7 / 6 / 7 / 4. Quality gains one point, because the model is measurably better than its predecessor on every benchmark row where both were tested, and Time and Quantity hold where they were. The 0.2 is small on purpose: a model that is better than the one before it, and worse value than the one after it, has bought a real capability gain and spent it on a price rise.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Tool Snapshot
GPT-5.5 is OpenAI's April 2026 flagship: a reasoning model that was the strongest agentic coding and computer-use model of its release week, sold at twice its predecessor's token price, still available at that price in November 2026, and superseded twice by cheaper models from the same vendor.
Category: Applied AI / Large Language Model. Agentic coding, computer use, knowledge work, document and spreadsheet production, tool use across the Responses API, and long-context analysis. It sat at the top of the OpenAI line in April 2026 and sits below GPT-5.6 Sol, GPT-6 Sol, GPT-6.1 Sol and GPT-6 Astra in the November 2026 catalogue.
Primary use cases:
Agentic coding on a bounded task, with a test suite as the finish line. The vendor reports 82.7 percent on Terminal-Bench 2.0 against 75.1 for GPT-5.4 and 69.4 for Claude Opus 4.7, and 58.6 percent on SWE-Bench Pro. Independent measurement records 84.27 percent on Terminal-Bench 2.1 at `xhigh`, which is consistent with the vendor's row on a later version of the test.
Computer use and tool chains. OSWorld-Verified at 78.7 percent against 75.0 for GPT-5.4, MCP Atlas at 75.3 against 70.6, Tau2-bench Telecom at 98.0 without prompt tuning, and a tool list that runs from web search and file search to hosted shell, apply patch, skills, computer use and MCP.
Knowledge work that ends in a document, a spreadsheet or a slide deck. GDPval at 84.9 percent wins or ties, OfficeQA Pro at 54.1, FinanceAgent v1.1 at 60.0 and an internal investment-banking modeling set at 88.5. The vendor's own internal examples run from a K-1 review of 24,771 forms to a weekly reporting job that saved five to ten hours.
Long-context analysis. A 1,050,000-token context window and 128,000 output tokens, with MRCR v2 eight-needle recall at 81.5 percent in the 256K to 512K band and 74.0 percent in the 512K to 1M band, against 57.5 and 36.6 for GPT-5.4. The long-context prices above 272,000 input tokens are the condition that travels with it.
A pinned baseline for an evaluation or a regulated workflow. The snapshot `gpt-5.5-2026-04-23` is fixed, the behaviour is documented, and a team that has calibrated a test suite to it can keep running that suite while it migrates. This is the one use where the model still has an advantage that a newer model cannot take away, and it is a cost of change rather than a capability.
What it is not. It is not the current OpenAI flagship: GPT-6 Astra is, with GPT-6.1 Sol as the near-flagship at $2 and $10. It is not the best value in its own family: GPT-5.6 Sol is cheaper on promotional rates and adds a `max` effort level, and GPT-6.1 Sol is cheaper again. It is not a model for new long-horizon work where the newest generation is available, because the later models have moved the knowledge cutoff and the effort ceiling past it. It is not open weights, not self-hostable and not auditable from outside OpenAI's service. It is not an image, audio or video generator, and it reads images to produce text. And it is not a teacher: nothing in the product moves a capability from the model to the reader.
Pricing, as published on 2026-11-14:
Line | Rate per million tokens | Note |
Input, prompts up to 272K tokens | $5.00 | Twice the GPT-5.4 input rate |
Output, prompts up to 272K tokens | $30.00 | Twice the GPT-5.4 output rate |
Cached input, prompts up to 272K tokens | $0.50 | Ten percent of the input rate |
Input, prompts over 272K tokens | $10.00 | 2x the standard input rate for the whole request |
Output, prompts over 272K tokens | $45.00 | 1.5x the standard output rate for the whole request |
Cached input, prompts over 272K tokens | $1.00 | 2x the standard cached rate |
Batch and Flex | 50 percent off | Asynchronous and lower-priority processing |
Priority processing | 2.5x the standard rate | The other direction on the same dial |
Regional processing | 10 percent uplift | Data residency endpoints |
Fast mode in Codex | 2.5x cost for 1.5x speed | A Codex plan setting rather than an API rate |
The 272,000-token line is the number to read twice. It is not a marginal rate on the tokens above the threshold; a request whose prompt crosses it pays double on input and one and a half times on output for the whole request, including the tokens below the line. A 300,000-token prompt therefore costs $3.00 in input at the long-context rate against $1.50 at the standard rate, and an agent that re-sends a long context across twenty turns pays the difference twenty times.
Official links:
Launch post: https://openai.com/index/introducing-gpt-5-5/
Model page: https://developers.openai.com/api/docs/models/gpt-5.5
Model guidance: https://developers.openai.com/api/docs/guides/latest-model?model=gpt-5.5
API pricing: https://developers.openai.com/api/docs/pricing
Business pricing: https://openai.com/api/pricing/
Deprecations: https://developers.openai.com/api/docs/deprecations
Full model catalogue: https://developers.openai.com/api/docs/models/all
System card: https://deploymentsafety.openai.com/gpt-5-5
Preparedness Framework: https://cdn.openai.com/pdf/18a02b5d-6b67-4cec-ab64-68cdfbddebcd/preparedness-framework-v2.pdf
Trusted Access for Cyber: https://openai.com/index/scaling-trusted-access-for-cyber-defense/
Codex memories: https://learn.chatgpt.com/docs/customization/memories
Codex documentation index: https://developers.openai.com/codex/llms.txt
Status page: https://status.openai.com
LLM-specific fields:
API model identifier: `gpt-5.5`. Pinned snapshot: `gpt-5.5-2026-04-23`. Amazon Bedrock: `openai.gpt-5.5`. The pro model is a separate id, `gpt-5.5-pro`.
Context window: 1,050,000 tokens. Maximum output: 128,000 tokens. Artificial Analysis measures a 922,000-token usable context, which is the same figure OpenAI publishes as the maximum input for its successor and is the number a retrieval design should use.
Modalities: text and image input, text output. No audio, no video, no generated images through this model id.
Reasoning effort: `none`, `low`, `medium` (the default), `high` and `xhigh`. There is no `max` level on this model; the successor adds one.
Knowledge cutoff: 2025-12-01, stated on the model page. Launch-day users reported the model answering with a June 2024 cutoff, which is a discrepancy in the record and not a vendor statement.
Endpoints: Responses and Chat Completions supported; Batch supported; Assistants, fine-tuning, embeddings, image generation, speech and transcription not supported on this model.
Tools: function calling, web search, file search, tool search, image generation, code interpreter, hosted shell, apply patch, skills, computer use and MCP.
Long context: prompts above 272K input tokens are priced at 2x input and 1.5x output for the whole request.
Regional processing: 10 percent uplift on data-residency endpoints.
Codex: 400,000-token context on plan surfaces, against 1,050,000 through the API, and a Fast mode at 2.5x cost for 1.5x speed.
Lifecycle: Active at the vendor, with no retirement notice on the deprecations page read on 2026-11-14. U365 status: Risky, for the reasons in the naming section.
License: proprietary hosted service. No weights, no parameter count, no architecture disclosure.
At a Glance Dashboard
Field | Value |
Category | Applied AI / Large Language Model (agentic coding, computer use, knowledge work and document production) |
CI-First Benefit Score | 6.0 / 10 (CI-First Positive) |
Sub-scores | Time 7 / Quantity 6 / Quality 7 / Skill 4 |
CI-First Profile | Primary: Co-Worker and Assistant (level 2). Secondary: Co-Researcher, Analyst and Tester (level 4), Co-Creator and Thought Partner (level 1) |
Humics Protection | Humics-Neutral (-1 / +3) |
AI Imposture Risk | Medium overall, with Skill Illusion High |
Status | Risky (vendor lifecycle: Active, superseded in the line-up) |
Last tested | 2026-11-14 |
Released | 2026-04-23 |
Access | OpenAI API (Responses, Chat Completions, Batch), Amazon Bedrock, Microsoft Azure, ChatGPT and Codex on paid plans |
Price | $5.00 input, $0.50 cached, $30.00 output per million tokens; 2x input and 1.5x output above 272K prompt tokens; batch and flex at half rate |
Context window | 1,050,000 tokens in, 128,000 tokens out; 400,000 in Codex on plan surfaces |
Effort levels | `none`, `low`, `medium` (default), `high`, `xhigh`; no `max` |
Framework comparison with siblings and peers | GPT-5.4 5.8 (CI-First Positive); GPT-5.6 Sol 6.0 (CI-First Positive); GPT-6.1 Sol 6.3 (CI-First Strong); GPT-6 Astra 7.0 (CI-First Strong); Claude Sonnet 5.5 7.0 (CI-First Strong) |
Benchmarks, one line each | Vendor: 82.7 percent on Terminal-Bench 2.0, 58.6 on SWE-Bench Pro, 84.9 on GDPval, 78.7 on OSWorld-Verified, 98.0 on Tau2-bench Telecom, 85.0 on ARC-AGI-2. Independent: 84.27 percent on Terminal-Bench 2.1 at `xhigh`, GDPval Elo 1357 at `xhigh`, Tau2 93.9 percent at `xhigh`; no composite Intelligence Index is published for this model under the current index |

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
The Problem
The problem a reader faces in November 2026 is not whether GPT-5.5 is good. It is whether a good model from April is worth its April price when the vendor has since shipped two cheaper models that do more.
Five problems sit in front of that reader, and the first is arithmetic.
The first is that the price did not move while the line moved past it. GPT-5.5 costs $5, $0.50 and $30 per million tokens. GPT-5.6 Sol, released 2026-07-09, costs $4, $0.40 and $20 on promotional rates the vendor says run to 2026-11-30, and the stated size of that cut, 20 percent on input and 33 percent on output, implies a list price of $5 and $30, which is where GPT-5.5 already sits. GPT-6.1 Sol, released 2026-09-29, costs $2, $0.10 and $10. A buyer comparing three OpenAI models on the pricing page sees the oldest one carrying the highest output rate of the three, and the only question left is whether its behaviour is different in a way the buyer needs.
The second is that the effort ladder was the product, and the successor extended it. GPT-5.5 runs five settings, from `none` to `xhigh`, and the independent component scores show how much of the model's quality lives in that choice: GDPval Elo runs from 978 in the non-reasoning setting to 1357 at `xhigh`, and Terminal-Bench 2.1 from 61.05 percent to 84.27 percent. GPT-5.6 Sol adds `max` above `xhigh`, and the newer GPT-6 family carries the same five-or-six-level ladder. A reader who wants the top of the ladder cannot reach it on GPT-5.5 at all.
The third is that the long-context price is a cliff, not a slope, and agent work crosses it. A prompt above 272,000 input tokens pays double on input and 1.5 times on output for the whole request. The window is advertised at 1,050,000 tokens, and the pricing page states the condition in one line. A document set that fits the window comfortably can therefore cost twice what a reader budgeted, and the difference is larger than the gap between GPT-5.5 and its successor on the headline rate. The launch-day thread contains the arithmetic from a reader who priced it at $5 and $10 input and $30 and $45 output across the line, and concluded that the model is significantly more expensive than the competitor beyond 272K.
The fourth is that the production record contains a specific defect and a quality dispute, both dated after launch. In July 2026 a detailed community analysis reported that GPT-5.5 in Codex clusters its reasoning output at fixed values spaced about 518 tokens apart, that the clustering correlates with errors on complex tasks, and that it is much less common on GPT-5.4 and almost absent on earlier models. In June 2026 a widely read thread reported that GPT-5.5 hallucinates about three times as often as an open-weight model on one evaluation, a claim whose metric is conditional on the model not knowing the answer and therefore not a general hallucination rate. Neither is a U365 measurement. Both are in the record a buyer is entitled to see, and both are cited in this review with their limits attached.
The fifth is that the lifecycle is ambiguous in a way that costs a team real money. OpenAI's deprecations page carries no retirement notice for `gpt-5.5`; a September trade report said the model would be retired on 2026-10-14; and the model is still in the catalogue with current prices on 2026-11-14. A team that reads only the trade report plans a migration it may not need. A team that reads only the catalogue may keep a dependency the vendor has already superseded. The honest position is to check the model record's `shutdown_date` and to treat the pinned snapshot as the only stable commitment.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
The Outcome
What changes for a reader who keeps GPT-5.5, what changes for one who moves, and what does not change either way.
Keeping it costs more per unit of work than moving, on the vendor's own rate card. $5 and $30 against $4 and $20 on the successor's promotional rate, and against $2 and $10 on GPT-6.1 Sol. A workload that spends $1,000 a month on GPT-5.5 output would spend about $667 on GPT-5.6 Sol at the promotional rate and about $333 on GPT-6.1 Sol, before any difference in tokens per task.
The successor adds a ceiling this model does not have. GPT-5.6 Sol supports `none`, `low`, `medium`, `high`, `xhigh` and `max`, moves the knowledge cutoff from 2025-12-01 to 2026-02-16, and publishes a 1,050,000-token context with a 922,000-token maximum input. On the work where a reader wants the last increment of reasoning, GPT-5.5 has no setting to offer.
The quality gap is real but not the reason to move. GPT-5.5's launch rows were strong and are independently corroborated: 84.27 percent on Terminal-Bench 2.1 at `xhigh` and a GDPval Elo of 1357 are not vendor numbers. The move is justified by price and by the ceiling, not by a claim that the older model cannot do the work.
The stability case is narrower than it sounds. A pinned snapshot does not change under you, which is worth something in a regulated workflow or a calibrated evaluation. It does not protect you from the vendor's retirement schedule, from a change in the surrounding API, or from the cost of the re-baselining you are postponing. Continuity is a reason to sequence a migration, not a reason to start new work here.
The long-context economics improve on the successor, and the cliff stays. GPT-5.6 Sol carries the same 2x input and 1.5x output rule above 272K, so the cliff is a family property rather than a GPT-5.5 defect. What improves is the base rate under it.
What does not change is the shape of your work. You state the task and the finish line, choose an effort level, read the output and verify it against something outside the conversation. The Skill sub-score of 4 says that plainly, and a newer model does not change it.
The status changes even if the score barely does. The score rises 0.2 against GPT-5.4 because the model is better. The badge moves to Risky because the model is no longer the one to buy. A reader who takes one thing from this review should take the distinction between those two sentences. ---

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Who Should Use GPT-5.5
Learner type | Difficulty | Typical ROI | Career path |
Students (Bachelor, Master) | Intermediate | A capable agentic model with a documented free-to-low-cost path through ChatGPT plans and a paid API, and a poor first purchase in November 2026 because the same vendor sells a cheaper model that does more. Its honest use for a student is as a study object: the launch post, the deprecations page and the independent measurements together show how a flagship ages, and that lesson survives the tool. Strong for a bounded coding exercise with a test suite and for a document set that has to become a structured summary. The Skill Illusion is the live risk, because the output reads as finished whether or not it is correct. | UIT (Technology, AI, Data Science) for agentic coding practice and benchmark reading, and UIC (Digital Communication, Marketing) for the document work. No published U365 credential assesses model routing or evaluation design as a named component, and none is asserted. |
Professionals (career upskilling) | Intermediate | The case is now a migration case rather than an adoption case. Engineers who own a GPT-5.5 integration get a clear return from running it while they re-baseline on GPT-5.6 Sol or GPT-6.1 Sol, and a poor return from extending it. Analysts producing documents from a source set get a strong first draft and a bill that is 50 to 100 percent higher than the successor's promotional rate. | UIT (Technology, AI, Data Science) engineering tracks for agent supervision and evaluation, and UIB (Business Management, Entrepreneurship) for the cost-per-completed-task case. The model supplies no management method of its own. |
Everyone (lifelong learners) | Beginner in ChatGPT, Intermediate on the API | A million-token window, a 128,000-token output ceiling and a tool list that covers search, files, code and computer use make it a capable assistant for a non-specialist. It is not the model to start on in November 2026: the cheaper siblings are easier to recommend, and the model's effort ladder and long-context pricing are traps for a reader who has not met them before. | LIPS Collect and Review phases for the reading and drafting work, and the UP-Context-Engineering Method order for prompting. UNOP fit is weak, because the model produces rather than teaches. No assessment home is asserted. |
For teams and organisations. The model is sold to companies as well as to individuals, and a team deciding on it in November 2026 starts with four questions.
Team deployment. Reachable through the OpenAI API on the Responses and Chat Completions endpoints, through Batch, through Amazon Bedrock as `openai.gpt-5.5`, through Microsoft Azure, and through ChatGPT and Codex on paid plans. Codex runs the model with a 400,000-token context rather than the API's 1,050,000, and its Fast mode trades 2.5x cost for 1.5x speed. A team standardising on the API and a team standardising on Codex are buying different context limits under the same model id.
Cost at team scale. Three lines move independently: the seat, the tokens and the context length. On tokens, $5 and $30 sit above the successor's promotional $4 and $20 and above GPT-6.1 Sol at $2 and $10. On context, a prompt above 272,000 input tokens pays 2x input and 1.5x output for the whole request, which is the line an agent that re-sends a long context will cross without anyone deciding to cross it. On processing, batch and flex halve the rate and priority multiplies it by 2.5, and regional processing adds 10 percent. One benchmarking firm reported in May 2026 that GPT-5.5 was about 1.5 to 2 times more expensive per completed engineering task than GPT-5.4, and a second measured about 3.5 times on its own suite. A team that budgets from the rate card alone will under-count.
Data and compliance. Enterprise deployments run under OpenAI's business terms, and the model is available on regional-processing endpoints at a 10 percent uplift for a team that has to keep inference in a named geography. The model is proprietary, is not self-hostable and publishes no weights, so a compliance review can establish what the vendor states and cannot inspect the model. A team that needs a zero-retention or in-region commitment should settle it with the vendor before the pilot rather than after.
U365 for companies. Professional learners reach University 365's academic services individually or through their organisation, and the company route runs through a customized training agreement for employee groups. Corporate education programmes are built on demand, and their tuition follows content and duration.
Skill level required: Intermediate. Driving this model well means scoping the task before the prompt, choosing an effort level deliberately, watching the 272,000-token line, and reading the output against something outside the conversation. The model will run without any of that, and the result will look finished either way.
Prerequisites. For ChatGPT and Codex, a paid plan that includes the model. For the API, an account with billing, a decision about the effort level each job runs at, and a decision about whether any job will cross the long-context threshold. For a pinned deployment, the snapshot string `gpt-5.5-2026-04-23` rather than the alias. Working knowledge of prompt structure and verification practice, because output at this level reads as finished whether or not it is correct.
Typical time to first result: Under five minutes in ChatGPT on a plan that includes the model. Under fifteen minutes on the API for a first call with the model id `gpt-5.5` at the default `medium` effort.
Typical time to competence: Ten to twenty hours of active use. Three skills carry most of the value: scoping, because the model is at its best on work small enough to check; effort selection, because the same task ranges from a 1.68-second non-reasoning answer to a 39.55-second `xhigh` run and from a GDPval Elo of 978 to 1357; and migration reading, because the useful question about this model in 2026 is what replaces it and at what price.
Who should not adopt it. Anyone starting a new integration, because GPT-5.6 Sol is cheaper on promotional rates, adds a `max` effort level and moves the knowledge cutoff two and a half months forward. Anyone whose volume is high enough for GPT-6.1 Sol's $2 and $10 to matter. Anyone who needs the newest knowledge or the top of the reasoning ladder. And anyone who cannot yet check a fluent document against its sources, because this is a model that will hand them one.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
U365 Institutes Alignment
The alignment below rates what a U365 institute could take from this model as a working instrument and as an object of study. The primary home is UIT (Technology, AI, Data Science), because agentic coding, computer use, effort policy and evaluation reading are the competencies this model exercises, and because a flagship that was priced at twice its predecessor and then superseded twice is itself a teaching object about how fast a model line moves. The other three readings are real and each is bounded. This is a superseded generation, and the alignment below is not a recommendation to adopt it: a Fellow starting new work begins on GPT-5.6 Sol or GPT-6.1 Sol, both cheaper, and uses GPT-5.5 as a study object and as the baseline a migration is measured against. Each row names what a Fellow still takes from this version, which is the question a legacy review has to answer.
UIT (Technology, AI, Data Science)
Rating. High (primary)
Why. Three competencies, each of which survives the removal of the tool. Agentic coding on a bounded task: state the finish line, name the tests, bound the paths, read the report before the diff. The vendor's rows make this a real exercise rather than a toy one, at 82.7 percent on Terminal-Bench 2.0 and 58.6 on SWE-Bench Pro, and the independent Terminal-Bench 2.1 figure of 84.27 percent at `xhigh` gives a student a second measurement to compare against the first. Effort policy: knowing that the same model runs from a GDPval Elo of 978 with no reasoning to 1357 at `xhigh`, that the default is `medium`, and that the choice belongs to the task. Model lifecycle: reading a deprecations page, a catalogue and a trade report that disagree, and deciding what to build on, is the evaluation skill this review exists to teach.
The limit that holds the row. The model is a service a practitioner operates, not an artefact a practitioner inspects. There are no weights, no parameter count and no architecture description, so the competencies are engineering-with rather than engineering-of. The catalogue's AI-agent instruction sits in the certificate and diploma series rather than in the degree paths: five published programmes carry `agent`, one carries `agentic` and six carry `prompt`, and 0 of the 20 degree programmes carry any of the three in title or description. No published programme assesses effort policy or model lifecycle as a named component. Adjacent anchors, not assessment homes.
UIB (Business Management, Entrepreneurship)
Rating. Medium
Why. Two decisions the release forces that are commercial before they are technical. Model selection with a published price and a hidden cost curve: the rate card says $5 and $30, the long-context line says double above 272,000 tokens, and two independent benchmarking firms reported per-task costs of about 1.5 to 2 times and about 3.5 times the predecessor. A business case built on the rate card alone is a case built on the wrong number, and that gap is a live exercise a cohort can run on published figures. And migration: a team that keeps a superseded model because it is already integrated is making a cost-of-change decision, and the exercise is to price that decision against the successor's rate.
The limit that holds the row. The model supplies no management method and does not measure its own return. It publishes no completion rate and no time-per-task figure outside the vendor's benchmark selection. No published U365 programme assesses the economics of a model portfolio as a named component: 0 of the 81 published programmes carry `portfolio`, `return on investment`, `cost` or `price` in title or description. Adjacent anchors, not assessment homes.
UIC (Digital Communication, Marketing)
Rating. Low to Medium
Why. One competency a communications Fellow keeps, and one surface that is real at a price. Reading a benchmark claim as a communication act: the launch material reports GDPval at 84.9 and OfficeQA Pro at 54.1 among its knowledge-work rows, and a team that repeats those numbers in a proposal without the comparison set is doing vendor relations rather than measurement. Telling a measured claim from a framing claim survives the model. The drafting surface is the second: a million-token window holds a campaign archive, a brand guide and a set of drafts in one session, and 128,000 output tokens let a long deliverable arrive in one pass. What has moved against it is the price, because the output rate is three times GPT-6.1 Sol's, so a team that drafts at volume runs the same brief on the successor before it standardises here.
The limit that holds the row. The model teaches no register, no audience analysis and no publication standard. It returns no sourced evidence of its own, so fact-checking stays with the writer, and nothing in it assesses a layout or a campaign. Rated as a drafting surface with a reading contact. No credential is mapped.
UID (Digital Design, UX/UI)
Rating. Low to Medium
Why. The production use is interface code. The model's agentic coding strength extends to front-end work, a build or a screenshot check decides whether the output is right, and a design student can produce variants fast enough that comparison becomes the work. Two reading contacts sit beside it. Image input is the measured one: MMMU Pro at 81.2 without tools and 83.2 with tools gives a student a way to ask about a layout that already exists. The second is the vendor's browser-based 3D app built from a reference image, a presentational task a cohort can reproduce. The band rests on the production use rather than on the reading contacts.
The limit that holds the row. The model generates no images and evaluates no design against a brief. It reads images and produces text, so the visual surface is input only, and a student who wants a critique of a layout is asking for a judgement the model cannot ground. Rated as interface-code production and presentation support. No credential is mapped.
U365 methods, not an institute (UNOP, ULM, LIPS, CARE and the UP-Context-Engineering Method)
Rating. Applicable
Why. The methods layer is relevant in the way a legacy model is. Version pinning is a LIPS decision before it is a procurement decision: the snapshot string, the date it was frozen and the reason belong in the project record, because the alias can move and the vendor's retirement schedule can change. The UP-Context-Engineering Method's context, role, task, constraints and output order is what makes a run reproducible when the same prompt can be run at five settings and three prices. The constraints part matters more here than usual, because the long-context cliff and the effort ladder both let a run spend more than the task deserves. The decision about which work is worth automating belongs in Career and Finance and in Quality of Life, and ULM is the six-domain frame that holds that decision; cost per completed task is CI-First cost engineering and the independent evaluator's metric, not a ULM method. UNOP has no direct fit: the model is not built to teach, it claims no teaching mode, and its Skill sub-score of 4 records that a user learns less by working with it.
The limit that holds the row. The model carries no method of its own and no coaching surface. A Fellow who does not write the version, the effort decision and the verification result into their own system has no account of them, and nothing in the product writes that account.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
How GPT-5.5 Works
A reasoning model with five effort settings and no top-level ceiling, a 1.05-million-token window with a pricing cliff at 272,000 tokens, and a tool surface broad enough to run an agent loop from search to shell to computer use.
Inputs: Text prompts, documents and images; through the API, a conversation history, tool definitions, file uploads and cached prompt prefixes. Through Codex, a repository, its instruction files and any rulebook you have written. The model reads text and images and produces text.
Outputs: Text, code, structured outputs and tool calls, and through agent surfaces, edits to files. Up to 128,000 tokens in a single response, inside a context window of 1,050,000 tokens, with a practical input ceiling that Artificial Analysis measures at 922,000 tokens. Independent measurement records output speeds of 73 tokens per second at `xhigh`, 69 at `high`, 70 at `medium`, 61 at `low` and 62 in the non-reasoning setting.
Underlying technology, as the vendor publishes it:
Model: GPT-5.5, model id `gpt-5.5`, snapshot `gpt-5.5-2026-04-23`, released 2026-04-23. The model was trained with and served on NVIDIA GB200 and GB300 NVL72 systems, and the vendor attributes part of its latency work to load-balancing heuristics written with Codex.
Reasoning effort: `none`, `low`, `medium` (default), `high` and `xhigh`. The default moved up from GPT-5.4, whose default was `none`.
Context and output: 1,050,000 tokens in, 128,000 out, with knowledge cutoff 2025-12-01.
Price: $5 input, $0.50 cached and $30 output per million tokens, with 2x input and 1.5x output above 272,000 prompt tokens, batch and flex at half rate, priority at 2.5x and regional processing at a 10 percent uplift.
Tools: function calling, web search, file search, tool search, image generation, code interpreter, hosted shell, apply patch, skills, computer use and MCP.
Endpoints: Responses, Chat Completions and Batch. No fine-tuning, no Assistants, no embeddings and no audio on this model.
Safeguards: Preparedness Framework High capability in cybersecurity and in biological and chemical capability, both below Critical; expanded cyber classifiers; Trusted Access for Cyber for verified defenders; external testing by CAISI and Irregular.
Codex: a 400,000-token context on plan surfaces, and a Fast mode that trades 2.5x cost for 1.5x speed.
What is not disclosed. No parameter count. No weights. No architecture description. No per-effort token budget, because effort is a named level rather than a number. No statement that would let a buyer audit what the model does internally. The clause assessment below turns on what ships on the surfaces, not on anything inside the model.
The effort ladder is where the model's quality actually lives. The vendor's headline rows were all run at `xhigh` in a research environment, and the independent component scores show what happens below that: GDPval Elo 1357 at `xhigh`, 1335 at `high`, 1242 at `medium`, 1053 at `low` and 978 with no reasoning; Terminal-Bench 2.1 at 84.27, 79.40, 80.52, 65.54 and 61.05 percent on the same five settings. A reader who runs the default `medium` is buying a materially different model from the one in the launch table, and that is not a defect; it is the design, and it is the reason the effort decision belongs to the task.
Two pricing behaviours change how a run should be built. The first is the 272,000-token cliff, which prices a request at 2x input and 1.5x output for the whole request once the prompt crosses it. The second is the processing dial: batch and flex halve the rate, standard is the list rate, priority multiplies it by 2.5. The same task can therefore be bought at four prices without any change to the model, and an agent that re-sends a long context twenty times multiplies whichever price it chose.
What changed against GPT-5.4, stated as facts a builder has to handle. The default effort moved from `none` to `medium`, so an unchanged request now reasons where it previously did not, and the bill moves with it. The price doubled on input and output. The context window, the output ceiling and the tool list are unchanged. The knowledge cutoff moved from 2025-08-31 to 2025-12-01. And the model added `xhigh` behaviour that the predecessor also had, but with a larger measured quality spread between the bottom and the top of the ladder.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Getting Started with GPT-5.5
Required accounts: A ChatGPT or Codex plan that includes the model, or an OpenAI API account with billing. An Amazon Bedrock or Microsoft Azure account with the model enabled in the region you use, if that is the route.
Installation: Nothing to install for ChatGPT. For Codex, the CLI, IDE extension or desktop app, with the model selected in the session. For the API, nothing beyond an HTTP client or an official SDK, with the model selected by the id `gpt-5.5` and pinned with `gpt-5.5-2026-04-23` where stability matters.
First-time configuration:
Decide the effort level by task, before the first prompt. Five positions, with `medium` as the default. The independent component scores put the same model at a GDPval Elo of 978 with no reasoning and 1357 at `xhigh`, and at 61.05 against 84.27 percent on Terminal-Bench 2.1. A run that needs the top of that range has to ask for it.
Price the prompt before you send it. A prompt above 272,000 input tokens pays 2x input and 1.5x output for the entire request. Count the tokens of the system prompt, the documents and the tool definitions together, and decide whether to trim, to chunk, or to accept the long-context rate.
Choose the processing tier on purpose. Batch and flex halve the rate and slow the answer; priority multiplies it by 2.5. A nightly job and an interactive agent should not share a setting by default.
Pin the snapshot in any system that has to stay stable. The alias `gpt-5.5` resolves to `gpt-5.5-2026-04-23` today. A pinned string is a commitment the vendor can still retire, but it does not move underneath you before then.
Put the model behind a router if you run more than one OpenAI model. The 5.5, 5.6 and 6.x lines differ in price, effort ladder and knowledge cutoff, and a single hard-coded model id will be the wrong one for part of the work within a quarter.
Handle a refusal or a safeguard response as a distinct outcome. The cyber and biological classifiers can stop a request, and the Trusted Access route exists for verified defenders. Branch on the response rather than parsing a refusal as an answer.
Decide what Codex memories do before your team uses the surface. The vendor documents local Codex memories as off until a person enables them, then written from eligible prior chats into local files under the Codex home directory. Read the documentation, decide whether that is acceptable for the repository, and write the decision down, because it is the mechanism behind the clause note in Strengths, Limits, and AI Imposture Risk.
Put the first task on a surface where you already own the check. A test suite, a validator, a schema, a quote table. The model's strongest measured rows are agentic coding, computer use and document production, and all three are cheap to check when the check exists before the run.
First 15 minutes checklist:
☐ Run one real task from your own work at `medium`, with a stated finish line and a stated stopping rule.
☐ Run the same task at `xhigh`, and compare the answer, the wait and the token count. Write both costs down.
☐ Take one prompt over 272,000 tokens, price it at both the standard and the long-context rate, and decide whether the window is worth the cliff for that job.
☐ Confirm your code pins a snapshot if it needs stable behaviour, and that it does not depend on the alias alone.
☐ Read the Codex memories documentation and decide whether the feature stays off for this work.
☐ State, in one sentence you could repeat to a colleague, which task you would move to GPT-5.6 Sol or GPT-6.1 Sol and which you would leave here.
Result: One real task completed end to end, an effort level chosen with its cost known, a long-context decision recorded, and a migration sentence you can defend. That is a working setup rather than an impression.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Real Workflows
Workflow 1: A bounded agentic code change in a repository with a test suite
Learner type: Professional (career upskilling). Developer, technical lead or platform engineer. CI-First benefit tags: Time, Quantity, Quality. Connects to: UIT (Technology, AI, Data Science) engineering tracks. Time estimate: Twenty to sixty minutes for a bounded change plus the review time you would have spent anyway.
What you do vs what the tool does:
Step | You do | The tool does |
1 | Write the failing test or name the existing one, and state what done means. | (Nothing yet) |
2 | Put the rulebook, the failing test and the scope in the directory the agent reads. | Reads the repository, plans the change and runs the test it has been given. |
3 | Choose the effort level before the run starts, and decide what the agent may not touch. | Works through the change at that effort, calling tools in sequence. |
4 | Read the report before the diff. | Returns what it changed, what it found and what it needs from you. |
5 | Run the full suite and the linter yourself. | (Nothing. You verify.) |
6 | Read the diff. If it is too large to read, the task was too large. | (Nothing. You decide.) |
Sample prompt (UP-Context-Engineering Method: context, task, constraints, output format):
Context: this repository is [project]. The defect is [the behaviour]. The failing test is
[test name or command]. Done means that test passes and no other test changes state.
I am running this at effort [level] and I chose it because [reason].
Role: AI as a Co-Worker and Assistant for the change. I hold the decision to merge.
Profile: Act as a Co-Worker and Assistant, keeping the change bounded and evidenced.
Task: make the failing test pass without changing behaviour outside the defect.
Constraints: one module at a time. Do not edit [protected paths]. Do not add dependencies.
Do not refactor code the defect does not touch. If you cannot finish, say what remains rather
than reporting the change as complete.
Output format: a short table with file, change, and the evidence you used. Then three headings:
Blocked on me, Changed, Found. State plainly anything you did not verify, and list anything in
the request you skipped.
Memory: the change table and the evidence I accepted belong in my repository record. If Codex
memories are enabled, treat them as the tool's working state and not as the record.
UP-Context-Engineering verification: I read the report before the diff, I run the suite myself,
and I can defend every change without the tool.
Data safety: this pack carries no personal data. I do not paste credentials, customer data or an
unreleased repository into it, and I keep the change record in version control.
Cost note: A bounded change at `high` is the setting this model was priced for, and it is now the expensive way to buy it. At $5 per million input tokens and $30 output, a repository context re-read across twenty turns costs twice what the same run costs on GPT-5.6 Sol at its promotional $4 and $20, and fifteen times what it costs on GPT-6.1 Sol per output token. The trap is the long-context line: a context above 272,000 tokens doubles the input rate and multiplies the output rate by 1.5 for the whole request. Measure the turn count before the run, not after.
Verification checklist:
☐ Multi-Model Check: run the same defect on GPT-5.6 Sol at the same effort and compare what each found. A difference in what the two models noticed is more useful than a difference in prose.
☐ External Source: run the project's own test suite, linter and static analysis. Do not accept the model's statement that the test passes.
☐ Human Review: read the diff. If it is too large to read, the task was too large.
☐ Report-to-Specification Check: compare the report against the request line by line, because a run can complete half the specification and describe the half it did.
☐ CI-First Test: can you explain and defend the change without the model? If not, it is not ready.
Workflow 2: A source set turned into a decision brief
Learner type: Professional. Analyst, communications lead or manager producing a recurring document. CI-First benefit tags: Time, Quality. Connects to: UIB (Business Management, Entrepreneurship) and UIC (Digital Communication, Marketing). Time estimate: One to two hours for a first draft, plus the review you would have spent on a junior colleague's draft.
What you do vs what the tool does:
Step | You do | The tool does |
1 | State the audience, the decision the brief supports and the length. | (Nothing yet) |
2 | Supply the source documents and name the figures that must appear. | (Nothing yet) |
3 | Choose `high` effort, not `xhigh`, and say which sections matter most. | Reads the set in one window and produces the structure with the figures placed. |
4 | Check every figure against the source document yourself. | (Nothing. You verify.) |
5 | Ask it to name what the set does not contain, and treat silence as a finding to test. | Returns an explicit gap list on request. |
6 | Rewrite the argument in your own words. | (Nothing. This is the step that is yours.) |
Sample prompt (UP-Context-Engineering Method):
Context: the attached set is [description, number of documents, period]. The brief is for
[audience] and supports [decision]. Done means every figure can be traced to a document, and
the brief is no longer than [n] pages. The set is [token estimate] tokens and I have checked
whether it crosses the long-context price line.
Role: AI as a Co-Worker and Assistant on a first draft. I hold the argument and the sign-off.
Profile: Act as a Co-Worker and Assistant, separating what the documents say from what you infer.
Task: produce the first draft of the brief, section by section.
Constraints: cite document and page for every figure. Do not reconcile figures that disagree;
report the disagreement. Do not fill a gap with a plausible value. Do not add sections beyond
the structure I gave you. Keep every heading to one sentence.
Output format: a table with section, claim, three supporting points, and the source for each
figure. Then a section headed What the set does not contain, and a section headed Where the
sources disagree.
Memory disclosure: keep the source set, the figure table and the structure I gave you for this
session. Do not retain the documents themselves, and do not write notes about this matter.
UP-Context-Engineering verification: I check every figure against the source, I rewrite the
argument in my own words, and I can present the brief without the tool open.
Data safety: this pack is [classification]. I have removed personal data and credentials, and the
figure table stays in the matter file rather than in the conversation.
Cost note: The saving here is the number of passes, not the rate. A brief that used to take three rounds with a colleague can arrive in one pass, and the vendor's own knowledge-work rows describe why. That is also the risk: a draft that is ready to send removes the round in which someone notices the argument is wrong. Budget the review time you saved as review time. On price, the same set costs 50 percent more on this model than on the successor's promotional rate, and the long-context line applies to the whole request if the set pushes the prompt past 272,000 tokens.
Verification checklist:
☐ Multi-Model Check: run the same source set on a second model and compare the section on where the sources disagree. A difference in what each model noticed is more informative than a difference in prose.
☐ External Source: open the source documents and check every figure, date and quotation in the figure table.
☐ Human Review: read the brief as the audience would, then ask a colleague who did not build it what the brief is arguing.
☐ Specification Check: confirm the brief addresses the decision you named rather than a nearby question the model found easier.
☐ CI-First Test: can you defend the argument in the meeting without the tool? If not, the draft is not finished.
Workflow 3: A controlled migration test against the successor
Learner type: Professional or graduate researcher. Engineer, analyst or evaluation owner responsible for a model choice. CI-First benefit tags: Time, Quality, Skill. Connects to: UIT (Technology, AI, Data Science) evaluation work and UIB for the cost case. Time estimate: Half a day to build the test set, then two hours to run it across two or three models.
What you do vs what the tool does:
Step | You do | The tool does |
1 | Take twenty to fifty real tasks from your own work, with a checkable end state for each. | (Nothing yet) |
2 | Record the GPT-5.5 result at the effort level you actually use, and its cost. | Produces the baseline under a fixed prompt and setting. |
3 | Run the same set on GPT-5.6 Sol and GPT-6.1 Sol at matched effort. | Produces the comparison runs. |
4 | Score each output against the same check, and count the failures, not the impressions. | (Nothing. You score.) |
5 | Compare cost per completed task, not cost per token. | (Nothing. You decide.) |
6 | Write the migration decision and the date it was taken into the project record. | (Nothing. This is the LIPS entry.) |
Sample prompt (UP-Context-Engineering Method):
Context: I am deciding whether to migrate a workflow from GPT-5.5 to a newer OpenAI model.
The workflow is [description], it runs [n] times a week, and it costs [amount] a month at
$5 input and $30 output. The check that decides whether an output is acceptable is [check].
Role: AI as an Analyst. You are not doing the workflow; you are building the comparison.
Profile: Act as a Co-Researcher, Analyst and Tester, holding the check constant across models.
Task: build a twenty-task test set from the description I give, state the check for each task,
and list the failure modes the check can and cannot catch.
Constraints: do not use a task whose answer you cannot verify from the material I supply.
Do not tune the prompt for one model. Keep the effort level matched across models, and say
which level that is. Where a model refuses or returns a safeguard response, record it as an
outcome rather than a failure.
Output format: a table with task, check, what the check misses, and the effort level. Then a
section headed What this test cannot decide.
Memory disclosure: keep the workflow description, the test set and the matched effort level for
this session. Do not retain my cost figures or the run results beyond the project record.
UP-Context-Engineering verification: I score the outputs myself, I compare cost per completed
task rather than cost per token, and I can defend the migration decision without the tool.
Data safety: this pack carries [classification]. I use work I am allowed to process, and I keep
the results in the project record rather than in the conversation.
Cost note: This is the workflow that turns a superseded model into a decision. Run it once, at the effort level you actually use, and compare cost per completed task across the three models. The published rates make GPT-5.5 the most expensive of the three on output; the test tells you whether it is also the one that finishes your work. The independent component scores suggest the answer will differ by task: GPT-5.5 is strong on agentic coding and knowledge work, and the successor's advantage is the effort ceiling and the knowledge cutoff rather than a uniform quality jump.
Verification checklist:
☐ Multi-Model Check: this workflow is the multi-model check, applied to your own work rather than to a benchmark.
☐ External Source: every task carries a check that does not depend on the model's account of itself, such as a test, a schema, a quote table or a named figure.
☐ Human Review: a second person scores a sample of the outputs blind to which model produced them.
☐ Regression Check: the test set is fixed and re-run after any prompt or model change, and the failure list is kept.
☐ CI-First Test: can you explain why you chose the model you chose, with the failure counts in front of you? If not, the decision is an impression.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Strengths, Limits, and AI Imposture Risk
Strengths
CI-First Benefit | Strength | Evidence |
Time | A large agentic coding and computer-use jump over its predecessor, at settings that answer in seconds and at a latency the vendor held level with GPT-5.4. | Vendor: Terminal-Bench 2.0 at 82.7 percent against 75.1 for GPT-5.4, OSWorld-Verified at 78.7 against 75.0, and per-token latency matched to GPT-5.4 while using fewer tokens on Codex tasks. Independent: 84.27 percent on Terminal-Bench 2.1 at `xhigh`, and a time to first answer token of 21.77 seconds at `high`, 11.22 at `medium`, 2.77 at `low` and 1.68 with no reasoning. |
Quantity | More finished units of work per day, through a 1.05-million-token window, a 128,000-token output ceiling and a broad tool list. | 1,050,000 tokens of context, 128,000 tokens of output, Batch and Flex at half rate, and tools from web search and file search to hosted shell, apply patch, skills, computer use and MCP. Held at 6 rather than higher because the price per unit is the highest in its family and the long-context cliff applies to the whole request. |
Quality | Strong measured quality at launch, independently corroborated, and clearly ahead of its predecessor on every shared row. | Vendor: GDPval 84.9 against 83.0, Terminal-Bench 2.0 82.7 against 75.1, ARC-AGI-2 85.0 against 73.3, SWE-Bench Pro 58.6 against 57.7. Independent: GDPval Elo 1357 at `xhigh` and Tau2 93.9 percent. Held at 7 by the rows where it trails Claude Opus 4.7 on SWE-Bench Pro and Humanity's Last Exam, and by the production record in What Users Say. |
Skill | Marginal, and scored conservatively at 4. | No teaching mode is claimed. The model completes agentic work end to end, which is work a user no longer learns by doing, and Codex memories can write durable notes from prior chats once a person enables the feature. The clause note below records the condition. |
Limits
It is superseded twice by its own vendor, at a lower price. GPT-5.6 Sol arrived on 2026-07-09 at $4 and $20 on promotional rates, with a `max` effort level and a later knowledge cutoff; GPT-6.1 Sol arrived on 2026-09-29 at $2 and $10. GPT-5.5 has stayed at $5 and $30.
The output rate is the highest in its family. At $30 per million output tokens it is 50 percent above the successor's promotional rate and three times GPT-6.1 Sol's. The input rate is 25 percent above the successor and 2.5 times GPT-6.1 Sol's.
The long-context line is a cliff. A prompt above 272,000 input tokens pays 2x input and 1.5x output for the entire request, including the tokens below the line. The advertised window is 1,050,000 tokens, which makes the cliff easy to cross without noticing.
There is no `max` effort level. The ladder stops at `xhigh`, and the successor adds a setting above it. A reader who wants the top of the range cannot reach it on this model.
The production record carries a specific defect. A July 2026 community analysis reported that GPT-5.5 in Codex clusters reasoning output at fixed values spaced about 518 tokens apart, that the clustering correlates with errors on complex tasks, and that it is much less common on earlier models. Users in the same thread reported step changes in quality and a workaround that restored behaviour.
A hallucination analysis puts it at the wrong end of one comparison. A June 2026 thread reported GPT-5.5 hallucinating about three times as often as an open-weight model on the AA-Omniscience evaluation. The metric is conditional on the model not knowing the answer, so it is not a general hallucination rate, and the discussion in the thread says so.
The knowledge cutoff is two and a half months behind the successor's and five months behind the current flagship's. 2025-12-01 against 2026-02-16 on GPT-5.6 Sol and 2026-04-30 on GPT-6 Astra. Launch-day users also reported the model answering with a June 2024 cutoff, which the vendor page does not explain.
Codex gives the model less context than the API does. 400,000 tokens on plan surfaces against 1,050,000 through the API, which changes what "a million-token model" means for a team that works in Codex.
The API arrived a day after the product launch, with additional safeguards. The launch post says API deployments require different safeguards; the April 24 update says the model is now in the API and the system card has been updated with the additional safeguards that apply.
No open weights, no self-hosting and no external auditability. Nothing about this model can be inspected from outside OpenAI's service.
AI Imposture Risk
Trap | Rating | Evidence |
Time Illusion | Medium | The savings are real at the settings most people use: a 1.68-second answer with no reasoning, 21.77 seconds at `high`, and an agentic coding score that turned a hard task type into a routine one. The overhead is real as well: an effort decision on every job, five settings whose measured quality spans a GDPval Elo of 978 to 1357, a long-context price that doubles the input rate, and documents that must be read against their sources before they can be sent. |
Quantity Illusion | Medium | The volume is the offer: 128,000 tokens of output, a million-token window, and documents that look finished. A polished brief and a correct brief are the same object to a reader who does not know the source material, and the model's own default now reasons, which produces more text rather than less. |
Skill Illusion | High | Expert-form code, documents and decks for users who cannot evaluate them, produced by a model whose selling point is that it finishes the task without you, on a surface that can write durable notes from prior chats once memories are enabled. The capability is close enough to the newest models that a failure reads as a plausible near-miss, and the model is old enough that a user may not notice the comparison has moved. Mitigations are stated below and they are specific, and none of them moves the capability to the reader. |
Overall Imposture Risk: Medium. One trap is High with clear mitigations stated, and two are Medium. Under the framework's arithmetic, one High with clear mitigations stated is Medium rather than High, and the band-precedence sentence does not change that outcome because the other two traps are Medium rather than High.
The mitigations, stated clearly, because the band condition requires them. First, the effort level can be fixed by policy rather than left to habit: a team that names the setting for each job class removes most of the time and cost risk in one decision. Second, every workflow in this review carries a verification step that does not depend on the model's account of itself, and two of the three are mechanical: a test suite and a fixed evaluation set. Third, the price is published per line and per processing tier, so a reader can see what a run cost before deciding whether the answer justified it. Fourth, Codex memories are documented as off until a person enables them, which means a team can decide about the feature rather than discover it. Fifth, the model is pinned by snapshot, so a change in behaviour is a decision rather than a surprise. These lower the frequency and the cost of failure. They do not transfer capability, which is why the Skill sub-score stays at 4.
Framework v1.2 clause note
Clause 5.2.3-a, agent-authored procedural memory: APPLIES to the Codex delivery surface, with a default-off condition. OpenAI's documentation states that local Codex clients keep a separate local memory store, that memories are off until a person enables them in settings, and that once enabled Codex turns useful context from eligible prior chats into local memory files under the Codex home directory. The clause's no-lower-than-Medium floor is met wherever the feature is on, because the user then holds a durable capability they did not write. The High threshold is met where the writes happen during use without a per-write decision and the user has no routine practice of reading what was written. Where a user never enables the feature, the store does not accumulate and the clause does not bite on that surface. The published GPT-6.1 Sol review recorded the same position, and this review keeps it rather than flattening it. The live condition to watch is any change to the default in either direction.
Clause 4.2-a, agent-mediated conversation: NULL as a generator, with the live condition recorded. Neither erosion condition is met by the model itself. No agent-authored text is presented as the person's own voice in a human-facing channel by default, and nothing substitutes agent interaction for human contact. The live condition is a deployment property rather than a model property: an application built on this model that sends text in the person's own name through a connected account, without the person reading it first, would meet condition (a). The model's position as a cheap executor behind an application makes that arrangement easier to build, which is why the condition is recorded rather than dismissed.
Clause 7.5: removed by framework v1.4, not assessed. The subsection was removed on 2026-10-13 and no part of this review reaches its case. It is recorded here so that a reader comparing this review with an older one knows why the clause is absent rather than unanswered.
Why the clause note does not carry the whole Skill finding. The Skill Illusion is High for a reason that no clause mechanism supplies: the model produces expert-form output on tasks whose correctness the reader often cannot check, and it completes work a user would once have learned by doing. The clause application adds a second, narrower mechanism on the Codex surface. A reader who left memories off would still face the first.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Section 7c: The cyber threshold, the trust gate and the cyber-permissive sibling, stated plainly
A Section 7c finding is recorded where a supplier's governance, safety record or conduct has a real result for the reader. The items below were checked against primary sources, and they produce findings a buyer should carry. All findings are stated as facts of record, and the difference between a company statement, a programme requirement and a product behaviour is kept intact.
GPT-5.5 was released with a preparedness finding of High in two domains, and the vendor says so in its own documents. OpenAI's launch post states that the model is treated as High capability in cybersecurity and in biological and chemical capability under its Preparedness Framework, and below Critical in both. The system card repeats the cybersecurity determination and explains the threshold: Critical would require the ability to develop functional zero-day exploits of all severity levels in many hardened real-world critical systems without human intervention, and the vendor states that GPT-5.5 does not reach it. A High determination is not a scandal and it is not a marketing line; it is the category that switches on the safeguards a buyer will meet.
The cyber safeguards were expanded for this release, and they can interrupt legitimate work. The launch post states that stricter classifiers for potential cyber risk are being deployed and that some users may find them annoying initially. The vendor's remedy is a programme rather than a setting: Trusted Access for Cyber, which OpenAI describes as expanded access to the advanced cyber capabilities of GPT-5.5 for verified users who meet certain trust signals, starting with Codex. A team doing security work should apply before it builds, because the default path is the restricted one and the permissive path is an application.
The API version arrived a day later with additional safeguards, and the gap is documented. The launch post of 2026-04-23 says API deployments require different safeguards and that the vendor is working with partners on the requirements; the April 24 update announces that GPT-5.5 and GPT-5.5 Pro are now available in the API and that the system card has been updated to describe the additional safeguards that apply. A one-day gap between a product launch and an API launch is short, and the fact that the safeguards differ between the surfaces is the part a developer has to carry.
An external evaluator found that the model gives real uplift to a modestly skilled operator. The system card reports an assessment by Irregular, a security lab, across an atomic challenge suite and a long-horizon offensive suite. Irregular found that GPT-5.5 had higher success rates and lower costs per success than GPT-5.4, that it provides significant uplift to a novice or moderately skilled cyber operator in vulnerability research and exploitation, and that it may remove some existing bottlenecks to scaling cyber operations. That is a finding about capability, published by the vendor in its own system card, and it is the reason the safeguards exist.
The cyber-permissive sibling is a separate model with a shutdown date. `gpt-5.5-cyber-preview` is listed on the deprecations page as Deprecated, with a shutdown date of 2027-02-01 and a notice date of 2026-11-05, and a recommended replacement described only as the most capable cyber model available to the buyer. It is not `gpt-5.5` with a flag, it is not covered by this review's score, and a team that needs it should read its terms rather than assume the base model's.
The governance record has one unresolved date, and it is stated rather than smoothed. A September 2026 trade report said OpenAI would retire GPT-5.5 on 2026-10-14. The vendor's deprecations page, read in full on 2026-11-14, carries no such notice for `gpt-5.5`, and the model page still publishes prices and endpoints. Either the report was wrong, or the plan changed, or the notice was withdrawn; the record does not say which. A buyer should check the model record's `shutdown_date` before planning beyond the next quarter.
No sub-score changed for these findings, and the reason is explicit. The Time and Quantity sub-scores already carry the access friction, because a safeguard response and a trust application are steps before the work rather than part of it. The Quality sub-score already carries the model's measured position on vendor and independent evidence. The Skill sub-score already carries the memory condition. The items above concern access structure, safeguard routing and supplier disclosure rather than a defect in the artefact a buyer receives, and none of them is a resolved safety failure. Section 7c closes with what it does not do: it does not allege misconduct, it does not treat a safeguard or a trust programme as a scandal, and it does not convert a company's own published caveats into findings against it. It records what a reader adopting this model is also adopting: a safeguard regime that can refuse a request, a trust gate that decides who gets the permissive version, and a sibling model with a date on it.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
U365 Co-Intelligence Rating
CI-First Profile
Primary profile: Co-Worker and Assistant (level 2). Secondary profiles: Co-Researcher, Analyst and Tester (level 4), Co-Creator and Thought Partner (level 1).
Why this profile. The vendor's own positioning is an execution framing: give the model a messy, multi-part task and trust it to plan, use tools, check its work and keep going. That is a Co-Worker and Assistant, and the strongest measured rows, at 82.7 percent on Terminal-Bench 2.0, 78.7 on OSWorld-Verified and 98.0 on Tau2-bench Telecom, are execution rows. Co-Researcher, Analyst and Tester (level 4) stays reachable as a secondary because reading a document set and naming what it does not contain is a genuine use, and because the model is strong on OfficeQA Pro and FinanceAgent. Co-Creator and Thought Partner (level 1) is recorded as secondary because a long design or writing conversation in a million-token window is a real use, and because the launch material's strongest testimonials describe collaborative debugging rather than one-shot generation. The primary stays at level 2 because the price, the tool list and the benchmark selection all point the same way.
CI-First Benefit Score
Dimension | Score (0-10) | Rationale |
Time | 7 | A strong net saving on agentic coding, computer use and document work. Terminal-Bench 2.0 at 82.7 percent against 75.1 for the predecessor, OSWorld-Verified at 78.7 against 75.0, and independent measurement of 84.27 percent on Terminal-Bench 2.1 at `xhigh`, with a 21.77-second time to first answer token at `high` and 1.68 seconds with no reasoning. Held at 7 rather than 8 by the effort overhead, the 39.55-second wait at `xhigh`, and the fact that a newer model completes the same work in fewer iterations. |
Quantity | 6 | A real increase in usable output, at the highest price per unit in its family. A 1,050,000-token window, a 128,000-token output ceiling, Batch and Flex at half rate, and a tool list that covers search, files, code and computer use. Held at 6 because the output rate is 50 percent above the successor's promotional rate and three times GPT-6.1 Sol's, and because the long-context line doubles the input rate for the whole request. |
Quality | 7 | Clearly ahead of its predecessor on every shared row and independently corroborated: GDPval 84.9 against 83.0, Terminal-Bench 2.0 82.7 against 75.1, ARC-AGI-2 85.0 against 73.3, and an independent GDPval Elo of 1357 at `xhigh`. Held at 7 by the rows where it trails Claude Opus 4.7 on SWE-Bench Pro and Humanity's Last Exam, by the absence of a composite index under the current Artificial Analysis version, and by the production record on reasoning-token clustering. |
Skill | 4 | Execution rather than learning in the common case, with a memory mechanism that is opt-in rather than on by default. Scored conservatively per the framework's guidance and held at the predecessor's level, because the model completes work a user would previously have learned by doing, and because the clause 5.2.3-a condition applies wherever Codex memories are enabled. |
CI-First Benefit Score: 6.0 / 10 (CI-First Positive)
Why the score sits where it sits
6.0 with sub-scores 7 / 6 / 7 / 4 puts this model above its predecessor, level with GPT-5.6 Sol on the total, and below GPT-6.1 Sol at 6.3 and GPT-6 Astra at 7.0. That ordering needs explaining, because a model that is no longer worth buying can still score well.
Why not higher. Three reasons, each measured. The price per unit is the highest in its family: $5 and $30 against $4 and $20 on the successor's promotional rate and $2 and $10 on GPT-6.1 Sol. The effort ladder stops at `xhigh`, so the model cannot reach the setting its successor added. And the production record carries a specific defect and a quality dispute, both dated after launch and both cited in Strengths and Limits, which is why Quality is 7 rather than 8.
Why not lower. The capability is real and independently corroborated. Terminal-Bench 2.1 at 84.27 percent at `xhigh` and a GDPval Elo of 1357 are not vendor numbers, and they describe a model that finishes real work. The context window and the tool list are unchanged against the successor. The price is high, not absurd, and a team that already owns an integration gets a genuine return from it while it migrates. A score below 5 would say the model does not deliver net benefit, and that is not what the evidence says.
Why the score moved up by 0.2 against GPT-5.4. The predecessor published 5.8 with 7 / 6 / 6 / 4. This review publishes 6.0 with 7 / 6 / 7 / 4. Quality gains one point because the model is better on every shared benchmark row, and Time and Quantity hold because the window, the output ceiling and the latency are unchanged while the price doubled. The movement is small because the model bought a real capability gain and spent it on a price rise, and because the successor has since taken the value case.
What the score does not carry. The four dimensions measure what your work gains. They do not carry the lifecycle ambiguity, the trust gate, the safeguard routing or the migration cost, which is why those sit in Section 7c and in the Status and Migration Path sections with an explicit statement that no sub-score changed. They do not carry the price relative to a model the review is not scoring, beyond the Quantity rationale. A reader who wants the score to encode procurement policy would need a different instrument, and the framework's instrument is the status badge, the clause note and the 7c finding.
Humics Protection Badge
Dimension | Rating | Rationale |
Creativity | Neutral (0) | It drafts, designs, lays out and executes against a direction you set, and the vendor's examples include interface and 3D work from a reference image. It does not originate the direction, and it neither trains nor replaces your ideation. A model that produces a polished brief on request leaves the judgement about which brief matters with you. |
Critical Thinking | Erodes (-1) | Fluent, near-frontier output for people who cannot evaluate it, in exactly the tasks where the editing pass used to be the practice: a document, a deck, a report, a code change. The vendor's knowledge-work rows describe work that arrives finished, and the production record includes users reporting that they stopped checking as closely as they once did. The mitigations lower the frequency and do not reverse it. |
Social Authenticity | Neutral (0) | The model produces text rather than speaking in a person's name, and clause 4.2-a returns a null for it as a generator. The live condition stays in the record: an application built on this model that sends under a person's identity without the person reading it first would move this dimension. |
Humics Protection Score: -1 / +3 Badge: Humics-Neutral
Superhuman Usage Guidance
When to invite this tool:
A pinned baseline that an evaluation, a regulated workflow or a contract already depends on, while the migration runs.
Bounded agentic coding with a checkable end state, where the model is already integrated and the marginal cost of keeping it for one more quarter is lower than the cost of re-baselining now.
Computer-use and tool-chain work where the workflow was built and validated against this model's behaviour, and where a change of model would require a new validation.
Low-effort, latency-sensitive calls where the 1.68-second non-reasoning setting is the thing you need and the newer models' default reasoning would slow the job down.
A teaching case about model lifecycle, pricing and benchmark reading, which is the use this review recommends most strongly.
When to keep this tool out:
Any new integration, because GPT-5.6 Sol is cheaper on promotional rates, adds a `max` effort level and moves the knowledge cutoff forward.
High-volume work where GPT-6.1 Sol at $2 and $10 changes the economics.
Any workload whose prompts cross 272,000 tokens without a deliberate decision, because the whole request pays the long-context rate.
Work that needs the newest knowledge, the top of the reasoning ladder or the current frontier.
Security work that needs the permissive cyber configuration, unless the team holds Trusted Access.
The final judgement calls: what to publish, what to send to a client, what to tell a person. Those are the Humics this model does not supply.
U365 method integration:
LIPS + CARE: route the model's drafting, extraction and analysis output into the Collect phase, and keep the Action Plan and Review phases as your own work. The version decision, the snapshot string, the effort setting and the verification result belong in the record, because the model holds no state beyond the session and a retirement schedule can change the plan.
ULM + EVA: the frame in which a Fellow decides whether the work is worth automating at all, in Career and Finance and in Quality of Life. The model carries no cost method of its own; cost per completed task is CI-First cost engineering and the evaluator's metric, and it is not a ULM method. Weak fit elsewhere.
UP-Context-Engineering: it responds to explicit context, a stated role, a task, constraints and a named output format, and the constraints part matters here because the long-context cliff and the effort ladder both let a run spend more than the task deserves. The workflows in Real Workflows use that order, and the prompt pack in Verdict and Next Steps repeats it.
UNOP: no direct fit. The model is not built to teach, and its reliability comes from capability and price rather than from any pedagogical mechanism.
Over-delegation warning: the failure mode with a superseded model is different from the failure mode with a new one, and it is quieter. A new model invites over-use because it is impressive; an old one invites neglect because it is familiar. The team that keeps GPT-5.5 because it works does not notice that the evaluation set has stopped moving, that the successor's ceiling is untested, and that the price gap has become a budget line nobody owns. The arithmetic is the framework's own: if your Human Intelligence input drops while the Artificial Intelligence term rises, the product falls. A reader who leaves the everyday work on a model that is no longer the one to buy, and stops reading the output as closely as they read a colleague's, has taken the worse half of both offers. The Skill sub-score of 4 and the clause note are the framework's way of recording that the offer is real.
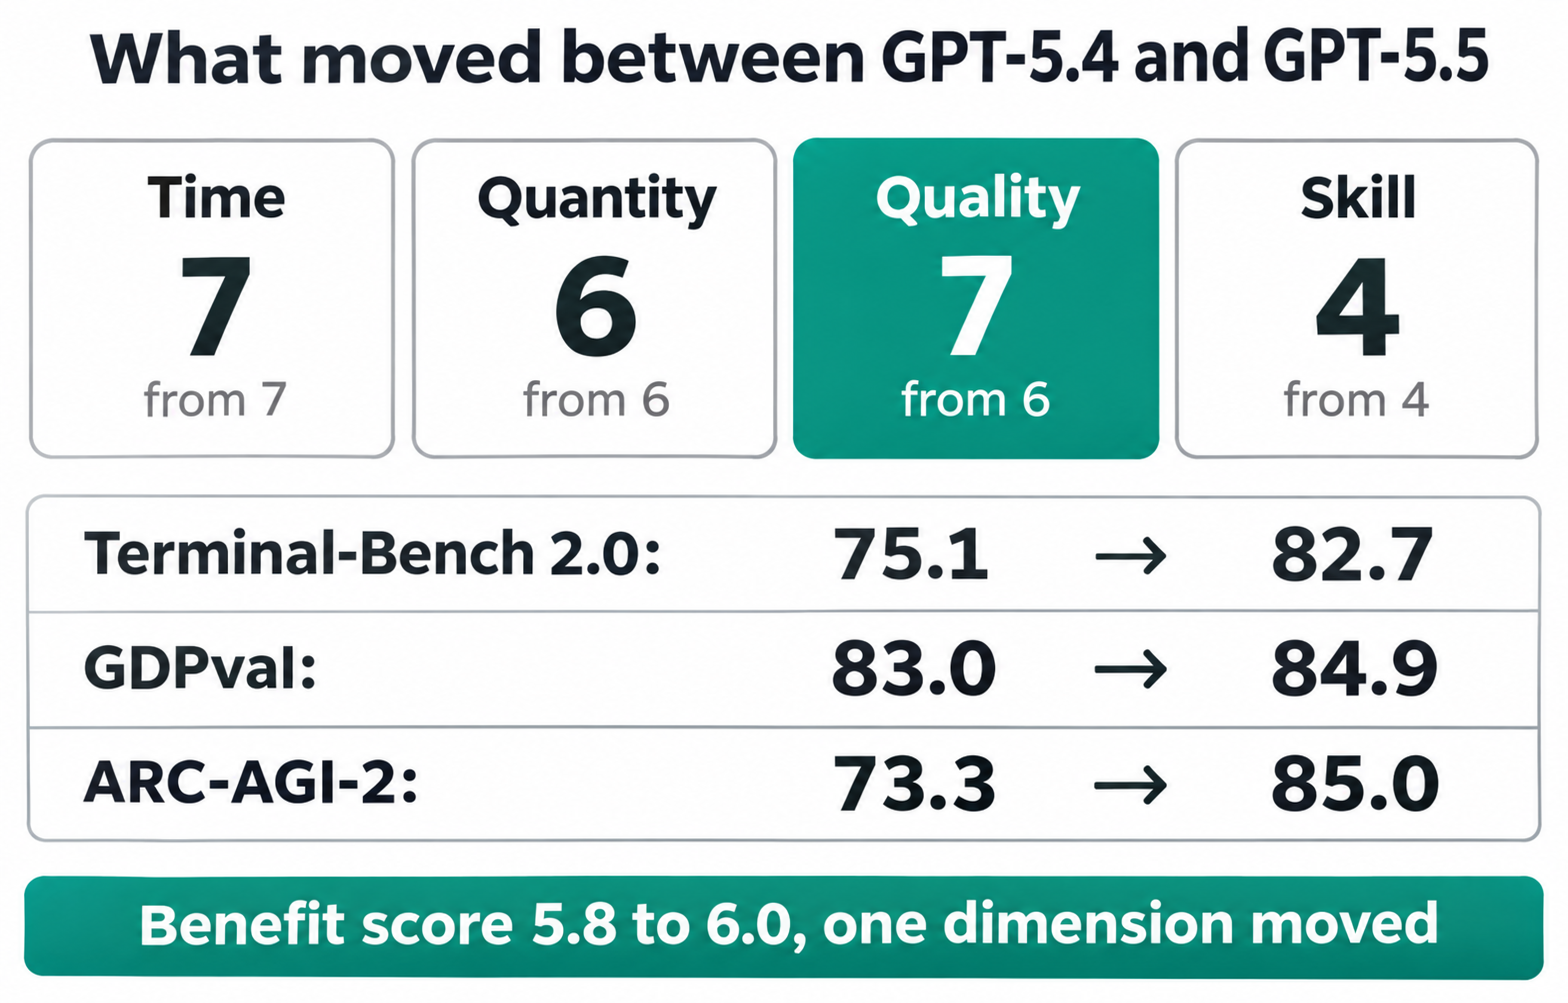

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
What Users Say
Aggregate Rating Table
Platform | Rating | Number of reviews | Link |
Hacker News, launch thread of 2026-04-23 | 1,580 points, strongly positive on capability and sharply divided on price | 1,056 comments | |
Hacker News, API release thread of 2026-04-24 | 256 points, focused on price, safeguards and the one-day gap | 159 comments | |
Hacker News, price thread of 2026-05-08 | 214 points, critical of cost per completed task | 73 comments | |
Hacker News, reasoning-token thread of 2026-07-04 | 372 points, critical, with reproductions | 152 comments | |
G2 | No reviews found on G2 | Not applicable | Not applicable |
Capterra | No reviews found on Capterra | Not applicable | Not applicable |
Trustpilot | No reviews found on Trustpilot | Not applicable | Not applicable |
Product Hunt | No model-level reviews found on Product Hunt | Not applicable | Not applicable |
Note on method, stated plainly because it affects how much this section is worth. No review platform rates an individual model endpoint, and no G2, Capterra, Trustpilot or Product Hunt listing for this model was found on 2026-11-14. The meaningful signals are the Hacker News launch thread, where practitioners posted measured comparisons within hours, and three later threads that carry the production record. This section reports those and attributes every quotation to the handle that posted it. The threads are first-days and first-months signals, not a controlled sample.
What Users Praise
The capability jump landed, and the first-day reports were specific. `refulgentis` wrote that he was "absolutely stunned" and that he "gave it two very long-running problems I haven't had the courage to work on in the last 2.5 years, solved each within an hour". That is a checkable claim with a described task, and it is the strongest thing a first-day reader can say.
The combination with Codex was the practical case. `robertwt7` wrote that "Gpt 5.5 combined with codex is really good", that he has "no doubt whenever I asked questions, plan, or implement a code with it", and that with a competing model he has to keep double checking. `gertlabs`, who publishes coding benchmarks, reported that GPT-5.5 was the most intelligent public model at the time and significantly faster than its predecessor. `nl` reported it as the second model to reach 25 of 25 on his SQL benchmark.
The efficiency claim found support as well as scepticism. `louiereederson` compared output volumes on the independent index and reported that GPT-5.5 used 22 million output tokens for a score of 56.7 where Claude Opus 4.7 used 111 million for 57, and called the efficiency gap enormous. `XCSme` reported that "5.5 low seems to be as good as 5.4 medium, but a lot cheaper", and that this held in his own agent work. Those two reports describe the same property from opposite ends: the model can be run cheaply at low effort, and it can be run expensively at high effort.
The coding case survived the price complaints. Even in the price thread, where the criticism is heaviest, `gaflo` reported that GPT-5.5 for agentic coding "did get significantly better" in his experience, and that he had not noticed a regression in his own work.
What Users Complain About
The price was the dominant complaint on day one and it has not aged out. `QuadrupleA` wrote that it is "exactly double the cost of GPT 5.4". `Topfi` priced the context ladder line by line and concluded that it is "significantly more expensive than Opus 4.7 beyond 272K", and that he had not seen enough token efficiency to compensate. `deflator` reported that two tasks he expected to cost $1 to $2 on an earlier Codex model "used $20 on each". `languid-photic`, reporting for a benchmarking firm, found that "5.5 is about 1.5-2x more expensive overall" per completed engineering task and that only `xhigh` was worth it on a Pareto basis, while `XCSme` measured about 3.5 times on his own suite.
The model over-complicates small changes. `darqis` wrote that "5.5 is overcomplicating it", describing a task that needed one authentication URL changed and received a service, middleware, a config reader and finally the change. `wincy` reported asking for a transaction with a rollback and receiving a placeholder statement instead, and said he had not had to prod a model to do what he asked in a while.
The benchmark story has a hole in it. `k2xl` asked why SWE-Bench Pro moved only from 57.7 to 58.6 percent while Claude Opus 4.7 reached 64.3, and why Terminal-Bench moved so much further. He also noted that ARC-AGI-3 was missing from the launch table. Those are fair readings of the vendor's own numbers.
The knowledge cutoff did not match the documentation for at least one user. `czk` reported on 2026-04-24 that the API page listed a cutoff of 2025-12-01 while the model, when prompted, said June 2024. This review records the vendor's stated cutoff and records the discrepancy separately; it does not resolve it.
A reasoning-token defect appeared in July, and the reports are specific. `maille` summarised an analysis showing that GPT-5.5 in Codex clusters `reasoning_output_tokens` at fixed values spaced about 518 tokens apart, that the stuck responses correlate with errors on complex tasks, and that the pattern is specific to GPT-5.5 and much less common on GPT-5.4. `nsingh2` reproduced it with a puzzle prompt and reported that when the model used 6,000 to 8,000 thinking tokens it returned the correct result. `zenapollo` reported "step jumps down in quality on an almost daily basis" at `xhigh` and said he had switched away. `zuzululu` reported that a workaround restored the behaviour he remembered from a month and a half earlier. These are individual reports against a published analysis, not a measured rate, and they are the most concrete quality evidence in the record.
A hallucination comparison put the model at the wrong end of one table. A June 2026 thread reported that GPT-5.5 hallucinates about three times as often as an MIT-licensed open-weight model on the AA-Omniscience evaluation. The thread's own discussion notes that the metric is conditional on the model not knowing the answer, so it measures confidence when ignorant rather than the chance of meeting a hallucination in ordinary use. The claim is recorded with that limit.
Some users found the value case had moved to open-weight models. `DeathArrow` wrote that "in terms of work done per dollar, new models from OpenAI and Anthropic are worse than the older models", and described switching his personal work to cheaper coding plans. `guilamu` reported that on his own WordPress benchmark the model was "one of the worst model of the leaderboard performance wise and the worst value wise", while acknowledging it was a single benchmark.
Sentiment Summary
Overall sentiment: Positive on capability, negative on price, and increasingly negative after July on production reliability at high effort.
Key themes: the model was a genuine step forward in agentic coding and computer use; it costs twice its predecessor and more per completed task than its headline rate suggests; the long-context cliff above 272K is the line that surprises people; the successor is cheaper and adds a setting the model does not have; and a specific reasoning-token behaviour reported in July 2026 is the most concrete quality complaint in the record.
U365 Editorial Note
User sentiment and the CI-First score agree on most of what matters, and the divergence is instructive.
They agree that the capability is real: the first-day reports describe solved problems rather than impressions, and the benchmark readings in the thread are correct readings of the vendor's own table. They agree on the price as well, with more precision than the launch page offered. What the thread does not do is separate the two purchases the model offered. At `low` or with no reasoning it is a fast, comparatively cheap executor, and several readers said so. At `xhigh` it is an expensive model whose per-task cost ran 1.5 to 3.5 times the predecessor in two independent measurements, and the people who complained loudest about cost were often running it at the top of the ladder.
Where the framework goes further is on what a superseded model does to the person using it. The risk is not that the model is bad; it is that it is good enough to stop the comparison. A team that keeps it because it works stops asking whether the successor's ceiling matters, whether the evaluation set still measures the work, and whether the price gap is a decision or a habit. The Skill sub-score of 4 and the Skill Illusion of High are the framework's answer: the work improves, the habit of checking it does not, and nothing in the product supplies the habit.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Comparison and Alternatives
This section carries the comparison a reader came for: GPT-5.5 against its successor, against the model it replaced, and against the newer OpenAI model that now sets its price.
The four-model comparison, on U365's own published readings
Field | GPT-5.5 | GPT-5.6 Sol | GPT-5.4 | GPT-6.1 Sol |
U365 CI-First Benefit Score | 6.0 / 10 (CI-First Positive) | 6.0 / 10 (CI-First Positive) | 5.8 / 10 (CI-First Positive) | 6.3 / 10 (CI-First Strong) |
Sub-scores (Time / Quantity / Quality / Skill) | 7 / 6 / 7 / 4 | 7 / 7 / 7 / 3 | 7 / 6 / 6 / 4 | 7 / 7 / 8 / 3 |
Humics Protection | Humics-Neutral (-1 / +3) | Humics-Neutral (-1 / +3) | Humics-Neutral (0 / +3) | Humics-Neutral (-1 / +3) |
AI Imposture Risk | Medium (Skill Illusion High) | Medium (Skill Illusion High) | Medium | Medium (Skill Illusion High) |
Primary CI-First Profile | Co-Worker and Assistant (level 2) | Co-Creator and Thought Partner (level 1) | Co-Creator and Thought Partner (level 1) | Co-Worker and Assistant (level 2) |
Released | 2026-04-23 | 2026-07-09 | 2026-03-05 | 2026-09-29 |
API price per million tokens | $5 in / $0.50 cached / $30 out | $4 in / $0.40 cached / $20 out on promotional rates to 2026-11-30 | $2.50 in / $0.25 cached / $15 out | $2 in / $0.10 cached / $10 out |
Effort ladder | `none`, `low`, `medium` (default), `high`, `xhigh`; no `max` | Adds `max` above `xhigh` | `none` (default), `low`, `medium`, `high`, `xhigh` | Adds `max` above `xhigh` |
Knowledge cutoff | 2025-12-01 | 2026-02-16 | 2025-08-31 | Not restated here; see the GPT-6.1 Sol review |
Independent measurement | 84.27 percent on Terminal-Bench 2.1 and GDPval Elo 1357 at `xhigh`; no composite index published under the current index version | Not restated here; see the GPT-5.6 Sol review | Not restated here; see the GPT-5.4 review | Not restated here; see the GPT-6.1 Sol review |
Where this model sits among the four, stated plainly. It has a real capability advantage over GPT-5.4, a real price disadvantage against the other three, and a score that lands level with GPT-5.6 Sol on the total while losing on the shape. GPT-5.5 trades one Quantity point for one Skill point against its successor: it has no `max` level, a later base rate and a smaller measured output per unit of money, and it asks for less of the user's own skill because it is a more complete executor. GPT-6.1 Sol is the model that makes the case hardest, at $2 and $10 with an independent Quality score of 8 and a U365 score of 6.3.
What moved against GPT-5.4, and what did not. Quality moved from 6 to 7: Terminal-Bench 2.0 from 75.1 to 82.7, GDPval from 83.0 to 84.9, ARC-AGI-2 from 73.3 to 85.0, and the independent Terminal-Bench 2.1 figure at 84.27. Time and Quantity did not move, because the window, the output ceiling and the latency were held while the price doubled. Skill did not move, because neither model teaches. What did not move in the reader's work either: state the task, choose an effort level, read the output, verify it.
One comparison caveat, stated because the record requires it. The vendor's launch table was run at `xhigh` effort in a research environment, and the comparison column is the vendor's own reading of a competing model. The independent component scores are measured at each effort level on a later version of Terminal-Bench, so they are not directly comparable to the vendor's Terminal-Bench 2.0 row. Where this review quotes 84.27 percent it says Terminal-Bench 2.1, and where it quotes 82.7 it says Terminal-Bench 2.0 and names the vendor as the source.
The field, with "Choose X if" guidance
Alternative | Choose the alternative if... | Choose GPT-5.5 if... |
GPT-5.6 Sol | You are starting now, you want the `max` effort level, or you want the same window at a lower promotional rate until 2026-11-30. It is the direct replacement and the vendor positions it as the successor. | You have a validated integration pinned to a GPT-5.5 snapshot and the cost of re-validating it now is higher than the price difference for one more quarter. |
GPT-6.1 Sol | You want the best value in the OpenAI line at $2 and $10 and a Quality score of 8. | You need the specific behaviour of this model in a workflow that was built and signed off against it. |
GPT-5.4 | You want the cheaper older model for a routine workload, or you are already running it and see no reason to move up. It scores 5.8 with a lower price. | You want the capability gain over 5.4 on agentic coding and can absorb the doubled rate. |
GPT-6 Astra | You need the frontier: the current flagship at $10 and $50, the highest measured intelligence in the OpenAI line, and the strongest computer-use performance. | You do not need the frontier, and the task is one this model already finishes to your check. |
Claude Sonnet 5.5 | You want the other 7.0 in the library, a cheaper output rate at $10, and a model with a higher Quality score on the same framework. | Your stack, your prompts and your evaluation are built around OpenAI's API and tools. |
Where GPT-5.5 is clearly better: on capability against its own predecessor, at 82.7 against 75.1 on Terminal-Bench 2.0 and 78.7 against 75.0 on OSWorld-Verified; on tool breadth, where the Responses API exposes search, files, code, shell, apply patch, skills, computer use and MCP under one model id; on the launch-week coding and computer-use rows, which were state of the art when published; and on continuity, where a pinned snapshot gives a team a fixed target.
Where GPT-5.5 is clearly worse: on price against every model in this comparison, at $5 and $30 against $4 and $20, $2.50 and $15, and $2 and $10; on the effort ceiling, where it has no `max`; on the knowledge cutoff against three of the four; on the long-context rate, which doubles input above 272K; and on the production record, where the July reasoning-token reports sit against it and no equivalent analysis sits against its successor.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Verdict and Next Steps
Who should adopt it: Nobody starting new work, and every team that already runs it should plan the move rather than extend the commitment. The three cases where keeping it for a defined period is defensible: a pinned baseline that an evaluation or a contract depends on; a validated computer-use or tool-chain workflow where a model change would require re-validation; and a low-effort, latency-sensitive call where the non-reasoning setting is the thing you need.
When: Not now, and not without a date. A team that keeps GPT-5.5 should write the migration date into the project record, name the successor it will test against, and put the test set in place before the date arrives. A team that has not started should begin on GPT-5.6 Sol or GPT-6.1 Sol and treat this review as the baseline it will compare against.
For what: A controlled migration test, a pinned baseline, a teaching case about model lifecycle, and the low-effort calls where a 1.68-second non-reasoning answer is the requirement. Not for new agentic coding, not for new document pipelines, and not for any workload whose economics depend on the output rate.
The honest caveat, stated once: this is a good model at the wrong price in the wrong quarter. It scored 6.0 on the framework, which is a real recommendation with disciplined use, and it carries a Risky badge, which is a statement about fitness rather than about quality. Both are true because the framework measures benefit and the badge measures position. Adoption advice: take the capability for what it was, move the new work to the successor, keep the pinned baseline only as long as the migration needs it, and check the vendor's `shutdown_date` before you plan beyond the next quarter.
UP-Context-Engineering prompt pack
Prompt 1: Decide whether this workflow should move.
Context: my workflow is [description], it runs [n] times a week, and it costs [amount] a month
on GPT-5.5 at $5 input and $30 output. The alternatives I can use are GPT-5.6 Sol at $4 and $20
on promotional rates until 2026-11-30 and GPT-6.1 Sol at $2 and $10. The check that decides
whether an output is acceptable is [check].
Role: AI as an Analyst. You are not doing the workflow; you are costing the choice.
Profile: Act as a Co-Researcher, Analyst and Tester, applying a stated rule rather than an impression.
Task: compare the three models on cost per completed task, on the check's pass rate, and on the
effort level each needs to pass it.
Constraints: use my measured numbers where I have them and the published rates where I do not.
Do not compare cost per token alone. State every assumption, and mark any figure you could not
verify. Do not recommend a model whose effort level I cannot reach.
Output format: a table with model, rate, effort, cost per completed task, pass rate, and the
assumption behind each figure. Then one paragraph headed What would change this answer.
Memory disclosure: keep my volume figures and the three rate cards for this session only. Do
not retain my organisation's commercial data, and do not write a note about our pricing.
UP-Context-Engineering verification: I can reproduce every figure from the rates and volumes I
supplied, and I can state the crossover point without the tool.
Data safety: do not paste supplier contracts, unpublished pricing, payroll or client commercial
terms. Use rounded internal figures and say that they are rounded.
Prompt 2: Audit a pinned GPT-5.5 deployment.
Context: we run gpt-5.5-2026-04-23 in [system] for [purpose]. The snapshot is pinned and the
workflow was validated on [date]. The vendor's deprecations page carries no retirement notice
today, and a September report said the model would be retired on 2026-10-14.
Role: AI as a Co-Researcher, Analyst and Tester. You are auditing the dependency, not defending it.
Profile: Act as a Co-Researcher, Analyst and Tester, separating what the vendor states from
what a report claims.
Task: list every place the deployment depends on behaviour specific to this model, every place
it would break on a model change, and every place the check would still pass on a newer model.
Constraints: do not assume a retirement date in either direction. Do not propose a migration
step that requires re-validating more than [n] components at once. Name the evidence for each
dependency.
Output format: a dependency table with component, model-specific behaviour, break risk, and the
check that would catch it. Then a migration order, longest lead time first.
Memory disclosure: keep the deployment description and the dependency list for this session. Do
not retain system names, internal architecture or anything under a client agreement.
UP-Context-Engineering verification: I confirm each dependency against our own record, and I
can defend the migration order without the tool.
Data safety: do not paste credentials, hostnames, customer data or a security finding that is
not cleared for a third party. Describe the system by role rather than by name.
Prompt 3: Turn the migration into a procedure you keep.
Context: I moved [workflow] from GPT-5.5 to [successor]. The check I used was [check]. What
changed in the output was [difference]. What I had to rewrite was [rewrite].
Role: AI as a Coach. You are helping me extract the reusable part.
Profile: Act as a Professor, Coach and Tutor, not as a generator. Do not write the workflow again.
Task: write the procedure I should follow the next time a model I depend on is superseded.
Constraints: no more than 10 steps. Every step must be something I did, not something the model
did. Name the decision points where I had to judge, and the check that caught the difference.
Do not include rates or settings that will change with the next release.
Output format: When to run this. Steps. Decision points. Checks. What I would do earlier next time.
Memory disclosure: keep this run's outcome and the correction for this session only. Do not
retain the artefact, the difference or the rewrite after the session.
UP-Context-Engineering verification: I can run this procedure without the model, and I can teach
it to a colleague in ten minutes.
Data safety: do not paste the artefact if it carries client material, unpublished results or
personal data. Describe the difference without reproducing the document.
Related U365 content
GPT-5.4 Tool Review. The direct predecessor, at 5.8 with sub-scores 7 / 6 / 6 / 4. Read it beside this review to see what one generation bought and what it cost.
GPT-5.6 Sol Tool Review. The direct successor, at 6.0 with sub-scores 7 / 7 / 7 / 3 and the first model in this line to carry a `max` effort level.
GPT-6.1 Sol Tool Review. The near-flagship at 6.3 and $2 and $10, and the model that now sets the value case in the OpenAI line.
GPT-6 Astra Tool Review. The current flagship at 7.0, with the highest Quality score in the OpenAI group.
The CI-First Evaluation Framework, version 1.4.1. The method behind the score, including the clause set applied in Strengths, Limits, and AI Imposture Risk.
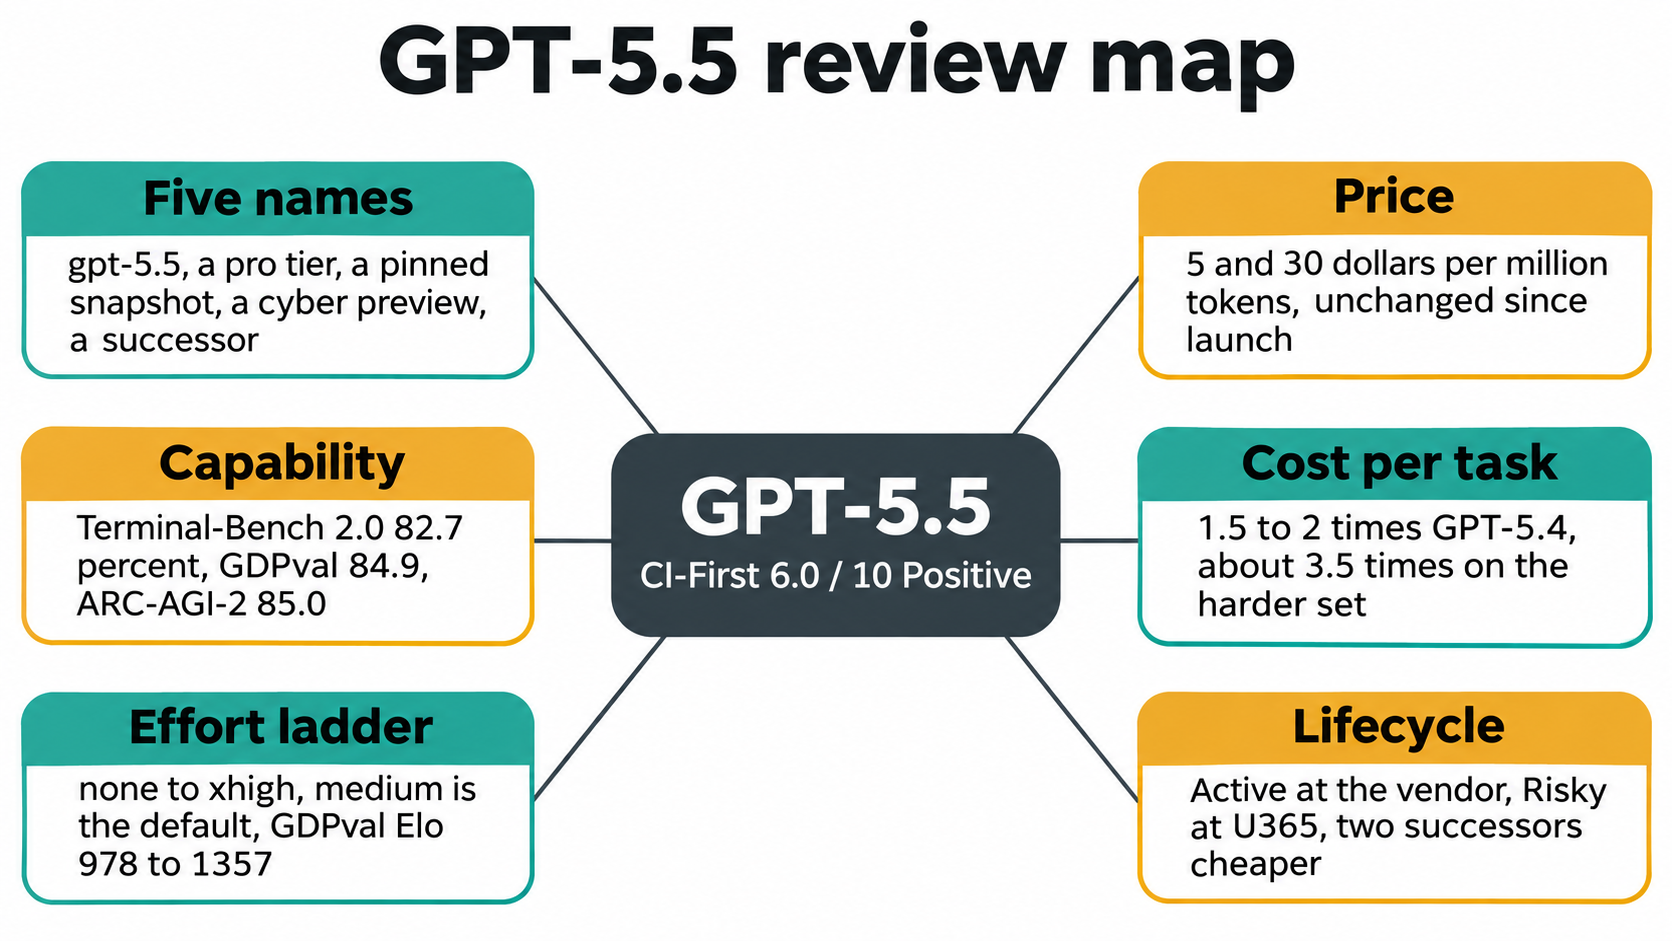

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Status and Last Tested
Status: Risky. Last tested: 2026-11-14. Version reviewed: GPT-5.5, `gpt-5.5`, default snapshot `gpt-5.5-2026-04-23`, released 2026-04-23. Next scheduled re-check: on any of the seven triggers at the top of this document, and in any case within six months.
Risky is the badge for a tool that has significant unresolved issues or has been clearly surpassed, so it is used with caution. This model has been clearly surpassed by its own vendor's later releases at a lower price, and its production record carries an unresolved reasoning-token finding. It is not Retired and it is not Deprecated in the vendor's vocabulary: OpenAI's deprecations page carries no retirement notice for `gpt-5.5`, and the model page still publishes prices and endpoints. The badge is a U365 judgement about fitness for new work, and the review states the vendor's lifecycle beside it so that a reader can see both.
The evidence was read on the date above, the independent component measurements were published against the five effort settings of this model, and the community record was read on the same day. A reader who arrives more than six months after 2026-11-14 should treat the price lines, the effort ladder, the lifecycle and the safeguard routing as unverified until a re-check is published.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Migration Path
Required, because the tool is Risky. The model still works, the vendor still sells it, and the migration is a planned move rather than an exit.
What transfers. Prompt structure and system instructions transfer to GPT-5.6 Sol and GPT-6.1 Sol without change, because both use the same Responses API and the same tool list. Function-calling schemas and structured outputs transfer. The tool set, from web search and file search to code interpreter, hosted shell, apply patch, skills, computer use and MCP, is available on the successor surfaces. A pinned snapshot string is replaced by the successor's own string, and the surrounding router and evaluation code stays where it is.
What does not transfer, and why. The effort ladder changes: GPT-5.5 stops at `xhigh`, and the successor adds `max`, so a team that tuned prompts at `xhigh` should test whether `max` buys anything on its own tasks before paying for it. The knowledge cutoff moves from 2025-12-01 to 2026-02-16, which changes what the model knows rather than how it behaves. The price lines change, including the promotional rate that expires on 2026-11-30, so a cost model built on the GPT-5.5 rate card cannot be carried across. The long-context rule is a family property and stays, at 2x input and 1.5x output above 272K. And the memory surface is shared: Codex memories are a client feature rather than a model feature, so the decision a team made about them travels with the team, not with the model.
Migration steps, in order. Pick the successor: GPT-5.6 Sol if the work needs the `max` ceiling or the vendor's current flagship position, GPT-6.1 Sol if cost per completed task is the deciding line. Take the twenty-to-fifty task test set from Real Workflows and run it at matched effort on both models. Score the outputs against the checks, count failures, and compute cost per completed task rather than cost per token. Move the easiest workflow first and keep the GPT-5.5 snapshot pinned until the new one has passed the test set twice. Update the router, the evaluation baseline and the project record in the same pass, because a migration that changes the model without changing the record leaves the next reader unable to tell which result came from which. Then retire the snapshot on a date you named before you started.
What to expect on the other side. A model that is cheaper per token, at least as capable on the tasks you tested, and slower at the top setting if you use `max`. A knowledge cutoff two and a half months further forward. A vendor lifecycle that is less ambiguous than this one, for as long as the successor remains current. And no change to the shape of your work: you still state the task, choose an effort level, read the output and verify it against something outside the conversation.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
U365's Recommendations to Learn More
These resources were curated to help you go deeper on GPT-5.5. We prioritise material that teaches something this review does not cover.
Official learning resources
The launch post: the benchmark table, the token-efficiency claim, the preparedness findings, the availability and the price. Read the API paragraph against the April 24 update. https://openai.com/index/introducing-gpt-5-5/
The model page: the identifiers, the snapshot, the context and output limits, the modalities, the effort levels, the tool list and the quick price comparison against GPT-5.4. https://developers.openai.com/api/docs/models/gpt-5.5
The model guidance: the vendor's own prompting and configuration advice for this model. https://developers.openai.com/api/docs/guides/latest-model?model=gpt-5.5
The API pricing page: the short-context and long-context lines, the cache rates and the batch discount, in one table. The 272K line is the one to read twice. https://developers.openai.com/api/docs/pricing
The deprecations page: the lifecycle states, the upcoming shutdowns and the notice periods. The page that settles whether `gpt-5.5` has a date on it. https://developers.openai.com/api/docs/deprecations
The full model catalogue: the current line-up and where this model sits in it. https://developers.openai.com/api/docs/models/all
The system card: the preparedness determinations, the cyber and biological evaluations, the external assessments and the safeguard design. https://deploymentsafety.openai.com/gpt-5-5
Trusted Access for Cyber: the programme a security team has to join to reach the permissive configuration. https://openai.com/index/scaling-trusted-access-for-cyber-defense/
Codex memories: what the feature writes, where it stores it, and how to turn it off. The mechanism behind clause 5.2.3-a in this review. https://learn.chatgpt.com/docs/customization/memories
The Codex documentation index, for the current CLI, IDE and cloud surfaces and their settings. https://developers.openai.com/codex/llms.txt
The status page, for the availability record a team should check before it schedules a dependent run. https://status.openai.com
Video tutorials and channels
OpenAI GPT-5.5 Full Review: Real Upgrade or Expensive Agent Hype? by Fluid Coding and AI. The question this review spends a section on, asked directly and answered with cost. https://www.youtube.com/watch?v=ZKdhrVoUUKM
GPT-5.5 is the best model ever made (but there's a catch), by Ben Davis. A practitioner's walkthrough that takes the capability claims seriously and names the catch. https://www.youtube.com/watch?v=nNib9Uz3dVA
GPT-5.5 in 7 Minutes, by Developers Digest. The shortest route to the feature set, the effort levels and the API shape for a reader who wants the facts before the argument. https://www.youtube.com/watch?v=A9G3s8Qeu_8
Written tutorials and deep-dive articles
Artificial Analysis, the model page: the five effort variants, the per-effort component scores, the latency and throughput readings, and the note that the composite index is not published for this model under the current version. https://artificialanalysis.ai/models/gpt-5-5
Artificial Analysis, the GPT-5.6 Sol page: the successor's measurements, for the comparison in this review. https://artificialanalysis.ai/models/gpt-5-6-sol
Artificial Analysis, the intelligence index methodology: the nine evaluations behind the current composite, so a reader can see why an older model's index may not be comparable. https://artificialanalysis.ai/methodology/intelligence-benchmarking
The Hacker News launch thread: 1,580 points and 1,056 comments of practitioner reports, including the price arithmetic, the efficiency comparison and the benchmark readings quoted in Comparison and Alternatives. https://news.ycombinator.com/item?id=47879092
The Hacker News price thread: the cost-per-completed-task measurements from two benchmarking firms, which is the evidence this review uses for its cost sentences. https://news.ycombinator.com/item?id=48057209
The Hacker News reasoning-token thread: the July 2026 analysis of the 518-token clustering, with reproductions and counter-reports. The most concrete quality evidence in the record. https://news.ycombinator.com/item?id=48789428
The OpenAI preparedness framework: the thresholds the launch post cites for its High determinations. https://cdn.openai.com/pdf/18a02b5d-6b67-4cec-ab64-68cdfbddebcd/preparedness-framework-v2.pdf
Community and social
Hacker News, the launch thread: the most useful single page in the record, because practitioners posted measured comparisons rather than impressions on the first day. https://news.ycombinator.com/item?id=47879092
Hacker News, the API release thread: the price and safeguard discussion that followed the one-day API gap. https://news.ycombinator.com/item?id=47894000
Artificial Analysis, the releases comparison page: the independent measurements as they are updated, which is where a reader should check whether the figures in this review still hold. https://artificialanalysis.ai/models/releases
Resources on X
Dedicated X channels. Three accounts carry this release: OpenAI's company account, which posted the availability announcement; the OpenAI Developers account, which carries the API and Codex material; and the Artificial Analysis account, which carries the independent measurements this review cites.
@OpenAI, the company account: https://x.com/OpenAI
@OpenAIDevs, the developer account: https://x.com/OpenAIDevs
@ArtificialAnlys, the independent evaluation account: https://x.com/ArtificialAnlys
Read any post against the measurement rather than against its own caption, and treat a launch-day thread as a pointer to a source rather than as a source.


GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
CI-First Evaluation Summary Card
Field | Value |
Tool | GPT-5.5, operated by OpenAI |
Category | Applied AI / Large Language Model (agentic coding, computer use, knowledge work and document production) |
Version reviewed | GPT-5.5 (`gpt-5.5`, default snapshot `gpt-5.5-2026-04-23`, released 2026-04-23), as documented by the vendor on 2026-11-14 |
Status | Risky (vendor lifecycle: Active, no retirement notice published, superseded in the line-up) |
Last tested | 2026-11-14 |
CI-First Profile | Primary: Co-Worker and Assistant (level 2). Secondary: Co-Researcher, Analyst and Tester (level 4) for first-pass document and gap work, Co-Creator and Thought Partner (level 1) for long design and writing conversations |
CI-First Benefit Score | 6.0 / 10 (CI-First Positive) |
Time | 7, strong net savings on agentic coding, computer use and document work, at 82.7 percent on Terminal-Bench 2.0 and an independent 84.27 percent on Terminal-Bench 2.1 at `xhigh`, with a 21.77-second time to first answer token at `high` and 1.68 seconds with no reasoning; held at 7 by an effort decision on every job, a 39.55-second wait at `xhigh`, and a newer model that finishes the same work in fewer iterations |
Quantity | 6, a real increase in usable output through a 1,050,000-token window, a 128,000-token output ceiling and Batch and Flex at half rate; held at 6 because the output rate is 50 percent above the successor's promotional rate and three times GPT-6.1 Sol's, and because a prompt above 272K tokens doubles the input rate for the whole request |
Quality | 7, clearly ahead of GPT-5.4 on every shared row at GDPval 84.9 against 83.0, Terminal-Bench 2.0 at 82.7 against 75.1 and ARC-AGI-2 at 85.0 against 73.3, with an independent GDPval Elo of 1357 at `xhigh`; held at 7 by the rows where it trails Claude Opus 4.7 on SWE-Bench Pro and Humanity's Last Exam, by the absence of a composite index under the current index version, and by the July 2026 reasoning-token reports |
Skill | 4, execution rather than learning, with an opt-in memory feature on the Codex surface; scored conservatively and held at the predecessor's level because the model completes work a user would previously have learned by doing |
Humics Protection Badge | Humics-Neutral (-1 / +3) |
Creativity | 0 Neutral: it drafts, lays out and executes against a direction you set, with interface and 3D work from a reference image among the vendor's examples; it neither trains nor replaces your ideation |
Critical Thinking | -1 Erodes: fluent, near-frontier output for people who cannot evaluate it, in exactly the tasks where the editing pass used to be the practice, and a production record where users report checking less closely as the output improved |
Social Authenticity | 0 Neutral: clause 4.2-a returns a null for the model as a generator; the live condition is an application that sends under a person's identity unread |
AI Imposture Risk | Medium overall, with Skill Illusion High |
Time Illusion | Medium: real savings at the settings most people use, against an effort decision on every job, five settings whose measured quality spans a GDPval Elo of 978 to 1357, a long-context price that doubles the input rate, and documents that must be read against their sources |
Quantity Illusion | Medium: high-volume fluent output in professional forms, with a million-token window and a 128,000-token ceiling, and nothing that separates a finished brief from a correct one for a reader who does not know the material |
Skill Illusion | High: expert-form output for users who cannot evaluate it, produced by a model whose selling point is finishing the task, on a surface that can write durable notes from prior chats once memories are enabled; mitigations are stated in Strengths, Limits, and AI Imposture Risk |
Clause 5.2.3-a | APPLIES to the Codex delivery surface once local memories are enabled; the vendor documents an explicit enable step, so the store does not accumulate where the feature is off. High threshold met where writes happen during use without a per-write decision and the user has no reading habit |
Clause 4.2-a | NULL as a generator, with a live condition: an application built on this model that sends text in the person's own name through a connected account without the person reading it first would meet erosion condition (a) |
Clause 7.5 | Removed by framework v1.4 on 2026-10-13, not assessed; recorded so that a reader comparing reviews knows why it is absent |
Section 7c finding | Preparedness High in cybersecurity and in biological and chemical capability, both below Critical, with expanded cyber classifiers, a Trusted Access gate for the permissive configuration, an external assessment that the model gives real uplift to a modestly skilled cyber operator, a separate cyber-permissive sibling model with a 2027-02-01 shutdown date, and a disputed September report of retirement. No sub-score changed, for reasons stated in the section |
Superhuman usage | Invite for a pinned baseline during a migration, a validated computer-use or tool-chain workflow, a low-effort latency-sensitive call, and a teaching case about model lifecycle; keep out of new integrations, high-volume work, prompts that cross 272K without a decision, the newest-knowledge work, permissive security work without Trusted Access, and the final judgement calls |
Over-delegation warning | The failure mode is a team that keeps a familiar model because it works, stops asking whether the successor's ceiling matters, and lets the price gap become a budget line nobody owns. If you cannot say which model runs which task, what the migration date is, and what you verified this week, the model is being paid for in attention rather than in dollars |
Verification checklists | Per workflow, in Real Workflows: multi-model check, external source, human review, specification or regression check, CI-First test |
U365 methods | LIPS holds the version decision, the snapshot string and the verification record, because the model holds no state beyond the session. ULM is the six-domain frame that holds the resource decision, in Career and Finance and in Quality of Life; cost per completed task is CI-First cost engineering and the evaluator's metric, not a ULM method. UP-Context-Engineering writes the context, role, task, constraints and output order the workflows use. UNOP: weak, because the model produces rather than teaches |
Re-check triggers | Any retirement notice or shutdown date for `gpt-5.5`; any change to the price lines, the 272K cliff or the successor's promotional rate; a new independent index revision that publishes a composite for this model; any change to the effort ladder or its defaults; a fix or confirmation of the reasoning-token clustering; any change to the Codex memory default; and a successor release that changes the routing advice |

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Glossary
CI-First
Co-Intelligence First: the U365 principle that the human is the ruler and the orchestrator and AI is the amplifier. The question this review answers with a score is whether the tool makes co-intelligence more profitable than human intelligence alone. GPT-5.5 is a CI-First Positive model: it amplifies you across the common work at a price that now sits above its own successors, and it requires you to supply the scoping and verification discipline the price assumes.
CI-First Benefit Score
The arithmetic mean of the four benefit dimensions, each scored 0 to 10, rounded to one decimal place. 0 to 2.0 is CI-First Negative, 2.1 to 4.0 is CI-First Neutral, 4.1 to 6.0 is CI-First Positive, 6.1 to 8.0 is CI-First Strong, and 8.1 to 10 is CI-First Transformative. GPT-5.5 scores 6.0, which is Positive.
Time Benefit
Whether the tool returns more time than it costs, after the overhead of using it is subtracted. GPT-5.5 is 7: a large agentic coding and computer-use jump over its predecessor, an independent 84.27 percent on Terminal-Bench 2.1 at `xhigh`, and a 21.77-second time to first answer token at the default `high` effort, against an effort decision on every job, a 39.55-second wait at `xhigh`, and a newer model that needs fewer iterations.
Quantity Benefit
Whether the same time produces more usable output. GPT-5.5 is 6: a 1,050,000-token window, a 128,000-token output ceiling, Batch and Flex at half rate and a broad tool list, held at 6 by the highest output rate in its family and by the long-context cliff that doubles input above 272K prompt tokens.
Quality Benefit
Whether the output is better, verified and durable. GPT-5.5 is 7: clearly ahead of GPT-5.4 on every shared row, independently corroborated at a GDPval Elo of 1357 and 84.27 percent on Terminal-Bench 2.1 at `xhigh`, and held below 8 by the rows where it trails Claude Opus 4.7 and by the production record on reasoning-token clustering.
Knowledge and Skill Benefit
Whether the user gains lasting capability. GPT-5.5 is 4: execution rather than learning, an opt-in memory feature on the Codex surface, and a model that completes work the user would previously have learned by doing, so the framework scores it conservatively.
CI-First Profile
The role the AI plays in your working relationship. (level 1) Co-Creator and Thought Partner, (level 2) Co-Worker and Assistant, (level 3) Professor, Coach and Tutor, (level 4) Co-Researcher, Analyst and Tester, (level 5) Challenger, Critic and Devil's Advocate. Lower level numbers indicate higher AI autonomy in the collaboration. GPT-5.5 is primarily a Co-Worker and Assistant (level 2).
Humics
The set of capabilities that are uniquely human, as defined by Pascal Bornet: creativity, critical thinking and social authenticity. The framework asks whether a tool strengthens, leaves neutral or erodes each one.
Humics Protection Badge
A rating of whether a tool protects, leaves neutral or erodes the three human capabilities: Creativity, Critical Thinking and Social Authenticity. Each is scored +1, 0 or -1 and the sum gives the badge. +2 to +3 is Humics-Friendly, -1 to +1 is Humics-Neutral, -2 to -3 is Humics-Risky. GPT-5.5 is Humics-Neutral at -1 / +3.
AI Imposture Risk
The likelihood that a tool traps you in one of three illusions. The Time Illusion is the appearance of saving time when net time is lost. The Quantity Illusion is high volume that does not survive inspection. The Skill Illusion is the appearance of competence while the underlying skill is absent or eroding. Each trap is rated Low, Medium or High with cited evidence. The overall level is Low when all three are Low, Medium when one, two or three traps are Medium or when one trap is High with clear mitigations stated, and High when two or more traps are High or when the tool's core value proposition is built on an illusion. GPT-5.5 is Medium overall, with Skill Illusion High.
User Sentiment
The aggregate of what users report about a tool, kept separate from the framework's own findings. No review platform carries model-level data for GPT-5.5; the signal is the Hacker News launch thread and three later threads that carry the production record, all directional and all attributed to the handles that posted them.
Review Status
The badge at the top of this review. The vocabulary is: Active, the tool is current and recommended; Active (updated), recently re-checked and refreshed; Changed, a re-check trigger has fired and an update is pending; Risky, the tool has significant unresolved issues or has been clearly surpassed, so use it with caution; Stale, not re-checked in over six months, so pricing and features are unverified; Retired, the tool still works but is no longer recommended; Deprecated, the tool has been shut down or fundamentally changed.
Last tested and Re-check
The date this review's evidence was gathered and the condition that forces a new pass. GPT-5.5 was tested on 2026-11-14 and re-checks on any of the seven triggers listed at the top of this document, and in any case within six months.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Sources
Vendor primary sources
The launch post, for the positioning, the benchmark table, the token-efficiency claim, the preparedness findings, the availability and the price: https://openai.com/index/introducing-gpt-5-5/
The model page, for the identifiers, the snapshot, the context and output limits, the modalities, the effort levels, the tool list and the text-token prices: https://developers.openai.com/api/docs/models/gpt-5.5
The GPT-5.4 model page, for the predecessor's identifiers, price and knowledge cutoff: https://developers.openai.com/api/docs/models/gpt-5.4
The GPT-5.6 Sol model page, for the successor's identifiers, price, promotional-rate statement, context and effort levels: https://developers.openai.com/api/docs/models/gpt-5.6-sol
The API pricing page, for the standard, long-context, batch and cache lines: https://developers.openai.com/api/docs/pricing
The business pricing page, for the processing modes and the enterprise offerings: https://openai.com/api/pricing/
The deprecations page, read in full on 2026-11-14, for the lifecycle states, the upcoming shutdowns and the notice periods: https://developers.openai.com/api/docs/deprecations
The full model catalogue, for the current line-up: https://developers.openai.com/api/docs/models/all
The system card, for the preparedness determinations, the cyber and biological evaluations, the external assessments and the safeguard design: https://deploymentsafety.openai.com/gpt-5-5
The preparedness framework, for the thresholds the launch post cites: https://cdn.openai.com/pdf/18a02b5d-6b67-4cec-ab64-68cdfbddebcd/preparedness-framework-v2.pdf
Trusted Access for Cyber, for the programme a security team has to join: https://openai.com/index/scaling-trusted-access-for-cyber-defense/
Codex memories, for the local memory store, the enable step and the storage location: https://learn.chatgpt.com/docs/customization/memories
The Codex documentation index, for the current surfaces: https://developers.openai.com/codex/llms.txt
The GPT-6 Astra launch post, for the later generation's positioning and its comparison with GPT-5.6 Sol: https://openai.com/index/gpt-6-astra/
Independent sources
Artificial Analysis, the GPT-5.5 model page, for the five effort variants, the per-effort GDPval Elo and Terminal-Bench 2.1 scores, the Tau2 scores, the time to first answer token, the output speed and the note that no composite index is published for this model: https://artificialanalysis.ai/models/gpt-5-5
Artificial Analysis, the GPT-5.6 Sol page, for the successor's release date and measurements: https://artificialanalysis.ai/models/gpt-5-6-sol
Artificial Analysis, the intelligence index methodology, for the nine evaluations behind the current composite: https://artificialanalysis.ai/methodology/intelligence-benchmarking
Community and community-reported evidence
Hacker News, the launch thread, 1,580 points and 1,056 comments, read on 2026-11-14, for every quoted commenter in the launch section: https://news.ycombinator.com/item?id=47879092
Hacker News, the API release thread, 256 points and 159 comments, read on 2026-11-14: https://news.ycombinator.com/item?id=47894000
Hacker News, the price thread, 214 points and 73 comments, read on 2026-11-14, for the cost-per-completed-task measurements: https://news.ycombinator.com/item?id=48057209
Hacker News, the reasoning-token thread, 372 points and 152 comments, read on 2026-11-14, for the 518-token clustering analysis and its counter-reports: https://news.ycombinator.com/item?id=48789428
Hacker News, the hallucination thread, 585 points and 294 comments, read on 2026-11-14, for the AA-Omniscience comparison and its methodological caveats: https://news.ycombinator.com/item?id=48600167
A September 2026 trade report, cited only as the origin of the retirement claim, not as an authority on the lifecycle: https://www.gizmochina.com/2026/09/16/openai-retiring-gpt-5-5-on-october-14-you-may-need-to-update-your-workflow/
Review platform sources
No reviews found on G2, Capterra, Trustpilot or Product Hunt for this model endpoint. Those platforms rate AI products and companies rather than individual model endpoints, and none publishes a model-level figure for GPT-5.5. This review states that rather than inventing a rating.
Framework and method
The U365 CI-First Evaluation Framework, version 1.4.1, which is the scoring method used here: CI-First Evaluation Framework
The U365 INSIDE Tools review template, which sets the structure of this post and the tool-type variants applied in it: INSIDE Tools Review template
Published U365 INSIDE Tools reviews, read as comparisons and named in this post, including the GPT-5.4, GPT-5.6 Sol, GPT-6.1 Sol, GPT-6 Astra and Claude Sonnet 5.5 reviews: INSIDE Tools reviews
The U365 methods house pages, for the UP-Context-Engineering Method, ULM, LIPS and UNOP as they are published: U365 methods

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Faculty Note on Evidence Quality
Six things should be said plainly about the evidence behind this review, because they change how much weight a reader should put on each part of it.
First, the vendor's launch table and the independent measurement are not the same test. OpenAI reports 82.7 percent on Terminal-Bench 2.0 at `xhigh` in a research environment, and Artificial Analysis reports 84.27 percent on Terminal-Bench 2.1 at `xhigh`. The two figures point in the same direction and they are not interchangeable: the test version differs, and the independent number is a later benchmark. This review quotes both with their version numbers attached, and it does not average them or treat one as confirmation of the other. The same discipline applies to GDPval, where the vendor reports a win-or-tie percentage of 84.9 and the independent page reports an Elo of 1357.
Second, the independent composite index is not available for this model, and that is a finding rather than a gap to fill. Artificial Analysis publishes `intelligenceIndex` as null for all five GPT-5.5 variants under index version v5.0.1, and its model page shows no composite figure. What the page does publish is the component evidence: GDPval Elo and Terminal-Bench 2.1 and Tau2 by effort. A launch-day reader cited an index of 56.7 at the time, and this review attributes that number to the reader rather than to the evaluator. A reader comparing this model's index against a newer model's is comparing two versions of a test that has changed, and the comparison is invalid.
Third, the cost figures are per task and per setting, and the spread is larger than the price gap between models. Two benchmarking firms reported, in the same thread and from different suites, that GPT-5.5 cost about 1.5 to 2 times and about 3.5 times what GPT-5.4 cost per completed task. A practitioner reported $20 on a task he expected to cost $1 to $2. The rate card explains part of that and not all of it, because token consumption and turn count move independently of the price. Every cost sentence in this review names the setting or the measurement behind it, because a cost without a setting is not a number a reader can use.
Fourth, the production record is a community record, and it is used as one. The July 2026 analysis of reasoning-token clustering is specific, reproducible in principle and supported by several independent reports in the same thread, and it is still not a controlled measurement of the model's error rate. The June 2026 hallucination comparison is a real evaluation with a conditional metric, and the thread itself explains why the metric does not describe ordinary use. This review attributes each claim to its source, states the limit in the same paragraph, and does not aggregate the threads into a rating. No review platform carries a model-level figure, and the absence is stated rather than filled.
Fifth, the lifecycle is the most contested fact in the review. OpenAI's deprecations page, read in full on 2026-11-14, carries no retirement notice for `gpt-5.5`; the model page publishes current prices and endpoints; the model is in the current catalogue; and a September 2026 trade report said the model would be retired on 2026-10-14. One of those facts is incomplete and the record does not say which. The review treats the vendor's documentation as the authority, records the report as a report, and tells the reader to check the model record's `shutdown_date` before planning beyond the next quarter. A reader who needs certainty should not take it from this review; they should take it from the API.
Sixth, the most arguable score is Quality at 7, and the argument is fair. At launch the model was an 8 on this dimension, and the case for holding it at 7 now rests on two things: the successor and the newer sibling measure better on the same framework, and the production record carries an unresolved finding that the vendor has not addressed in public. A reader who says the model still does the work and should keep an 8 is making a defensible point. The framework's answer is that Quality measures verified, durable output relative to the user's own baseline, and a model with a documented reasoning-token defect and two cheaper successors has a weaker claim on durability than it did in April. The adverse finding is stated as prominently as the favourable ones, and it is the reason the badge is Risky rather than Active.
Review conducted by URC under the CI-First Evaluation Framework, version 1.4.1. Scoring date 2026-11-14. Tool version reviewed: GPT-5.5, `gpt-5.5`, default snapshot `gpt-5.5-2026-04-23`, released 2026-04-23.

GPT-5.5: OpenAI's Superseded Flagship Still Costs $5 and $30
Status and Re-check
Status: Risky | Last tested: 2026-11-14 (GPT-5.5, `gpt-5.5`, snapshot `gpt-5.5-2026-04-23`, released 2026-04-23) | Re-check: trigger-based (max 6 months)
Risky: the tool has significant unresolved issues, or it has been clearly surpassed by newer alternatives. Use it with caution and read the Limits section.
For detailed explanations of the CI-First evaluation terms used in this review, including the Humics Protection Badge and the AI Imposture Risk levels, see the Glossary above.
Re-check triggers:
Any retirement notice or shutdown date for `gpt-5.5`. The vendor's deprecations page carries none on 2026-11-14, and a September report said the model would be retired on 2026-10-14. A notice, a withdrawal or a shutdown date moves every lifecycle sentence in this review.
A price change on any line, or the successor's promotional rate ending. $5 input, $0.50 cached and $30 output, with 2x input and 1.5x output above 272K prompt tokens, is the rate card this review scores. GPT-5.6 Sol's promotional $4 and $20 runs to 2026-11-30, and the date when it changes is a date when this model's relative position changes.
A new independent index revision that publishes a composite for this model. Artificial Analysis publishes no Intelligence Index for GPT-5.5 under v5.0.1. A published composite, or a re-run under a newer index, would change the independent section.
Any change to the effort ladder or its defaults. Five settings with `medium` as the default and no `max` is the ladder this review scores. A new level, a changed default or a changed behaviour at `xhigh` moves the cost and quality arithmetic.
A fix or confirmation of the reasoning-token clustering. The July 2026 analysis reported output clustering at about 518-token intervals, correlated with errors on complex tasks. A vendor fix, a public explanation or a retraction changes the Quality rationale.
Any change to the Codex memory default. Clause 5.2.3-a applies where local memories are enabled and the user has no reading habit. A move to on-by-default, or a move that removes the feature, re-opens the clause.
A successor release that changes the routing advice. GPT-5.6 Sol and GPT-6.1 Sol are the models this review routes new work to. A GPT-6.2 or a GPT-7 would make both the comparison table and the migration advice stale in one step.



Comments